# Botminds — full corpus
> Botminds is an agentic AI platform for document-heavy operations, purpose-built for lending, credit decisioning and underwriting. Teams describe the outcome they need; Botminds delivers a governed, certified solution running on its own platform — agents that read, extract, decide and cite their sources, with human approval where judgment matters — instead of raw code someone still has to secure, test, host and scale.
Headquarters: Seattle, WA, USA. Product engineering: Chennai, India.
Compliance: SOC 2, ISO 27001, GDPR. Curated index: https://www.botminds.ai/llms.txt
---
# Comparisons
## Botminds vs C3 AI: purpose-built vs general-purpose enterprise AI
URL: https://www.botminds.ai/compare/botminds-vs-c3-ai
> C3 AI offers a broad enterprise AI application platform. Botminds is purpose-built for document-heavy operations in lending and credit — live in days, governed by design.
## Two different answers to "how do we get AI into the enterprise"
C3 AI's answer is breadth: a platform plus an application catalog that stretches from predictive maintenance to defense analytics, deployed as an enterprise program with serious data-integration machinery underneath. For organizations whose AI ambition spans the whole estate, that breadth is the pitch.
Botminds' answer is depth. Lending and credit operations run on documents — borrower financials, tax returns, bank statements, credit files — and the teams processing them don't need an AI program; they need the work done, governed. So the platform ships the workflows themselves: spreading, intake, memo generation, underwriting support — with agents that read and cite, and analysts who approve.
## Depth shows up in the details breadth can't reach
What does purpose-built actually buy? Spreading templates that survive a borrower's creative Excel. Normalization that respects accounting standards. Approval gates that match credit policy, not a generic workflow engine. Citations an underwriter clicks during a live deal review. A regulator-ready trail produced as a by-product of the work, not as a reporting project afterward.
None of that is impossible on a general platform — it's just months of program work each, because the domain knowledge has to be built in on site. On Botminds it's the starting point, hardened by every lending operation already running on it.
## The adoption test
Here's a simple way to decide: ask each vendor what happens in the first two weeks. On a broad enterprise platform, week two looks like data-source inventories and integration architecture. On Botminds, week two looks like your analysts reviewing real spreads from real borrower files, with every number cited — and telling you what to tune.
---
## Botminds vs Claude Code: Build vs Adopt
URL: https://www.botminds.ai/compare/botminds-vs-claude-code
> Claude Code writes excellent code. Botminds delivers a running, governed solution — reviewed, tested, secured, hosted and scaled. The difference is everything around the code.
## The prompt is the same. What comes back is not.
Give Claude Code a serious prompt — "build me a system that reads borrower financials and produces a spread" — and it will do something genuinely remarkable: plan the work, write the code, wire the parsers, even draft the tests. Engineers rightly love it. We use agentic coding tools ourselves, every day.
But look at what's in your hands when it finishes: **a codebase.** Nobody has reviewed it. Nothing has load-tested it. No auditor has certified it. It has no infrastructure, no monitoring, no on-call rotation, no compliance story, and no track record. Every one of those gaps is now an engineering project, and every project lands on your team — not once, but for the life of the system.
Ask Botminds for the same outcome and what comes back is different in kind, not in degree: a **BMX solution running on the Botminds platform**. The extraction agents, the normalization logic, the approval workflow — defined in days, running on infrastructure that already carries production lending volume, inside a security envelope that is already SOC 2 and ISO 27001 certified, with test cases attached and every extracted number cited to the exact page it came from.
## A solution is code plus everything you forgot to estimate
The honest arithmetic of DIY looks like this: the code is perhaps 20% of a production system. The other 80% — review, testing, security hardening, compliance evidence, hosting, scaling, monitoring, upgrade paths, provenance, access control — is the part no coding agent hands you, because it isn't code. It's operational maturity, and it only comes from running real workloads in production for years.
That 80% is precisely what a platform is. When a bank runs financial spreading on Botminds, it isn't trusting freshly generated code; it's trusting a governed system that has already processed the last thousand borrowers' statements, under certifications an auditor can inspect, with a human approval step exactly where credit policy demands one.
## Where this comparison actually lands
This isn't a contest between Botminds and Claude Code — they're different layers of the same revolution. Coding agents have made *code* astonishingly cheap. That makes everything that *isn't* code — governance, certification, provenance, scale — the scarce, valuable thing. If your goal is to build software, use a coding agent. If your goal is to **operate a document-heavy business process you can defend to a regulator**, adopt a platform where that operation is already certified, tested and running.
---
## Botminds vs CrewAI: a framework for builders vs a platform for operators
URL: https://www.botminds.ai/compare/botminds-vs-crewai
> CrewAI is a popular open-source framework for orchestrating AI agent teams in code. Botminds delivers governed agent solutions for document operations — no framework assembly required.
## Frameworks are how builders think. Platforms are how operations run.
CrewAI deserves its popularity: it made multi-agent orchestration approachable, and thousands of developers learned to think in crews, roles and tasks through it. If your team's job is to *engineer an agent system*, it's a fine place to stand.
But an enterprise operation doesn't run on primitives. It runs on the things frameworks deliberately leave out — because they're not the framework's job: security certification, per-number provenance, approval workflows, evaluation before deployment, monitoring after it, and someone on the hook for scale. Every CrewAI project that reaches production grows this surround by hand. Botminds *is* that surround, with the agents already inside.
## The prototype trap
The pattern we see: a sharp team builds an agent demo in two weeks and the organization concludes production is a month away. Six months later they're deep in eval harnesses, retry semantics and security review — building a worse version of a platform instead of their business. The two weeks were real; so is the 80% that follows. Adopt the 80%, keep your two-week energy for what differentiates you.
---
## Botminds vs Cursor: an AI editor vs an operating platform
URL: https://www.botminds.ai/compare/botminds-vs-cursor
> Cursor makes developers dramatically faster at writing software. Botminds removes the need to write the software at all for document-heavy operations — the solution already exists, governed.
## Faster code is not the same as no code to own
Cursor has earned its reputation: engineers move visibly faster in it, and for building software products that speed compounds. But speed changes the cost of *writing* a system, not the cost of *owning* one. Whatever a team builds — however quickly — it must then review, test, harden, host, monitor, patch and evidence for as long as the business depends on it.
Botminds attacks the other side of the equation. For document-heavy operations — spreading, intake, credit memos, underwriting support — the software already exists, running on a platform whose security certification, test discipline and scale are amortized across every customer. Adopting it means there is no new system to own at all.
## The question that decides it
Don't ask "could we build this?" — with modern tools, the answer is almost always yes. Ask "do we want to *operate* this, forever, under audit?" If the answer is no, the build-vs-adopt decision has already made itself.
---
## Botminds vs GitHub Copilot: assistance vs adoption
URL: https://www.botminds.ai/compare/botminds-vs-github-copilot
> GitHub Copilot accelerates developers inside the world's default code platform. Botminds removes the development project entirely for document-heavy operations — adopt the governed solution instead.
## The most popular answer isn't always the relevant one
Copilot is the default answer to "how do we use AI in engineering," and deservedly so — it meets millions of developers exactly where they work. But notice what question it answers: *how do we build software faster?* Lending and operations leaders are asking a different one: *how do we get this document-heavy process running, governed, without an engineering program?*
Answering the second question with a coding assistant means commissioning software: roadmap slot, build, test, security review, hosting, on-call, compliance evidence — accelerated, yes, but all still yours. Answering it with Botminds means adopting a solution that already exists on a certified platform, where the AI's every number is cited to its source and your analysts hold the approval pen.
## Two budgets, one decision
A Copilot seat is an engineering-productivity spend; a Botminds solution is an operations spend that *frees* engineering capacity. The organizations that get this right run both — Copilot where they build, Botminds where they'd otherwise be forced to.
---
## Botminds vs LangGraph: graph plumbing vs governed operations
URL: https://www.botminds.ai/compare/botminds-vs-langgraph
> LangGraph gives engineers precise, stateful control over agent workflows in code. Botminds ships those workflows finished and governed for document-heavy lending operations.
## Precision tools, and the factory around them
LangGraph earned engineering respect by being honest about agent systems: they're stateful, they fail, they need checkpoints and human interrupts. If you're going to *engineer* an agent workflow, this is the caliber of tooling you want.
Adopting Botminds is a decision one level up: not *how* to engineer the workflow, but *whether* your organization should be engineering it at all. For document-heavy lending operations the answer is usually no — the workflow isn't your differentiation, but the certified surround it needs is expensive, and the platform that already has both exists.
## Where the 80% lives
Take a LangGraph prototype of financial spreading to production and list what remains: extraction quality across scanned tax returns and creative Excel; normalization to your chart of accounts; eval suites that catch regressions; a security review your CISO signs; per-number provenance an underwriter can click; hosting, monitoring, on-call; audit evidence, forever. None of that is a graph problem. All of it is the platform.
---
## Botminds vs Microsoft Copilot Studio: general-purpose builder vs domain platform
URL: https://www.botminds.ai/compare/botminds-vs-microsoft-copilot-studio
> Copilot Studio lets organizations build custom copilots and agents across the Microsoft 365 world. Botminds ships governed, domain-deep solutions for document-heavy lending operations.
## Reach and depth are different products
Copilot Studio's superpower is reach: if your organization lives in Microsoft 365, you can put an assistant almost anywhere an employee works, administered by the IT machinery you already trust. For the broad middle of business processes, that's a compelling default.
Document-heavy credit operations sit outside that middle. Their difficulty isn't distribution — it's domain: scanned tax returns that resist extraction, accounting standards that resist normalization, credit policies that dictate exactly who approves what, auditors who want the trail. Depth like that isn't assembled from connectors; it's earned processing real lending volume, which is where Botminds lives.
## The coexistence answer
This is rarely an either/or. The pattern that works: Copilot Studio for estate-wide assistants; Botminds as the system of operation for document-heavy credit work; governed, cited outputs flowing from the second into the first. What fails is the inverse — asking a general-purpose builder to be a lending platform, one connector at a time.
---
## Botminds vs nCino: the banking system of record vs the agentic layer of work
URL: https://www.botminds.ai/compare/botminds-vs-ncino
> nCino is the cloud banking OS — loan origination, records, process. Botminds is the agentic AI layer that does the document work feeding those records — and the two compose naturally.
## Record and work are different systems
Banking runs on two layers that get conflated: the **record** — where loans, statuses and processes live — and the **work** — where a human (today) actually reads the tax return, builds the spread, drafts the memo. nCino conquered the record layer; it's the category-defining loan origination and banking OS, and this page won't pretend otherwise.
Botminds lives in the work layer. Its agents do the reading and drafting that process steps demand, with the properties the work layer needs: extraction that survives scanned returns and creative Excel, numbers cited to their source page, approvals aligned to credit policy, an audit trail as exhaust.
## Why the layers compose
A process step in the record system says "spread completed." Botminds is how it *gets* completed in minutes instead of hours — and the spread that lands back carries its citations with it, so downstream reviewers inherit checkability, not just data. That's why this comparison usually ends in an integration diagram, not a bake-off: the record keeps the truth about the loan; Botminds produces the truth about the documents.
---
## Botminds vs Ocrolus: document analysis vs document operations
URL: https://www.botminds.ai/compare/botminds-vs-ocrolus
> Ocrolus is a strong document-analysis engine for lending — classification, extraction, analytics. Botminds is the operating platform around and beyond that step: workflows, decisions, approvals, agents.
## The step vs the operation
Ocrolus picked a hard, valuable problem — reading lending documents reliably — and built focused products on it. Within that boundary it's a credible, well-regarded engine, and lenders with engineering teams happily consume it as an API.
Botminds drew the boundary differently: the *operation* is the product. Extraction is one stage inside a governed flow that begins at intake and ends at an approved, cited, auditable decision. Nothing returns to "your stack" for orchestration, because the orchestration — approvals, exceptions, provenance, monitoring — is the platform.
## One vendor decision vs a platform decision
Choosing a document-analysis API is a component decision: it assumes the surrounding workflow exists or will be built. Choosing Botminds is an operating decision: the workflow, its governance and its evidence arrive together, and the next document-heavy use case is a configuration away. Which decision you're actually facing depends on whether you want to be in the workflow-engineering business at all.
---
## Botminds vs Palantir: the ontology program vs the working solution
URL: https://www.botminds.ai/compare/botminds-vs-palantir
> Palantir's platforms model an enterprise's entire data world. Botminds ships working, governed solutions for document-heavy lending operations — no ontology program required.
## A whole-world platform vs a this-problem platform
Palantir's proposition is grand: model everything your organization knows into an ontology, and build operational applications on top. When the mission spans a government agency or a global industrial base, that ambition is precisely what's required — and Palantir has the record to prove it.
Most lending operations are not that mission. They are a queue of borrower financials, a spreading template, a credit policy, and a deadline. Botminds is built at exactly that altitude: the workflow is the product. There is no ontology phase because the domain model — statements, line items, spreads, memos, approvals — is already in the platform, hardened by production lending volume.
## Governance where the decision happens
Both platforms take governance seriously; they place it differently. Palantir governs the data estate — access, lineage, control across systems. Botminds governs the *decision*: this number came from this page of this statement; this exception went to this analyst; this spread was approved by name. For credit files and regulators, that per-decision trail is the artifact that matters — and it's produced as a by-product of doing the work.
---
## Botminds vs Salesforce Agentforce: CRM-native agents vs document-native operations
URL: https://www.botminds.ai/compare/botminds-vs-salesforce-agentforce
> Agentforce puts AI agents to work inside the Salesforce world — service, sales, CRM data. Botminds puts governed agents to work on documents — lending files, spreads, credit decisions.
## Agents follow their platform's gravity
Every agent platform inherits the gravity of the system it grew from. Agentforce's gravity is the CRM: its agents are strongest where Salesforce data and channels are the world — service, sales, customer operations. That's a real strength, at massive scale.
Botminds' gravity is the document. Lending doesn't start in a CRM record; it starts when a borrower's PDF hits an inbox. Everything Botminds does — extraction across hostile formats, normalization to your templates, citations to the page, approval gates from credit policy — exists because documents, not objects, are the raw material of credit operations.
## Upstream and downstream, not head to head
Put the two on a map of a lending workflow and they barely collide: Botminds governs the upstream — documents into decisions; the CRM owns the downstream — relationships and pipeline. The cited, approved outputs of one become trustworthy fields in the other. Enterprises that see this stop asking "which agent platform?" and start asking "which platform for which gravity?"
---
# Solutions
## 401(k) Compliance Extractor
URL: https://www.botminds.ai/solutions/401k-document-processing
> Extracts and reconciles plan data from Form 5500 filings, payroll files, and plan documents — continuous compliance monitoring, every figure traced to source.
401(k) administration usually runs on an annual look-back. Census data sits in payroll, contribution data sits with the recordkeeper, and nobody reconciles the two until year-end — when non-discrimination test failures are expensive to fix and corrective distributions land on unhappy executives. The 401(k) Compliance Extractor replaces that cycle with agents that read the plan's actual paperwork continuously.
## What it reads and reconciles
The agents ingest Form 5500 filings, payroll exports, HRIS records, plan documents, and recordkeeper statements. From these they maintain a live census — hours worked, compensation definitions, deferral changes, HCE and Key Employee status — and validate every contribution against the rules in the plan document itself. Employer match is recalculated per pay period, so over- and underpayments surface immediately rather than at audit. Eligibility tracking runs on the same data: when an employee crosses the plan's age and service thresholds, the system raises an alert, closing the gap that produces "lost opportunity" corrections for missed enrollments.
## From forecasting to a defensible record
Because the census stays current, ADP/ACP testing outcomes can be forecast mid-year. Teams see a likely failure while there is still time to adjust deferral strategy, and when a correction is needed, the system models QNECs against refunds so the remediation choice is made on cost, not guesswork. Every proposed correction goes to a human for approval before anything moves.
A retirement plan's tax-qualified status rides on being able to show your work. Every extracted figure is cited to its source page in the original filing or payroll file, and testing results, census snapshots, and plan amendments live in one permanent, searchable archive. A Form 5500 audit becomes a read-only review of pre-organized evidence instead of a multi-week hunt through email and spreadsheets.
---
## Adaptive Client Journey Platform
URL: https://www.botminds.ai/solutions/adaptive-client-journey-platform
> Turns signed contracts into running onboarding projects — provisioning, checklists, and milestone tracking generated from the deal documents, fully traceable.
Customer implementation breaks at scale in a predictable way. The context that sales gathered lives in emails, CRM notes, and verbal agreements; success managers spend their first weeks rediscovering it. Engineers burn time on repetitive provisioning instead of integration work. Leadership tracks onboarding health in static spreadsheets and learns about stuck accounts from escalations. The Adaptive Client Journey Platform closes that gap by treating the deal documents themselves as the source of the onboarding plan.
## From signed contract to running project
When a deal closes, agents read the contract and order form, map each sold line item to the configuration tasks it requires, and generate the project timeline and customer-facing checklist automatically. Environment setup, user accounts, permissions, and welcome emails are triggered from the same source — no template selection, no manual project setup, no handoff meeting to reconstruct what was sold. Because the plan is derived from the documents, it is also verifiable against them: configuration validation checks that no required technical step was skipped, and standard operating procedures are enforced by the workflow rather than by memory.
## Exceptions, visibility, and a record that holds up
Milestone tracking and inactivity alerts run continuously. When a customer goes quiet or a deadline slips, the system detects it and routes an escalation to leadership before the account becomes a churn surprise. Sales sees the progress of its closed deals in the same shared record, so status requests stop landing on the implementation team. End-of-quarter signup spikes run through the same workflows at the same standard, which is what lets account capacity per CSM grow without degrading the experience.
Every step — each provisioning action, checklist item, and approval — is recorded with its trigger and timestamp. When an implementation is questioned later, the answer is in the trail.
---
## Asset Intelligence Platform
URL: https://www.botminds.ai/solutions/asset-data-management
> Consolidates asset data from ERP, maintenance logs, sensors, and spreadsheets into one governed record — every attribute validated and traced to its origin.
Asset-heavy operations run on fragmented data. Condition readings sit in SCADA, purchase records in the ERP, inspection results on paper, and the rest in spreadsheets. The result is familiar: run-to-failure maintenance, ghost assets nobody can locate, duplicate procurement, and certifications that surface only when an auditor asks. The Asset Intelligence Platform turns those scattered sources into one governed asset record.
## One governed source of truth
The platform ingests asset data from ERPs, maintenance logs, IoT sensor feeds, inspection records, and spreadsheets, then standardizes formats, removes duplication, and validates critical attributes. Every record is cross-referenced to its origin — the system, log, or document it came from — so any figure on a dashboard can be traced back to the reading or entry behind it. On top of that record, teams get a complete lifecycle history per asset: operations, maintenance events, and component changes in one place, instead of reconstructed from tribal knowledge when a machine goes down.
## From reactive to predictive
With unified condition and usage data, the platform detects performance deviations that precede failure — often weeks ahead — so maintenance is planned rather than emergency-scheduled. When a diagnostic threshold is breached, a CMMS work order is triggered automatically. Spare parts inventory aligns to predicted demand instead of blanket safety stock, cutting both stockouts and excess. Real-time dashboards show utilization, lifecycle stage, and compliance gaps across the fleet, so capital decisions are made against actual asset condition rather than fixed schedules.
Asset decisions carry safety, compliance, and capital consequences, and the record has to hold up to all three. Inspection records and certifications live in the same governed archive as operational data, so audit questions are answered from the record — while the ERP and CMMS stay in place as the operational systems they already are.
---
## Audit Trail Intelligence Suite
URL: https://www.botminds.ai/solutions/audit-trial-intelligence-suite
> Correlates ERP logs, approvals, and communications into one verified timeline per transaction — full-population audit coverage instead of sampling.
Traditional audits sample. Resource constraints mean reviewers examine a fraction of transactions, and the systemic errors or targeted fraud sitting in the rest go unverified until they surface some other way — usually months later, during a quarterly or annual review, when remediation is expensive. The Audit Trail Intelligence Suite replaces sampling with full-population monitoring.
## Every transaction, reconstructed
Agents ingest and link activity logs, approval workflows, communication streams, and transaction data across ERPs, CRMs, and collaboration platforms. For every financial event, the system reconstructs the complete lifecycle: who initiated it, what changed, who approved it, and in what sequence — regardless of which system each step happened in. This closes the two gaps that make audit reconstruction painful: evidence scattered across systems, and logs that show what changed without the context of why. The email approval and the ERP entry land on the same timeline.
## Controls that run continuously
Each reconstructed workflow is validated against your defined compliance policies. Violations — unauthorized limit changes, duplicate payments, segregation-of-duties conflicts, overrides without approval — are flagged the moment they occur, with full context attached for review. Beyond rule checks, the system detects behavioral patterns that indicate fraud or process gaps, so the audit function shifts from finding last quarter's problems to stopping this week's.
An audit trail is only useful if it is verifiable. Every entry in the unified timeline links back to the source log, document, or approval it came from, forming an immutable record that connects financial entries to their supporting evidence. When external auditors arrive, they get direct, read-only access to organized, pre-validated evidence packages — sign-offs proceed from the record itself, and the multi-week scramble through emails and spreadsheets does not happen.
---
## Batch Manufacturing Records Automation
URL: https://www.botminds.ai/solutions/batch-manufacturing-records-automation
> Digitizes batch records — scanned, printed, or handwritten — validates every entry against the master record, and routes deviations to QA for sign-off.
Batch release decisions wait on paperwork. Batch manufacturing records arrive as printed forms, scanned pages, equipment printouts, and handwritten logbook entries — and reconciling them against the master batch record is slow, manual work that sits directly on the critical path to release. Batch Manufacturing Records Automation turns those records into structured, validated process data.
## From paper to structured batch data
The system ingests records from shop-floor systems, scanned forms, and logbooks, handling electronic documents, printed materials, and handwritten notes. Extraction models pull every meaningful value — weights, instrument readings, timestamps, operator entries — and align each one to the corresponding step in the master batch record. Every data point is recorded with its timestamp and a reference to the exact source page it came from, so the structured record never loses its connection to the original evidence.
## Validation, deviations, and release
Each extracted value is checked against the expected ranges defined in the master record and relevant SOPs. In-spec data flows through; anything out of range or inconsistent opens a deviation, routed to QA for investigation and sign-off before the batch moves forward. The system prepares the evidence, and the QA reviewer makes the release call. Versioning preserves the full evolution of every batch record, so MSAT and QA teams can see how the record got to its final state, not just what it says now.
In regulated manufacturing, the record is the product's license to ship. Because every entry is traceable to its source and every deviation carries its investigation trail, the digital archive answers audits and inspections directly — no reconciliation sprint, no hunting through binders. Reconciliation time drops, and release decisions are made on complete, verified data rather than on whichever pages happened to be checked.
---
## Borrower & Portfolio Company Risk Monitoring
URL: https://www.botminds.ai/solutions/borrower-portfolio-company-risk-monitoring
> Monitors borrower and portfolio company financials continuously — surfacing changes in financial health and emerging risk with source-cited evidence.
Portfolio risk rarely announces itself. It shows up as a margin that slipped two quarters in a row, a liquidity position quietly tightening, an operating report filed late and thinner than the last one. Manual monitoring catches these signals only as fast as analysts can read submissions — which, across a growing portfolio, means annually and unevenly. Borrower & Portfolio Company Risk Monitoring reads every submission, every period, and surfaces what changed.
## What it watches
The agents ingest the documents borrowers and portfolio companies actually submit: financial statements, operating reports, compliance certificates, bank statements. From each package they extract the metrics that define financial health — revenue, margins, leverage, liquidity, cash flow — into structured data linked to its source pages. Each period's figures are compared against prior periods, covenant levels, and your policy thresholds, so the trend is visible, not just the snapshot.
When something moves — performance deteriorating, a threshold approached, an anomaly between what the financials say and what the bank statements show — the account is flagged with the specific evidence attached. Risk teams open an alert and see the metric, the trend, and the exact source line behind it, rather than a score with no explanation.
## Why governed matters here
A risk-monitoring signal is only actionable if you can defend it — to a credit committee deciding on a workout, or to a regulator asking why an account was downgraded when it was. Every alert here carries full lineage: the extracted values, the source documents, the thresholds applied. Every review decision is taken by a human and recorded in the audit trail. That turns portfolio surveillance from a sampling exercise into a consistent, portfolio-wide discipline — the same standard applied to every account, every period, with the paper trail built as it happens.
---
## Borrower Application Intake
URL: https://www.botminds.ai/solutions/borrower-application-intake
> Captures borrower applications and onboarding documents through digital intake — classified, extracted, and validated into a decision-ready lending file.
Every lending decision starts with intake, and intake is where files go wrong first. Applications arrive as scanned PDFs, spreadsheets, and email attachments in no particular order; data gets rekeyed by hand; and senior analysts spend their time on document triage instead of credit judgment. When something is missing, underwriting discovers it weeks later. Borrower Application Intake makes the front door of the lending process structured, fast, and traceable.
## What it reads and what comes out
The intake agents handle any PDF — scanned or digital — along with Excel spreadsheets, Word documents, and web-based data. Each incoming document is classified against the checklist for the loan type, and borrower information, application data, and onboarding details are extracted into structured fields. Cross-checks catch the classic intake failures early: a name that does not match across documents, a stale statement, a missing schedule. The output is a complete, indexed lending file where every data point links back to the page it came from — ready for credit, risk, and operations teams to act on without rework.
Automation runs end to end, with human oversight at the decision points. Anything ambiguous is routed to a reviewer with the source evidence attached rather than silently guessed.
## Why governed matters here
Intake data feeds every downstream decision, so an untraceable intake file poisons the whole pipeline. Because each extracted value carries its source citation and each processing step lands in the audit trail, the file is regulator-ready from the moment it is assembled — and the process is repeatable across one application or a portfolio-wide intake queue. Policy-governed workflows enforce the same standard on every file, and pre-built connectors move the structured output into your loan origination system and core banking infrastructure.
---
## Borrower Financial Capacity Analysis
URL: https://www.botminds.ai/solutions/borrower-financial-capacity-analysis
> Evaluates borrower income, leverage, liquidity, and cash flow from source financials — repayment capacity analysis with every figure cited to its page.
## From source documents to capacity metrics
Repayment capacity is the core question in any credit decision, and answering it still
consumes most of an analyst's week. Figures get rekeyed from tax returns into spreads,
cash flow gets rebuilt by hand from bank statements, and by the time the numbers are
assembled there is little time left to think about them. This solution does the assembly,
so analysts spend their time on judgment.
The agents read the borrower's actual financial record — tax returns and their schedules,
financial statements, bank statements, debt schedules — whether it arrives as clean PDFs,
scans, or spreadsheets. Extracted figures are structured into income, leverage, liquidity,
and cash flow analyses, and repayment capacity is computed against your credit policy
definitions rather than a generic template. Spreading that took days of manual entry runs
five times faster, and inconsistencies between documents — income on the return that fails
to reconcile with deposits on the statements, a liability on the debt schedule missing
from the balance sheet — are flagged instead of slipping through.
The output is decision-ready: the metrics, the underlying spread, and the exceptions, each
linked to the exact source page. An analyst reviewing a debt-service figure clicks through
to the line on the tax return it came from.
## Why governed matters here
Capacity analysis is exactly the work a regulator or credit committee will ask you to
defend. Every number in the output is cited to its source; every computation and flag
lands in the audit trail; and no credit conclusion ships without human approval. That
combination — automated assembly, transparent lineage, human sign-off — makes the analysis
repeatable across a portfolio and defensible on any individual file, whether it's one
borrower or a full review cycle.
---
## Borrower Identity, Entity & Eligibility Verification
URL: https://www.botminds.ai/solutions/borrower-identity-entity-eligibility-verification
> Validates borrower identity, business entity details, and eligibility attributes from source documents — consistent, auditable checks on every file.
Before capacity or collateral matters, a lender has to answer three basic questions: is this borrower who they say they are, is the entity what the paperwork claims, and does the file meet the program's eligibility rules. Answered manually, these checks are slow and inconsistent — different analysts check different things, and the evidence behind a "verified" stamp lives in someone's memory. This solution makes verification a structured, repeatable step.
## What gets verified
The agents read identity documents, entity formation records — articles of incorporation, operating agreements, EIN letters, certificates of good standing — and the supporting documents that carry eligibility attributes. Names, registration numbers, addresses, ownership details, and entity status are extracted into structured fields, then cross-checked across the file: the legal name on the application against the formation documents, the signer against the operating agreement's authority provisions, the entity details against every place they appear. Mismatches that manual review misses — a transposed registration number, a legal name that drifted between documents — are flagged with both sources shown side by side.
Eligibility screening runs against your policy criteria, not a generic checklist. Each attribute is tested, and the result is recorded as pass, fail, or exception with the evidence attached. Exceptions go to a human reviewer; the system never waves a file through on its own.
## Why governed matters here
KYC and eligibility decisions are the ones examiners test first, and the question they ask is what you checked, against what rule, and where the evidence is. Every verification step here produces a record: the extracted value, the document and page it came from, the rule it was tested against, and who approved the exception if there was one. That gives compliance a file that defends itself — consistent across the portfolio, repeatable on renewal, and ready for review without reconstruction.
---
## Borrower Intake & Document Collection
URL: https://www.botminds.ai/solutions/borrower-intake-document-collection
> Collects and organizes borrower financials, statements, and supporting documents into one structured lending file — complete, indexed, and source-linked.
Every deal starts the same way: a borrower, a checklist, and a package that arrives incomplete. Financial statements come as scans, tax returns are missing schedules, bank statements cover the wrong months — and the gaps surface only when an underwriter finally opens the file, weeks into the process. Borrower Intake & Document Collection owns that gap and closes it at the front of the pipeline.
## From inbound pile to structured file
The agents collect whatever the borrower sends — any PDF, scanned or digital, Excel spreadsheets, Word documents, web-based data — across every channel. Each document is classified against the deal's required-documents checklist, and the identifying details are extracted: entity names, statement periods, tax years, account numbers. Cross-format document intelligence means a handwritten schedule and a clean digital statement land in the same structured file with the same treatment.
Completeness checks run continuously. A missing K-1, financials that are a fiscal year stale, an unsigned document — each gap is flagged specifically while there is still time to fix it cheaply, instead of stalling underwriting later. What comes out is a single structured lending file: indexed, complete, and organized the way your credit process expects, with every document and extracted field linked back to its source.
## Why governed matters here
The intake file is the foundation for everything downstream — capacity analysis, verification, credit memo, review. If the foundation is untraceable, nothing built on it holds up. Here, every classification and extraction is recorded with its source citation, every completeness decision lands in the audit trail, and policy-governed workflows enforce the same intake standard on file one and file one thousand. Human reviewers step in at the decision points that matter, and the assembled file moves into your loan origination and document management systems through pre-built connectors — so a regulator-ready package is the default output of intake rather than a later reconstruction.
---
## Borrower Risk Analysis
URL: https://www.botminds.ai/solutions/borrower-risk-analysis
> Analyzes borrower performance, anomalies, and repayment risk from extracted financial data — every finding traced to the source document behind it.
The riskiest thing in a credit file is the pattern nobody had time to see. Borrower performance data arrives buried in statements, returns, and schedules; assembling it into a view that reveals trends and anomalies is manual work, so it happens thoroughly for large exposures and thinly everywhere else. Borrower Risk Analysis applies the same analytical depth to every file.
## From extracted data to risk signal
Working from the financial data extracted across the borrower's documents, the agents build a consistent multi-period picture of performance: revenue trajectory, margin movement, leverage, liquidity, and cash flow against obligations. On top of that structure, the analysis hunts for what a rushed manual review misses — anomalies within a period, breaks in trend between periods, and inconsistencies across documents, such as reported income that fails to reconcile with banking activity or a debt schedule that disagrees with the balance sheet.
Repayment risk is then assessed against your credit policy, with the drivers spelled out rather than compressed into an opaque score. An analyst sees which specific factors moved the assessment — and clicks through from any figure to the exact page of the source document it came from. The result is decision-ready intelligence for credit, risk, and operations teams: accurate, repeatable, and consistent whether it runs on one borrower or across the portfolio.
## Why governed matters here
Risk conclusions drive pricing, structure, and approval — decisions a lender must be able to reconstruct and defend later. Every finding in this analysis carries its lineage: the source citation, the computation, the policy rule applied. Every conclusion goes to a human for approval before it shapes a decision, and every step lands in the audit trail. Guesswork is eliminated by making every claim checkable against the borrower's own documents.
---
## Claims Resolution Platform
URL: https://www.botminds.ai/solutions/claims-process-automation
> Reads claim packets — EDI 837s, HCFA and UB-04 forms, medical attachments — validates codes against payer policy, and flags anomalies with audit traceability.
Claims operations break when volume outruns manual adjudication. Backlogs build, improper payments leak out, and providers wait weeks for decisions. The Claims Resolution Platform is document-to-decision automation for that problem: it reads every claim packet, validates it against policy, and routes only the genuinely ambiguous ones to a human.
## One pipeline for every claim format
Claims arrive as structured EDI 837 streams, scanned HCFA and UB-04 forms, and faxed medical records — and the clinical evidence that justifies a billed code is usually in a different document than the code itself. The platform ingests all of it, extracts member data, procedure codes, and diagnosis descriptions, and correlates them across the packet, so cross-referencing clinical evidence with billing lines stops being a manual research project.
## Payment integrity before payment
Validation runs before the money moves. Billed CPT and ICD-10 codes are checked against payer policy and medical-necessity guidelines automatically and consistently — the same rules on every claim, which is what manual review can never promise. Patterns that indicate fraud, waste, or abuse — upcoding, unbundling, duplicate submissions — are detected across claim history, not just within a single file, and flagged in real time rather than discovered in a look-back audit.
Routine, clean claims are cleared for straight-through processing. High-cost, ambiguous, or anomalous claims route to nurse or SIU review with the specific inconsistency and its source evidence already attached, so reviewers act on decision-ready information instead of re-reading the packet from scratch. Every extraction, validation, and decision links back to the exact page of the source document, and flagged decisions are human-approved. The full trail — what was read, what was checked, who decided — is preserved per claim, supporting HIPAA obligations and making audit response a query rather than a scramble. Seasonal spikes get the same rigor, without temporary adjudication staff.
---
## Clinical Protocol Validator
URL: https://www.botminds.ai/solutions/protocol-validation-automation
> Validates clinical study protocols against regulatory guidance, internal SOPs, and their own tables and text — before amendments get expensive.
A protocol amendment costs close to $500,000 and months of study delay — and most
amendments trace back to inconsistencies that were sitting in the initial document all
along. A lab test listed in the Visit 3 column of the Schedule of Assessments but
missing from the Visit 3 text. An eligibility criterion like "uncontrolled hypertension"
that every site interprets differently. Safety language a recent FDA or EMA guidance
expects that the draft never picked up.
## Four classes of error, caught upstream
The Clinical Protocol Validator reads draft protocols in Word or PDF and stress-tests
the logic before a single patient is enrolled:
- **Internal consistency** — cross-references the synopsis, body text, footnotes, and
the Schedule of Assessments, flagging procedures that appear in a table but not in the
visit description, and vice versa.
- **Eligibility precision** — detects subjective inclusion and exclusion wording and
suggests quantifiable replacements, such as *no dose change in the last 30 days*
instead of *stable medication*.
- **Regulatory alignment** — maps the draft against current FDA/EMA guidance and
therapeutic-area frameworks to confirm required endpoints and safety language are
present.
- **Site and patient burden** — scores procedural intensity per visit, so heavy visits
that threaten recruitment and retention are visible at design time.
## Findings with full traceability
Every finding cites its source — the guidance paragraph, the SOP clause, or the
conflicting section of the protocol itself — so medical writers can verify the issue
rather than take the system's word for it. Flags route to the writing team for
structured review; the validator proposes, humans decide. Teams iterate on the draft
with a live view of what remains inconsistent, ambiguous, or non-compliant, and the
review history stays attached to the document for IRB/EC and audit purposes.
The result is a protocol that is executable the first time: fewer preventable
amendments, fewer site queries, and an approval process that starts from a clean
document.
---
## Clinical Summary Generator
URL: https://www.botminds.ai/solutions/patient-discharge-summarization
> Turns scattered clinical notes, labs, and imaging reports into source-linked discharge summaries care teams can verify at the point of care.
Clinicians spend more time hunting for data than treating patients. A single patient's
history is scattered across EHR tabs, scanned referral PDFs, and lab portals, and the
notes that do exist suffer from bloat — hundreds of pages where the relevant facts hide.
The Clinical Summary Generator does the assembly work so the clinician does the
clinical work.
## One patient, one timeline
The system ingests records from every source — HL7 feeds, CCDA documents, unstructured
progress notes, scanned external records — and organizes the key clinical concepts into
a single chronological profile: diagnoses, medications, procedures, allergies.
Duplicates and administrative noise are filtered out. Details that keyword search
misses, like social determinants or medication non-adherence buried in free text,
surface because the system reads meaning rather than matching strings.
From that profile it generates a coherent narrative summary, ready for discharge,
referral, or morning rounds. Lab values and vitals extracted from years of notes can be
graphed to show progression, and the view adapts to the reader — renal function
foregrounded for the nephrologist, cardiac history for the cardiologist.
## Safe enough for a handoff
A summary a clinician cannot verify is a summary they cannot use. Every generated
statement anchors to its exact source snippet in the original record — hover, see the
evidence, move on. Where sources disagree, such as mismatched medication lists, the
conflict is flagged for provider review instead of being silently reconciled. That
discipline is what makes the output usable at shift change and defensible in the chart:
this is document-to-decision work where the decision belongs to the clinician, and the
system's job is to make the evidence impossible to miss.
---
## Collateral & Structure Assessment
URL: https://www.botminds.ai/solutions/collateral-structure-assessment
> Reads appraisals, guaranties, and loan documents to assess collateral strength, guarantor support, and structural protections — every finding cited to source.
When credit asks what protects the bank if cash flow fails, the answer lives in a stack of documents: appraisals, guaranty agreements, security agreements, title reports, loan documents. Pulling a defensible answer out of that stack is slow, senior-analyst work — and it is done a little differently on every deal. This solution makes it fast, consistent, and auditable.
## What it reads
The platform ingests the collateral package in whatever form it arrives — scanned appraisals, executed guaranties, loan agreements, UCC filings, Word memos, Excel schedules — and extracts what the assessment actually needs: collateral type and appraised value, lien position and perfection status, guarantor obligations and the support written into the guaranty language, covenants, and the structural protections embedded in the loan documents. Values and terms are cross-checked across documents, so a valuation that disagrees with the schedule, or a guaranty that caps lower than the memo assumes, gets flagged instead of slipping through.
## The assessment it produces
The output is a structured assessment: collateral strength measured against the exposure, guarantor support quantified from the actual agreement text, and loan structure evaluated against your credit policy. Every data point links back to its source page — a reviewer clicks from the finding to the clause or figure behind it. Because the same method runs on every deal, assessments are comparable across analysts, deals, and the whole portfolio, instead of varying with whoever wrote them.
Nothing is decided by the machine. Credit officers review and approve every assessment, and the full trail — what was read, what was extracted, who approved — is preserved for internal review and examiners. Routine assembly work moves off senior analysts, and what reaches the credit committee is a regulator-ready artifact rather than a summary that has to be re-verified by hand.
---
## Commercial Due Diligence Intelligence
URL: https://www.botminds.ai/solutions/commercial-due-diligence-intelligence
> Reads data rooms, CIMs, customer contracts, and external research to build a cited view of market, customers, competitors, and growth for the deal team.
Commercial due diligence runs on a hard deadline against a soft data set: a data room assembled by the seller, a CIM written to persuade, and a pile of external research that may or may not agree with either. The manual version means senior people skimming hundreds of documents and hoping the important contradiction is in the ones they read. This solution reads everything and shows its work.
## Reading the room — all of it
The platform ingests the full diligence set: the CIM, data room documents, customer contracts, management presentations, earnings transcripts, and external market research, in any format. It extracts the commercially meaningful content — market size and share claims, customer concentration and retention signals, competitive positioning, pricing structures, growth assumptions — and structures it so the deal team queries findings instead of hunting through folders.
Crucially, it corroborates. A revenue-quality claim in the CIM gets checked against the actual customer contracts. A market-growth assumption gets set beside the external research. Where sources agree, the finding is stronger; where they conflict, the conflict itself is surfaced as a diligence item, with both sources cited.
## Decision-ready, not just summarized
Every finding links back to the document and page that produced it, so a partner can verify any number in the output in one click. Nothing reaches the report on the platform's authority alone: conclusions are human-approved by the deal team, with the evidence trail attached. That traceability is what holds up in the investment committee — and later, when someone asks why the thesis said what it said.
The practical effect: the first structured, cited read of a data room takes hours instead of days, and senior time goes to judgment — the questions the documents raise — rather than to finding what the documents say.
---
## Company Comparable Analysis Automation
URL: https://www.botminds.ai/solutions/company-comparable-analysis-automation
> Extracts and normalizes operating metrics from filings, transcripts, and decks so analysts compare peers on one taxonomy — with every number cited to source.
Most of the effort in comparable analysis is extraction, not analysis. Analysts spend the bulk of their time hunting through 10-Ks, transcripts, and press releases for KPIs, then arguing spreadsheets into agreement — because every company reports differently, and mapping labels by hand is slow and subjective. This solution does the scavenging and the normalization, and leaves the judgment to the analyst.
## From filings to a common basis
The platform ingests public filings, earnings transcripts, investor presentations, and press releases across the coverage set. Because it reads financial context rather than matching keywords, it maps each company's reporting labels to a single standard taxonomy, aligns fiscal periods, converts currencies, and keeps as-reported and adjusted figures distinct. One issuer's "Subscription Revenue" and another's "Recurring Services" land on the same line by policy, rather than by whoever built the spreadsheet.
Depth stops being rationed. Manual bandwidth usually limits comparison to revenue and EBITDA; here, granular operating metrics — CAC, net retention, R&D efficiency, Rule of 40 — are extracted with the same effort as the top line. When a peer's metric moves, the surrounding context — an acquisition, a restatement, a definition change — is captured alongside it, so the "why" travels with the number.
## Numbers a committee can trust
Every extracted metric links to its exact source — the sentence in the transcript or the cell in the filing table — so any figure in the comp set can be verified in one click. Outliers and low-confidence extractions are flagged for human review rather than silently included; the analyst approves what the model surfaced before it ships. That is what makes the output usable in valuation work and investment memos, where a wrong comp is worse than a missing one.
Coverage scales the way headcount cannot: a cohort of 50 industry players is as tractable as the five direct competitors you track today, and the comp set stays current with each new filing instead of aging in a quarterly report.
---
## Company Filings Extraction
URL: https://www.botminds.ai/solutions/company-filings-automation
> Extracts, validates, and normalizes financial disclosures from 10-Ks, 10-Qs, and annual reports across formats and languages — cited, structured, model-ready.
The gap between a filing's release and usable data is where analysis teams lose. Key metrics sit buried in dense text and inconsistently formatted tables across 10-Ks, 10-Qs, and annual reports, and manual spreading caps how many companies a team can realistically cover. This solution closes the gap: filings in, validated structured data out, every number cited.
## Extraction that survives real filings
Real filings are messy — layouts vary wildly between issuers, tables break across pages, footnotes qualify the numbers above them. The platform ingests PDF, XBRL, and scanned documents across jurisdictions and languages, identifies financial statements, footnotes, and management commentary, and extracts figures with context-aware table reading. There is no template to build per issuer and none to maintain when a company redesigns its report. Line items then map to a standard taxonomy, so periods and peers land in one comparable schema instead of a per-company spreadsheet dialect.
## Validated, cited, defensible
Extraction without validation just moves the error downstream. The platform reconciles sub-totals, checks accounting logic, and scores its own confidence — anything ambiguous is flagged for a human before it enters your data set, while clean values flow straight through. That is what lets spreading run five times faster than manual entry without trading away the accuracy that high-stakes decisions require.
Every extracted metric links to its exact location in the original filing — click the number, see the source cell. Every extraction and correction is logged, which satisfies internal audit and keeps model inputs defensible long after the analyst has moved on. Built on a platform that has understood more than 1M+ documents, the practical outcome is coverage: teams spread more companies, faster, and analysts spend their time interpreting the numbers instead of retyping them.
---
## Company Profile & Tear Sheet Automation
URL: https://www.botminds.ai/solutions/company-profile-tear-sheet-automation
> Builds continuously refreshed company profiles and tear sheets from filings, news, and internal sources — every fact dated and cited to where it came from.
A tear sheet is simple to describe and expensive to keep honest: a one-page fact pack on a company, assembled from filings, news, presentations, and internal notes — and stale the week after it is written. Teams either burn analyst hours refreshing profiles nobody may read, or walk into meetings with facts from two quarters ago. This solution keeps the profile current by making the refresh automatic.
## A profile that maintains itself
The platform ingests the sources a profile depends on — regulatory filings, press releases, investor presentations, company websites, broker research, internal memos — and extracts the facts that belong on the sheet: financial highlights, ownership and management, business description, recent events, key metrics. Each fact is stored with its date and its source. When a new filing or announcement lands, the affected facts update; superseded ones are retired with their history intact, never silently overwritten.
Because assembly is automated, the house format holds by construction: the same sections, the same order, the same definitions across the entire coverage list. A reader who knows one tear sheet knows them all, and gaps are visible instead of papered over — if a fact could not be sourced, the sheet says so rather than guessing.
## Cited, dated, approved
Every fact on the page links to the document it came from and carries the date it was true. An analyst reviews and approves before the sheet goes to a committee or a client — the platform assembles, the human signs. That trail matters when a profile informs a credit decision or a deal conversation: months later, you can show exactly what was known, from where, as of when. Analyst hours move from maintenance to the companies that actually need thought.
---
## Competitive Insights Hub
URL: https://www.botminds.ai/solutions/competitive-insights-hub
> Monitors competitor filings, pricing pages, job posts, and announcements; separates strategic signals from noise and maps changes to a cited timeline.
Competitive intelligence fails in two opposite ways: analysts drown in thousands of alerts that are mostly noise, while the moves that matter — a silent pricing change, a reworded positioning page, a hiring spree in one engineering domain — never get announced at all. The Competitive Insights Hub fixes both. It watches more than a human team can, and surfaces less.
## Watching what competitors do, not just what they say
Agents continuously monitor competitor websites, regulatory filings, job boards, patent activity, and user forums. Change detection catches the stealth updates: pricing pages that quietly shift, terms of service that gain a clause, documentation that reveals an unshipped feature. Semantic analysis then does the triage a human analyst would — distinguishing a routine blog post from a strategic signal — so what reaches your team is already filtered for relevance.
Scattered observations become narratives. A job-posting cluster, a patent filing, and a partnership announcement that individually look minor combine into a coherent read on where a competitor is heading — with each contributing data point kept and cited.
## Current, shared, and sourced
Quarterly battlecards are stale by the time they circulate. The hub updates continuously: when a differentiator shifts, the change pushes to sales enablement tools and CRM immediately, so teams walk into deals with current intelligence. Because every insight links to a cached copy of the source page or document, claims are verifiable — strategy debates run on evidence rather than anecdotes from someone's inbox.
The hub also ends the silo problem. Product, sales, and strategy query one shared, sourced record of the competitive field — the same facts, the same timeline, the same evidence. Coverage extends to emerging players and indirect competitors without diluting analyst focus, because the watching is automated and only the judgment is human.
---
## Compliance Case Intelligence Hub
URL: https://www.botminds.ai/solutions/compliance-intelligence-hub
> Runs compliance investigations as structured cases — evidence gathered across systems, timelines assembled, narratives drafted, every step traceable.
Investigators lose most of their time before analysis starts. Evidence for a single case sits scattered across transaction logs, email archives, chat records, and voice recordings — finding it is the job, and analyzing it is what's left of the day. The Compliance Case Intelligence Hub inverts that: when a case opens, the evidence comes to the investigator.
## The dossier arrives before you do
On case creation, the platform queries every connected system — ERP, CRM, email archives, transaction stores — and assembles a case dossier before a human logs in. Entity resolution ties records to the right people and accounts; a link graph shows how the subject connects to other entities and previous cases, surfacing networks that reading files one at a time would miss. The timeline that used to be pieced together by hand in a spreadsheet builds itself from the evidence, in order, with each event tied to its source record.
## Consistent cases, defensible filings
When every investigator documents cases their own way, similar cases produce dissimilar files — which weakens SAR filings and frustrates regulators. The hub enforces one structure and one methodology, then goes further: it drafts the case narrative — who, what, where, why — directly from the collected evidence, and pre-populates the regulatory filing. The investigator's job becomes review and judgment: verify the facts, correct the read, approve or reject. Filing deadlines stop slipping on report-writing, and look-back or mass-remediation projects run through the same hub with progress visible across the whole team.
Every step is preserved: what data was pulled, what the investigator saw, what was decided and by whom. An auditor can replay the exact sequence behind any decision — no reconstructed justifications, no lost evidence. Drafts are always human-approved before anything is filed. For work that ends in a regulatory submission, that traceability is the point.
---
## Compliance Intelligence Engine
URL: https://www.botminds.ai/solutions/compliance-intelligence-engine
> Extracts obligations from regulations, maps them to internal policies and controls, and tracks adherence with evidence — a live, audit-ready record.
Compliance breaks when regulatory change moves faster than manual tracking. Updates arrive scattered across government sites, newsletters, and feeds; mapping them to internal policy is line-by-line work; and when an auditor asks for proof, the evidence is spread across inboxes and shared drives. The Compliance Intelligence Engine replaces that scramble with a maintained, queryable chain: regulation to obligation to policy to control to evidence.
## From legal text to trackable obligations
Agents continuously scan regulatory bodies across jurisdictions and do the first triage automatically — separating substantive rule changes from administrative noise, so compliance officers read what matters instead of everything. From the rules that matter, the engine extracts discrete obligations: the specific requirements inside a regulation, each one a trackable item with its citation.
Each obligation is then mapped to the internal policies and controls designed to satisfy it. That mapping is the engine's core asset. When a new mandate has no covering policy, the gap is visible immediately — flagged to the responsible officer with the regulatory citation attached — rather than discovered in an audit finding. When a rule changes, the affected policies and control owners are identified automatically, and impact assessment starts from a mapped list instead of a blank page.
## Adherence you can prove
Obligations without evidence are promises. The engine connects each control to its operational proof, maintaining the link between what the regulation requires, what the policy says, and what the organization actually did. Deviations surface as they occur. Because the record is continuous, you can demonstrate compliance as of any point in time — how the organization met a requirement last March, with the evidence that existed then.
Human judgment stays where it belongs: officers review flagged gaps, approve policy mappings, and own remediation. The engine does the reading, the mapping, and the record-keeping — the parts that were never a good use of a compliance officer's time.
---
## Contact Center Automation
URL: https://www.botminds.ai/solutions/contact-center-automation
> Reads incoming cases across email, chat, and voice; classifies intent and urgency, routes work to the right resource, and guides agents with context.
First-in, first-out routing treats a frustrated top-tier account and a routine password reset as equals. Meanwhile the context an agent needs — CRM history, usage data, billing records — sits in separate systems, and resolving a case starts with toggling between screens to reconstruct the customer's story. Contact Center Automation fixes the two failures behind most bad service: work going to the wrong place, and agents working without context.
## Routing on intent, not arrival order
The platform reads every incoming signal across email, chat, and voice, and determines intent, urgency, sentiment, and customer value against the history behind the message — before the case enters a queue. Low-touch inquiries resolve through automated workflows. Frustrated customers and high-value accounts route to senior agents immediately. Everything else goes to the right skill group with priority already set. Routing logic, prioritization rules, and agent guidance are configured without code, so operations teams tune the behavior themselves as volumes and products change.
## Context and guidance at the moment of contact
When a case reaches an agent, the story arrives with it: unified context pulled from CRM, usage logs, and billing systems into one view. As the conversation runs, the platform pushes next-best-action recommendations grounded in that live context, so different agents converge on the same good answer instead of improvising ten different ones. Every recommendation and decision is logged, which makes the consistency a governance win as well as an experience win.
Retention stops being reactive. Usage drops and sentiment dips trigger customer-success workflows as they happen, well before the cancellation request — support and success operating on one shared logic layer instead of finding out from each other after the fact. Interaction spikes are absorbed by better triage rather than emergency headcount.
---
## Contract Command Center
URL: https://www.botminds.ai/solutions/contract-automation-and-intelligence
> Ingests contracts in any format, extracts terms, obligations, and risks with clause-level citations, and monitors renewals and deviations at portfolio scale.
Most companies cannot answer basic questions about their own contracts: which agreements auto-renew next quarter, which carry non-standard liability terms, which counterparties hold change-of-control rights. The agreements exist — trapped in PDFs, inboxes, and shared drives — but the knowledge in them is unsearchable. The Contract Command Center turns that dark archive into structured, queryable, monitored data.
## From static documents to structured terms
The platform ingests agreements of any type — NDAs, MSAs, SOWs, amendments — from any source, including legacy archives that predate your current systems. Without templates or rules to configure, it identifies parties, definitions, key dates, standard clauses, and obligations, and every extracted term carries a citation to the exact provision it came from. A GC can click from a data point to the clause behind it; a migration or M&A team can analyze an acquired portfolio for assignment provisions and change-of-control risks in days instead of a quarter.
## Review that holds the line — before and after signature
Manual redlining varies by attorney, and risky terms slip through on the tenth NDA of the day. The Command Center compares every incoming draft against your corporate playbook and flags deviations and high-risk terms for counsel review — routine agreements clear quickly, and legal attention concentrates where the actual risk is. Sales cycles stop stalling on standard paper, and the review standard stops depending on who was assigned the file.
Post-signature is where spreadsheet tracking fails: auto-renewals fire unnoticed, milestones pass, obligations go unmet. Here, every date and obligation extracted at ingestion becomes a monitored event with alerts ahead of the deadline. Structured contract data flows into CLM, ERP, and CRM systems, so commercial teams work from one source of truth instead of three inconsistent ones. Every extraction, flag, and approval is logged — counsel decides, and the record shows it.
---
## Contract Risk & Obligation Tracking
URL: https://www.botminds.ai/solutions/contract-risk-and-obligation-tracking
> Extracts obligations, commitments, and risk clauses from contracts, then tracks deadlines and deviations — every item mapped to its source clause.
A signed contract is a list of promises — payment terms, service levels, indemnities, renewal windows — and most of them go straight into a repository nobody rereads. The promises stay binding. Only the attention lapses.
## From signed pages to a tracked register
This solution reads every contract, amendment, and schedule, extracts the clauses that carry commercial or legal weight, and converts each into a structured obligation record: what was promised, by whom, by when, under what conditions. Every record keeps a link to the exact clause it came from, so any obligation can be verified against the original language during a review or an audit. Legal sees risk classification and defensible compliance evidence; commercial sees deadlines, performance against commitments, and renewal exposure — both working from the same records and the same source clauses, with no parallel spreadsheets drifting apart.
## Deadlines, deviations, and evidence
Extraction is the start. The platform monitors timelines, dependencies, and compliance status continuously. A deliverable slips, a certificate lapses, a renewal window opens — the responsible owner is alerted while there is still time to act. Deviations route as exceptions to the right team, and every resolution is documented against the clause that triggered it, building a complete lineage of contractual actions.
That lineage is what makes the system governed rather than merely automated. When a counterparty disputes a service credit, or an auditor asks how a renewal decision was made, the answer is the clause, the record, and the log — assembled in the course of normal operation. Nothing material is auto-actioned into the dark: the platform does the reading, tracking, and flagging, while escalation and remediation decisions stay with the people accountable for them.
---
## Conversation Intelligence Suite
URL: https://www.botminds.ai/solutions/call-transcripts-analysis-automation
> Reviews every sales and support conversation — calls, chats, email — and turns each one into scored, evidence-linked performance and compliance data.
Manual QA teams review a sample — typically under 2% of calls and chats. The other 98% is where compliance failures, churn signals, and lost revenue hide. The Conversation Intelligence Suite reviews all of it: every call, every chat, every support email, converted into structured, queryable performance data.
## Every interaction, structured
The suite ingests voice and text interactions across telephony, email, and chat, transcribes with speaker separation, and redacts PII on the way in. Then it does what a QA analyst does — on every interaction instead of a sample. It verifies that mandatory disclosures, mini-Miranda language, and privacy statements were actually spoken. It scores the agent against your rubric. It tags objections, competitor mentions, and pricing pushback, and tracks sentiment as it shifts through the conversation.
The output is structured data — scores, flags, topics, outcomes — correlated with business results like closed-won deals and CSAT, so leaders can see which conversation behaviors drive success and which quietly lose accounts. One rubric applies to everything, so a score means the same thing across teams and weeks, and agents stop getting conflicting feedback based on who happened to listen.
## Same-day coaching, governed evidence
Calls where an agent missed the script or struggled with an objection route to their manager the same day, with the exact moment in the recording linked — while the deal is still live, and while a new hire can still correct course. A score nobody can verify is an opinion; here, every flag and score links back to the exact span of transcript that produced it, and every action is human-approved — the platform surfaces and drafts, your team decides. That evidence trail makes the output usable for compliance monitoring and dispute resolution, and volume spikes — holiday seasons, product launches — get the same full coverage without adding QA headcount.
---
## Corporate Actions Monitor
URL: https://www.botminds.ai/solutions/corporate-actions-process-automation
> Normalizes corporate action announcements from messages, vendor feeds, and exchange PDFs into one validated event record, with lineage to each source.
Corporate action announcements arrive as ISO 15022/20022 messages, vendor feeds, exchange PDFs, and custodian emails — and they routinely disagree with each other. Analysts burn hours cross-referencing sources to establish the truth while election deadlines on voluntary events tick down.
## One validated record per event
This solution ingests every channel, normalizes each announcement into a common event structure, and compares sources field by field. Where sources agree, the validated master record — the golden copy — builds itself. Where they conflict, the discrepancy is isolated and routed to a senior analyst with every version presented side by side. Standard mandatory events process touchless; analyst time goes only to the events that genuinely need judgment, and every one of those calls is human-approved before it moves downstream.
Complex events are where manual processing hurts most. A misread ratio on a rights issue, a missed deadline on a Dutch auction or spin-off — each is a direct financial liability. The platform validates dates, checks ratios, and reads the narrative text of announcements against prospectus terms, flagging anything that deviates from the historical pattern for that event type.
## Lineage down to the field
Every field in the master record carries lineage to the source document that supplied it, so an auditor — or a doubtful trader — can trace any date or ratio back to the original announcement in seconds. The same validated record feeds trading desks, risk teams, and client reporting at the same time, replacing the copy-paste chains that let versions drift. Seasonal spikes in dividend and proxy season are absorbed by the platform rather than by temporary staff, and the audit trail is a by-product of normal operation, ready the moment anyone asks.
---
## Covenant Monitoring & Compliance Surveillance
URL: https://www.botminds.ai/solutions/covenant-monitoring-compliance-surveillance
> Reads credit agreements and borrower financials to test covenants, flag breaches and late reporting, and track compliance trends across a portfolio.
A covenant breach almost never announces itself. A compliance certificate arrives a few weeks late. Leverage creeps up two quarters in a row. Headroom that was comfortable at origination quietly compresses. Manual monitoring catches these things when an analyst happens to look — and across a growing portfolio, nobody can look everywhere at once.
## The agreement becomes the monitoring contract
The platform reads each credit agreement and its amendments to extract the covenant package: definitions, thresholds, test dates, cure periods, and reporting obligations. That extracted package is what gets enforced. As compliance certificates and borrower financials arrive, they are captured and spread — 5× faster than manual spreading — and each covenant is tested exactly as its agreement defines it, with the negotiated add-backs and carve-outs intact. Waivers and amendments are recorded against the covenants they modify, so the tested threshold is always the one currently in force.
Surveillance covers three failure modes. Hard breaches are flagged the moment a tested ratio crosses its threshold. Reporting failures are flagged when a certificate or statement is late or missing. Deterioration is flagged as a trend — headroom narrowing across periods — so the borrower conversation happens before the breach. Every alert routes to the credit team, and every breach determination is confirmed by a named analyst before it drives action.
## Regulator-ready by construction
Every number in a covenant test is cited to its source page in the certificate or financial statement it came from. When an examiner or internal audit asks how a compliance status was determined, the evidence is the extraction, the calculation, and the approval log — assembled continuously as tests run rather than reconstructed under deadline. Credit, risk, and operations work from one covenant record per facility, portfolio-wide.
---
## Credit File Assembly & Underwriting Readiness
URL: https://www.botminds.ai/solutions/credit-file-assembly-underwriting-readiness
> Assembles borrower, collateral, and supporting documents into one complete, indexed credit file — with gaps flagged before underwriting opens it.
Underwriting speed is set long before an underwriter touches the deal. It is set by how fast a complete, coherent credit file comes together — borrower financials, tax returns, bank statements, collateral appraisals, insurance, entity documents — arriving across email, portals, and internal systems in no particular order. Assembling that file by hand is slow and unreliable: the expensive failure is the underwriter who gets forty pages in before discovering the guarantor's tax return is missing or the appraisal is two years old.
## The file builds itself in checklist order
The platform owns the assembly. Every inbound document is classified against the required-documents checklist for the product and deal stage, key data is extracted into structured fields, and the file builds in the order the checklist defines — whatever order documents happen to arrive in. Gaps become visible the day they exist, while there is still time to chase them.
A stack of documents is still short of a decision-ready file, so the platform cross-checks the package as it grows: borrower names and entity identifiers reconciled across documents, tax years matched to the checklist requirement, amounts and dates compared where they should agree. Mismatches and stale items are flagged immediately instead of surfacing as underwriting rework. Every extracted data point is cited to its source page, so anything in the file can be verified against the original in one step.
## What underwriting receives
One indexed file per deal: complete against the checklist, internally consistent, with exceptions explicitly noted. Readiness itself stays a human call — the platform assembles the evidence and states what is present, what conflicts, and what is outstanding, and the team decides when the deal moves. The audit trail of who supplied what, when, and what changed comes free with the process.
---
## Credit Memo Generation
URL: https://www.botminds.ai/solutions/credit-memo-generation
> Drafts credit memos from spread outputs, borrower documents, and risk signals — every figure cited to its source page, every draft analyst-owned.
A credit memo is mostly transcription: numbers from the spreads, ratios from the model, facts from the application, collateral values from the appraisal, risk language adapted from the last similar deal. Analysts spend days assembling what is already known before they spend hours on what actually requires judgment. This solution reverses that split. It gathers borrower documents, spread outputs, and risk signals into one working set and writes the first draft — structured to your memo template, section by section.
## A draft you can interrogate
The difference between a useful draft and a dangerous one is verifiability. Every figure in the generated memo is cited to its source: the statement page behind a revenue number, the spread cell behind a coverage ratio, the appraisal behind a collateral value. An analyst reviewing the draft clicks through any number to the page it came from and verifies the claims that matter in minutes. Because the spreads themselves are produced 5× faster than manual spreading, the draft is ready while the deal is still fresh rather than after a week in the queue.
## The analyst owns the recommendation
The platform writes the assembly; it makes no credit decision. Risk factors and mitigants are surfaced from the file as candidates, and the analyst edits, challenges, and rewrites until the memo says what they are prepared to defend in committee. Every memo is human-approved before it moves, and the final document carries its full evidence trail — which is what makes it durable in front of credit committee, internal audit, and examiners alike. Consistency improves as a side effect: every memo in the portfolio is built on the same structure, the same definitions, and the same standard of citation.
---
## Customer Contract-to-Support Linkage
URL: https://www.botminds.ai/solutions/contract-to-support-linkage
> Maps SLAs, entitlements, and penalty clauses from signed contracts to live support tickets, so teams service what was sold — with clause-level proof.
Service terms live in signed MSAs, SOWs, and addendums locked in a legal repository. Support agents live in a ticketing system that has never read them. The result is predictable: premium support delivered to standard-tier customers, penalty clauses discovered only after the SLA was missed, and simple tickets escalating because nobody can produce the agreed terms fast enough.
## Entitlement checks before work begins
This solution reads customer contracts and every amendment, extracts the terms that govern service — response-time guarantees, support tiers, included modules, penalty and credit clauses, renewal and expiry dates — and maps them to the customer profile in your ticketing system. When a ticket arrives, the agent checks it against the customer's actual entitlements before anyone starts work. Covered requests proceed with the right priority and the right clock. Out-of-scope requests are flagged with the clause that says so — turning accidental over-servicing into a deliberate commercial decision, and a contract gap into an upsell conversation instead of quiet revenue leakage.
Disputes shrink the same way. Ambiguity over renewal dates, credits, or coverage limits stops being an argument when the agent retrieves the exact clause and page number in seconds. Support answers with evidence, and Legal stops fielding routine lookup requests from the service floor.
## Why governed matters here
Entitlement decisions touch revenue, margins, and customer relationships, so every check leaves a trace: the source clause, the extracted term, and the decision are logged together. Complex, custom-negotiated support packages scale across thousands of accounts because the system of record is the signed contract itself — amendments and addendums included — and any agent can prove what was sold. Support operates on the signed reality.
---
## Customer Insights Engine
URL: https://www.botminds.ai/solutions/voice-of-customer-automation
> Turns calls, tickets, surveys and social posts into structured, quantified customer intelligence — with every theme traceable to real feedback.
Voice-of-customer programs fail on volume, not intent. The feedback exists — in call
recordings, support tickets, survey comments, chat logs — but manual analysis cannot keep
pace, so tagging is inconsistent, emerging issues get mislabeled, and the complaint that
predicted a churned account is found afterward, in the post-mortem. Product teams hear
about a problem weeks after the tenth customer mentioned it.
The Customer Insights Engine reads it all. It ingests interactions from every channel,
transcribes and translates audio, and classifies each piece of feedback into specific
topics and sub-topics — capturing intent rather than matching keywords. Non-actionable
noise is filtered out, and personally identifiable information is detected and redacted
before analysis begins, so the pipeline is privacy-safe by default.
## From qualitative noise to operational metrics
The output is numbers a business can run on. Complaint themes are counted and trended, so
a spike in "login failure" mentions alerts engineering the day it starts rather than at
the quarterly review. Feature requests are quantified by volume and sentiment, giving
product a data-backed roadmap argument. Feedback trends correlate with operational
metrics, which is how you learn exactly why an NPS score moved — and churn-risk signals
surface while there is still time to intervene. Insights route directly to the department
that owns them, without a reporting layer in between.
## Every theme has receipts
Aggregated sentiment is easy to dismiss until you can read the underlying feedback. Here,
every theme, score and alert links back to the actual interactions that produced it — the
transcript passage, the ticket, the survey comment. When the dashboard says billing
complaints doubled, the evidence is one click away, redacted but real. That traceability
moves customer insight from an interesting chart to a basis for decisions: teams act on
it because they can verify it.
---
## Data Room Intake & Diligence Organization
URL: https://www.botminds.ai/solutions/data-room-intake-diligence-organization
> Ingests CIMs, financials, presentations, and contracts from any data room into one indexed diligence workspace with source-linked extraction.
Data rooms arrive as they were assembled: thousands of files, inconsistent naming, CIMs next to scanned contracts next to half-labeled spreadsheets. The first week of diligence is usually spent building an inventory of what is even there — time that comes straight out of the review period.
## Day one, not week two
The platform ingests the room as delivered, identifies each file by reading its content rather than trusting its filename, and maps every document to the diligence checklist item it satisfies. What you get on day one is what teams normally have by week two: a complete, classified inventory, including a precise list of what the seller has not provided — while there is still time to ask for it.
Classification is the floor. Agents extract the material substance — financial figures from statements and models, key terms from contracts, dates and parties from corporate records — into structured records, each linked to the exact page it came from. Everything else becomes searchable by concept, so "termination rights in customer contracts" finds the clauses whether or not the word appears in the filename or even in the clause. Analysts stop skimming folders and start answering questions.
## Defensible conclusions
Diligence conclusions end up in front of investment committees, lenders, and lawyers, so provenance is the working standard. Every extraction in the workspace traces to its source document and page, and material findings are reviewed and approved by the team before they harden into the deal narrative. When a number in the model is challenged, the answer is one click away — the page it came from, in the document the seller provided. The same workspace serves the whole deal team, so credit, legal, and financial workstreams stop maintaining three private inventories of the same room.
---
## Document Classification & Intake Intelligence
URL: https://www.botminds.ai/solutions/document-classification-intake-intelligence
> Classifies inbound borrower documents against your checklist, extracts key identifiers, and builds a structured intake package underwriting can trust.
Every lending workflow inherits the quality of its intake. Borrower documents arrive as they always have — a portal upload here, an email attachment there, a 40-page scan containing three different documents — and someone has to turn that pile into an organized package before any real work starts. Done manually, it is slow and inconsistent. Done wrong, the cost lands downstream: an underwriter discovers mid-review that the "2024 return" is actually 2022, and the deal loses a week.
## Classified by content, slotted by checklist
The platform reads every inbound document and classifies it by content, ignoring the filename. A K-1 is recognized as a K-1 whether it arrives alone, buried in a combined PDF, or as a photographed page. Multi-document files are split, duplicates are detected, and each item is stamped with the identifiers that matter: borrower, entity, tax year, statement period.
Knowing a document is a bank statement is half the job; the other half is knowing whether it is the bank statement the deal needs. Classification runs against the intake checklist for the specific loan program, so each document lands in its checklist slot and the gaps become visible in real time. Wrong-year returns, missing schedules, and stale statements are flagged the day they arrive, while the borrower conversation is still easy.
## Trust through traceability
Every classification decision is auditable: what the document was identified as, what was extracted, and with what confidence. Low-confidence items route to a person instead of guessing — the platform's job is to be reliably right or honestly unsure. The result handed to underwriting is a structured intake package where every document is what the label says it is, and can be proven so.
---
## Document Command Center
URL: https://www.botminds.ai/solutions/intelligent-document-management-system
> One control plane for enterprise documents — ingest from every channel, classify, extract and route, with a live view of volume, backlog and exceptions.
Document operations break in predictable ways. Files arrive through email, portals, SFTP
and scanners with no single point of receipt, so nobody can say whether a document ever
landed. Routing depends on a person reading each file, so the "front door" becomes the
bottleneck for everything downstream — accounts payable, onboarding, claims. The data
itself stays trapped in PDFs, re-keyed by hand into the systems that need it. And ops
leaders manage all of this blind, with no live view of volume or backlog.
The Document Command Center is the control plane that replaces that. Every channel feeds
one entry point where each file is logged, classified and tracked from receipt to
resolution. Agents identify the document type — invoice, form, contract, technical
drawing — and extract structured data regardless of layout, language or image quality.
Clean data flows into your ERPs, CRMs and ECMs; documents route to the right queue by
content and priority, not by whoever opened the mailbox.
## Built for the exception path
Real document streams are messy, and a system that pretends otherwise creates silent
errors. The platform validates extracted data before it enters downstream systems,
flags duplicates, and routes low-confidence files to a human review queue rather than
guessing. Every action — classification, extraction, correction, routing decision — is
recorded in a full audit trail, so you can trace any document from arrival to the business
action it triggered.
## Operational visibility as a feature
Because every document passes through one governed layer, the operational picture comes
for free: live throughput, queue depths, exception rates, and bottlenecks visible as they
form rather than in next month's retro. Teams scale volume by tuning routing rules and
review thresholds, not by adding administrative headcount. That is the document-to-decision
model applied to the whole document estate: structured, traceable, and measurable end to end.
---
## Document Intake Hub
URL: https://www.botminds.ai/solutions/mail-room-automation
> A single front door for inbound documents — ingests every channel, classifies and cleans each file, then routes it to the right workflow with a receipt log.
Every document-heavy operation has a front door, and most front doors are manual.
Files arrive by email, API, SFTP and web portal; someone opens each one, figures
out what it is, and forwards it to the right queue. That mailroom function is
invisible until it fails — a lost attachment, an urgent notice sitting unread, a
month-end spike that buries the team — and by then the damage is downstream, in
every process that started late or started with bad data.
## One pipeline for every channel
The Document Intake Hub replaces the manual front door with a single governed
pipeline. It monitors every inbound channel simultaneously, logs a receipt for
each file, and gets the document ready for work: pages rotated, noise removed,
integrity validated, so OCR and extraction downstream start from clean input.
Classification identifies what each document is — invoice, contract, notice,
correspondence — and intelligent separation splits multi-document files into their
parts, distinguishing main documents from attachments.
Routing is where intake becomes operational. Each classified document is
dispatched to the correct department or workflow without a human sorting step, and
header-level metadata is extracted on the way through so high-urgency items jump
the queue. Corrupt or unrecognizable files stay visible — they route to a named
resolution queue, logged and accounted for.
## Control at the entry point
Operations leaders finally see the front door. Live intake metrics show what is
arriving, from where, and where the backlog sits, so resource planning runs on
measured volume. Month-end and seasonal spikes flow through the same pipeline
without temporary staff.
Governance starts at intake: every receipt, classification and routing decision is
logged and traceable, so when someone asks where a document went — a customer, an
auditor, a downstream team — the answer is on record. Clean, classified,
accounted-for data at the entry point is what makes every document-to-decision
process behind it trustworthy.
---
## Document Intelligence Repository
URL: https://www.botminds.ai/solutions/document-intelligence-repository
> Turns unsearchable PDFs, scans, and shared-drive files into a classified, searchable repository with automatic metadata, lineage, and audit history.
The bulk of an organization's documents — scanned PDFs, image files, old Word files on shared drives — are effectively dark: keyword search cannot see inside them, and the manual tagging meant to compensate never survives contact with real workloads. People tag inconsistently or stop tagging, duplicates multiply across drives and cloud folders, and teams end up negotiating against the wrong version of a contract or citing a policy superseded a year ago.
## Read, classified, connected
This solution reads every file that enters the repository. It identifies that a file is a master services agreement, who the parties are, when it was signed, and what its key terms say, then applies that metadata automatically and consistently — no tagging fatigue, no folder-taxonomy debates, no drift. Because the repository understands content, retrieval stops depending on remembering the right keyword: a query like "the contract with the indemnity clause about flooding" finds the clause even when those exact words never appear together. Duplicate and near-duplicate detection surfaces the governing version, and related documents link automatically — an invoice to its purchase order to the contract behind both — so context travels with the file instead of living in someone's head.
## Governance you can demonstrate
For regulated content, storage without control is a liability. Document-type-driven retention policies apply themselves on ingestion, sensitive content stops hiding in forgotten folders because every file has been read and classified, and each document carries its full lineage: where it came from, how it was classified, what changed, and who touched it. When an auditor asks for the record and its history, the answer is a retrieval, not a search party. Legal, finance, and operations work against the same understood corpus — documents connected by business context rather than folder hierarchy.
---
## Document Request & Collection
URL: https://www.botminds.ai/solutions/document-request-collection
> Tracks required borrower documents across channels and deal stages, requests exactly what is missing, and verifies each file against the checklist.
## Chasing documents is a job nobody staffed
Between application and underwriting sits an unglamorous grind: knowing which documents
each deal still needs, asking the borrower for them, recognizing what actually came back,
and asking again. Done by hand it fills inboxes and stalls pipelines, and the requests
borrowers receive are often so vague — "please send financials" — that the wrong documents
arrive and the cycle restarts. Every day lost here is a day added to time to decision.
This solution runs that grind as a managed process. The required-documents checklist for
each product and stage drives everything: what gets requested, what counts as received,
and what remains outstanding. Borrowers get specific, plain-language asks — the 2024
federal return for the operating entity, the January-through-June statements for the
account that matters — which is the single biggest lever for getting the right file the
first time.
## Verified on arrival, logged for good
Collection without verification just moves the problem downstream. Each incoming document
is matched to its checklist item and checked immediately: correct type, correct period,
correct entity, all pages present, actually readable. A statement from the wrong account
or a return from the wrong year is caught and re-requested the same day, while the
borrower is still engaged — long before an underwriter would have found it.
Every request, receipt, verification, and follow-up is logged against the deal, so the
state of any package is a fact you can look up. For regulated lending, that log doubles
as evidence: what was asked for, when it arrived, and how it was checked. Loan teams stop
relaying attachments and start managing exceptions — the deals that genuinely need a
human call.
---
## Due Diligence & M&A Document Analysis
URL: https://www.botminds.ai/solutions/due-diligence-and-m-and-a-document-analysis
> Reviews every contract, filing, and disclosure in the data room, surfaces material risks like change-of-control triggers, and cites each finding.
A data room holds tens of thousands of files, and the deal clock allows for reading a fraction of them. The standard compromise is sampling — senior counsel reviews the material contracts, and everything else gets a skim or nothing. The risks that kill value after closing are precisely the ones sampling misses: a change-of-control trigger in a mid-size customer contract, an uncapped indemnity in a supplier agreement, an IP assignment gap in an early employment file.
## Read everything, escalate judgment
This solution reads the room as delivered — any provider, any structure, any language. Every document is classified by content, and 100% of the contracts are reviewed against the deal-specific risk matrix, each red flag anchored to the exact clause that raised it. Routine documents with standard terms clear automatically; non-standard, ambiguous, and high-exposure clauses route to senior counsel with the language highlighted and context attached. Every red-flag determination that reaches the report is human-approved — counsel spends hours on the fifty clauses that matter instead of weeks on the thousands that do not. When the seller's answers need checking, semantic search locates evidence for representations and warranties across the whole room in seconds.
## From findings to a closing position
Fragmented attorney notes become a uniform, exportable risk report and disclosure schedule, every item citing its source clause — which changes negotiating posture, because each finding arrives with proof. Contracts requiring consent or assignment are tagged during diligence, so the Day 1 execution plan is a by-product of the review rather than a post-close scramble. What used to surface as an integration surprise surfaces as a negotiating point instead.
---
## Earnings Call & Transcript Intelligence
URL: https://www.botminds.ai/solutions/earnings-call-transcript-intelligence
> Turns earnings calls and transcripts into structured signals, themes, and cited talking points for credit, risk, and research teams.
Every quarter the same pile arrives: call transcripts, prepared remarks, Q&A sessions, investor decks, and the filings behind them. The signal is in there — guidance changes, margin commentary, management hedging — but extracting it by hand takes days, and the result depends on who did the reading.
## What it does
Botminds ingests transcripts and related documents as they publish, then agents extract what matters: stated guidance, KPI mentions, shifts in tone between prepared remarks and the Q&A, and themes that recur across quarters. The output is structured — a signal table, a theme map, and analyst-ready notes. It reads call transcripts, digital or scanned, alongside 10-Ks, 10-Qs, press releases, and investor presentations, and normalizes them into one comparable structure per company, per quarter.
Every extracted claim links back to the exact passage in the source. An analyst verifies a statement in one click instead of re-reading forty pages to find where the CFO said it.
## Governed at scale
A misread of management commentary moves a credit view or an investment call. So agents draft, classify, and cite — and a human approves before anything flows downstream. The full trail is stored: source passage, extraction, reviewer, decision. When a committee asks where a signal came from, the answer is a page reference.
Teams covering dozens of names get what manual reading can never give them: the same signal definitions, the same taxonomy, and the same evidence standard applied to every company. When a new quarter lands, the same pipeline runs and the deltas against last quarter surface on their own — guidance raised or walked back, themes that appeared or vanished, language that hardened or hedged. Analysts spend their time on judgment, not on transcription.
---
## Earnings Commentary Generation
URL: https://www.botminds.ai/solutions/earnings-commentary-generation
> Drafts earnings summaries and commentary from financial results and KPI baskets, with every figure cited and every draft human-approved.
Earnings commentary is skilled work built on unskilled hours. Analysts spend the crunch nights of every reporting cycle restating tables in prose: revenue moved this much, margin compressed that much, three segments beat and one missed. The judgment is in the framing; the hours go to the mechanics.
## What it does
Botminds takes the mechanics. Feed it the earnings release, the financial statements, and the KPI basket you track, and agents compute the movements — quarter over quarter, year over year, actual versus guidance — and draft the commentary around them. Drafts follow your house structure and terminology because they are built from your prior commentary and your KPI definitions rather than a generic template.
Each number in the draft is cited to the statement line or release paragraph it came from: click the figure, see the source. Reviewers verify the claims that matter and skip the archaeology. The result is a first draft in minutes — analysts start from a near-complete draft and spend their time on what the numbers mean.
## Governed by design
No draft self-publishes. Commentary moves through an approval flow: agents write, an analyst reviews and edits, a named person signs off, and the platform records who approved what and when. That trail matters when commentary feeds investor materials, credit reviews, or anything a regulator might later ask about.
The pattern holds at any scale. Whether you run one entity's earnings or commentary across an entire coverage list, the same pipeline applies the same movement math, the same house structure, and the same evidence standard, every cycle — so quality stops depending on which analyst drew the crunch-night shift.
---
## eDiscovery Evidence Engine
URL: https://www.botminds.ai/solutions/e-discovery-process-automation
> Culls, clusters, and ranks case data from emails, chats, and files so legal teams review what matters — privilege screened, chain of custody intact.
Modern matters arrive as terabytes: email archives, Slack and Teams exports, mobile backups, cloud drives. Reading it all linearly stopped fitting inside any real deadline or budget years ago, and large review teams grinding through mundane documents miss context anyway — fatigue is a property of humans at volume. The working alternatives are defensible automation or sampling luck.
## Cull first, then find the story
The engine ingests the full collection while preserving chain of custody for every file. Culling starts immediately: exact duplicates removed, email threads collapsed so each conversation is read once, near-duplicates grouped, conceptually similar documents clustered. The reviewable population shrinks drastically before a single attorney hour is spent, and password-protected or corrupt files are segregated for technical handling instead of silently vanishing from the record.
Early case assessment stops being a weeks-long dig. Communication patterns, key actors, and dominant topics are visible within hours of collection — enough to judge case viability and settlement posture while options are still open. Relevance ranking puts the documents most likely to matter at the front of the review queue, and potentially privileged attorney-client communications are flagged and walled off for focused second-tier review: the difference between a privilege log and a privilege waiver.
## Defensibility is the product
Everything the engine does is designed to be examined by opposing counsel. Culling criteria, search methodology, and ranking decisions are captured in automated audit reports; custody is traceable from collection to production; and production decisions remain with the legal team — the engine narrows, ranks, and documents, and humans decide what leaves the building. Multi-terabyte class actions and regulatory inquiries run on the same machinery as routine matters, without the review-team surge.
---
## Emerging Trends Intelligence Hub
URL: https://www.botminds.ai/solutions/emerging-trends-intelligence-hub
> Monitors filings, publications, and news for evolving themes, classifies signals by materiality, and traces every insight to a verified source.
Market monitoring breaks at scale. Millions of articles, posts, and releases publish daily; the material events hide inside them; and by the time an analyst has read a headline, checked the source, and found the right person to tell, the window to act has often closed.
## Meaning, then materiality
The hub works on what an event means. Agents ingest from premium feeds, the open web, filings, and social channels, deduplicate the noise, resolve entities, and classify each event — an acquisition, a leadership change, a supply disruption, a regulatory shift. Every signal is scored for materiality and linked to the specific things you track: your suppliers, your borrowers, your investments, your competitors. Coverage spans more than 100 languages with instant translation, so a regional story reaches you without a regional analyst. Routine press releases stay quiet; strategic pivots get through.
When the hub confirms a relevant event, it can trigger the work that follows: open a risk assessment on the affected vendor, update a forecast input, draft the briefing note for leadership. Triggers are configured in a few clicks — no code involved.
## One verified stream, one shared truth
Every insight carries its source, and reputable outlets are distinguished from unverified rumors before anything is flagged. Risk, strategy, and communications teams work from the same event stream and the same facts, which prevents the familiar failure of three departments reacting to three different versions of the same story. When someone asks why an alert fired — or why it stayed quiet — the answer is the source article, the classification, and the rule that matched, all on record.
---
## ESG Intelligence Workbench
URL: https://www.botminds.ai/solutions/esg-intelligence-workbench
> Extracts environmental, social, and governance data from disclosures, maps it to CSRD, TCFD, SASB, and GRI, and links every metric to its source page.
## What it does
The metric you need is on page 187 of a sustainability PDF, in a footnote, in the
company's own units. Multiply that by a coverage universe and a set of frameworks that
change every year, and ESG analysis becomes a data-entry job that senior analysts do badly
because nobody can do it well by hand.
The workbench ingests sustainability reports, proxy statements, annual reports, and
supplier audits, and extracts the ESG data buried in them — emissions figures, diversity
statistics, governance policies, Scope 3 estimates. It distinguishes a measured metric
from a stated ambition, converts units, tracks history, and structures everything into one
model, however the company chose to report it. Framework alignment happens in the same
pass: extracted metrics map to CSRD, TCFD, SASB, GRI, and ISSB requirements, so a new
regulation becomes a portfolio scan — which holdings are missing which required
disclosures — instead of a re-tagging project.
## Claims, checked against numbers
Self-reported highlights are where greenwashing lives. Because the workbench holds both
the pledges and the numbers, it flags the gaps between them: a net-zero commitment beside
capital expenditure that says otherwise, a policy statement with no metric behind it.
Analysts see the inconsistency with both sources cited and decide what it means.
Every metric links to the page and sentence it came from — click a number, see the
disclosure. Flagged items route to a human steward before they enter reporting, and the
review trail — source, extraction, reviewer — stays attached to the data for as long as
you hold it. That is what makes a rating defensible to an auditor, a regulator, or an
investment committee.
---
## Exception Detection & Approval Workflows
URL: https://www.botminds.ai/solutions/exception-detection-approval-workflows
> Finds policy exceptions in loan files and credit terms, then routes each one through a governed approval path with a complete decision trail.
Policy exceptions rarely announce themselves. They surface mid-review when a careful analyst catches one, or after close when an auditor does. Both are expensive — the first as rework and delay, the second as a finding.
## Catch exceptions before they cost you
Botminds reads the loan file the way your policy team would, if they had time to read every file. Agents compare the terms in loan agreements, term sheets, and credit memos against the credit policy rules that apply — pricing floors, LTV and DSCR limits, collateral requirements, guarantor conditions, documentation standards — and flag every deviation as a named exception. Each flag cites both sides: the clause in the document and the policy rule it breaks. Reviewers see exactly what tripped, where, and why, in minutes instead of at the end of a manual read. When the policy changes, the change is made in one place, and every file after that is measured against the new standard.
## Governed routing, with the trail regulators expect
Detection is half the job; disposition is the other half. Each exception routes to the approver whose delegated authority actually covers it — severity, exposure, and product determine the path. Approvers see the exception, the evidence, and the file context in one place; they approve, decline, or escalate, and the decision is recorded with a rationale. Nothing moves downstream on an unresolved exception, and nothing gets waved through without a name attached.
When an examiner asks how many pricing exceptions you approved last quarter, who approved them, and on what grounds, the answer is a query. Every exception carries its full history — detection, evidence, routing, decision, approver — so portfolio-level exception reporting is a report you run, and every individual decision can be reconstructed exactly as it happened.
---
## FHIR Data Harmonizer
URL: https://www.botminds.ai/solutions/fhir-compliance-automation
> Converts fragmented clinical data — HL7 V2, C-CDA, PDFs, CSVs — into validated FHIR R4 resources with terminology mapping and full trace links.
Patient data is locked in whatever format each system happened to speak: HL7 V2 from one EHR, C-CDA from another, lab results as PDFs, registries as CSVs. Assembling a longitudinal record across them is a systems-integration project — and CMS and ONC mandates now require FHIR readiness that legacy interfaces cannot deliver.
## Any format in, validated FHIR out
The harmonizer replaces point-to-point interfaces and manual mapping with agents that ingest whatever arrives. Structured messages and unstructured documents are parsed in the same pipeline: the system identifies the FHIR resources inside — Patient, Encounter, Observation, Medication — and maps them to the correct R4 profiles without hand-written scripts. Free-text clinical notes keep their narrative content alongside the structured data, so the patient record stays whole.
Terminology gets the same treatment. Local drug and lab codes convert automatically to RxNorm, LOINC, and SNOMED, which is what makes the output usable — data that shares a schema but still speaks local vocabularies cannot be analyzed together.
## Validation, with humans on the exceptions
Every generated resource is tested against its implementation guide — US Core, CARIN Blue Button, or your own profiles — before it is published. Resources that fail validation, and mappings the system cannot resolve confidently, are flagged and held for a data steward's review rather than passed through silently. Each published resource keeps its trace links back to the source message or document, so any value in the FHIR output can be followed to the data it came from.
Compliance is the mandate; usefulness is the payoff. Harmonized records support real-world evidence work — aggregating disparate patient histories for clinical trial matching — and can be exposed through validated FHIR APIs to authorized partner applications, with consent managed at a granular level. One canonical format, from every source you have.
---
## Field Service Intelligence Hub
URL: https://www.botminds.ai/solutions/field-service-intelligence-hub
> Unifies work orders, field notes, and asset telemetry into one traceable record — improving dispatch, first-time fix rates, and service reporting.
Field operations fail in the gap between dispatch and the driveway. Schedules are built on static rules that ignore traffic, skill gaps, and parts availability. Technicians arrive without the asset's history or the manual for its firmware version. And the truth about what happened on site lives in notes typed up hours later — which is why billing lags, inventory drifts, and the same defect gets rediscovered at every site it appears.
## One record from dispatch to invoice
The hub pulls the fragments together: work orders, technician profiles, field notes, safety checklists, parts records, and asset telemetry. Agents extract diagnostics, parts consumption, and service outcomes directly from unstructured notes, so the structured record exists the moment the job closes — no evening admin, no re-keying, no lag between work done and invoice sent. Every service event is traceable to its source: the note, the checklist, the telemetry reading.
Scheduling gets smarter with the same data. Jobs route on real constraints — the right skills, the right parts, the shortest path — and reroute when an escalation or a delay hits, without unraveling the rest of the day.
## Fix it right the first time
First-time fix rate is where field economics are won. The hub raises it by giving technicians what the best technician already knows: the asset's complete history, past fixes for this failure mode, and the manual sections that matter, delivered on mobile before arrival. Safety compliance is enforced in the same flow — checklists and risk assessments verified complete before work begins.
Because field notes become structured data, patterns become visible. The hub detects recurring defects across an asset class, correlates telemetry with failures, and flags the assets likely to fail next — so maintenance gets scheduled before the emergency gets dispatched. Dispatch, inventory, and billing finally read from one shared record.
---
## File Completeness & Missing-Item Detection
URL: https://www.botminds.ai/solutions/file-completeness-missing-item-detection
> Checks every loan file against its required-document checklist and flags missing, expired, or inconsistent items before underwriting begins.
Incomplete files are discovered at the worst possible time: mid-underwriting, when an analyst reaches for the rent roll that was never submitted. The file goes back, the borrower gets the third request this month, and the close date slips again. The cost is rework for the team and churn for the borrower.
## Checked the moment it arrives
Botminds checks completeness on arrival. Agents classify every document in the submission — regardless of how it was named or which pages were stapled together — then test the file against the checklist that applies to its product, policy, and borrower type. A scanned PDF labeled "docs_final_v3" resolves into a tax return, two bank statements, and an insurance certificate, each checked off against what the file requires.
The check goes past presence. Expired certificates are flagged. So are cross-document inconsistencies: a borrower name that differs between the application and the entity documents, dates that fail to line up, an amount that contradicts the statement behind it. Wrong documents fail the check the same way missing ones do.
## One request, then a governed clear
The output is a single gap list, produced in minutes: what is missing, what is expired, what conflicts, and which checklist rule each finding traces to. Operations teams send the borrower one complete request, and underwriters open files that are actually ready.
No file advances on the platform's word alone. A reviewer confirms the completeness verdict — with each finding one click from its evidence — before the file is cleared downstream. The check itself is recorded: what was tested, against which checklist version, what was found, and who cleared it. When policy changes, the checklist changes in one place, and every file after that is measured against the new standard.
---
## Filings & Financial Document Intelligence
URL: https://www.botminds.ai/solutions/filings-financial-document-intelligence
> Extracts financial metrics and disclosures from filings and reports, then compares them across periods with every figure cited to its page.
The numbers that matter in a filing are rarely on the face of the statements. They are in the footnotes, the segment tables, the risk factors that quietly changed since last quarter. Reading for them is slow; reading for them consistently across a portfolio of filers is beyond what any team does by hand.
## What it does
Botminds ingests filings and financial reports as they publish — 10-Ks, 10-Qs, 8-Ks, annual reports, digital or scanned — and extracts the metrics and disclosures inside them into one structured model. Line items normalize across different presentation formats and entities, so a figure from one filer is genuinely comparable with the same figure from another, and with the same filer a year ago.
The comparison is where the value concentrates. The platform diffs each new filing against its predecessors: a disclosure that was reworded, a metric that moved between sections, risk language that appeared for the first time, a footnote that grew three paragraphs. Changes a manual read would miss — because nobody re-reads last quarter's filing side by side — surface automatically, ranked and cited.
## Every figure defends itself
Extracted data is only worth what you can verify. Every metric and disclosure in the output links to the exact page it came from; click the number, see the filing. Analysts confirm the items that matter in seconds, and anything built on the data downstream — a credit memo, a model input, a research note — inherits a citation trail back to the primary source.
Because extractions feed credit views, risk assessments, and investment decisions, nothing flows downstream unreviewed. Agents extract, normalize, and flag; an analyst approves. The record keeps the whole chain — source page, extracted value, reviewer, decision — which is exactly what a committee or an examiner asks for when they ask where a number came from.
---
## Finance & Accounts Automation
URL: https://www.botminds.ai/solutions/finance-and-accounts
> Pre-built AI agents for finance and accounts teams — invoices, filings, leases, spreads, and audit trails — with human review on every output.
Finance and accounts teams run on documents that never stop arriving: invoices, lease
agreements, company filings, plan documents, financial statements. Most of it is
unstructured, which is why so much of the function is still skilled people rekeying
numbers. Botminds automates the document work and keeps your team on the judgment calls.
## Nine solutions, ready to deploy
Each one arrives knowing its documents and its job:
- **Invoice Intelligence Hub** — invoice processing from capture to closure
- **Financial Spreading Suite** — statements extracted and normalized across formats, standards, and entities
- **Lease Data Extractor** — clause-level lease insights with version awareness
- **Company Filings Extraction** — key financial disclosures extracted and validated at scale
- **401(k) Compliance Extractor** — plan details from filings and records, with audit traceability
- **Loan Document Intelligence Agent** — classification, extraction, and compliance validation across the loan lifecycle
- **Mortgage Intelligence Hub** — loan documents, borrower data, and compliance records in one traceable layer
- **M&A Deal Intelligence Agent** — deal tracking and comparison with source-level traceability
- **Audit Trail Intelligence Suite** — a single, verifiable source of audit truth across documents and workflows
Beyond the pre-built set, the same platform handles adjacent work — KYC/AML due diligence,
claims and policy documents, regulatory compliance monitoring, and research summarization.
## One platform underneath
Every solution runs on the same foundation: a no-code platform with generative AI at the
core, deployable in private cloud or on-premises, certified to ISO 27001 and SOC 2. Every
extracted value traces to its source document, and outputs the platform is less confident
about route to a human before they post. Month-end stops waiting on keying, audit samples
resolve in a click, and your controllers spend their time reviewing — which is what a
finance team is for.
---
## Financial Spreading
URL: https://www.botminds.ai/solutions/financial-spreading
> Extracts and normalizes financial statements — any format, any accounting standard — into spread-ready data, five times faster than manual work.
Spreading is the bottleneck of commercial credit. Before an analyst can think about a deal, someone has to turn the borrower's financials — an audited PDF here, a scanned tax return there, a management Excel with its own creative structure — into the bank's template, line by line. It takes hours per borrower, and the analysts doing it were hired for judgment, not transcription.
## What it does
Botminds reads financial statements the way a trained spreader does, at machine speed. Agents extract every line item from income statements, balance sheets, cash flow statements, tax returns, and audited financials — digital or scanned — and map them to your spreading template and chart of accounts. A borrower's "Other operating income" lands where your policy says it lands, consistently, on every file. Multi-period and multi-entity statements normalize into one comparable structure, ready for ratio work and rating models.
The result is a spread in minutes instead of hours — five times faster than manual spreading — with the analyst's time moved from typing to reviewing.
## Trust is a citation, not a promise
Every number in the spread links back to the exact page and figure it came from. An analyst verifying a spread does not re-derive it; they click the values that matter and see the source. That single property is what makes automated spreading usable in a credit process: the output is checkable in seconds, so it can be trusted at scale.
## Governed by design
No spread posts itself. Values the platform is less confident about are flagged for review, and a named analyst approves every spread before it flows into your loan origination system or rating models. The full record — source document, extracted value, mapping, reviewer, approval — stays with the spread, so any figure in a credit memo can be traced to the borrower's own statements, months or years later.
---
## Financial Spreading & Performance Tracking
URL: https://www.botminds.ai/solutions/financial-spreading-performance-tracking
> Normalizes recurring financial statements into consistent spreads and tracks borrower and portfolio performance trends period over period.
## Consistent spreads, every period
Spreading one statement is a task. Spreading the same borrower's statements every quarter,
consistently enough that the trend line means something, is the part portfolio teams
actually struggle with — and it is why annual reviews become a crunch and early warnings
arrive late.
Botminds spreads each incoming statement — interim financials, audited accounts,
management accounts, tax returns, covenant certificates — to the same template with the
same mapping rules, every time. That consistency is the point: when EBITDA means the same
thing in Q1 as in Q3, the movement between them is signal. New periods append to the
borrower's history automatically, five times faster than manual spreading, with every
number cited to its source page.
## Trends you act on before review season
With a clean history in place, the platform computes what portfolio managers actually
watch: revenue and margin trajectories, leverage creep, liquidity trends, covenant
headroom shrinking quarter by quarter. Deterioration is flagged when the trend turns —
months before the annual review would have reached that name. Analysts confirm each flag
against the cited source figures and decide what warrants action, so alert noise stays low
and the flags that fire mean something. The same normalized data rolls up to portfolio
level: which segments are weakening, which covenants are tightening across names, where
concentrations are building.
Because spreads accumulate all year, the annual review starts from a complete, cited
financial history. Every figure traces to the borrower's own statements; every spread
carries its reviewer and approval. When credit committees or examiners ask how a rating
held while margins slid, the record answers with pages and dates.
---
## Financial Spreading Suite
URL: https://www.botminds.ai/solutions/spreading-process-automation
> Turns tax returns, financial statements and spreadsheets into standardized spreads — every figure cited to its source page, 5× faster than manual.
Credit analysis stalls where it should not: senior analysts spending hours interpreting
formats instead of assessing risk. Borrower submissions arrive as scanned tax returns,
PDFs, Excel workbooks and mixed schedules. Each analyst recasts revenue, expenses and
adjustments a little differently, so EBITDA and coverage calculations drift across the
portfolio — and every manual derivation compounds the error into DSCR and downstream
risk models.
Financial Spreading Suite reads the raw documents and produces standardized,
analysis-ready spreads. It normalizes across IFRS, GAAP and local standards, reconciles
entities, and auto-computes the key metrics — EBITDA, ROE, debt-to-equity, coverage
ratios — the same way every time. Time-series and peer comparison come from the same
structured foundation, and exceptions and variances are flagged for a human before they
flow into a decision.
## What governed spreading looks like
Every figure in the spread links back to the page it came from. Click a normalized
revenue line and you land on the exact cell of the Excel schedule or the exact line of
the scanned return that produced it. Mapping decisions are visible, derived metrics show
their formulas, and an analyst approves the spread before it moves into decisioning. That
is what makes the output regulator-ready as well as fast — when a number is questioned,
its provenance is one click away.
## The payoff
Spreading runs about 5× faster than manual work, and the platform has understood 1M+
documents across formats and standards. The compounding value is consistency: one mapping
logic across the whole portfolio means quarter-over-quarter trends and portfolio-wide
exposures are actually comparable. Analysts stop re-keying and start doing the job they
were hired for — judging credit.
---
## Financial Statement Normalization & Quality of Earnings Support
URL: https://www.botminds.ai/solutions/financial-statement-normalization-qoe-support
> Normalizes target financials and drafts a cited quality-of-earnings view — adjusted EBITDA, working capital and one-off items traced to source pages.
## From four formats to one databook
Every diligence engagement starts the same way: three years of target financials in four
formats, none of which match. Audited statements disagree with management accounts; the
trial balance uses a chart of accounts nobody on the deal team has seen. Before anyone can
discuss earnings quality, someone has to normalize all of it by hand — usually your most
senior analyst.
Botminds does the normalization. It reads audited financials, management accounts, trial
balances, GL exports, and tax returns in whatever shape they arrive — scanned PDF, digital
PDF, Excel — and maps every line item to a standard chart of accounts, reconciled across
periods, entities, and currencies. Five times faster than manual spreading, with every
number cited to the page it came from.
## Adjustments that survive partner review
Normalization is the floor. On top of the standardized statements, the platform surfaces
the items a QoE reviewer hunts for: one-off revenue and expense items, owner compensation
add-backs, related-party transactions, working-capital swings, and period-over-period
movements that break the trend. Each is presented as a candidate adjustment with the exact
source page attached; an analyst accepts, rejects, or edits it. Nothing enters the
adjustment schedule without a named sign-off.
The result is a databook the deal team can stand behind: normalized statements, an
adjusted-EBITDA bridge, and a working-capital analysis where every figure links back to
its document. When a number is challenged six weeks later — by the partner or by the other
side's advisors — the answer is one click: which document, what was adjusted, who approved
it, and when.
---
## Governance Intelligence Agent
URL: https://www.botminds.ai/solutions/governance-intelligence-agent
> Captures policies, maps obligations to controls, and tracks regulatory change — with linked evidence so governance stays current instead of shelfware.
Most governance programs fail quietly. Policies live in scattered SharePoint folders and
email threads, so employees act on the wrong version. Regulations change faster than the
policy team can run gap analyses. Corporate secretaries spend their time compiling board
packs instead of analyzing them. And in multi-entity groups, local practice drifts from
corporate standard until an audit or an M&A process finds the gap.
The Governance Intelligence Agent turns that static document pile into an active system.
It ingests policies, procedures, regulatory texts, attestations and board materials, then
builds a regulation-to-control map: every external obligation linked to the internal
policy and control that answers it. When a regulation changes, the agent shows exactly
which policies are affected — with the relevant clauses side by side.
## What it reads and what it produces
Inputs are the documents governance already runs on: internal policies in every version,
external regulatory texts and updates, control matrices, attestation records, and
subsidiary procedures. Outputs are working artifacts: a versioned policy repository where
employees find only the approved current document, a gap register with each conflict cited
to the exact clauses on both sides, and board-ready dashboards of attestation rates and
open items that replace hand-built PDF packs.
It also answers the everyday questions that clog the compliance inbox — "what is the gift
policy limit?" — directly from the approved policy text, with the source cited.
## Why governed matters here
A governance tool that hallucinates an obligation is worse than no tool. Every finding the
agent raises is linked to the specific regulatory clause and policy paragraph behind it,
and no policy change, gap closure or attestation is recorded without a named human
approving it. The audit trail is the product: when a regulator asks how a requirement is
covered, the answer is a traceable chain from law to policy to control to evidence.
---
## Income, Asset & Liability Verification Intelligence
URL: https://www.botminds.ai/solutions/income-asset-liability-verification-intelligence
> Extracts and normalizes borrower income, asset and liability evidence from paystubs, statements and returns — cited and ready for underwriter review.
Income verification is where loan files stall. A single application can carry a dozen
evidence documents — paystubs, W-2s, bank statements, tax returns, credit reports — each
in its own layout, some scanned at an angle on a phone. A processor keys the figures into
the LOS by hand, an underwriter re-checks them, and any mismatch sends the file back to
the start of the queue.
Botminds reads the whole evidence package in one pass. It classifies each document against
the program's verification checklist, extracts income, asset and liability figures
regardless of layout or scan quality, and normalizes them into the structure your
underwriting process expects — monthly qualifying income, liquid assets, recurring
obligations.
## Verified means cross-checked
Extraction alone verifies nothing. The platform cross-checks figures across the package:
year-to-date paystub income against the W-2, stated deposits against bank statement
activity, disclosed liabilities against the credit report. Consistent evidence flows
straight through; discrepancies are flagged with both source pages side by side so a
processor resolves them in seconds instead of hunting through the file. Stale documents,
missing pages and wrong tax years are caught at intake, before an underwriter ever opens
the loan.
## Why governed matters here
A qualifying income number without a source is a finding waiting to happen — in QC, in a
repurchase review, or in an exam. Every figure Botminds produces is cited to the exact
page it came from, every cross-check is logged, and no verification result reaches the
underwriter without passing the checks your policy defines. Underwriters approve
decisions; the platform never does. The output is a loan file where each number can be
defended months later with one click — which is what makes the speed usable, not just
impressive.
---
## Investment Memo & IC Pack Generation
URL: https://www.botminds.ai/solutions/investment-memo-ic-pack-generation
> Drafts investment memos and IC packs from deal documents — every figure and claim traced to its source page, ready for analyst review and sign-off.
The investment memo is where a deal team's work becomes a decision — and where the hours
go. Analysts spend days re-keying figures from financial statements into memo tables,
chasing the latest term sheet version, and assembling exhibits, leaving less time for the
part that actually matters: the judgment. And when a committee member asks "where does
this number come from?", the answer is too often a search through the data room.
Botminds generates the first draft. It reads the deal file — financial statements, term
sheets, market studies, diligence reports, cap tables — and produces a memo in your house
format: transaction overview, financial summary, risk factors, terms. Every figure and
every factual claim carries a citation to the exact source page. What the platform cannot
support from the documents, it leaves flagged rather than invented.
## A draft the deal team challenges
The memo that goes to committee is the deal team's, not the machine's. Analysts work
through the draft section by section: correcting, sharpening the thesis, overriding
extracted figures where judgment says otherwise — with each override logged. Nothing
reaches the IC pack without human approval, and the pack assembles itself from approved
sections, current exhibits and the supporting appendices, so version drift between memo
and materials disappears.
## Why governed matters here
Committee materials are audited artifacts. Regulators, LPs and internal review all ask the
same question later: what did the committee see, and what was it based on? Because every
number in a Botminds-drafted memo is cited to source and every edit and approval is in the
audit trail, that question has a one-click answer. The speed is what teams notice first;
the traceability is what makes the memo defensible when the deal is old and memories
aren't.
---
## Investment Research Workbench
URL: https://www.botminds.ai/solutions/investment-research-workbench
> Turns filings, transcripts and broker notes into standardized model inputs — with tone signals and red flags, every number traced to its source page.
Research teams drown in information. Quarterly filings, earnings transcripts, broker
notes and alternative data arrive faster than any team can read, so analysts trade depth
for breadth. The highest-paid hours in the building go to copying numbers from PDF tables
into Excel, and the model that finally updates in week two of earnings season answers a
question the market asked on day one.
The Investment Research Workbench takes the mechanical layer off the analyst's desk. It
ingests filings, transcripts and notes as they publish, extracts financial statements, KPI
tables and guidance ranges, and maps them into your proprietary models — handling non-GAAP
reconciliations and fiscal-year differences that make naive extraction useless. Models
update on earnings day, and every input carries a citation to the page it came from.
## A second reader that argues back
The workbench is built to counter the failure mode of human research: confirmation bias.
It quantifies shifts in management tone across earnings calls, flags footnote items that
cut against the thesis, and highlights divergences between what management promised and
what they delivered. Analysts can run semantic screens across the whole universe —
"companies discussing supply-chain on-shoring with declining margins" — in the time a
keyword search used to take. The system surfaces evidence; the analyst owns the call.
Every buy or sell recommendation stays a human decision, backed by traceable data.
## Why governed matters here
An investment process is only as defensible as its record. Because every model input,
assumption and revision is logged with its source, the CIO and the analyst look at the
same evidence base — and compliance, client reporting and post-mortems draw from a
governed research archive instead of a folder of spreadsheets. Coverage grows per analyst
because the reading scales; conviction stays human because the deciding doesn't move.
---
## Invoice Intelligence Hub
URL: https://www.botminds.ai/solutions/automated-invoice-processing
> Template-free invoice processing from capture to closure — extraction, validation, PO matching, and exception routing with a complete audit trail.
Invoice operations were not built for the volumes they now carry. Invoices arrive through email, vendor portals, EDI, and scanned paper; line-item checks, tax validation, and PO matching still depend on manual effort; and exceptions accumulate faster than the team can clear them. Approvals crawl across disconnected systems while payment SLAs slip and vendors chase status. The Invoice Intelligence Hub runs the invoice lifecycle from capture to closure.
## Extraction without templates
Agents capture invoices in any format and extract header and line-item data without per-vendor templates — new vendors and new layouts do not mean new configuration. Each invoice is validated against its purchase order and goods receipt, checked for tax correctness, and screened for duplicates and anomalies that suggest fraud. Clean invoices flow straight through to approval and posting. Everything else becomes an exception with context: the mismatch, the source pages, and the suggested resolution are routed to the right team, so reviewers decide rather than investigate.
Because every invoice becomes structured data, finance gets more than throughput. Spend by vendor, payment-term utilization, duplicate patterns, and approval bottlenecks are visible in real time — the inputs to cash-flow decisions that used to require a month-end reconstruction.
## Why governed matters here
Invoices are financial records, and auditors treat them that way. Every extracted value is cited to its location on the source document; every validation result, exception decision, and approval is captured with a timestamp and an owner. When an auditor asks why an invoice was paid, the complete history is one lookup. AP, compliance, and finance leadership work from the same record — and volume spikes at quarter-end run through the same governed workflows, which is what makes the automation trustworthy at scale.
---
## Knowledge Orchestrator
URL: https://www.botminds.ai/solutions/knowledge-process-automation
> Connects your repositories and answers operational questions with cited sources — respecting existing permissions, with no content migration required.
## The answer exists — finding it is the problem
In most enterprises the answer exists: in a SOP on SharePoint, a runbook in Confluence, a
thread in Slack, a closed ticket from 2023. What is missing is a way to find it. Keyword
search returns a list of forty documents; employees parse long files to find one procedure
step, or ask the senior person who happens to know. When that person leaves, the knowledge
leaves with them.
The Knowledge Orchestrator sits across your existing repositories — no migration, no
re-tagging, no new-wiki project — and answers questions directly. Ask what the escalation
path is for a failed settlement, and it synthesizes the answer from the manuals, SOPs, and
historical tickets that cover it, with each source cited so the reader can verify in one
click. Answers appear where people work: in the search bar, in Slack or Teams, in
Salesforce.
## Permissions are the hard part, and they are built in
An answer engine that ignores access control is a data breach with a chat interface. The
Orchestrator respects your existing permission hierarchies: every answer is filtered by
the asker's ACLs, so a person only ever sees content they could already open. Sensitive
repositories stay sensitive.
It also tells you what is missing. Failed queries are a map of your documentation gaps:
the Orchestrator tracks the questions no document answers and surfaces them, so experts
write the content that is actually needed — before the next person hits the same wall.
Because answers come from the current approved source instead of a stale copy on an old
email, teams stop acting on obsolete procedures. Institutional knowledge stops being a
retention risk and becomes an asset you can operate.
---
## KYC Compliance Accelerator
URL: https://www.botminds.ai/solutions/kyc-anti-money-laundering-aml-process-automation
> Verifies identity documents, unravels ownership to the UBO, screens against watchlists, and logs every adjudication for regulators and audit.
## Onboarding diligence as a governed pipeline
KYC breaks in two directions at once. Onboarding is too slow: unraveling ultimate
beneficial owners in a layered corporate structure means chasing registry documents across
jurisdictions for weeks. Screening is too noisy: watchlist tools flood analysts with
alerts on common names, so the team spends its days clearing false positives instead of
investigating actual financial-crime risk.
The KYC Compliance Accelerator runs that workload end to end. Agents ingest identity
documents and registry extracts, validate them against registries and biometric checks,
and navigate corporate ownership trees to identify UBOs — producing a visual ownership
graph with every node backed by a source document. Screening runs with fuzzy-match
resolution: obvious false positives are discounted on secondary identifiers like date of
birth and location, so analysts see the matches that deserve investigation, each arriving
with its evidence already assembled.
Calendar-based re-KYC means a high-risk change can sit unnoticed until the scheduled
three-year review. Because the platform maintains a single, current risk profile per
customer, it triggers review when something material actually changes — new ownership, new
adverse media, a jurisdiction shift — and stays quiet otherwise. The same machinery
handles remediation lookbacks at scale, without hiring a temporary army.
## Why governed matters here
Financial-crime compliance is judged on its record. Every screening decision, discounted
alert, and analyst adjudication in Botminds is logged with the evidence it was based on,
and no risk decision is taken without a named human approving it. When the regulator asks
why a match was cleared in March, the answer is the complete adjudication trail — the
identifiers compared, the rationale, the approver — produced in minutes, months or years
later.
---
## Lease Data Extractor
URL: https://www.botminds.ai/solutions/lease-abstraction-automation
> Abstracts leases, amendments and rent schedules into structured, audit-ready data — clause-level citations, built for ASC 842 and IFRS 16 reporting.
A lease portfolio managed in spreadsheets is a liability estimate with error bars nobody
has measured. Agreements sit as scattered PDFs and scans across regions; variable rent
steps, free-rent periods and CAM charges get mis-keyed during manual abstraction; and a
missed termination-notice date turns into an unintended auto-renewal with a real cost
attached. Under ASC 842 and IFRS 16, those errors flow straight into reported liabilities.
The Lease Data Extractor abstracts the portfolio automatically. It reads lease agreements,
amendments and addendums in whatever format they arrive and extracts the fields that
matter: parties and premises, term and options, full rent tables including escalations and
abatements, CAM provisions, and critical dates. It does this template-free — no
per-landlord configuration — and normalizes currencies, square footage and payment
frequencies into one reporting structure across international portfolios.
## Precision where the money is
Rent tables are where abstraction tools fail, because payment schedules are where leases
are most idiosyncratic. The platform digitizes stepped rents, indexation clauses and
abatement periods into structured schedules, then validates them against accounting rules
before they reach your books. Anything ambiguous or non-standard is routed to a human
reviewer with the source clause on screen — the platform never guesses on a number that
feeds a liability valuation. Validated data pushes into lease accounting systems and ERPs,
and critical dates — renewals, breaks, escalations — become scheduled alerts instead of
calendar folklore.
## Why governed matters here
Auditors accept an abstract they can trace. Every extracted field keeps a permanent link
to the specific clause in the original contract, and every expert review and correction is
logged. When an auditor questions a right-of-use figure, the path from reported number to
source clause is one click — which turns lease-accounting audits from an annual excavation
into a lookup.
---
## Legal & Compliance
URL: https://www.botminds.ai/solutions/legal-and-compliance
> Document-to-decision AI for legal and compliance teams — contracts, obligations, diligence, eDiscovery and research, with evidence traced to source.
Legal and compliance work is document work at hostile scale. Contracts multiply,
regulations change mid-quarter, litigation produces terabytes of case data, and nearly
all of it is unstructured — which means the highest-cost professionals in the company
spend their hours reading, extracting and cross-referencing instead of advising.
Botminds automates the reading layer, so counsel spends time on judgment.
## Nine solutions, one governed platform
Botminds ships pre-built solutions across the legal and compliance stack: a Compliance
Intelligence Engine that centralizes obligations and monitors adherence; a Contract
Command Center that turns every contract into structured, risk-aware insight; Contract
Risk & Obligation Tracking with renewals tied to source clauses; Due Diligence & M&A
Document Analysis for surfacing material risks across contracts, filings and
disclosures; an eDiscovery Evidence Engine that turns voluminous case data into
verifiable findings; Legal Research Automation with traceable citation mapping;
Litigation Document Management with governed access and version control; a Patent
Intelligence Workbench across claims, classifications and prior art; and Policy &
Clause Compliance Validation against regulatory frameworks.
Each runs on the same platform primitives: cross-format document understanding,
extraction cited to the source passage, policy-governed workflows, and human review at
every decision point. Start with one solution and a working deployment in weeks; add
the next on the same foundation instead of integrating another point tool.
## Why governed matters here
Legal conclusions without provenance are opinions. Every finding Botminds produces — a
flagged clause, a compliance gap, a diligence risk — carries a link to the exact
document passage behind it, and nothing becomes a decision without counsel's sign-off.
Deployment fits the sensitivity of the work: Botminds cloud, private cloud or on-prem,
with SOC 2 compliance and role-based access control. The audit trail that protects the
company is the same one that makes the AI trustworthy to the lawyers using it.
---
## Legal Research Automation
URL: https://www.botminds.ai/solutions/legal-research-automation
> Analyzes judgments, filings and opinions to extract facts, rulings and citations — building a searchable, source-linked legal knowledge base.
Legal research is precise work done under time pressure — a combination that punishes
manual methods. A researcher building a precedent analysis reads hundreds of judgments
to find the dozen that matter, extracts holdings by hand, and assembles citations into
a memo, knowing a single mis-attributed quote can undermine the whole argument.
Legal Research Automation moves that work to structured, evidence-based analysis. The
platform ingests judgments, pleadings and legal opinions at volume and extracts the
relevant facts, issues, rulings and outcomes from each. Every extracted point is tied
back to the original paragraph or citation — the specific passage, and only the specific
passage — so verification is a click instead of a re-read.
## From documents to a working knowledge base
Individual extractions become more useful in aggregate. The system clusters related
cases by issue and statute, revealing precedent lines and legal trends that a linear
reading would miss. Researchers can trace how an argument has fared across
jurisdictions, generate summaries with source references attached, and build case
compendiums in minutes rather than weeks. The output is a unified, searchable legal
knowledge base that grows with every matter — institutional research memory that
outlives the memo that prompted it.
## Why governed matters here
Legal work product has to survive adversarial scrutiny. A summary that can't show its
sources is a liability in front of a partner, a client, or a court. Botminds' lineage
model guarantees that every insight in the knowledge base is backed by an original
document: each statement in a generated summary links to the paragraph it came from,
every extraction is logged, and a researcher signs off before anything ships. The
result is research that is faster to produce and easier to defend — because the
citation trail is built in from the first document rather than reconstructed at the
end.
---
## Life Sciences
URL: https://www.botminds.ai/solutions/life-sciences
> Document-to-decision AI for life sciences — batch records, protocols, claims, literature and SOPs processed with the traceability regulated work demands.
Life sciences runs on documents that regulators will one day read: batch manufacturing
records, clinical protocols, safety literature, patient records, standard operating
procedures. The volume grows every year, most of it is unstructured, and the cost of an
error is measured in compliance findings and patient risk rather than rework alone.
Document automation in this industry has to be traceable before it is fast.
## Nine solutions, one governed platform
Botminds ships pre-built solutions across the life-sciences document estate: Batch
Manufacturing Records Automation that digitizes, validates and reconciles batch records
with full process traceability; a Claims Resolution Platform that surfaces
inconsistencies, policy deviations and high-risk items in healthcare claim disputes; a
FHIR Data Harmonizer that converts fragmented health and product data into
standards-aligned FHIR outputs; Literature Monitoring & Signal Detection with traceable
safety evidence; a Clinical Summary Generator that turns raw patient records into
structured discharge summaries; a Process Investigation Workbench for root-cause
analysis and deviation tracking; a Clinical Protocol Validator that checks study
protocols against standards, guidelines and internal rules; an RCM Performance Suite
for revenue-cycle intelligence with audit traceability; and a SOP Unifier that
consolidates and governs procedures across the organization.
Each is a tested template on the same platform — start with the workflow that hurts
most and expand on the same foundation, rather than integrating another point tool per
problem.
## Built for regulated deployment
Validation-minded teams get the controls up front: every extracted value and generated
summary is cited to its source document, exceptions route to qualified human reviewers,
and the complete audit trail — what was read, what was produced, who approved it — is
regulator-ready by construction. Deployment options fit data-sensitivity requirements:
Botminds cloud, private cloud or fully on-prem, so no data leaves your instance, with
enterprise security covering ISO 27001 and SOC 2. Dedicated, SLA-backed solution
experts handle onboarding and support.
---
## Literature Monitoring & Signal Detection
URL: https://www.botminds.ai/solutions/literature-monitoring-and-signal-detection
> Screens PubMed, Embase and local journals at scale — deduplicates, classifies and extracts Patient-Drug-Event relationships with cited, audit-ready evidence.
Literature surveillance breaks at volume. Teams screen thousands of abstracts a week
across PubMed, Embase and local journals, and keyword search buries them in false
positives. Reviewers spend their hours discarding irrelevant articles instead of
analyzing the ones that matter — and every day of triage backlog is a day an adverse
event goes unreported.
## From keyword matching to biomedical context
Botminds agents read the literature the way a trained reviewer does. They ingest from
subscription databases, conference abstracts and open-web sources, deduplicate records
that appear in more than one database, and classify each article by what it actually
contains: a valid safety signal, efficacy data, or noise. Entity recognition and
relevance scoring rank the queue so high-severity candidates surface first. The agent
extracts Patient-Drug-Event relationships and highlights Day 0 criteria, so ICSR
candidates move to triage the day they appear — before a backlog forms, and well before
one clears.
The same pipeline extends without new headcount: add a therapeutic area, a local
journal or a new source, and the agents cover it on the next cycle.
## Built for inspection
Pharmacovigilance is a document-to-decision operation, and regulators audit the
decisions. The platform keeps the complete trail: which search strings ran, which
articles were retrieved, how each was classified, who reviewed it and what they
decided. Every extracted relationship is cited to the passage it came from, so a
reviewer — or an inspector — can check the evidence in one click. Nothing is
auto-dispositioned into silence: reviewers approve every safety-relevant call, and the
system records that they did.
Safety, clinical development and medical writing teams work from one shared repository
of validated findings instead of parallel spreadsheets — the same article, the same
disposition, the same evidence, everywhere it is needed.
---
## Litigation Document Management
URL: https://www.botminds.ai/solutions/litigation-document-management
> One governed repository for litigation files — filings, exhibits and correspondence indexed, versioned and traceable through discovery, review and audit.
Litigation runs on documents, and litigation documents are unforgiving. A missed
filing, an untracked amendment, or an exhibit that cannot be traced to its origin costs
more than time — it costs credibility with the court. Yet in most legal teams, case
files live across email threads, shared drives and external court portals, and version
history lives in filenames.
## Every document, one governed record
The platform captures everything tied to a matter — filings, affidavits, exhibits,
correspondence — and organizes it automatically. Each document is classified, assigned
case metadata, and linked to its case record and event timeline, so anyone on the team
sees where a file sits in the life of the matter. Version control is built in: every
edit, every version, every user access is preserved, and redline comparison shows
exactly what changed between drafts. Docket monitoring closes the external gap, pulling
updates from court portals so new filings land in the case record instead of being
discovered late.
Reconstructing document history for a compliance review or a regulatory audit stops
being an archaeology project. The lineage is already there.
## Knowledge that compounds
Most legal teams have won the same argument twice — and drafted it from scratch both
times, because past work product is siloed from current matters. With every brief and
motion indexed and searchable, the team's own successful arguments surface when a
similar matter arises. Search spans internal work product and case documents together,
so drafting starts from what already worked.
This is document-to-decision infrastructure for disputes: a clean, complete, verifiable
file behind every strategic call, from early case assessment through trial preparation
and post-litigation reporting. Legal and compliance teams get transparent visibility,
outside counsel gets a complete record, and when a regulator or opposing counsel asks
how a document came to be, the answer is one query away.
---
## Loan Document Intelligence Agent
URL: https://www.botminds.ai/solutions/loan-document-automation
> Reads mixed loan packets — applications, income proofs, appraisals, disclosures — and returns validated, source-linked data mapped to your checklists and LOS.
Loan operations stall at the packet. Borrowers send IDs, bank statements, tax returns
and appraisals as one mixed upload, in whatever format they have, and skilled staff
spend their day sorting pages and re-keying fields before underwriting can start. The
lag between document receipt and verified data is the lag between application and
funding — and slow funding sends borrowers elsewhere.
## From raw packet to decision-ready file
The agent ingests complete loan packages from any channel, separates mixed PDFs into
distinct document types, and extracts what underwriting needs: borrower identity,
income, collateral descriptions, covenant terms. No templates — it works from document
understanding, so a new lender format or a new appraisal layout needs no configuration.
Validation is where the time goes back to the business. Extracted data is
cross-referenced against your credit policies and external databases; the agent
verifies that all required stipulations are present and current before a file moves to
underwriting, and flags missing signatures, expired documents and data mismatches for a
human to resolve. Compliance checks map to the frameworks lenders answer to — TRID,
HMDA, RESPA — with the evidence attached.
## Traceable for the life of the loan
Every field in your LOS keeps a direct link to the page it came from, so an internal
audit is a click-through rather than a file hunt. After closing, the same agent keeps
working: it extracts data from periodic borrower submissions to track covenant health,
and flags fraud markers and anomalies as they appear. The loan file becomes a
maintained digital record rather than a folder that goes stale at funding.
Volume spikes stop being staffing events. End-of-quarter surges flow through the same
pipeline at the same accuracy, and exceptions — never every file — are what humans
review. Every exception decision stays with a person; the agent makes sure it is the
only kind of decision left.
---
## Loan File Classification & Document Intelligence
URL: https://www.botminds.ai/solutions/loan-file-classification-document-intelligence
> Splits and classifies large mortgage files into named, bookmarked documents so underwriting, QC and audit teams work from an organized, traceable file.
A mortgage file arrives as a single PDF of several hundred pages, in no particular
order: application, appraisal, title policy, pay stubs, disclosures, all fused
together. Before anyone can underwrite, audit or board that loan, someone has to find
where each document starts and ends, name it, and put it in order. Done by hand, that
is hours per file — and it is exactly the kind of routine work that keeps senior
analysts away from actual analysis.
## Structure without templates
The platform reads the combined file, detects document boundaries, and classifies each
document by what it is — independent of where a template expects it to be. New document
variants, unfamiliar layouts and poor-quality scans are handled by document
understanding rather than configuration, so onboarding a new correspondent or a
purchased portfolio requires no template building first. Classified documents are
bookmarked, named and stacked to your convention, giving every downstream team the same
clean, navigable file.
Where the model is unsure, it says so: low-confidence splits and classifications route
to a reviewer instead of passing silently into the file. Confidence is a property
attached to every decision the platform makes.
## Why traceability is the point
Classification is only trustworthy if you can check it. Every page in the organized
output remains linked to its position in the original upload, and every split,
classification and reviewer correction is logged. When a QC team, an investor or a
regulator asks how the file was assembled, the answer is on record.
The operational result: underwriters open files that are already organized, QC reviews
the whole file instead of sampling around the mess, and portfolio-scale work — due
diligence, servicing transfers, audits — starts from structure instead of chaos.
---
## Loan Package Triage & Document Intelligence
URL: https://www.botminds.ai/solutions/loan-package-triage-document-intelligence
> Triages complex lending packages on arrival — splits mixed PDFs, classifies every document and flags what's missing, so teams start from a clean file.
Complex lending packages do not arrive clean. Commercial deals, syndications and
broker submissions come in as sprawling bundles — applications, financial
statements, collateral schedules, guarantor documents and correspondence, often
merged into a handful of oversized PDFs. Before credit work can start, someone has
to answer three questions: what is in here, what is missing, and what should be
worked first. Answering them manually is slow, error-prone, and consumes the
capacity of exactly the analysts the deal needs.
## Triage as a system
The platform answers those questions on arrival. It splits combined files into
individual documents, classifies each one by type, and checks the assembled
package against your required-documents list. Gaps, duplicates and stale items —
last year's financials, an unsigned guarantee — are flagged before the file
reaches a person, so follow-up starts on day one instead of surfacing mid-review.
The output is a clean, structured, completeness-checked file, routed to the right
team with its priority visible.
Because classification is driven by document understanding rather than templates,
package variety does not degrade it. A new broker's format, a scanned exhibit, a
financial statement in an unfamiliar layout — all handled by the same pipeline,
with low-confidence calls routed to a reviewer rather than passed through
silently.
## Governed from the first page
Triage decisions shape everything downstream, so they have to be inspectable.
Every split, classification and completeness flag is logged, and every document in
the structured file traces back to its position in the original submission. Credit,
risk and operations teams work from one file with one history — and when an
auditor asks why a package was worked in a given order, or how a document was
identified, the record answers. Exceptions stay with humans; the platform's job is
to make sure exceptions are the only manual work left.
---
## M&A Deal Intelligence Agent
URL: https://www.botminds.ai/solutions/m-and-a-deal-document-analysis
> Reads the entire data room — contracts, financials, filings — and surfaces change-of-control terms, liabilities and cost overlaps with cited evidence.
Diligence breaks when the data room outgrows the deal team. A virtual data room
holds thousands of unorganized files — contracts, financial statements, HR records,
IP filings — and the review window does not move. So teams sample. And sampling is
how a change-of-control clause, an uncapped indemnity or pending litigation stays
buried until after close, when it becomes the buyer's problem.
## Full coverage inside the window
The agent ingests the entire data room, whatever its structure or scan quality,
and classifies every document so the team knows what the room actually contains —
and what is missing from it. From there it extracts the terms that move valuation:
change-of-control and assignment clauses, indemnities, exclusivity, termination
rights, litigation references. Findings are ranked by risk, and non-standard
agreements are isolated for senior counsel instead of sinking into the pile. Every
contract gets read, and the review hours go to judgment.
Diligence Q&A compresses with it. When a question comes in, semantic search
locates the specific evidence across the whole room in minutes, and the answer
carries its citation.
## From findings to Day 1
Diligence output usually dies in a static report. Here it stays structured: the
agent maps interdependencies — which customer contracts terminate on acquisition,
which vendor agreements overlap and can be consolidated — so revenue-at-risk and
integration cost models rest on the underlying documents. Risk findings convert
directly into a Day 1 action list for the integration team.
Every extraction and every flag is cited to the exact document and passage it came
from, and every disposition is made by a person and logged. This is
document-to-decision work at deal stakes: when the investment committee asks how
a number was reached, the evidence is one click behind it.
---
## Market Intelligence Dashboard
URL: https://www.botminds.ai/solutions/market-and-competitive-intelligence-monitoring
> Aggregates filings, news and company updates into one tagged view — trends, entities and sentiment, with every insight traced to its source document.
Market monitoring done by hand does not scale past a handful of sources. Analysts
skim the same feeds every morning, paste findings into decks, and still miss the
filing that mattered — because the signal was on page four of a source nobody was
assigned to watch. Web crawlers fetch pages, but they cannot target the relevant
blocks, handle layout variation and duplicates, or tell a product launch from a
press-release reprint.
## Aggregation with classification built in
The dashboard centralizes updates from filings, news feeds, regulatory sources and
the open web into a single working view. Each record is tagged on arrival by
sector, company and event type — new launch, acquisition, media mention — so
filtering is precise. Deduplication collapses the same story appearing across ten
outlets into one record with ten sources. Analysts review sentiment, track
entities and keywords, and watch trend lines built from classified events rather
than raw article counts, with automated tracking flagging shifts in activity or
disclosure volume across themes.
The same platform serves whichever team needs the signal: media coverage for PR,
competitor deal wins for sales, sector disclosure patterns for strategy and
research.
## Provenance behind every insight
An unsourced insight is a rumor with a chart. Every data point on the dashboard —
every event, every summary line, every trend — links back to the original document
it came from, creating an auditable trail from conclusion to evidence. When a
number reaches a board deck or an investment memo, the source page is one click
behind it.
That provenance discipline is the same one Botminds applies to lending and credit
work, applied here to the open market: document-to-decision, with the documents
attached.
---
## Mortgage Intake & Application Packaging
URL: https://www.botminds.ai/solutions/mortgage-intake-application-packaging
> Captures and assembles mortgage applications, disclosures and borrower documents into one complete, indexed file — gaps flagged before underwriting starts.
Mortgage intake is where loan timelines are won or lost. Borrowers send documents
in fragments — a 1003 from the portal, pay stubs by email, a disclosure signed
late — and processors spend their days reconciling what has arrived against what
the file needs. Every gap discovered in underwriting instead of intake adds a
condition, a follow-up cycle, and days to close.
## Assembly as an automated discipline
The platform treats packaging as a process with a definition of done. Each
incoming document is captured from whatever channel it arrives on, classified by
type, and indexed to the loan file. The assembled package is checked continuously
against the required-documents checklist for the loan program: missing items,
expired documents, unsigned disclosures and wrong-year income proofs are flagged
the moment the gap is knowable, while the borrower is still responsive. What
reaches underwriting is a complete, consistently ordered application file, every
document named and in its place.
Because classification works from document understanding rather than templates,
intake handles the reality of borrower submissions: phone-camera scans, merged
PDFs, unfamiliar formats from a new correspondent. Low-confidence calls route to a
person; nothing ambiguous passes silently into the file.
## Governed intake, downstream trust
Everything that happens at intake is recorded — what arrived, when, through which
channel, how it was classified, and who resolved each exception. Every document in
the packaged file traces back to the original submission. That record is what makes
the downstream file trustworthy: compliance reviews verify the intake trail rather
than reconstructing it, and audit questions about a document's origin have an
answer on record.
The operational effect is simple to state: underwriters open files that are ready
to underwrite, processors chase exceptions instead of paperwork, and volume growth
is handled by the pipeline rather than by weekend overtime.
---
## Mortgage Intelligence Hub
URL: https://www.botminds.ai/solutions/mortgage-process-automation
> Turns full mortgage files into validated data — automated stacking, income analysis, TRID checks and pre-fund QC, every figure linked to its source page.
Mortgage margins die by a thousand manual checks. High-cost staff spend their
hours stacking loan files, re-typing figures from pay stubs, and
"stare-and-compare" validating documents against the LOS — while QC samples a
fraction of the portfolio and hopes the rest is clean. The result is a cost to
originate that keeps climbing and a loan file whose quality is assumed more than
verified.
## The whole file, extracted and checked
The hub ingests complete loan files — hundreds of pages in arbitrary order — and
separates them into discrete, named documents. Specialized agents extract the
data that drives the loan: borrower intent from the 1003, income from pay stubs
and bank statements, appraisal values, title exceptions. Extraction is
provider-agnostic; a new appraisal layout or document vendor requires no setup.
Validation replaces the manual comparison work. Extracted data is cross-referenced
against LOS records and investor guidelines, including Fannie Mae and Freddie Mac
requirements. TRID compliance is checked directly: the platform verifies the
presence and accuracy of LE and CD disclosures before closing. Discrepancies —
missing signatures, expired documents, income math that does not reconcile — route
to an underwriter with the evidence attached. Fraud markers, from doctored bank
statements to undisclosed debts, are flagged the same way.
## QC and liquidity on the same rails
Because extraction covers the whole file, pre-fund QC runs on every loan at the
same depth, and repurchase risk stops hiding in the unsampled majority. The same
validated data serves the capital side of the business: boarding a purchased
portfolio into servicing, or validating an MSR data tape against source documents
before a trade, runs on the pipeline you already have — with every field on the
tape linked to the page it came from.
Decisions stay human. The hub hands underwriters and QC reviewers a file where the
reading, matching and arithmetic are already done, cited, and ready to check.
---
## Mortgage Risk Analysis
URL: https://www.botminds.ai/solutions/mortgage-risk-analysis
> Reads the complete mortgage file and surfaces documentation defects, borrower risks and underwriting signals — each finding cited to its source page.
Mortgage risk hides in the seams between documents. The income on the application
that the pay stubs do not quite support. The bank statement whose deposits do not
match the stated employer. The appraisal comment that undercuts the collateral
value. A human underwriter can find these — given unlimited time. Under volume,
review narrows to the checklist, and the cross-document signals are exactly what
gets skipped.
## Reading the file the way risk actually works
The platform reads the complete mortgage file as one body of evidence rather than
a stack of independent documents. It reconciles data across sources — stated
income against income proofs, application details against credit records,
collateral descriptions against the appraisal — and surfaces what does not line
up. Documentation defects, missing or expired items, borrower risk signals and
underwriting-relevant inconsistencies are detected across the whole file, then
ranked by severity so the material findings reach the underwriter first, ahead of
the trivia.
This is consistency at scale: the same analysis, at the same depth, on the
hundredth file of the day as on the first. Growing volume changes the queue
length, and the quality of the review holds — while senior analysts spend their
time on judgment calls instead of hunting for the discrepancy.
## Findings you can defend
A risk flag without evidence is an opinion. Every finding the platform raises is
linked to the exact pages and fields that triggered it, so an underwriter can
verify the signal in seconds — and so the decision that follows is defensible to
QC, investors and regulators later. Every disposition is made by a person and
recorded: what was flagged, what was decided, and on what evidence.
The output is a reviewed, cited, decision-ready risk picture of the file — the
groundwork of underwriting done thoroughly, every time, with the judgment left
where it belongs.
---
## Mortgage Underwriting Decision Support
URL: https://www.botminds.ai/solutions/underwriting-decision-support-mortgage
> Helps mortgage underwriters clear files faster with structured findings, rule checks and exception visibility — every item cited to the loan file.
A mortgage file is a few hundred pages that must agree with each other: the income on the
application against the pay stubs and W-2s, the deposits on the bank statements against
the stated assets, the appraisal against the loan amount. Underwriters spend most of
their review locating rather than deciding — paging through documents to verify that the
numbers line up and the conditions are met, while the pipeline behind them grows.
This solution reads the complete loan file, classifies every document, extracts income,
asset, liability and collateral data, and reconciles it across the package. Your
underwriting rules run against the extracted data automatically, and the underwriter
receives structured findings: what passed, what failed, what is inconsistent, and what
is missing.
## Exceptions first, pages second
The output is built around exception visibility. Instead of reading front to back, the
underwriter opens a worklist — an income discrepancy between the W-2 and the pay stub, a
large unexplained deposit, an appraisal condition still open — with each item citing the
exact page that raised it. Clean files clear fast because there is nothing to hunt for;
hard files get the underwriter's full attention on the parts that are actually hard. The
decision remains entirely human: the system prepares and flags, the underwriter rules.
## A file that can defend itself
Every extraction, rule check and cleared condition is logged with its source citation, so
the finished file carries its own evidence. In post-close QC, an investor review or a
regulatory exam, the question "how was this verified?" is answered by the record — which
rule ran, what data it saw, which page it came from, and who signed off. That audit
trail is the same structure the underwriter worked from, preserved with the file.
---
## Multi-Source Research Intake & Monitoring
URL: https://www.botminds.ai/solutions/multi-source-research-intake-monitoring
> Continuously ingests filings, transcripts, presentations and press releases into one research layer — deduplicated, tagged and cited back to source.
Research teams lose their edge to logistics. The filing is on EDGAR, the
transcript is with a vendor, the deck is on the company's IR page, last quarter's
notes are in someone's drive — and before any analysis happens, an analyst spends
the morning collecting, renaming and skimming. Coverage depends on who checked
which source, and the answer to "have we seen this before?" depends on memory.
## One research layer, always current
The platform turns collection into infrastructure. It continuously ingests
filings, earnings transcripts, investor presentations, press releases and other
research sources as they publish, extracts structure from each format, and
deduplicates content that arrives through more than one channel. Every document is
tagged by company, sector, period and event type, so retrieval is a single
query: everything the team holds on an entity, in one place, current as of
this morning.
Monitoring closes the loop. New arrivals and changes on tracked entities are
flagged as they land, so coverage stops depending on which analyst checked which
source — the layer watches everything the team has connected, every day.
## Research you can stand behind
An investment view is only as strong as its weakest citation. Because every
document in the layer keeps its source, date and origin, any claim built on it
traces back to the filing page or transcript passage it came from. When a number
moves from the research layer into a memo or a model, its provenance moves with
it — and an internal review or a compliance check follows the citation instead of
reconstructing the trail.
For credit, risk and research teams alike, the effect is the same: analysts start
the day at the analysis, because the intake already happened.
---
## Obligation Intelligence Agent
URL: https://www.botminds.ai/solutions/obligation-intelligence-agent
> Extracts contractual and regulatory obligations from contracts, tenders, and rulebooks, then tracks adherence with clause-level audit trails.
A contract is a list of promises. So is a tender, a regulation, and every addendum that
follows. The Obligation Intelligence Agent reads them all and turns dense text into a
live register of discrete obligations — who owes what, to whom, by when — with every
entry linked back to the clause it came from.
## From dense documents to a live obligation register
The agent ingests complete document packages — hundreds of pages of technical
specifications, legal terms, and addendums — and decomposes them into individual,
trackable obligations regardless of the issuer's format. Each one is mapped against your
internal capability library and control framework. Standard terms get auto-populated
responses; ambiguous or non-standard clauses are flagged for legal review, never
silently accepted.
For bid teams, this replaces days of manual RFP shredding. A raw tender package becomes
a line-by-line requirement traceability matrix in minutes, with commercial risks scored
alongside: consequential damages, unlimited liability, and penalty clauses surface
immediately, forcing an honest go/no-go decision before resources are committed.
Technical sections route automatically to the right subject-matter experts, and incoming
terms can be benchmarked against your history of signed contracts to spot deviations
from your standard position.
## Why governed matters here
An obligation you missed is a liability you own. The agent maintains a complete audit
log: what was extracted, from which clause, how it was mapped, who reviewed it, and what
changed. When a regulator or counterparty asks how a commitment was tracked, the answer
is a click. Adherence monitoring runs continuously after signature, so the register
stays true as amendments land.
Every decision the agent informs — accept, negotiate, escalate, walk away — stays with a
human. The agent does the reading; your team does the judging, with the evidence already
assembled.
---
## Operational Diligence & Value Creation Analysis
URL: https://www.botminds.ai/solutions/operational-diligence-value-creation-analysis
> Reads data rooms, management reports, and cost data to map operating models, surface execution gaps, and flag value-creation levers for deal teams.
Operational diligence lives or dies on how fast a team can turn a messy data room into a
clear picture of how the business actually runs. The documents are inconsistent, the
sources are fragmented, and the senior people who can interpret them are the scarcest
resource on the deal. This solution puts the reading on the platform and keeps the
judgment with the team.
## What it does
Botminds ingests the full data room — management accounts, organization charts, vendor
and supplier contracts, KPI reports, process documentation — and extracts a structured
view of the operating model: cost structure by line, headcount and spans, vendor
dependencies, and where execution responsibility sits. Every extracted data point is
linked back to its source page, so a number in the findings pack is never an orphan.
From that structured base, the analysis surfaces what diligence is really after:
execution gaps, cost outliers against comparable deals, single-vendor dependencies, and
the value-creation levers worth underwriting into the deal thesis. The same checklist
runs the same way on every target, which means findings are comparable across deals
instead of depending on which analyst pulled the late shift.
## Governed by design
Diligence conclusions end up in investment memos and lender presentations, so every
claim must carry its evidence. Each metric, gap, and opportunity in the output holds
its citation. Ambiguous or conflicting data is flagged for review rather than smoothed
over, and human sign-off gates every conclusion before it moves downstream. The result
is a diligence work product that is faster to produce and easier to defend — to the
investment committee now, and to anyone who re-opens the file later.
---
## Operations & Digital Transformation
URL: https://www.botminds.ai/solutions/operations-and-digital-transformation
> Intelligent process automation for document-heavy operations — AI does the repetitive reading and data entry, your experts review and approve the output.
Most digital transformation programs stall on the same rock: core operations run on
documents, and documents resist generic automation. The usual answers both fail —
asking skilled experts to do repetitive extraction wastes them, and staffing junior
people as data-entry operators behind layers of manual checks just moves the bottleneck.
Botminds takes a different position: AI does the boring work, and your experts become
reviewers of AI output instead of producers of manual output. That single change is
where the productivity multiple comes from.
## What you deploy
The platform ships deployable modules for the common document-heavy operations —
document intake and routing, a command center for governing enterprise documents,
procurement and vendor intelligence, customer-feedback analysis, and web data
harvesting. A library of tested solution templates means you start from a working
pattern, not a blank canvas, and a live process is measured in weeks rather than
quarters.
Under the hood it is one no-code, end-to-end platform: generative AI at the core,
vertically integrated from ingestion to decision, so you are not stitching an OCR tool
to a rules engine to a workflow product and owning the seams.
## Enterprise constraints, met
Operations teams do not get to trade control for speed, so the platform does not ask
them to. Deploy on Botminds cloud, your private cloud, or fully on-prem — no data
leaves your deployment instance. The platform is ISO 27001 and SOC 2 certified and
already runs sensitive workloads. Every automated step leaves an audit trail, every
exception routes to a named reviewer, and dedicated, SLA-backed support covers
onboarding and beyond. The transformation is real because the governance survives
contact with your auditors.
---
## Patent Intelligence Workbench
URL: https://www.botminds.ai/solutions/patent-search-automation
> Semantic prior art search, claim charting, and competitor monitoring across global patent data — every result traceable to the original document.
Patent work breaks when global filing volume outruns human search capacity. Millions of
documents sit across disconnected databases and languages, and Boolean keyword queries
miss the art hidden behind synonyms or deliberately obscure drafting. A missed reference
becomes an invalid patent or an infringement suit.
## Search that reads like an examiner
The workbench ingests global patent repositories, scientific literature, and technical
disclosures, then searches them semantically. It matches on what a claim means, not
which words it uses, so relevant art surfaces even when the terminology diverges across
jurisdictions or decades. Results come back ranked by relevance with the critical claim
limitations highlighted, and anything linguistically ambiguous is flagged for attorney
review rather than silently scored.
Freedom-to-operate work gets the same treatment: product features are mapped against
patent claims in structured claim charts, so FTO opinions stop gating R&D timelines.
Automated alerts track new filings and status changes by named competitors or targeted
technology domains, and filing-trend maps expose saturated areas and white space for
new research investment. Portfolio managers can finally align maintenance spend with
business value instead of renewing by default.
## Traceability is the product
An FTO opinion or invalidity position is only as strong as its evidence chain. Every
search the workbench runs is logged — parameters, sources covered, results returned —
producing a defensible record of what was searched and when. Every extracted claim
element and every ranked reference links back to the original document, so counsel
verifies in seconds instead of re-running the search. This is document-to-decision work
where the decision may be tested in litigation; the audit trail is built for that
standard, and the final call on every matter stays with a human expert.
---
## Peer Comparison & Benchmarking Intelligence
URL: https://www.botminds.ai/solutions/peer-comparison-benchmarking-intelligence
> Compares companies across filings, disclosures, and performance narratives — normalized metrics with every figure cited to its source page.
Peer comparison sounds simple until you do it at scale. Every company reports
differently — different formats, different definitions, different levels of disclosure —
and the analyst assembling the comparison spends most of the time re-keying numbers
from PDFs instead of interpreting them. When the peer set grows or the quarter turns,
the work starts over.
## Benchmarking as a repeatable process
Botminds collects the raw material for the full peer set — annual reports, regulatory
filings, earnings releases, investor presentations, rating reports — in whatever format
it arrives, scanned or digital. Metrics, disclosures, and management commentary are
extracted into one normalized structure, so revenue is revenue and coverage is coverage
across every company in the set.
From that base, the comparison is mechanical rather than heroic: line up performance
across the group, track how each company's metrics and narrative shift period over
period, and flag where a borrower or target deviates from its peers. Credit and risk
teams use the same peer view to position an obligor within its industry; deal teams use
it to test a target's story against companies that have already published theirs. The
method is identical every time it runs, which makes quarter-over-quarter comparisons
honest.
## Numbers you can defend
A benchmark that ends up in a credit memo or an investment committee paper has to
survive the question "where did that number come from." Here the answer is built in:
every extracted figure links to the exact source page, every normalization step is
logged, and conflicting disclosures are flagged for the analyst instead of silently
averaged. Human review gates the final pack. The output is decision-ready intelligence
with its evidence attached — regulator-ready by construction.
---
## Policy & Clause Compliance Validation
URL: https://www.botminds.ai/solutions/policy-and-clause-compliance-validation
> Extracts clauses from policies, contracts, and regulations, maps obligations across frameworks, and validates internal controls against each requirement.
Compliance lives in the gap between what the documents say and what the organization
does. Policies sit in 50-page PDFs on forgotten intranets, contracts carry obligations
nobody indexed, and regulations change faster than the control library that is supposed
to satisfy them. This solution closes the loop: extract every clause, map every
obligation, and validate that a real control stands behind each requirement.
## From static documents to a validated map
Botminds ingests the full corpus — internal policies, contractual clauses, regulatory
frameworks, codes of conduct — and extracts discrete obligations into a structured
register. Each obligation is then matched across frameworks (the same requirement often
appears in several) and mapped to the internal controls meant to satisfy it. What
remains visible is exactly what compliance teams need: requirements with no covering
control, controls justified by outdated policy versions, and clauses whose language is
too ambiguous to map — flagged for expert review rather than force-fitted.
The same clause-level index powers day-to-day use. Employees can ask plain-language
questions — "Can I accept a $50 gift?" — and get a precise, cited answer drawn strictly
from the latest approved version, in Slack, Teams, or a web portal. Sensitive scenarios,
such as whistleblower inquiries, route directly to the appropriate human officer.
## Evidence that survives an investigation
Check-the-box acknowledgments provide weak defense in an investigation. Here the audit
trail is substantive: which version answered which question, who attested to what, and
how each obligation traces to its control and its source clause. Recurring employee
questions expose the policy language that confuses people, so legal teams revise based
on data instead of incidents. Outdated versions stop circulating because there is one
governed source, and every judgment call along the way stays with a human.
---
## Policy Rule Checks & Eligibility Decisioning
URL: https://www.botminds.ai/solutions/policy-rule-checks-eligibility-decisioning
> Tests every loan file against credit policy, eligibility rules, and product constraints — pass, fail, or exception, each with cited evidence.
Credit policy is written down; applying it is where the inconsistency creeps in. Two
analysts read the same file against the same rulebook and reach different conclusions,
because a hundred pages of borrower documents leave room to miss things. This solution
makes the policy check mechanical, so the judgment can be human.
## Every rule, every file, every time
Botminds extracts the decision-relevant data points from the complete borrower file —
income and cash flow from financial statements, obligations from credit reports,
collateral and entity details from supporting documents — and tests them against your
credit policy, eligibility rules, and product constraints. Each rule returns a clear
result: pass, fail, or exception, with the evidence that produced it cited to the source
page in the file.
Nothing is silently waived. A file that fails a debt-service threshold or falls outside
a product's constraints is routed to a credit officer with the triggering rule, the
extracted values, and the source documents in one view. Policy exceptions become
deliberate, documented decisions instead of things discovered later in QC. And because
the same rule set runs identically on every file, decisioning is consistent across
analysts, branches, and volume spikes.
## Regulator-ready by construction
Eligibility decisions get examined — by internal audit, by investors, by regulators.
Every check the platform runs is logged: which policy version, which rules fired, what
evidence supported each result, who reviewed it, and what they decided. Fair and
consistent application of policy stops being an assertion and becomes a queryable
record. The platform never auto-declines or auto-approves on its own; every decision is
human-approved, made faster because the rule work arrives already done and already
cited.
---
## Portfolio Intake & Ongoing Data Collection
URL: https://www.botminds.ai/solutions/portfolio-intake-ongoing-data-collection
> Collects recurring financials, compliance certificates, and reporting packages across the portfolio — chasing, classifying, and filing without spreadsheets.
After closing, every loan turns into a stream of paper: quarterly financials, compliance
certificates, covenant reports, insurance renewals, borrowing base certificates. Across
a growing portfolio that stream becomes hundreds of recurring obligations tracked in
spreadsheets and chased by email — slow, error-prone, and invisible until something is
missed.
## The collection calendar, run by an agent
Botminds holds the reporting calendar for the whole portfolio: which obligor owes which
package, on what cadence, in what form. When a period opens, the platform requests
what's due; when a submission is late, it follows up with a specific ask — the Q2
compliance certificate, naming the document and the period, rather than a generic
reminder. Inbound files arrive in every format and through every channel, and each one
is classified, matched to the right obligor and period, and checked against the
requirement it is meant to satisfy.
Extraction happens on arrival. Key figures and dates come out of each financial
statement and certificate with citations to the source page, so covenant monitoring and
portfolio reporting start from structured data instead of a shared drive of PDFs.
Mismatched periods, missing schedules, and stale documents are flagged immediately, and
persistent gaps escalate to the portfolio team while there is still time to act.
## Why governed collection matters
Regulators and credit committees do not ask whether you requested the financials; they
ask whether you can prove what you received, when, and what you did about the gaps.
Every request, receipt, classification, and extraction here is logged against the
reporting period, producing a complete, auditable record per obligor. Analysts stop
being collectors and go back to being analysts — reviewing flagged exceptions rather
than running the chase, with every decision remaining theirs.
---
## Portfolio Reporting & Exposure Analytics
URL: https://www.botminds.ai/solutions/portfolio-reporting-exposure-analytics
> Concentration, exposure, covenant health, and peer comparison computed from source-cited data across the book — every report reproducible on demand.
Portfolio questions are simple to ask and expensive to answer. What is our exposure to
this sector? Which borrowers are trending toward covenant breach? How does this
quarter's book compare to last year's? In most institutions the answer lives in
spreadsheets assembled by hand from documents someone read weeks ago — accurate the day
they were built, stale by the time they are presented.
## Analytics on governed data
Botminds builds portfolio reporting on data it has already extracted and cited: spread
financials, covenant calculations, loan terms, risk ratings, and reporting packages
collected across the book. Every obligor's data is normalized to the same definitions,
so portfolio-level aggregation is trustworthy — concentration by sector, geography,
product, and single-name exposure computes from comparable numbers rather than
reconciled approximations.
Covenant health rolls up the same way. Instead of learning about deterioration at the
annual review, the portfolio team sees which borrowers are tightening against their
thresholds as each new financial package lands. Comparative views — this obligor
against its peers, this vintage against the last, this quarter against the trend — come
from the same governed base, so the comparisons hold.
## Reports that survive scrutiny
The difference between a dashboard and a portfolio report is what happens when someone
challenges a number. Here every figure in every view traces back through the
calculation to the source document and page it came from. Reports for the board,
investors, or a regulator are reproducible on demand: same data, same definitions, same
citations. Analysts spend their time on the exposures that need judgment — and the
judgment, as everywhere on the platform, stays human, made with the evidence already
assembled.
---
## Post-Closing Quality Control & Audit Review
URL: https://www.botminds.ai/solutions/post-closing-quality-control-audit-review
> Reviews funded loan files for missing documents, data mismatches, and policy defects — a complete, source-cited QC record before the auditor asks.
Post-closing QC has a math problem. Files are hundreds of pages, reviews are manual, so
institutions sample — five or ten percent of funded loans — and hope the defects
cluster where they looked. The defects that surface later, in an audit or a loan sale,
were sitting in the unsampled files all along.
## Review every file, not a sample
Botminds ingests the complete funded file — closing package, note and security
instruments, application, disclosures, funding worksheets — and runs the full QC
checklist against it. Completeness first: every required document present, executed,
and the right version. Then consistency: borrower names, loan amounts, rates, and dates
cross-checked across every document where they appear, and against the system of
record. A mismatch between the note and the funding worksheet is a finding with both
pages cited, rather than a discrepancy someone might notice.
Policy defects get the same treatment. The file is tested against the credit policy and
product rules it was approved under, so undocumented exceptions and missed conditions
surface now — while cure is cheap — rather than during an investor repurchase demand.
Because the platform does the reading, reviewing every funded loan costs what sampling
used to, and QC staff spend their time confirming and curing defects instead of hunting
for them.
## An audit that answers itself
Every check, finding, severity grade, and cure action is logged per file, with each
defect cited to the exact page that proves it. When internal audit, an investor, or a
regulator pulls a file, the QC record is already there: what was checked, what was
found, who reviewed it, how it was resolved. Defect trends across the book feed back to
origination, and every grading decision stays with a human reviewer.
---
## Process Investigation Automation
URL: https://www.botminds.ai/solutions/process-investigation-automation
> Automates batch genealogy, SOP tracking, and manufacturing data analysis for pharma process investigations — findings traced to the original batch record.
When a batch deviates, the clock starts. Product waits in quarantine while MSAT and
quality teams reconstruct what happened from batch records, SOPs, deviation logs, and
lab data — much of it scanned, none of it in one place. The investigation becomes
document archaeology; the root-cause thinking gets whatever time is left.
## Genealogy, SOP checks, and data analysis in one pass
The platform ingests the full investigation corpus — executed batch records, the SOPs
that governed them, deviation reports, and lab results — regardless of format. From it,
the batch genealogy builds automatically: which raw material lots, intermediates,
equipment, and process steps fed the batch in question, and which other batches share
that lineage. Tracing the blast radius of a suspect lot drops from a week-long exercise
to a query.
Executed records are then checked against their governing SOPs, so missed steps,
out-of-sequence operations, and undocumented interventions surface as flagged findings
rather than things a reviewer might catch on page 214. Manufacturing and lab data
correlate across batches, making visible where a parameter drifted and which batches it
touched — the raw material of a defensible root cause.
## Built for a regulated record
A pharma investigation file has one audience that matters most: the next auditor. Every
finding links to the exact page of the batch record, SOP, or lab report that supports
it, and every analysis step is logged. Investigators and QA reviewers approve each
conclusion — the platform assembles evidence; people close investigations. The result
is document-to-decision work at manufacturing speed: faster approvals, shorter
quarantines, and an investigation record that reads the way regulators expect because
it was built that way from the first page.
---
## Process Investigation Workbench
URL: https://www.botminds.ai/solutions/process-investigation-workbench
> Structured root-cause analysis for process deviations — capture evidence, correlate findings, and keep an audit-ready record of every investigation.
Every deviation starts an investigation, and every investigation starts with a
scavenger hunt: batch records in one system, equipment logs in another, the governing
SOP three revisions deep in a document repository. The facts exist. Assembling them is
the work — and while investigators assemble, the clock on release, remediation, and
regulatory response keeps running.
## The case builds itself
The Process Investigation Workbench constructs the investigation file for you. It
ingests the records around a deviation — batch records, equipment and environmental
logs, operator notes, the SOPs in force at the time — and correlates them into a
single, structured case. Timestamps in the equipment log line up against entries in the
batch record. Procedure steps line up against what the SOP actually requires.
Deviations, contributing factors, and candidate root causes surface with the supporting
record attached to each.
Investigators then work the case in a structured cycle: confirm or reject candidate
causes, document the rationale, assign corrective and preventive actions, and track
them to closure. Every finding links to the document, data point, or record that
supports it, so the conclusion is checkable by anyone who reads it — and the case file
updates as new records arrive, without losing the status of items already reviewed.
## Why governed matters here
Process investigations exist because a regulator, an auditor, or your own quality
system will one day ask what happened and how you know. The workbench maintains an
audit-ready history of every investigation cycle: what was found, who reviewed it, what
was decided, and which records supported the decision. Root-cause conclusions are
proposed by the system and approved by people — that is the platform's standing rule.
When the question comes, the answer is already a file.
---
## Procurement Intelligence Hub
URL: https://www.botminds.ai/solutions/procurement-intelligence-hub
> Unified contract, spend, and sourcing intelligence for procurement teams — classify spend, match invoices to POs, and watch vendor risk continuously.
Procurement runs on documents that never agree with each other. The purchase order says one price, the invoice another; the contract that settles it sits in a folder nobody opens. Spend data is scattered across ERPs, card statements, and invoices, so category managers budget against a picture they know is incomplete — and off-contract buying quietly erodes the discounts the sourcing team negotiated.
## One map of enterprise spend, enforced
The Procurement Intelligence Hub ingests spend data from every purchasing channel and classifies it against a standard taxonomy. Line items from invoices, POs, and contracts are normalized and cross-referenced into a single, granular map of what the enterprise actually buys, from whom, and at what price. Dark spend gets a category; maverick purchases get flagged against the approved vendor list and the negotiated contract they bypassed.
Three-way matching — purchase order, receiving receipt, invoice — runs automatically. Standard transactions clear without a human touch; price variances, quantity mismatches, and contract-rate violations route to a buyer with the discrepancy and the source documents side by side. Buying policy is enforced by the system rather than by whoever happens to review the invoice, and every exception decision is logged with its evidence.
## From processing to sourcing intelligence
Clean, classified spend data compounds. The hub surfaces vendor-consolidation opportunities, detects price creep across renewals, and gives sourcing teams line-item usage history and price benchmarks to take into negotiations. Supplier health is monitored continuously rather than vetted once at onboarding, so financial instability or compliance issues show up before they disrupt supply. Every figure in every dashboard traces back to the invoice, PO, or contract it came from — which is what makes it usable in a negotiation, an audit, or a board deck.
---
## RCM Performance Suite
URL: https://www.botminds.ai/solutions/revenue-cycle-management-automation
> Extracts claim and clinical data across formats, scores denial risk before submission, and keeps every RCM metric traced to its source document.
Revenue cycle teams lose money in predictable places: prior authorizations that stall
for missing medical-necessity documentation, claims denied because a code didn't match
the clinical record, appeals that need expert clinical arguments nobody has time to
write. For high-complexity diagnostics — molecular and genomic testing especially —
generic billing tools can't bridge the gap between the science in the record and the
payer's policy language.
## From post-denial recovery to pre-claim prevention
The RCM Performance Suite reads the documents on both sides of that gap. It consolidates
patient encounters, claim forms, and medical records in any format, and applies your
payer and policy logic through a rule engine. Every claim is scored for denial risk
before submission; high-risk claims route to a coding specialist with the specific
mismatch identified, so the error is fixed before it leaves the building.
Prior-authorization packets are assembled from the clinical record and submitted with
the evidence payers require. When denials do happen, the suite drafts appeal letters
that reference the patient's history and the payer's own policy guidelines.
Patients get clarity too: out-of-pocket estimates calculated from real-time eligibility
and deductible status, before the service — which reduces surprise bills, abandonment,
and bad debt.
## Governed for healthcare finance
Every anomaly the suite flags and every metric on the performance dashboards —
turnaround times, denial trends, revenue leakage — is traced back to its origin in the
claim or the clinical documentation. As your team reviews and corrects, the system
learns and refines its predictions. Each denial-risk call is a recommendation that named
staff approve, and the audit trail records who decided what and on which evidence. The
result is fewer denials, faster reimbursement cycles, and numbers finance can defend to
auditors and leadership alike.
---
## Research & Analysis
URL: https://www.botminds.ai/solutions/research-and-analysis
> Document AI for research and analysis teams — extract, structure, and synthesize data from filings, reports, and transcripts, with every claim cited.
An analyst's edge is judgment. Most of the working week goes to something else: finding
the one number that matters inside filings, transcripts, broker reports, and news — each
in a different format, each in a different place. Outsourcing the hunt to data vendors
adds turnaround time and takes extraction quality out of your hands. Botminds puts the
document work on the platform, so the desk's hours go to analysis.
## Seven solutions, one governed platform
Botminds ships pre-built solutions across the research stack: Company Comparable
Analysis Automation extracts operating metrics across industries for valuation work;
the Competitive Insights Hub keeps competitor updates, filings, and market activity in
one verified view; the Corporate Actions Monitor tracks and validates actions from
announcement to execution; the ESG Intelligence Workbench structures disclosures and
maps metrics to reporting frameworks; the Investment Research Workbench standardizes
inputs and keeps models traceable for equity and credit research; the Market
Intelligence Dashboard brings market signals, company updates, and sector movements
into one place; and the Research Workflow Engine runs investigative research with
traceable documentation and checkpoints.
Each ships as a working template: start from it, point it at your sources, and adjust
the outputs. All of them run on the same primitives — reading across formats (scanned
PDFs, spreadsheets, web pages, transcripts), extraction cited to the source page, and
human review where it matters.
## Why cited matters here
A research figure without provenance has to be re-derived before anyone will stake a
recommendation on it. Every number Botminds extracts stays linked to the page it came
from, so an analyst verifies a figure in one click. Datasets tuned to your domain are
achievable in days and stay current as new documents arrive, with structured output
flowing to models and downstream systems through APIs. Deploy in Botminds cloud,
private cloud, or on-prem, so sensitive research never leaves your instance.
---
## Research Workflow Engine
URL: https://www.botminds.ai/solutions/research-process-automation
> A governed research engine that reads your whole document estate — tables and charts included — and returns cited, analyst-grade briefings.
A strategic question rarely fails for lack of information. It fails because the answer
is spread across hundreds of pages an analyst doesn't have time to read: PDFs, web
reports, internal wikis, the memo from last quarter that contradicts this quarter's
headline. Generic AI tools summarize fast, but a summary without citations can't back a
high-stakes decision — and one fabricated fact poisons trust in everything else the tool
produces.
## Answers with provenance
The Research Workflow Engine deploys agents that actually read — across your internal
estate and external sources, including the tables and charts most tools skip. They
extract the relevant facts and construct a coherent answer with a citation on every
claim. Click any generated sentence and the source document opens at the page, with the
supporting passage highlighted. That single property turns a summary you re-verify into
an answer you can forward. Output takes the shape the question demands — comparative
tables, SWOT analyses, literature reviews, executive briefings — tuned to the intent
behind the question rather than a fixed template.
Real document sets disagree with themselves. Instead of averaging the disagreement away,
the engine detects conflicting data points across sources and presents them side by
side — Report A says X, Report B says Y — for the analyst to resolve. Knowledge gaps are
reported as gaps: grounded generation means the system asserts only what it can cite.
## Built to scale a desk
Junior staff answer complex questions with the sourcing rigor of senior analysts,
because the rigor is enforced by the system rather than by experience. The output
accumulates into a shared, queryable knowledge layer, so the organization's collective
research is instantly accessible and always current. Checkpoints and traceable
documentation run through the whole workflow — every briefing carries the record of what
was read, what was found, and who reviewed it.
---
## Risk & Governance
URL: https://www.botminds.ai/solutions/risk-and-governance
> Document AI for risk, governance, and compliance teams — find risky clauses, score documents against your risk profile, and keep humans in the loop.
Risk and compliance documents are the ones you can't send out. They are sensitive, they
are subjective, and the judgment they require differs from one organization's risk
profile to the next — which is why the standard playbook of outsourcing document review
to a data vendor doesn't apply. The work stays in-house, and in-house teams drown in it.
## Teach it your risk profile
Botminds handles the sensitivity, subjectivity, and severity of risk documents inside
your own deployment — Botminds cloud, private cloud, or on-prem, with no data leaving
the instance. Teach the platform to recognize the clauses and patterns your team
considers risky by adding a handful of examples; it then scores incoming documents
against that trained profile, informed by past learning and your own policy. A
human-in-the-loop review step keeps experts in control: the AI identifies candidate risk
clauses, your reviewers verify or reject them, and every verdict feeds back into the
model. Each flagged clause links to its exact location in the source document, so review
becomes verification rather than re-reading.
## Solutions in this family
- **KYC Compliance Accelerator** — customer due diligence with traceable verification
- **Obligation Intelligence Agent** — contractual and regulatory obligations extracted and tracked
- **TPRM Intelligence Agent** — continuous third-party risk monitoring
- **Vendor Risk Analysis Suite** — vendor risk assessed with documented metrics
- **Tender Risk Radar** — risk signals detected across tender documents and submissions
- **Underwriting Decision Engine** — data-driven risk evaluation with traceable inputs
- **Governance Intelligence Agent** — governance frameworks aligned with documented evidence
- **Compliance Case Intelligence Hub** — compliance cases with structured workflows and evidence traceability
Each is a working template: start from it, point it at your documents and policies, and
adjust. All run governed — cited findings, human approval on judgment calls — on a
platform certified to ISO 27001 and SOC 2.
---
## Risk Grading & Credit Recommendation Support
URL: https://www.botminds.ai/solutions/risk-grading-credit-recommendation-support
> Structured risk views, graded against your credit policy, with recommendation summaries and rationale — every input cited, every decision human-approved.
Every credit decision ends in the same artifact: a graded risk view and a recommendation
the institution has to stand behind — to the committee, to audit, and to the regulator.
Producing that artifact today means senior analysts assembling numbers from spreads,
memos, and third-party reports, applying policy from memory, and writing rationale under
deadline. It is slow, it varies by author, and when someone asks where a number came
from, the answer is a hunt.
## From file to graded risk view
Botminds assembles the risk picture from the documents themselves: financial statements,
tax returns, bank statements, credit memos, collateral and third-party reports.
Extracted metrics feed your grading framework — your scales, your thresholds, your
policy — and the platform produces a structured risk view with each factor scored and
each input cited to its source page. Financial spreading, the slowest part of the
assembly, runs 5× faster on the platform.
## Rationale a committee can interrogate
On top of the graded view, the platform drafts the recommendation summary and decision
rationale: strengths, weaknesses, mitigants, and conditions, each grounded in the
underlying evidence. Analysts edit and own the narrative; the platform keeps the numbers
under it consistent, current, and traceable — click any figure and the source document
opens at the right page. No grade or recommendation leaves the system without human
approval, and every step is logged: what was extracted, which policy was applied, who
reviewed, what changed. Routine grading work stops consuming senior analysts, and the
consistency problem disappears, because the framework is applied the same way on the
first case of the day and the fiftieth. For individual cases or portfolio-wide reviews,
the output is accurate, repeatable, and regulator-ready.
---
## Risk Synthesis & Red-Flag Reporting
URL: https://www.botminds.ai/solutions/risk-synthesis-red-flag-reporting
> Consolidates diligence findings into clear risks, red flags, open questions, and mitigation themes — each one traced back to its source document.
By the end of a diligence or review cycle, the findings exist — spread across analyst
workpapers, third-party reports, data-room documents, and a hundred margin notes.
Decision-makers need the synthesis: which risks are real, which flags are red, what
remains open, and what the mitigation themes are. Producing that synthesis manually is
slow, it leans entirely on whoever writes the memo, and the link between a stated risk
and its underlying evidence usually dies in the process.
## Red flags with receipts
Botminds consolidates findings from across the document set into a single structured
report: risks classified and ranked, red flags called out, open questions listed with
what would close them, and mitigation themes grouped across workstreams. Every item
traces back to its source — the clause, the figure, the page — so a reviewer can go from
"related-party transactions flagged" to the exact contract language in one click.
Conflicting findings between sources are surfaced side by side rather than silently
reconciled, and the report updates as new documents arrive without losing the status of
items already reviewed.
## Decision-ready output
The output is built for the meeting where it lands: a committee pack, a diligence
summary, an exception report. Structure is consistent from deal to deal and quarter to
quarter, so readers compare substance instead of decoding each author's format. Analysts
stay in control — they edit, re-rank, and approve before anything is issued, and the
platform records who changed what. Routine consolidation stops consuming senior people,
which is where the capacity for actual judgment comes back from. For credit, risk, and
operations teams, the result is a reporting layer that is accurate, repeatable, and
regulator-ready — with the evidence one click behind every claim.
---
## Sales & Support
URL: https://www.botminds.ai/solutions/sales-and-support
> Document AI for sales and support operations — read contracts, transcripts, and tickets at scale, and turn them into decisions your teams can defend.
A sales cycle generates documents at every step — prospecting notes, deal contracts,
onboarding paperwork — and support generates even more: tickets, call transcripts,
emails by the million. The information that would shorten the next cycle or save the
next account is in there. Someone has to read it, and no team can read at that volume.
Botminds agents do the reading, so your teams act on evidence.
## Six solutions, one governed platform
Botminds ships pre-built solutions across the revenue stack: the Conversation
Intelligence Suite turns sales and support conversations into insights, actions, and
metrics; Contact Center Automation drives case intake, routing, and response
intelligence; the Smart RFP Responder drafts RFP, RFQ, and proposal responses from
reusable, approved knowledge; the SLA Compliance Intelligence Agent monitors
service-level commitments with evidence attached; Customer Contract-to-Support Linkage
aligns support operations to what the contract actually commits; and the Win-Loss
Insights Agent produces traceable analysis of deal outcomes and competitive patterns.
Each ships as a working template you point at your own channels and customize with
point-and-click configuration — no code, no data-science backlog. Results land where
your teams already work, through pre-built connectors and APIs into CRM and ticketing
systems, and the first production workflow is measured in weeks.
## Why source-linked matters here
A claim about a customer — what they were promised, why they churned, what they keep
asking for — carries weight only if it can be checked. Every value Botminds extracts
stays linked to the source document or the exact moment in the transcript, so the check
takes seconds. Feedback loops are built in: corrections teach the models, and quality
is measurable at every stage of customization.
---
## SLA Compliance Intelligence Agent
URL: https://www.botminds.ai/solutions/sla-and-entitlement-document-monitoring
> Extracts service-level terms from contracts and monitors them against live performance data — breach risk flagged early, every commitment evidenced.
Service-level commitments live in contracts; performance lives in ticket queues. In between sits a static CRM field that doesn't know about holidays, business hours, or the custom terms your biggest account negotiated — so breaches are discovered after they happen, penalties follow, and when a customer disputes a deadline, nobody has the timeline to prove otherwise.
## How the agent works
The SLA Compliance Intelligence Agent extracts service-level terms directly from the contracts — response times, resolution targets, support tiers, pause-clock conditions, penalty clauses — and monitors live ticket streams against them. Time remaining is computed truthfully: customer-specific business hours, holiday calendars, and tier all factored in. Agent queues re-rank dynamically so the genuinely at-risk ticket rises to the top instead of the easy one getting cherry-picked. Risk alerts fire hours before a breach, giving managers time to swarm the issue while it can still be saved.
Multi-tier logic that is impossible to police manually — Premium versus Standard versus the one custom contract — becomes configuration the system enforces uniformly. New premium tiers with their own timers roll out without retraining the frontline team.
## Evidence, not arguments
Every commitment tracked carries its trace: the contract clause it came from, the ticket events against it, the pause-and-resume history of the clock. When a customer claims a missed SLA, the response is an audit-ready timeline rather than a negotiation — which is what ends unjustified service-credit payouts. Beyond individual tickets, the agent analyzes the root causes of past breaches — topics, times of day, staffing patterns — and surfaces the adjustments that prevent recurrence. Account managers see real-time adherence and health for their key accounts from the same governed data the support team works from, so success and support argue from one record instead of two.
---
## Smart RFP Responder
URL: https://www.botminds.ai/solutions/smart-rfp-responder
> Drafts RFP, RFI, and DDQ responses from your approved knowledge library — answers cited to source, gaps routed to the right expert, nothing stale.
The answers to most RFP questions already exist somewhere in the company — in past
proposals, wikis, drive folders, and the heads of the same few experts who get asked the
same security questions every quarter. The proposal team's real work is hunting those
answers down, verifying they are still true, and formatting them — which consumes most
of the timeline and leaves little room for the tailoring that actually wins deals.
## First drafts from validated knowledge
The Smart RFP Responder ingests RFP, RFI, and DDQ documents in whatever shape they
arrive — Excel grids, Word documents, portal exports — and shreds them into individual
requirements. It matches each question on semantic intent against your validated
knowledge library and auto-populates high-confidence answers, each linked to its
approved source; drafts arrive around 80% complete. What can't be answered confidently
is never guessed: gap analysis flags the net-new and genuinely complex questions, and
only those route to the right subject-matter expert, with context attached. Experts
answer once; the library remembers.
## A library that stays current
Stale content is the quiet liability of proposal automation — outdated pricing or a
deprecated feature description in a signed response becomes contractual exposure. The
responder curates the library continuously, learning from every edited and approved
proposal and scoring content freshness so aging answers surface for review instead of
shipping silently. Sales messaging stays in lockstep with product reality and security
posture, because both draw from the same governed source. Along the way, the system
flags non-standard requirements and compliance risks hiding in the questions themselves,
and reports which content wins — turning the response archive into competitive
intelligence. End-of-quarter RFP spikes get absorbed by the library, and the team keeps
its weekends.
---
## Social Media & Community Monitoring
URL: https://www.botminds.ai/solutions/social-media-and-community-monitoring
> Reads public posts across LinkedIn, X, Reddit and industry forums, filters the noise, and routes verified buying and churn signals to the right team.
Prospects ask for vendor recommendations on LinkedIn. Frustrated customers vent on Reddit
before they ever open a support ticket. Traditional listening tools catch all of it — and
bury it under job posts, marketing spam and every stray brand mention, so the few signals
that matter drown in notifications nobody reads.
This solution treats public conversation as a document-to-decision problem. Agents read
posts across LinkedIn, X, Reddit and industry forums, classify each mention by intent, and
discard the noise. What survives is a short list of things worth acting on: a prospect
evaluating alternatives, a customer reporting a bug in public, an influencer discussing
your category.
## From mention to action
Detection alone changes nothing if the signal stays in a marketing dashboard. Each
classified mention is enriched with available business context and routed to the team
that owns it — high-intent posts to sales as trackable leads, public complaints to
support as tickets with an SLA clock already running. Marketing, sales and support work
from the same record instead of three disconnected tools, so outreach is specific and
nothing gets handled twice.
Coverage runs across time zones without staffing a round-the-clock social team, and
competitor discussions are captured alongside your own mentions, giving a running read
on market perception.
## Why the audit trail matters
Sentiment scores are easy to produce and easy to distrust. Here, every theme, every
classification and every alert links back to the original public post. When a dashboard
says complaint volume spiked around billing, you can open the actual posts and read them.
That traceability is what lets a team act on the data — escalate, respond, or change the
product — without first re-verifying it by hand. It is the same governed pattern Botminds
applies to every document flow: no conclusion without a source you can inspect.
---
## SOP Unifier
URL: https://www.botminds.ai/solutions/sop-consolidation-and-harmonization
> Consolidates SOPs from QMS platforms, file shares and legacy formats into one governed library — versioned, clause-traceable and audit-ready.
In regulated operations, procedures accumulate faster than they get reconciled. SOPs live
in QMS platforms, local file shares and legacy documents; global standards and
site-specific versions drift apart; and finding the contradictions between them takes
weeks of manual cross-referencing. The result is version conflicts, compliance gaps, and
audits that open with forensic reconstruction instead of a clean record.
SOP Unifier ingests the whole sprawl — Word files, PDFs, QMS exports, even scanned legacy
forms — and consolidates overlapping content into a single harmonized framework. It aligns
clause semantics across documents, surfaces divergences between corporate directives and
local procedures, and routes each conflict to the quality lead who owns the call.
## Change without chaos
When a regulation or internal standard changes, the hard part is knowing every document
the change touches. SOP Unifier propagates updates selectively across affected SOPs and
produces an impact report before anything changes, so quality teams decide with the blast
radius in front of them. A built-in review workflow keeps subject-matter experts in
charge: the system proposes, humans approve, and corrections feed back to improve future
alignment. New sites and acquisitions onboard the same way — digitize their legacy
procedures, align them against corporate standards, resolve the deltas.
## Built for the audit
Every sentence, clause and term in the unified library traces back to its original source
document, and every comparison, change and approval is logged. When an auditor asks why a
procedure reads the way it does, the answer is a click. A consistent SOP library is
useful; a consistent SOP library that can prove its own history is what turns audit
preparation from a recurring emergency into a routine check.
---
## Tender Risk Radar
URL: https://www.botminds.ai/solutions/tender-risk-analysis
> Reads RFPs, exhibits and SOWs against your corporate risk playbook, scores every opportunity, and links each flagged clause to its source page.
The clauses that turn a winning bid into a loss-making contract are rarely on page one.
Uncapped indemnities, liquidated damages and mandatory certifications sit deep in
hundred-page legal exhibits, and finding them means expensive legal review before
proposal work can even start. Meanwhile go/no-go decisions get made on sales optimism,
because the objective read of the documents arrives too late to matter.
Tender Risk Radar reads the entire tender packet — RFPs, contract exhibits, SOWs,
compliance schedules — against your corporate risk playbook. It extracts payment terms,
warranty periods and liability caps without boolean search strings or templates,
identifies non-compliant terms and technical showstoppers, and produces a weighted risk
score for the opportunity. Deviations from your standard positions are tracked clause by
clause, and the system suggests specific redline language for the risks it finds.
## Discipline at bid speed
The consistency is the point. Every opportunity passes through the same model before
resources are assigned, which removes the bias of who is championing the deal. Tenders
that breach defined thresholds — an uncapped liability, a missed certification mandate —
are escalated automatically instead of being discovered three weeks into proposal
writing. Legal review shifts from reading everything to ruling on the flagged exceptions,
so the bid team gets its answer in hours and spends the calendar on writing a winning
response.
## Every flag has a page number
A risk score no one can verify is just another opinion. Every deviation Tender Risk Radar
raises links back to the exact clause in the source document, so when sales asks why a
bid is rated high-risk, legal can show the sentence. Decisions stay human — the system
scores and cites, your team decides — and the record of what was flagged and who accepted
it survives for the post-mortem.
---
## TPRM Intelligence Agent
URL: https://www.botminds.ai/solutions/tprm-intelligence-agent
> Continuous third-party risk monitoring across sanctions lists, court dockets and news — entity-resolved alerts with the source evidence attached.
Point-in-time due diligence has a structural flaw: it only sees the vendor on the day you
looked. Screening happens at onboarding, and then the file goes quiet — while lawsuits
are filed, sanctions lists change, and adverse events accumulate in court dockets and
local news that no one is reading. The threat is rarely invisible; it is just published
somewhere your annual review will not reach for another ten months.
The TPRM Intelligence Agent replaces that snapshot with a standing watch. Agents
continuously read sanctions and PEP lists, court records, regulatory watchlists and news
coverage, looking specifically for the entities in your third-party network — including
sub-tier suppliers whose problems surface as your disruptions.
## Fewer alerts, better alerts
Legacy keyword monitoring buries legal teams in false positives — flag every "Smith" and
soon nobody reads any of them. This agent resolves entities before it alerts: it
distinguishes your counterparty from a name lookalike, scores severity based on the
specific relationship and jurisdiction, and groups related events into a single risk
profile instead of a drip of disconnected notifications. When a new sanctions list
publishes, the entire entity database is re-screened against it immediately, ahead of any
review cycle.
## Evidence you can act on
An alert that says "possible litigation risk" starts an investigation; an alert that
links to the docket entry ends one. Every finding the agent raises carries its source —
the court record, the list entry, the article — so legal can verify in minutes and move
straight to mitigation: escalate, renegotiate, or exit the relationship. Classification
is machine-made, but the judgment stays human, and the trail of what was flagged, when,
and from which source is preserved for regulators and internal audit alike.
---
## Underwriting Decision Engine
URL: https://www.botminds.ai/solutions/underwriting-process-automation
> Ingests broker submissions, ACORD forms and loss runs, scores each risk against your appetite, and hands underwriters a decision-ready file.
Underwriting desks lose business two ways: quoting slowly, and quoting the wrong risks.
Thousands of broker submissions arrive by email, the good ones buried among the rest,
and the data an underwriter needs — insured details, limits, loss history — sits in
PDF applications and Excel loss runs that take hours to re-key. Meanwhile guideline
adherence varies by individual, and risk creep accumulates quietly in the portfolio.
The Underwriting Decision Engine automates the submission lifecycle from inbox to queue.
It ingests broker emails, ACORD forms and loss runs, extracts the risk data without
templates, validates each submission against your specific appetite, and enriches the
file with external data so the underwriter opens a complete risk profile instead of a
stack of attachments.
## Discipline encoded, speed gained
Appetite rules run before a human touches the file: submissions outside defined bounds —
excluded classes, loss thresholds — are declined at intake with the reason recorded.
What remains is ranked so the best business gets quoted first, and the underwriter's
time goes to risk selection rather than data entry. Guideline validation applies the
same logic to every file, which is how consistency stops depending on who happened to
pick up the submission. Seasonal spikes and new markets are absorbed by the same
pipeline, without hiring a bench of underwriting assistants first.
## Traceability from quote to portfolio
Every extracted field links back to its source document, and every validation and
declination is logged with the rule that produced it. Pricing models and underwriting
decisions reference the same structured data, so actuarial teams and the front line
argue from one set of numbers instead of two. When a decision is examined later — by
audit, by reinsurers, by your own portfolio review — the file shows exactly what the
underwriter saw and why the engine ranked it where it did.
---
## Underwriting Decision Support
URL: https://www.botminds.ai/solutions/underwriting-decision-support
> Gives underwriters policy checks, issue summaries and explainable recommendations — every finding cited to source, every decision human-made.
An underwriting decision is only as good as the file behind it, and the file is usually
the problem: PDFs, spreadsheets, scans and reports in inconsistent formats, read under
time pressure, with policy checks done from memory. Senior people spend their day on
routine verification, results vary by who picked up the case, and when a decision is
questioned later, reconstructing why it was made takes longer than making it did.
Underwriting Decision Support reads the whole case file — applications, financial
statements, bank statements, credit reports — extracts the decision-relevant data, and
runs it against your credit policy. The underwriter gets a structured briefing: which
rules pass, which fail, what the exceptions are, and a recommended outcome with the
reasoning written out.
## The underwriter stays in control
The system prepares the decision; the underwriter makes it. Recommendations are
explainable by construction — each one states which policy rules fired and which
document evidence triggered them, with every finding cited to the source page. The
underwriter accepts the recommendation, overrides it with judgment, or sends the file
back for more information. What changes is the starting point: instead of opening a raw
file, the underwriter opens a checked, summarized, evidence-linked case and spends their
attention on the genuinely hard calls.
## Governance built into the flow
Every extraction, policy check, recommendation and human decision lands in the audit
trail. When a regulator or internal reviewer asks why a case was approved, the answer is
the actual record — rules evaluated, evidence cited, who decided, and what they saw at
the time. Policy-governed workflows mean the checks applied are the ones your credit
committee wrote, applied the same way to case one and case ten thousand. Consistency at
that level is what turns decision support from a convenience into a control.
---
## Underwriting-Ready Package Assembly
URL: https://www.botminds.ai/solutions/underwriting-ready-package-assembly
> Cleans, validates and structures the borrower file so underwriting starts from a complete, indexed package instead of a raw document dump.
Most underwriting delay is spent waiting. Files arrive incomplete,
documents are misfiled or stale, and the discovery happens late: an underwriter opens the
package, finds the missing tax year or the mismatched entity name, and the file goes back
in the queue while someone chases the borrower. Every round trip adds days, and every
manual sort adds errors.
Underwriting-Ready Package Assembly moves that work upstream. As borrower documents
arrive — tax returns, bank statements, financial statements, IDs, collateral documents,
in any format from any channel — the system classifies each one against your checklist,
extracts the identifying data, and cross-validates it across the package. Does the name
on the bank statement match the application? Is the financial statement inside the
required freshness window? Is the signature actually there?
## Problems found on day one, not day ten
Gaps and defects surface at intake, when they are cheapest to fix. The system generates
specific follow-ups — the exact document, the exact tax year, the exact missing page —
rather than a generic "please send documents" that starts another guessing round. By the
time the file reaches an underwriter it is complete, indexed and internally consistent,
which means decisioning starts immediately and pull-through improves because borrowers
are not lost to week-long silences.
## Structure that survives the decision
The assembled package is evidence-linked as well as tidy. Every classification and
every extracted value carries a citation to the page it came from, and the assembly
history — what arrived when, what was flagged, what was cured — is logged. Downstream,
that structure pays twice: the underwriter works from validated data instead of raw
scans, and audit or QC can reconstruct exactly how the package was built. It is the
document-to-decision pattern applied to the very first mile of the credit process, where
most of the friction lives.
---
## Vendor Intelligence Hub
URL: https://www.botminds.ai/solutions/vendor-intelligence-hub
> One governed record per vendor — contracts, certificates, spend and risk in a single place, with expirations and SLA breaches flagged automatically.
Ask three systems about the same vendor and you get three answers: the contract is in a
shared drive, the spend is in the ERP, the contacts are in someone's inbox, and the
insurance certificate expired four months ago without anyone noticing. Without a single
trustworthy record, vendor management runs on anecdote — and risk reviews happen only at
onboarding, which is precisely when vendors look their best.
The Vendor Intelligence Hub builds and maintains that single record. It ingests
onboarding documents, contracts, certificates, tax forms and performance data, and
resolves them into a vendor master that updates itself — contacts, certifications,
financial health, spend — instead of decaying the day after it is created.
## From filing cabinet to early-warning system
Storage is the smallest part of the job; the hub watches what it holds. Insurance
certificates and tax forms are validated against expiry dates, with renewal workflows
triggered directly with the vendor before a lapse becomes an exposure. Delivery times,
error rates and responsiveness are tracked against contractual SLAs, giving operations
hard data where there used to be anecdotes. Sanctions matches, bankruptcies and adverse
media on any active vendor raise alerts the day they surface, not at next year's review.
Onboarding gets faster too: a self-service portal lets vendors upload their own documents
into automated validation, clearing queues without manual chasing.
## Governance is the product
Every metric, alert and score in the hub links back to the document or data source that
produced it — the clause in the contract, the line in the SLA report, the certificate on
file. Correlating spend against performance identifies which partners earn their volume
and which need remediation, and because the evidence travels with the insight,
procurement can act on it in a vendor conversation without a research detour. One
governed record, continuously verified, turns third-party management from reactive
cleanup into actual oversight.
---
## Vendor Risk Analysis Suite
URL: https://www.botminds.ai/solutions/vendor-risk-analysis-suite
> Spreads vendor financials, correlates cyber and legal risk signals, and scores every supplier — each metric linked back to its source document.
Vendor risk assessment has a depth problem. Questionnaires capture what vendors say about
themselves; validating those claims against evidence is manually impossible at scale, so
tick-box answers stand in for truth. Meanwhile the real signals sit unread: analysts
spend hours re-keying PDF financial statements into Excel to compute liquidity ratios,
cyber scores and legal disputes live in separate silos, and the compound risks that
precede a vendor failure — declining cash flow plus executive departures plus a control
lapse — are never seen together.
The Vendor Risk Analysis Suite reads the actual evidence. It ingests 10-K filings,
private audited financials, SOC 2 reports and security questionnaires, spreads the
financial data automatically, and computes solvency and liquidity metrics without a
spreadsheet in sight. Then it correlates financial, cyber and legal signals into a single
risk picture per vendor, with anomaly detection and trend analysis running across the
portfolio — the view siloed tools cannot produce.
## What the vendor says versus what the documents show
Self-attestation gets checked, not accepted. A questionnaire answer about security
controls is compared against the vendor's SOC 2 report and external evidence; a claim of
financial health is tested against the computed ratios from their own statements.
Deteriorating solvency indicators flag a supplier months before a missed shipment, and
because the analysis is automated, that depth extends to Tier 2 and Tier 3 suppliers —
where surprises usually originate, and where manual teams never had capacity to look.
## One scorecard, fully cited
Credit risk and operational risk teams work from the same standardized vendor scorecard,
and every number on it links back to the source document — the line in the filing, the
section of the SOC 2 report, the questionnaire answer it contradicts. Scores are
machine-assembled; conclusions stay human. When a risk committee decides to exit or
remediate a supplier, the decision rests on evidence anyone in the room can open and
read.
---
## Watchlist & Early Warning Intelligence
URL: https://www.botminds.ai/solutions/watchlist-early-warning-intelligence
> Detect portfolio deterioration early and route exposures into governed watchlist workflows, with every trigger traced to its source document.
Deterioration rarely announces itself. It shows up as a missed covenant certificate, a
slipping current ratio buried in an interim statement, a supplier dispute in the local
press. When monitoring depends on quarterly reviews and analyst bandwidth, those signals
sit unread until they become losses. Watchlist & Early Warning Intelligence reads them
continuously.
## What it does
The solution ingests the documents and data that describe each exposure — financial
statements in any format, covenant compliance certificates, bank statements, loan
agreements, and external news. Agents extract the metrics that matter, normalize them
across borrowers and formats, and test each exposure against the thresholds your credit
policy defines. When a signal crosses a line, the exposure is routed into a structured
watchlist workflow: flagged, scored, and packaged with the evidence that triggered it.
Every data point is linked back to its source. An analyst reviewing a flag can click
through to the exact statement line or agreement clause that produced it. No guesswork,
no reconstructing the reasoning after the fact.
## Why governed matters here
A watchlist entry is a credit decision with regulatory weight. Moving a borrower onto —
or off — a watchlist changes provisioning, reporting, and relationship handling, so the
reasoning has to survive an examiner's questions months later. That is why the platform
enforces two things without exception. First, every trigger, metric, and classification
carries its citation, so the audit trail writes itself as the work happens. Second, no
exposure changes status on model output alone: the agent detects and routes, an analyst
decides. Policy-governed workflows keep the process consistent across the portfolio,
whether you monitor fifty names or fifty thousand.
Credit, risk, and operations teams get the same thing from it: earlier signals,
consistent handling, and a defensible record — instead of a spreadsheet someone updates
when they have time.
---
## Web Intelligence Harvester
URL: https://www.botminds.ai/solutions/web-data-extraction-automation
> Crawl targeted sites and portals, extract fields into a consistent schema, and track changes over time — every data point linked to its source URL.
Every web data project has two separate problems: reaching the page and reading the page.
Most teams solve the first with rule-based crawlers that break every time a site changes,
and the second with people copying values into spreadsheets. Web Intelligence Harvester
replaces both.
## What it does
You define the target — competitor sites, regulatory portals, public registries, supplier
price lists, online databases — with point-and-click setup rather than scraping code.
Record-and-replay navigation lets crawlers reach content behind menus, filters, and
dynamic rendering, and built-in throttling keeps crawling well-behaved. Extraction is
schema-aware: you declare the fields once, and the system reads them consistently across
pages and sites, normalizing everything into a single structure.
The harvester then keeps watching. Change detection re-visits monitored pages and raises
delta alerts when a value moves — a rate updated, a regulation amended, a product
delisted. Instead of a one-off scrape, you get a live, versioned dataset. Teams use it to
track competitors, regulatory updates, and market signals, and lenders use it to enrich
credit files with registry and public-source data.
## Data you can defend
Web data is only useful if you can say where it came from. Every extracted value carries
its source URL and capture time, so anyone downstream can open the exact page a number
was read from. Crawler quality is checked and improved through feedback from your
subject-matter experts — when extraction drifts, a reviewer corrects it once and the
correction sticks.
Output goes wherever the work happens: download formats for analysts, or out-of-the-box
integrations and APIs that feed downstream systems directly. The result is
document-to-decision intelligence from the open web — structured, current, and traceable
— without a maintenance backlog of hand-written scrapers.
---
## Win-Loss Insights Agent
URL: https://www.botminds.ai/solutions/win-loss-insights-agent
> Analyze deal outcomes, buyer feedback, and competitive patterns across your pipeline — every insight cited to its source and gated by access controls.
Every closed deal leaves evidence: the calls, the proposal versions, the objections, the
competitor that showed up in round two. Most of it scatters across CRM fields,
transcripts, and shared drives, and the pattern behind the outcomes never gets read. The
Win-Loss Insights Agent reads all of it.
## What it does
The agent connects the sources where deal evidence lives — CRM records, call transcripts,
proposals, RFP responses, and buyer feedback — and builds a semantic index across them.
Where keyword search returns a list of links to open and reconcile, the index connects
concepts across file types: a pricing objection raised on a call, the clause it refers to
in the proposal, and the discount that followed in the CRM.
On top of that index, agents analyze outcomes. Why do deals stall at security review.
Which competitor wins on price and which on integrations. What changed in the quarter
losses spiked. You ask in plain English; the agent answers with a synthesis built
exclusively from your internal data — no outside guesses — and every claim carries a
click-to-citation link to the document it came from, so a skeptical sales leader can
verify the source in one click.
## Governed by design
Deal data is sensitive, so access control is inherited rather than bolted on. The agent
answers each user only from documents that user is already authorized to see — existing
permission boundaries carry straight through to generated answers. Hallucination
guardrails keep synthesis grounded in retrieved sources, and PII redaction protects buyer
contacts where policy requires it.
The practical effect is a shared, checkable source of truth about why you win and lose.
Sales, product, and leadership stop debating anecdotes and start reading the same cited
evidence — and when a veteran seller leaves, the reasoning behind their deals stays
behind.
---
# Recent writing
## Credit is civilization's source code — and agents are about to rewrite it
URL: https://www.botminds.ai/post/credit-is-civilizations-source-code
> Lending is the load-bearing layer of the modern world — $348 trillion of priced trust holding up homes, factories, research and human ambition. What happens to all of it when agents can read, verify, reason and underwrite? A long letter from the CTO's desk.
Everything above the line is financed by the line. Homes, schools, hospitals, factories, offices, research — all of it stands on priced trust. The spark is what's new.
The oldest written artifacts our species possesses are ledgers. Clay tablets from Uruk and Ur, five thousand years old, recording who borrowed barley, how much, and when it was due — older than any poem or prayer we have ever dug up. The strongest evidence says writing itself was invented for accounting. Debt came first. Literature is a side effect of lending.
Eight hundred years later, the Code of Hammurabi — one of humanity's first legal systems — spends an astonishing share of its 282 laws on credit: caps on grain interest, caps on silver interest, debt forgiveness in flood years. Lending was the first thing we ever regulated at civilizational scale.
I keep coming back to this because it reframes what our industry actually is. Strip the jargon away and a loan is a promise about the future, priced in the present, between strangers. Lending is the technology that lets trust scale past the village — past the hundred-odd people you can personally vouch for — to millions of strangers cooperating across decades. It is, quite literally, civilization's source code: the trust protocol everything else compiles against.
And for five thousand years, that protocol has had one hard constraint: **somebody has to read the tablets.** A human being has to look at the evidence, judge the promise, and write down a decision. Every cost, every delay, every bias and every exclusion in the modern credit system flows from that single bottleneck.
That constraint just broke. I want to walk you through what I believe happens next — carefully, with numbers, because the numbers are staggering.
## The load-bearing layer nobody looks at
Start with scale. The Institute of International Finance measured global debt at a record **$348 trillion** at the end of 2025 — roughly three times world GDP. Governments carry about $107 trillion of it, non-financial companies about $101 trillion, households about $65 trillion. US households alone hold $18.8 trillion of debt, $13.2 trillion of it mortgages. Global consumer lending is a $27 trillion machine. Private credit crossed $2 trillion in 2024 and Preqin projects $4.5 trillion by 2030.
These numbers are so large they stop meaning anything, so make it personal instead. Almost everything you touched today was borrowed into existence. The home you woke up in — mortgage. The building you work in — construction loan. The road you drove — municipal bonds. The phone in your pocket — corporate debt financing a supply chain across nine countries, plus receivables financing at every hop. The coffee shop on the corner — a working-capital line. Your salary, in more companies than you'd like to know, clears payroll off a revolving credit facility. The medicine in your cabinet was a decade of venture debt and R&D credit before it was a pill.
All of it is debt as **infrastructure** — the invisible layer that lets the future pay for the present. Credit comes first and prosperity follows; economists have known this since long before fintech. The places where collateral can't be pledged and credit can't flow are the places that stay poor, no matter how talented their people are.
Here's the thought experiment I use to make the point land. Suppose credit froze tonight — every new loan, every rollover, every facility renewal halted, with money itself still flowing freely. How long before civilization notices? We actually have the answer, because in September 2008 the commercial paper market — the mundane, boring market where companies borrow for 30 to 90 days to make payroll — seized for a matter of *days*, and household-name corporations came within a week of missing salaries. Days. The modern world runs about ninety days deep on trust, and it refinances that trust continuously, forever. Lending is the economy's heartbeat.
> If lending is civilization's source code, then every flaw in lending is a flaw the whole civilization inherits. And the flaws are not small.
## The machine is magnificent — and broken
Because when you actually inspect this load-bearing layer, what you find is a masterpiece of institutional engineering running on a paleolithic bottleneck: human reading.
Look at the friction first. The Mortgage Bankers Association puts the average cost of originating a single US mortgage at **$11,076** — it peaked above $14,000 in 2023. Nearly all of that is the price of *processing*: document chasing, re-keying, verification, stipulations, committee. ICE's data says the average mortgage still takes about **38 days** to close — and that's a modern record; a few years ago it was 49. McKinsey's benchmark for SME lending at banks is grimmer: **three to five weeks to a decision, nearly three months to cash**. Three months, for a business that needed the working capital *this* month.
The friction is pure logistics — moving facts out of documents and into decisions, at human reading speed, at human reading cost.
Now look at who the friction lands on, because this is the part that should make everyone uncomfortable. Underwriting has a mostly *fixed* cost — it costs a bank nearly as much to read the file for a $40,000 loan as for a $4 million one. So the system does the economically rational, humanly corrosive thing: it ignores small borrowers. The IFC's 2025 estimate of the credit gap for formal micro, small and medium enterprises is **$5.7 trillion** — $8 trillion if you count informal firms. Seventy percent of MSMEs in emerging markets can't get adequate financing, and these are the firms that make up over 90% of all businesses and roughly half of world GDP. The Asian Development Bank measures a **$2.5 trillion** trade finance gap, with SMEs rejected at a 41% rate. The World Bank's 2025 Findex still counts **1.3 billion adults** with no financial account at all. Even in the United States, the CFPB's latest estimates put roughly **32 million adults** — one in eight — outside conventional credit scoring: seven million with no file at all, twenty-five million with files too thin to score.
Read that list again: it is a list of **unread people** — people and businesses whose evidence of creditworthiness exists (sales ledgers, harvest cycles, mobile-money histories, order books, rent paid on time for a decade) but has never been economically worth a human's reading time. The cruelty of the current system is precisely that it is rational: when diligence costs thousands of dollars per file, the poor are unprofitable to understand.
And when files *do* get read, human judgment carries human noise. The landmark Berkeley study of US mortgage data (Bartlett, Morse, Stanton and Wallace) found face-to-face lenders charging risk-equivalent Latino and Black borrowers about **7.9 basis points more** on purchase mortgages — roughly **$450 million a year** in excess interest — and estimated over a million minority applications rejected between 2009 and 2015 that identical white applicants would have had approved. The same study's algorithmic lenders showed *no* detectable approval discrimination and about a third less pricing disparity. Two loan officers reading the same file on different afternoons produce different answers. We have simply learned to call that variance "judgment."
Every one of these behaviors is the rational response to a single constraint: underwriting is a *reading profession*, and reading has never scaled. Until now.
## What an agent actually is — and why it's not "AI in banking, again"
Banks have had AI for decades: scorecards since the 1950s, neural networks in fraud since the 1990s. So what's different?
Everything that was called AI in lending until now was a **number about the past**. A credit score compresses your history into three digits and hands it to a human who still has to do the actual work — read the bank statements, tie the tax return to the P&L, catch the related-party transaction in note 14, check the collateral registry, write the memo, defend it in committee.
An agent is a system that does that work itself: it **reads** every page of every document with citations back to the source line; it **verifies** claims against registries, bureaus and bank data; it **reasons** over your credit policy the way an analyst reasons — but over the entire file, not the sample a tired human has time for; it **writes down its reasons** in language a regulator can audit; and it **acts** within governed bounds — assembling the file, chasing the missing document, drafting the memo, flagging the exception to a human whose accountability is real.
The distinction matters because lending's bottleneck has always been *processing evidence*, and that is exactly where agents land. McKinsey estimates generative AI can add **$200–340 billion of annual value** to banking; BCG puts the retail-banking prize at $370 billion of additional annual profit by 2030, with agents' share of that value nearly doubling by 2028. In corporate credit specifically, McKinsey's early agentic deployments report **20–60% productivity gains and roughly 30% faster credit turnaround** — and credit-memo agents cutting manual workloads by a third to a half. And yet the adoption paradox is stark: EY finds 99% of banking executives familiar with agentic AI but only **31%** actually moving to implementation; in Fenergo's survey, 93% of financial institutions plan agents within two years while just **6%** run them today. Translation: essentially everyone can see it coming; almost no one has rewired the lending process around it yet. Which means the interesting part — the part below — is still ahead of us.
## The five inversions
Here is what I believe agentic lending actually does to the industry. "Faster loans" is the boring, first-order prediction — the equivalent of guessing the internet would speed up mail. The real story is five structural inversions.
### 1. The cost of diligence collapses — and the bottom of the pyramid becomes bankable
When an agent underwrites, the marginal cost of reading a file falls from thousands of dollars toward the cost of computation — cents, and falling. Follow that to its conclusion: **the $800 loan can receive the same quality of diligence as the $8 million loan.** The fixed-cost logic that made small borrowers unprofitable to understand simply dissolves.
That $5.7 trillion MSME gap? I'd argue most of it is a *reading-cost* gap wearing a risk gap's clothes. The seamstress with three years of mobile-money records, the farmer with a decade of harvest receipts, the two-person machine shop with a full order book: their evidence was always there. It was just never worth $11,000 of human process to examine. The 41% SME rejection rate in trade finance is substantially a cost-of-diligence rejection rate. When diligence is nearly free, rejection has to earn its keep on risk alone. Entire continents of creditworthy humans become, for the first time in history, *legible*.
### 2. Credit stops being an event and becomes a condition
Today, credit is episodic. You apply; you are photographed financially; the photograph is filed; the file goes stale the day it closes. Your bank meets your business three or four times a decade and extrapolates wildly in between. Covenants are checked quarterly. Default arrives as a surprise that was visible for months in data nobody was reading.
An agent never stops reading. The same system that underwrote you can watch the *actual* cash flows, the *actual* receivables aging, the *actual* order book — continuously, with consent, under governance. Underwriting and monitoring merge into a single ongoing act of attention.
A balance sheet stops being a photograph and becomes a heartbeat. Trouble stops being a default and becomes an early conversation.
What follows is profound: **credit limits that breathe** with your actual season; pricing that drifts down as your real risk drifts down, without you begging for a review; distress detected as a pattern in week two instead of a missed payment in month six — met with restructuring while restructuring can still work. Default rates fall because the relationship finally, literally pays attention.
### 3. The loan application dies
The application is an artifact of reading scarcity — a form invented so scarce human attention could consume you in summary. When attention is abundant, the form is absurd.
Within a decade, I don't think most credit will begin with anyone "applying." Your agent — your business's fiduciary software, holding your permissioned data — will negotiate with lenders' agents continuously and silently. It will notice you're about to take a purchase order that strains working capital, canvass forty lenders' agents overnight, exchange evidence under consent, and present you one decision in the morning: *"Here are three offers; this is the best one; here's the reasoning; sign here."*
Lending becomes a conversation between fiduciary machines — with humans holding the pen on anything that matters.
Notice what this does to market structure. Switching costs collapse — your agent re-shops your entire credit stack continuously, so incumbency stops being a moat and *price* has to be. Price discovery becomes per-borrower and near-real-time. The subsidy that inattentive borrowers currently pay to attentive ones — the loyalty tax that funds much of consumer finance — evaporates. Some lending revenue pools shrink; I won't pretend otherwise. The ones that remain will be earned on underwriting skill rather than customer inertia. That is a better industry.
### 4. The past stops masquerading as the future
Credit history and collateral are *proxies* — inventions of a world where the actual truth about risk, the forward cash flows and real contracts and real behavior, was too expensive to read. We deny the future capital because the past was too expensive to verify.
Agents invert this. A system that can read and verify everything can price the loom, not the land under it; the order book, not the credit file; the demonstrated discipline of three years of wallet history, not the absence of a bureau record. The evidence is no longer hypothetical. Upstart's 2025 access-to-credit analysis reports its AI model approving **41% more applicants at 33% lower average APRs** than a traditional credit-score model — with the largest gains for Black and Hispanic borrowers. FinRegLab's independent testing found that machine-learning models using cash-flow data were the most predictive across *every* demographic subgroup, lifting approvals without lifting defaults. An NBER study of "invisible primes" found that borrowers a traditional model would reject at a 70% higher rate turn out, under alternative-data underwriting, to be excellent credits. And all of that is with today's models, on yesterday's data rails. Extend the curve. The 32 million credit-invisible Americans, the 1.3 billion unbanked — these populations were only ever unread.
### 5. Fairness becomes an architectural property, not an aspiration
This is the inversion I care about most, and the one people find most counterintuitive — because "algorithmic bias" has become shorthand for a dystopia.
But hold the current system honestly in view: judgment that varies by afternoon, by accent, by zip code; disparities measured in basis points that compound into generational wealth gaps; decisions whose true reasons are unrecoverable even in litigation, because they lived in a loan officer's head. **You cannot audit a hunch. You can diff a policy.**
An agentic decision, done right, ships with its own evidence trail: every factor, every weight, every citation back to a source document, every policy rule that fired. Bias stops being an accusation to litigate and becomes a defect to detect — a regression you can test for before deployment, measure in production, and patch in the next release. Underwriting fairness becomes an engineering discipline with the properties engineering disciplines have: reproducibility, monitoring, rollback. No human credit committee, however well-intentioned, has ever offered that.
## What keeps me up at night
I'm a builder of these systems, so read this section as the confession it is. Four things worry me.
**Monoculture.** If every lender's agent descends from the same two or three foundation models, credit errors correlate. Humanity has run diversified, de-correlated credit judgment for five millennia — thousands of banks, millions of loan officers, all wrong in *different* ways. That diversity was a stabilizer we never appreciated. A monoculture credit system could misprice an entire asset class simultaneously and at machine speed. 2008 took eighteen months to propagate; an agentic mispricing could take eighteen hours. The BIS has been signaling exactly this in its recent AI chapters, and they're right to.
**The fraud arms race.** Synthetic identities — people assembled from fragments of real data — already had US lenders holding a record **$3.3 billion** in exposure by the end of 2024, against *human* verifiers. Agents will verify better — and generative tools will fabricate better. Documents stop being evidence unless they're cryptographically anchored to their source. The entire evidentiary chain of lending has to be rebuilt for a world where anything can be forged and everything can be checked. That work has barely begun.
**Bias at scale.** Inversion five has to be earned. An ungoverned agent trained naively on decades of biased lending history will industrialize that bias, with a confidence score attached. The difference between the utopia and the dystopia here comes down to governance alone: bias testing as a release gate, decision logs as a legal artifact, humans accountable for policy. Fairness-by-architecture is available — and it has to be deliberately chosen, engineered and enforced.
**Accountability.** You cannot fine an agent, jail it, or make it feel shame — the load-bearing deterrents of financial regulation for centuries. So accountability has to be *engineered*: every agent action attributable, every decision explainable, every autonomy boundary explicit, a named human owning every policy. And regulation itself must invert — from reviewing individual decisions after the fact to certifying decision *systems* before deployment, the way we certify aircraft rather than inspecting each flight.
This is, not coincidentally, a description of how we build at Botminds. Blast-door isolation between agent and system of record. Citations on every extracted fact. Evaluation harnesses before autonomy. Audit trails as first-class product, not compliance afterthought. The lesson of every powerful technology is that the guardrails *are* the revolution. A fast, opaque credit machine would be worse than the slow one it replaced.
## The world on the other side
Zoom all the way back out, to where we started — clay tablets, barley, the first trust protocol.
Talent is evenly distributed across the human species. Capital access never has been. That mismatch — between where ability lives and where credit reaches — may be the single largest reservoir of wasted human potential on Earth. Every unread seamstress, every unfunded machine shop, every farmer paying informal-market rates for working capital, every student whose thin file priced her out of an education: that is the compounding, invisible cost of underwriting at human reading speed.
Now imagine the other side. Diligence that costs cents. Credit that watches over a business like a partner instead of photographing it like an examiner. Capital that finds a good order book in Nairobi as easily as a good credit score in Nashville. Trouble met at week two with restructuring instead of month six with repossession. Every decision carrying its reasons, inspectable by the borrower it affects. The interest-rate spread between the world's connected and unconnected borrowers — mostly a *reading premium*, all along — grinding toward zero.
I don't know exactly how fast this arrives. Adoption in banking is never a straight line, and the failure modes above are real. But the direction feels as clear to me as anything in my career: the five-thousand-year-old constraint at the heart of lending — *somebody has to read the tablets* — is gone. Every prior time the cost of trust fell, civilization got bigger: writing gave us cities, double-entry bookkeeping gave us the Renaissance firm, the joint-stock company gave us the industrial age. The pattern is not subtle.
Lending built the modern world quietly, one read file at a time. Agentic lending will build the next one — and it will read *everyone's* file.
Somewhere out there right now is a founder, a farmer, a lab, a town — creditworthy in every way that matters and invisible in every way that's measured. The most consequential thing our industry will do this decade is finally read them.
That's the future we're building toward at Botminds — agentic underwriting with citations, governance and audit at the core, [live today in credit teams](/platform/agentic-finance) that have stopped accepting the ninety-second-per-page world. If you run lending and any paragraph above felt personal, [I'd genuinely like to talk](/demo).
*— Ansari*
---
## Would we notice? The question behind Pulse
URL: https://www.botminds.ai/post/pulse-observability-platform-that-watches-itself
> Every system I trust can answer one question: would we notice if it went quietly wrong? Why observability became a first-class Botminds surface — and how it caught a real incident during its own test run. From the CTO's desk.
There's a question I ask about every system we run, and I've learned to ask it before any other: **would we notice?**
Not "is it working" — everything is working, right up until it isn't. The question is whether anyone would *know*, and how fast, when something goes quietly wrong. Queues backing up at 2am. A latency creep that adds four seconds per document and nobody files a ticket because four seconds doesn't feel like an incident. A cost line drifting 30% over a month of small decisions. None of these page anyone. All of them are exactly the kind of failure that erodes an operation from the inside.
For an AI platform, this question carries extra weight — because our customers ask it about *us*. Trust in agentic AI isn't only about whether the agents produce correct answers. It's about whether the platform underneath them is demonstrably healthy while producing them. So this cycle, observability stopped being our internal tooling and became a first-class surface of the product. We call it **Pulse**.
## One live picture, not twelve stale ones
The failure mode of most observability isn't missing data — it's scattered data. Health in one tool, queues in another, infrastructure in a third, cost in a spreadsheet someone updates on Fridays. When a leader asks "is everything okay?", someone assembles a picture. Assembly takes time; incidents don't wait for it.
Pulse's design rule was blunt: **the picture is simply up.** All day, one surface — workloads moving through the system, processing latencies, infrastructure health, cost signals — environment-aware, so an operations leader sees their world and a platform admin sees all of it. Nobody assembles anything.
The design rule: nobody assembles the picture. It's simply up, and it's the same picture for everyone who needs it.
## Then it did something better than pass its tests
Here's the story I'll be telling for a while. During Pulse's own verification run — our engineers were literally testing whether the anomaly detection worked — it flagged an irregularity in **live traffic**. Not a seeded test case. A real one, in the platform, right then.
We'd built the feature to answer "would we notice?" It answered the question about itself, mid-test, before the test finished. The fix shipped before any customer-facing impact. I have rarely seen a cleaner proof that a capability is real: the instrument interrupted us while we were still calibrating it.
The proof I didn't plan: the instrument caught a real incident while we were still testing the instrument.
## Dashboards describe yesterday. Instruments interrupt today.
That's the distinction I want buyers to hold onto. Plenty of platforms have dashboards — retrospective, pretty, opened for the quarterly review. An instrument is different: it watches continuously and it *interrupts you* when reality diverges from expectation. One is furniture. The other is the difference between a near-miss and a headline.
And I'd go one step further: observability is a **governance feature**. We talk constantly about governing the decision — every number [cited to its source page, every judgment routed through human approval](/technology). Pulse governs the system underneath those decisions: continuous evidence that the platform doing the work is healthy, performant, and within budget. When we say "certified and battle-proven," this is part of what the words cost us to say honestly.
## Ask your platform the question
Whatever you run your operations on — us or anyone — ask it my question. *Would we notice?* Then ask the follow-up that separates instruments from furniture: **has it ever interrupted you?** If the answer is no, you don't have observability; you have wallpaper.
Every solution on the platform, from [borrower intake](/solutions/borrower-intake-document-collection) to [financial spreading](/solutions/financial-spreading), now runs under Pulse's watch. [Request a demo](/demo) and ask to see the platform's heartbeat live — anomalies included, if we're lucky.
---
## You wouldn't hire a team off one interview question
URL: https://www.botminds.ai/post/crew-evaluations-measure-your-ai-workforce
> Single-agent accuracy is the wrong metric for production AI. Why we built Crew Evaluations — scoring whole agent teams against golden cases, with a promotion gate — from the CTO's desk.
The AI industry has trained buyers to ask one question: *how accurate is the model?* It's a fine question — for a demo. In production, it's the wrong unit of measurement entirely, and I want to explain why we spent an engineering cycle building the machinery that measures the right one.
Here's the thing about real document operations: no single agent runs them. A borrower file moves through a **crew** — an extraction agent reads the statements, a normalization agent maps them to your template, a drafting agent writes the memo, an approval flow routes exceptions to a human. Four specialists, three handoffs. And after watching thousands of these runs, I can tell you where production failures actually live: **in the handoffs**. The extractor was right. The normalizer was right, given what it received. And the final answer was still wrong — because "right, given what it received" is exactly how teams fail.
Single-agent metrics are blind to this. It's like hiring a whole team by asking each person one interview question, separately, and never watching them work together.
Why single-agent accuracy is the wrong unit: three green agents, three amber handoffs, one wrong answer.
## So we built evaluations for crews
**Crew Evaluations** shipped this cycle, and the design principle was simple: measure the unit you actually deploy.
You define golden cases — real documents with known-correct outcomes, your hardest ones, the scanned tax return with the creative Excel sidecar. Then you run the *whole crew* against them: individual agents, orchestrated workflows, meshes of cooperating agents. The platform scores the end-to-end result **and every intermediate step**. So the finding is never just "the memo was wrong." It's "extraction was right, normalization dropped the minority-interest line on multi-entity statements." That's not a report card — that's a repair manual.
And evaluations stream live. You watch the crew work, agent by agent, artifact by artifact, every number appearing with its citation. I've sat in rooms where this changed the conversation in real time: an operations leader stops asking "do we trust the AI?" — which is unanswerable — and starts asking "which step do we tune next?" — which is engineering.
The point of measuring is the gate: crews earn production; regressions get caught before an underwriter ever sees them.
## Promotion is earned, not assumed
The part I care most about as CTO: the gate. Crews that clear their evaluation bar get promoted into production. Changes that regress get stopped — before a customer, before an underwriter, before an auditor. Software engineering learned this discipline decades ago; nobody ships to production on "the demo looked good." Your AI workforce deserves the same rigor, and now it has it. It's also the only honest way to keep saying "battle-proven" release after release — proof has to be *re-earned* every time something changes.
## The question to take away
If you're deploying AI on work that matters, stop asking vendors how accurate their model is. Ask them: **how do you evaluate the team, where do failures between agents show up, and what stands between a regression and my production queue?** If the answer is a benchmark table, keep looking.
If you want to see a crew evaluated against your own documents — messy ones welcome, that's the point — [request a demo](/demo). Crew Evaluations run under the same governance core as everything else we ship: [citations, approvals, audit trail](/technology), all the way down to [financial spreading](/solutions/financial-spreading).
---
## The most expensive screen in enterprise software
URL: https://www.botminds.ai/post/command-deck-navigate-your-agentic-operations
> Why we rebuilt the front door of the Botminds platform as a Command Deck — and why I now believe navigation is a governance feature, not a UI garnish. From the CTO's desk.
Here's a question I started asking last quarter, and it made a few people uncomfortable: **what is the most expensive screen in our platform?**
Everyone guesses the clever ones — the spreading workbench, the agent designer, the evaluation console. Wrong. The most expensive screen is the one between a person and their work. The listing page. The launcher. The screen nobody designs seriously because "it's just navigation." I watched a credit operations manager — one of the sharpest operators I know — spend the first ninety seconds of every task getting *to* the task. Multiply that by every analyst, every task, every day, across every customer. That's not a UX nitpick. That's an institutional tax, and nobody was budgeting for it.
So we stopped treating our front door as furniture and rebuilt it as a product. We call it the **Command Deck**, and it shipped this month.
The tax nobody budgets for: five screens between a signed-in analyst and the actual work, versus one deck and one move.
## What we actually built
Sign in, and you land on a deck, not a directory. Your workspaces, your recent destinations, the solutions your team lives in — one governed surface. Browsing the wider estate opens as an overlay, so exploring never costs you your place. And the logo is a constant escape hatch: however deep you've drilled, one click brings you home. Small decision, disproportionate calm.
Then we made everything answer to the keyboard. Jump workspaces, open a solution, pull up browse — hands never leave home row.
Muscle memory as a feature: the whole journey from "I need the Meridian spreads" to working on them, without touching the mouse.
## Why a CTO cares about a landing page
Because navigation is governance's first mile. That's the sentence I kept repeating internally, so let me earn it.
Every platform team eventually learns this the hard way: when the governed path is slow, work leaks. People export to spreadsheets. They keep side channels. They batch things up "to do properly later." None of that is malice — it's friction economics. The moment the certified workflow, with its citations and approval gates and audit trail, is also the *fastest* path to done, the leakage stops on its own. Governance stops being a police function and becomes gravity.
So no, the Command Deck is not a cosmetic release. It's the part of governance nobody writes compliance documents about: making the right way the easy way.
## The standard I'd hold any platform to
If you're evaluating agentic platforms — ours included — here's a test that takes thirty seconds and tells you more than a feature matrix: sign in, start a stopwatch, and measure the distance to real work. Then ask how much of that journey your least-patient analyst will tolerate at 9am on a Monday, two hundred times a quarter.
We measured ourselves and didn't love the answer. Now the deck is live for every platform user, and the stopwatch tells a different story. Come run it yourself — [request a demo](/demo), or see what's waiting behind the front door: [Agentic Finance](/platform/agentic-finance) and the [technology that governs it](/technology).
---
## Agentic Credit Decisioning: How NBFCs Can Cut TAT Without Losing Risk Control
URL: https://www.botminds.ai/post/agentic-credit-decisioning-how-nbfcs-can-cut-tat-without-losing-risk-control
> How Indian NBFCs can cut lending turnaround time with agentic credit decisioning while keeping every decision explainable, traceable, and human-approved.
For many Indian NBFCs, the lending bottleneck is no longer demand. It is decision capacity.
Applications are coming in faster. Borrowers expect quicker responses. Boards want portfolio growth. Regulators expect stronger governance, traceability, and borrower protection.
But the credit process still depends heavily on manual work. Analysts collect documents, pull bureau data, review bank statements, check GST, refer to MCA filings, prepare CAM notes, and track exceptions across multiple systems.
That model does not scale cleanly.
Adding more credit analysts may increase throughput, but it also increases cost, inconsistency, review load, and operational dependency. The bigger opportunity is to change the credit workbench itself.
That is where agentic credit decisioning comes in.
### What agentic credit decisioning actually means
Agentic decisioning is not another rules engine.
Traditional automation follows fixed logic: if this condition is met, trigger that action. Useful, but limited. It breaks when cases are incomplete, documents vary, or policy interpretation requires context.
Agentic credit decisioning works differently. It helps credit teams assemble, interpret, and route lending cases with more intelligence.
A credit agent can:
- Collect borrower data from internal and external sources
- Extract financial, banking, bureau, GST, and company information
- Identify missing documents and inconsistencies
- Prepare a decision-ready borrower profile
- Highlight policy deviations and risk indicators
- Draft credit notes and reviewer summaries
- Maintain a clear audit trail for every step
The credit officer remains in control. The agent does not replace judgment. It removes the non-judgment work around the judgment.
**Why it matters:** Credit teams should spend more time assessing risk and less time assembling files.
### **Why NBFCs are looking at this now**
Three pressures are making the old model harder to defend.
### **1. Turnaround time is becoming a revenue risk**
Fintechs and digital lenders have changed borrower expectations. Even in commercial lending, customers now expect faster responses, cleaner communication, and fewer document loops.
Every delay has a cost. A delayed sanction can mean a lost borrower, slower disbursement, or weaker relationship control.
**Why it matters:** TAT is no longer just an operations metric. It directly affects growth.
### **2. Growth cannot depend only on headcount**
Many NBFCs want to grow books faster, enter new segments, or expand geographically. But if every new file requires proportional analyst effort, scale becomes expensive.
The question is not whether the credit team can work harder. The question is whether the operating model can support higher volume without weakening control.
**Why it matters:** Agentic workflows help increase decision capacity without simply adding more people.
### **3. Governance expectations are rising**
The Reserve Bank of India’s Digital Lending Directions, 2025 have reinforced expectations around accountability, transparency, borrower protection, and digital lending governance for regulated entities.
For NBFCs, this means speed alone is not enough. Every decision must be explainable, traceable, and aligned with policy.
**Why it matters:** The winning model is not faster lending at any cost. It is faster lending with stronger control.
### The three shifts agentic decisioning enables
## **Shift 1: From document collection to decision-ready case files**
Today, analysts spend too much time gathering information from different systems and portals. Bureau reports, banking data, GST filings, MCA details, financial statements, and internal policy checks often sit in separate workflows.
An agentic system can assemble this information into one decision-ready file. It can extract key fields, reconcile mismatches, flag missing data, and prepare a structured borrower view.
**Why it matters:** The first credit review starts faster and with fewer gaps.
## **Shift 2: From static scorecards to policy-aware risk assistance**
Scorecards are useful, but they cannot capture every exception, segment nuance, or changing risk signal.
Agentic decisioning does not remove the institution’s credit policy. It works around it. The agent can check the case against policy, identify deviations, explain why a case needs human review, and help reviewers focus on the real risk questions.
**Why it matters:** Credit teams get more consistent files, better deviation visibility, and faster review cycles.
## **Shift 3: From periodic monitoring to early warning intelligence**
Many institutions still review portfolio risk monthly or quarterly. By then, early stress signals may already have turned into collection issues.
Agentic monitoring can track borrower behavior, repayment patterns, sector signals, document changes, and other risk indicators continuously.
**Why it matters:** NBFCs can move from delayed review to earlier intervention.
### Is your institution ready?
Agentic decisioning works best when three basics are in place:
- **Clear credit workflows**
Your current process, approval matrix, policy rules, and exception paths should be documented.
- **Accessible data sources**
The system should be able to access the data needed for credit assessment, including internal systems and external sources.
- **Leadership ownership**
This cannot be treated as a small technology experiment. It needs sponsorship from business, credit, risk, and operations.
### The real opportunity
Agentic credit decisioning is not about removing credit officers from the process.
It is about giving them a better operating system.
The institutions that move first will not just approve faster. They will build cleaner credit files, stronger audit trails, better portfolio visibility, and lower cost per decision.
For NBFCs trying to grow without losing risk control, that is the real advantage.
---
## From Abundance to Action: Botminds at the Middle East Gen AI & Analytics Summit 2026
URL: https://www.botminds.ai/post/from-abundance-to-action-botminds-at-the-middle-east-gen-ai-analytics-summit-2026
> Recap of the Middle East Gen AI & Analytics Summit 2026 in Dubai: keynotes on the era of abundance and moving AI from pilots to governed production.
On February 5, 2026, Botminds participated as a Presenting Partner at the Middle East Gen AI & Analytics Summit & Awards (6th Edition) in Dubai. The event brought together enterprise leaders, innovators, and AI practitioners to discuss the evolving role of Generative AI in real-world business environments.
Across keynote sessions, panel discussions, and technical deep dives, one theme consistently surfaced: enterprises are moving beyond experimentation. The focus is shifting toward operationalizing AI systems that are scalable, structured, and accountable.
Here are the key highlights from the summit.
## Opening Keynote: The Era of Abundance
Gokul Ganapathi opened the summit with a keynote centered on the concept of the *Era of Abundance*.
Today, intelligence is no longer scarce. AI capabilities are widely accessible. The constraint is no longer technological possibility — it is operational discipline.
The discussion emphasized that in an environment where “anything and everything seems possible,” the differentiator for enterprises will be how responsibly and systematically AI is deployed. The future belongs to organizations that build systems capable of scaling accountability alongside intelligence.
## From Pilot Limbo to Production Reality
In his session, *From Pilot Limbo to Production Reality*, Vikas Anand addressed a challenge many enterprises quietly face: widespread AI experimentation without production impact.
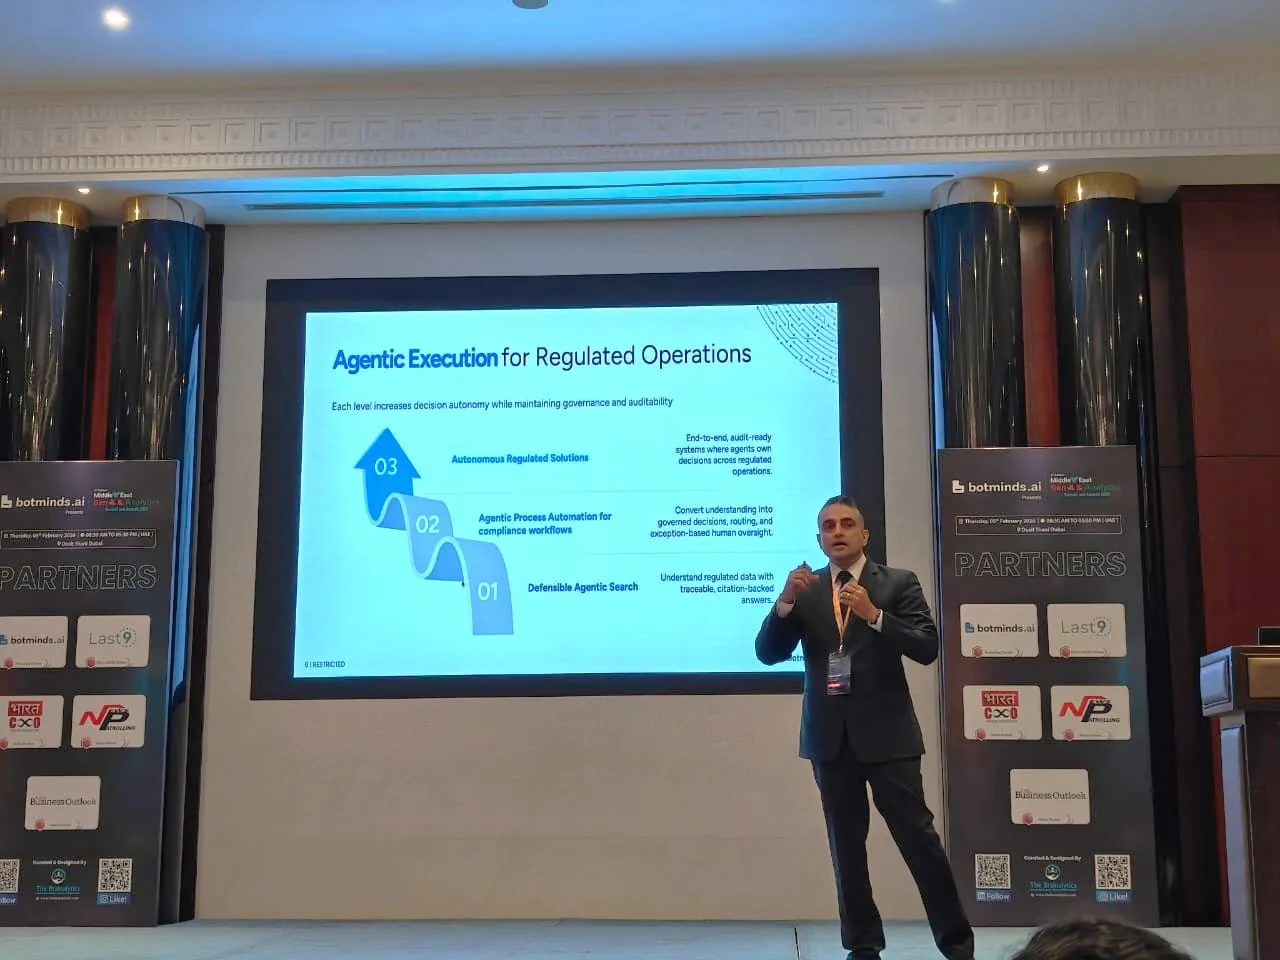
Across industries, organizations have:
- Innovation labs
- Copilot tools
- Isolated proof-of-concepts
Yet few initiatives transition into enterprise-wide operational systems.
The session outlined an agentic blueprint for moving from fragmented pilots to structured, production-grade deployments. The focus was not on adding more tools, but on embedding AI within governed workflows, measurable outcomes, and enterprise processes.
The conversation resonated strongly with leaders seeking clarity on how to scale AI beyond experimentation.
## Voice of Customer: From Listening to Action
Beniston Jeyapaul and Gorpam Azmatulla Khan led a session on how Agentic AI transforms Voice of Customer into actionable enterprise workflows.
Traditionally, VoC systems generate dashboards, sentiment scores, and reports. The discussion demonstrated how agentic systems move beyond insight generation to operational response — enabling enterprises to:
- Diagnose issues across channels
- Trigger structured workflows
- Maintain traceability across actions
- Close the loop between signal and execution
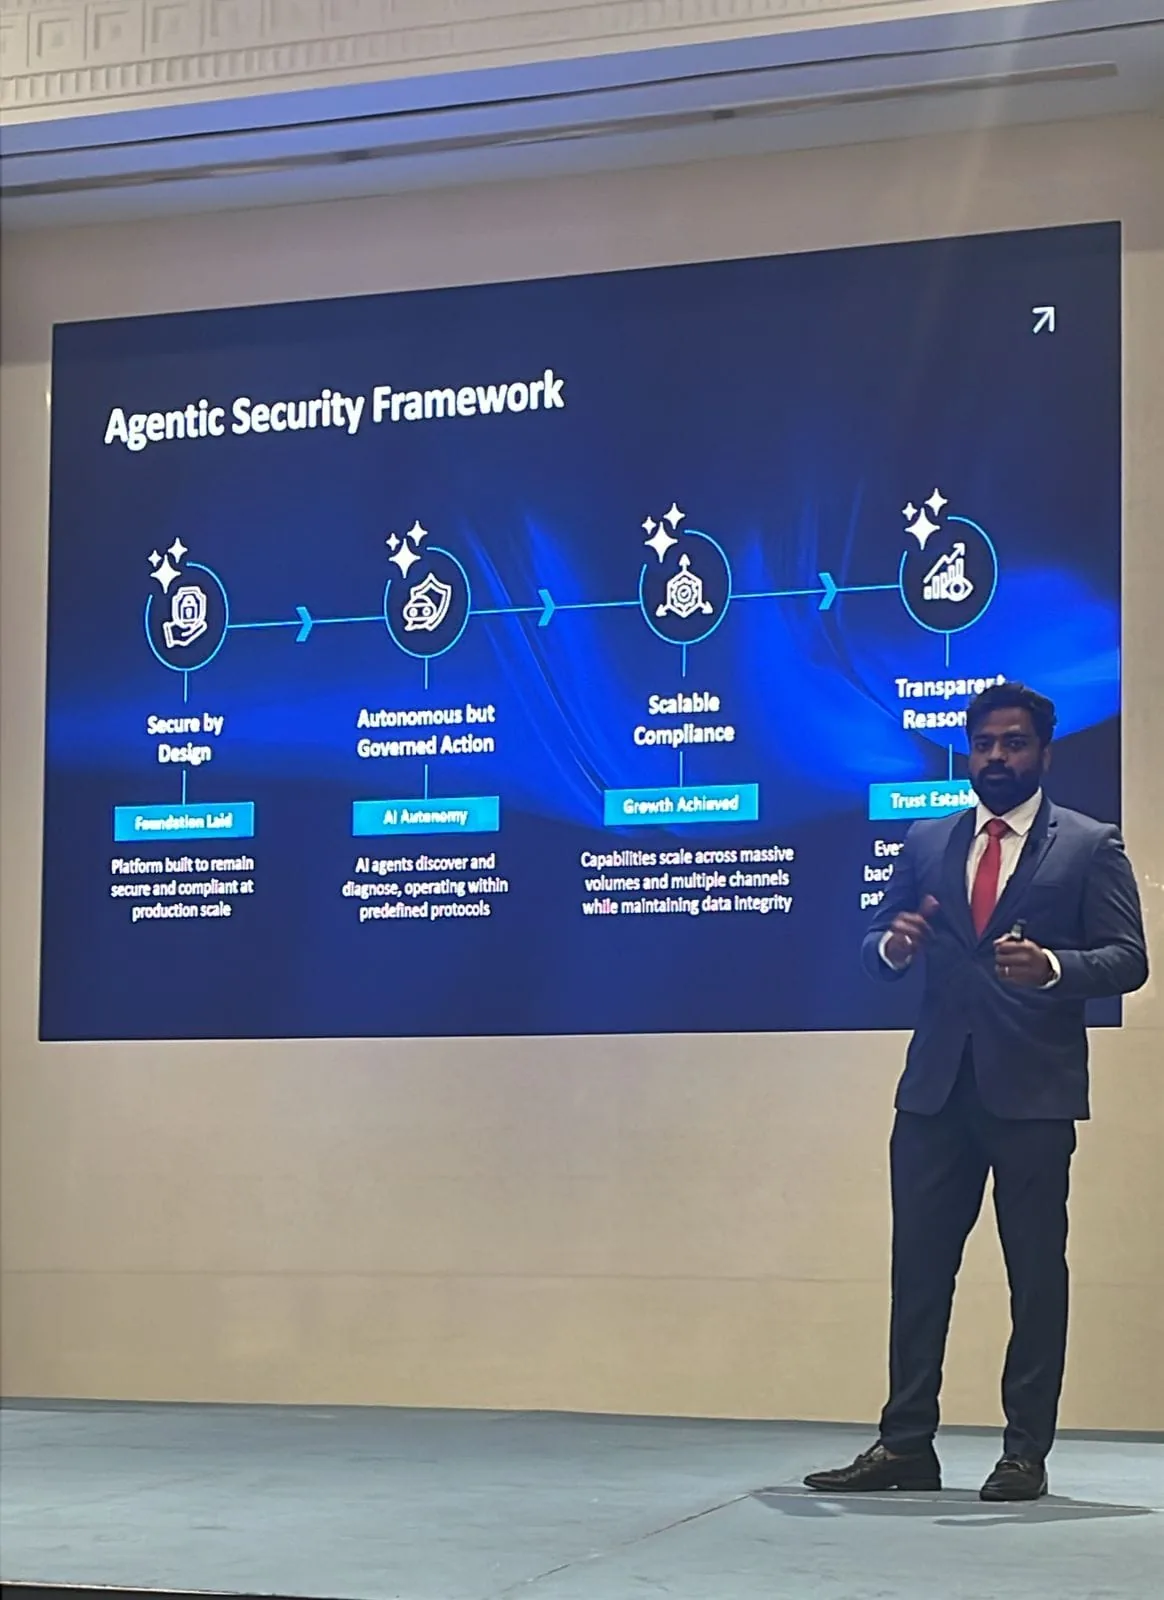
A key supporting concept presented was the **Agentic Security Framework**, emphasizing secure-by-design architecture, governed autonomy, scalable compliance, and transparent reasoning. The framework underscored that operational AI systems must be architected for scale and defensibility from the outset.
## Panel Discussion: GenAI-as-a-Service
The panel on *GenAI-as-a-Service: Enabling Scalable Innovation for the Enterprise*, moderated by Vikas Anand, brought together cross-industry perspectives on deploying generative AI at scale.
The discussion explored:
- Enterprise adoption realities
- Service-layer models for AI deployment
- Organizational readiness
- Practical barriers to scaling innovation
The conversation was grounded, pragmatic, and reflective of where enterprises truly are — transitioning from isolated experimentation toward structured AI service models.
## A Shift in Enterprise Conversations
Across sessions, panels, and audience interactions, one trend was clear:
The enterprise AI conversation is maturing.
Leaders are asking fewer “what can AI do?” questions and more “how do we operationalize this responsibly?” questions.
From abundance to production.
From experimentation to structure.
From insights to action.
The summit reinforced that agentic systems — designed for scale, governed in operation, and transparent in reasoning — will define the next phase of enterprise AI.
## Continuing the Conversation
If you would like access to the session materials or a walkthrough of the concepts presented at the summit, our team would be glad to connect.
Contact us to continue the discussion on operationalizing Agentic AI within your enterprise environment.
---
## Thinking Behind Botminds
URL: https://www.botminds.ai/post/the-future-runs-on-accountability-inside-the-thinking-behind-botminds
> AI makes execution nearly free, but accountability cannot be automated. Why governance is the real rate limiter — and the thesis Botminds is built on.
### The Future Runs on Accountability: Inside the Thinking Behind Botminds
We’ve been thinking a lot about a weird paradox we haven’t quite internalized yet.
Everyone says AI gives “unlimited leverage.” And at the execution level, that’s basically true. Models can write code, draft policies, generate designs, run analyses, spin up workflows, and coordinate other models. Add agents. Add tools. Add robots or humanoids. At some point, execution stops being the hard part.
But here’s the catch: the world isn’t structured around execution. The world is structured around governance. That’s literally how civilization stays coherent.
Even if AI can produce anything, it doesn’t mean we can safely use anything it produces. And it doesn’t mean we can scale output infinitely. Something else rate-limits reality.
That “something else” is accountability. And once you see it, it’s hard to unsee.
## Society is a four-layer system (whether we admit it or not)
Most people look at society like it’s just “people + jobs + markets.” That’s too flat. The actual structure is layered, because rules and consequences exist. A cleaner model is four layers:
1) The Normative Layer: This is the legitimacy layer. Constitutions, laws, regulations, and the principles underneath them. It defines what’s allowed, what’s forbidden, and what society claims to value.
2) The Interpretive Layer: Rules are never self-executing. Someone has to decide what they mean in context. Judges, regulators, auditors, compliance teams, oversight bodies. This layer translates “the rule” into “what happens here.”
3) The Accountability Layer: This is the “names on the line” layer. Executives, owners, signatories, directors, managers with real responsibility. When things go wrong, this is where blame, liability, and consequences land.
4) The Execution Layer: The layer that actually does work. Builders, operators, engineers, analysts, workers, service roles, creators. This is historically the biggest layer by headcount.
That’s basically civilization: values → meaning → responsibility → action. And it works because it gives society a structure that can scale without collapsing into chaos.
## AI detonates the execution layer first
Now insert ubiquitous AI. AI doesn’t start by rewriting constitutions. It starts by doing tasks. It eats the execution layer. The marginal cost of execution trends toward zero.
The moment execution becomes cheap, we get abundance: abundant output, abundant automation, abundant “solutions”, abundant reasoning, abundant syntheses, abundant plans, etc
But abundance creates a new problem. If models can produce 1,000 “good options,” humans don’t magically become 1,000 times better at choosing. So pressure flows upward.
The execution layer stops being the bottleneck. The bottleneck moves into interpretation and accountability.
## The real rate limiter: you can’t automate blame
This is where a lot of naive AI narratives break. AI can do the work. AI can propose the action. AI can even explain why it thinks the action is justified.
But when the action causes harm, violates policy, breaks a regulation, or creates a systemic incident, the AI doesn’t go to court. The AI doesn’t face the regulator. The AI doesn’t lose its professional license. The AI doesn’t get fired. The AI doesn’t carry reputational damage.
Some humans or institution does. That’s the accountability layer. And if accountability doesn’t scale, then execution can’t scale safely. Period. So yes, AI gives “unlimited leverage.”. But you can’t cash unlimited leverage without an accountability system that can govern it.
Accountability is the speed limit of AI.
## A back-of-the-envelope simulation (because numbers force clarity)
Let’s take 8 billion humans. Roughly speaking, today society looks like: 75% in execution and 25% in the top three layers (normative, interpretive, accountability). Don’t take that as precise. Take it as structural.
So that’s: 6 billion humans mostly executing and 2 billion humans mostly governing / interpreting / being accountable
Now imagine AI replaces execution to the point where the execution layer is effectively “gone” for humans. All those 6 billion people shift upward. Reskilled, redeployed, re-institutionalized — whatever you want to call it.
So now we have 8 billion humans operating largely in the top layers. If we keep the system proportional, meaning we still want a functioning pyramid, just scaled, then we now need a new execution base that matches this expanded governance capacity. That execution base becomes AI: agents, systems, robots, humanoids, autonomous workflows.
In our thought experiment, the math lands around: 8B humans operating in the top layers, 24B AI “execution equivalents” in the bottom layer, 32B total “actors” in the global system
Even in a world with effectively infinite compute, infinite agents, infinite automation… the system hits a ceiling determined by what the top layers can responsibly govern. So the real constraint isn’t compute. It’s not even talent. It’s governance throughput.

## This is why “post-scarcity” won’t feel like what people think
People think: if we get 4x GDP per capita, life becomes 4x better. Sometimes it does. Up to a point, money buys real outcomes: health, safety, mobility, education, time. But after baseline needs are met, the bottleneck shifts again. More output doesn’t automatically produce more meaning. It produces more choice, more optionality, more complexity. And complexity has a cost: more decisions, more coordination, more risk surface area, more regulatory exposure, more failure modes, etc
So in the high-AI world, the central human question becomes: What are we willing to do? What are we not willing to do? Who owns the consequences? Can we defend the decision? That’s civilization-level design.
## The accountable layer becomes the new “working class”
This is the part we find most under-discussed. If execution becomes abundant, then the heavy labor shifts upward into: deciding, approving, constraining, auditing, defending, owning risk, etc.
That’s cognitive and legal work. It’s still labor. And it’s labor under consequence. In that future, the scarcest resources aren’t ideas. They’re: defensibility, traceability, clarity of ownership, governance that can keep up with automated action
And the group under the most stress is the accountability layer — because they’re the ones who have to sign off on machines doing 10,000 things a day. That layer cannot remain artisanal. It has to become engineered.
## So what does the world actually need?
If you accept this model, the “AI platform” story changes. Most AI tooling today is obsessed with execution: generating content, automating tasks, coding faster, agent frameworks, productivity boosts, etc. All useful. But incomplete.
Because the limiting factor is shifting toward: compliance, governance, policy enforcement, auditability, lifecycle control, versioned, explainable, defensible decisions, etc. The world is going to need systems that make accountable humans scalable.
That’s the real infrastructure gap.

Where Botminds fits: building for the rate limiter
Botminds isn’t being designed for the execution layer. We’re designing it for the people who have to answer when execution goes wrong. That’s the accountable layer: the signatories, the executives, the compliance owners, the risk leaders, the operators of regulated systems.
And the platform has to do four things extremely well, because those are the survival requirements of accountability at scale:
1) Pre-built agentic blocks: So you don’t start from scratch. You assemble governed capability like architecture.
2) Trust + Traceability: Every action must have provenance: what happened, why it happened, what it used, who approved it, what policy it followed, what model version ran it. If you can’t defend the chain, you can’t scale the chain.
3) One platform for risk, compliance, and governance: Because fragmentation is fatal when execution explodes. Governance can’t live across 12 tools and 20 dashboards. It has to be centralized enough to be coherent.
4) Lifecycle management with versioning built in: Accountability is temporal. What was allowed last quarter may not be allowed next quarter. Policies evolve. Models drift. Regulations change. If you can’t version the world, you can’t govern it. That’s the foundation: governed execution at scale.
## Why we structure solutions as L1 / L2 / L3
It maps directly to what accountable people actually need, in the order they need it.
### L1: Agentic Search for Defensive Decisions
Before you act, you need to know. But “knowing” isn’t about retrieval anymore — it’s about defensibility. Not “give me an answer.”
More like: “show me the evidence, the context, the policy implications, the sources, and the reasoning trail so I can sign my name under it.” That’s accountability-grade search.
### L2: Agentic Automation for Governed Processes
Automation is easy. Safe automation is hard. Accountable teams don’t want “automate everything.” They want: “automate what can be bounded, audited, constrained, and reversed.” This is where most enterprise automation will go: not wild agents, but governed workflows with controls.
### L3: Agentic Systems for End-to-End Operations
Finally, you run autonomous systems — but inside a governance envelope. The system should operate like a machine, but behave like an institution: policy-aware, audit-ready, version-controlled, exception-handling, escalation paths for humans
This is how you get end-to-end autonomy without creating end-to-end liability chaos.
## AI can scale execution, but governance scales reality
If you remember one idea from all this, it’s this: AI makes execution abundant. Accountability makes execution usable. In the coming years, the biggest winners won’t be the teams who generate the most output. Output becomes cheap.
The winners will be the teams who can scale: defensible decisions, governed automation, accountable autonomy. Because the real bottleneck isn’t compute. It’s whether society can safely absorb what compute can do.
And that’s exactly where the next software era is going to be built: not at the bottom of the pyramid, but at the rate limiter.
That’s the layer we’re building for.
---
## 2025 in Review: A Year of Intentional Progress at Botminds AI
URL: https://www.botminds.ai/post/2025-in-review-a-year-of-intentional-progress-at-botminds-ai
> A look back at Botminds in 2025: a Rs 200 crore MoU with the Government of Tamil Nadu, a new office, new leadership, and campus hiring.
2025 was an electrifying year of bold, focused advancement for Botminds AI! We didn’t just chase momentum—we seized it with purpose, building unbreakable scale, pushing enterprise capabilities to new heights, and delivering game-changing outcomes that truly matter.
This was our year of soaring maturity: sharpening our platform for the toughest real-world challenges, forging powerful alliances, fueling talent with fresh energy, and creating impact that resonates. As we look back, these milestones have supercharged our foundation and ignited unstoppable innovation for what’s next!
### Forging Powerful Ecosystems Through Game-Changing Collaboration
A defining moment of 2025 was signing a landmark Memorandum of Understanding with the Government of Tamil Nadu, backed by a massive Rs 200 crore investment and the creation of over 250 high-impact jobs! This partnership is a testament to the unstoppable power of uniting industry, academia, and government to drive responsible AI innovation.
We’re laser-focused on delivering compliant, locally empowered solutions—actively shaping a vibrant ecosystem for scalable, governed AI that transforms industries and communities alike.
By focusing on compliant, locally relevant solutions, we're contributing to a broader ecosystem that supports scalable AI deployment and governance.
## 10 Years of Botminds – A Decade of Building, Belief, and Breakthroughs
We marked a defining milestone in our journey by celebrating **10 years of Botminds** with the inauguration of our new office space at **WorkEZ, Guindy**.
The celebration was graced by distinguished leaders from industry and academia, including **Samuel Santhosh Kumar (Sam), Director – Business Development at Microsoft; Muthuvelan T, CEO of Nihon Technology; Arunprakash, Founder & CEO of HCL GUVI**, and other esteemed guests. Their presence and insights reaffirmed our evolution as an AI-first automation company — from **Document AI to Agentic AI**.
This milestone stands as a symbol of stability, resilience, and our readiness to shape the next decade of enterprise AI innovation.
## Strengthening Leadership and Operations
As we scale into our next phase of growth, we strengthened our leadership bench with seasoned leaders who bring depth, execution rigor, and strategic clarity.
We welcomed **Pankaj** as **Chief Strategy Officer and Chief Operating Officer**, reinforcing our focus on scalable operations and long-term growth. Alongside him, **Beniston** and other senior leaders joined the team, further strengthening our ability to execute at enterprise scale.
These leadership additions mark a deliberate step toward organizational maturity — enabling Botminds to move faster, operate stronger, and deliver sustained impact across customers, partners, and markets.
### Investing in Talent and Future Innovation
Exceptional platforms are powered by exceptional people—and in 2025, we supercharged our talent engine with a dynamic recruitment drives at top institutions like SRM, SSN, Great Lakes, Loyola, PSG Coimbatore, and Thiagarajar College of Engineering.
These weren’t just interviews—they were high-energy conversations about tackling real-world challenges, mastering applied AI, and building systems that dominate at enterprise scale. The result? An influx of brilliant minds ensuring bold ideas, continuity, and explosive long-term growth!
These initiatives went beyond hiring—they fostered discussions on practical AI applications and enterprise-scale problem-solving, ensuring fresh perspectives and long-term strength for our team.
### Advancing Product Capabilities with Discipline
We maintained strong product momentum, launching V25 with enhancements in performance, usability, and enterprise readiness. Work also progressed on V26, emphasizing scalability, orchestration, and advanced agentic features.(Coming soon)
Additionally, the introduction of X-Flow enabled more intelligent workflow orchestration. These releases reflect our commitment to shipping high-impact updates aligned with user needs.
### Evolving from Platform to Ecosystem Marketplace
Botminds AI grew into a true ecosystem enabler with the launch of our marketplace for pre-built templates. This allows enterprises to accelerate deployment using proven, workflow-aligned solutions—reducing time-to-value and focusing on reliable outcomes over experimentation.
### Enhancing Accessibility and User Experience
To better serve our users, we revamped our UX and website for greater clarity and relevance. The updated design makes it easier for decision-makers, practitioners, and partners to discover how Botminds delivers value.
### Growing Our Community and Presence
Our LinkedIn community surpassed 20,000 followers, driven by meaningful engagement with enterprise leaders and partners. We also relaunched community programs and training initiatives to share knowledge and support real-world AI applications.
### Supporting Broader Developer Communities
Beyond our platform, we hosted the NG India Angular Community Meetup in Chennai, fostering collaboration among developers and reinforcing the importance of strong practitioner ecosystems.
### Engaging in Key Industry Conversations
Botminds participated in prominent events, including the NASSCOM GCC Summit & Awards, CEA Summit at IITM Research Park, and UBS Future of Manufacturing Summit & Awards—sharing insights and aligning with enterprise priorities.
### Delivering Jaw-Dropping Enterprise Impact
Real progress = real results—and 2025 delivered big time!
Our Voice of Customer solution unlocked ~12,000 hours of powerful actionable insights, accelerating decisions from signal to success. We also doubled down on pharma breakthroughs, powering complex, regulated global deployments with unshakeable accuracy and governance.
These wins prove we build solutions that dominate at enterprise scale—where precision and impact are everything!
Learn more
### Charging into 2026 with Unstoppable Momentum!
2025 was pure fire: intentional building, rock-solid foundations, laser focus, and massive value creation. Now, as we blast into 2026, our mission is crystal clear—scale what’s winning, amplify what sets us apart, and lead with fearless clarity.
A huge, heartfelt **THANK YOU** to our incredible customers, partners, community, team, and supporters—you made this epic year possible! The future is brighter than ever, and we can’t wait to push boundaries even further together.
Here’s to an even more extraordinary decade ahead!
---
## Reimagining Legal Automation: Inside Botminds' Agentic AI Framework for Smart NDA Review
URL: https://www.botminds.ai/post/reimagining-legal-automation-inside-botminds-agentic-ai-framework-for-smart-nda-review
> Why extraction-only legal AI falls short, and how Botminds orchestrates specialized agents to review NDAs against your standards with human oversight.
How Multi-Agent Orchestration is Transforming Legal Operations
### The Enterprise Legal Challenge
Non-disclosure agreements represent one of the most paradoxical documents in enterprise operations. They're simultaneously routine and critical, high-volume contracts that appear in nearly every business relationship, yet carry substantial legal and financial risk when improperly managed. A single misaligned confidentiality clause or missing indemnification provision can expose an organization to intellectual property disputes, regulatory penalties, or competitive disadvantage.
Despite decades of advances in natural language processing, legal automation has remained stubbornly manual. Legal teams continue spending countless hours reviewing NDAs line-by-line, cross-referencing organizational standards, tracking document versions across email chains, and managing vendor revisions through iterative cycles. The pain points are systemic: manual clause validation introduces human error, compliance gaps emerge from template drift, and version chaos creates operational bottlenecks that delay critical business partnerships
### The Problem with Traditional AI for Legal Documents
Most AI-powered legal tools today operate as sophisticated extraction engines. They excel at identifying clauses, classifying document types, and pulling key data points into structured formats. These systems leverage machine learning and NLP to achieve impressive accuracy in pattern recognition.
Yet they fundamentally lack contextual judgment. A traditional ML model can identify a non-compete clause, but it cannot assess whether that clause aligns with your organization's risk tolerance, industry regulations, or preferred contractual language. It cannot propose corrections, explain why a deviation matters, or adapt its understanding based on legal team feedback.
Technical leaders recognize this limitation immediately: it's AI without autonomy. These systems remain passive observers that accelerate data capture but don't participate in decision-making. They're tools that make lawyers faster at the same manual work, rather than systems that transform how legal work gets done
### Enter Agentic AI, The Next Evolution
Agentic AI represents a paradigm shift from reactive automation to proactive intelligence. Unlike traditional AI systems that wait for human direction, agentic systems perceive their environment, make autonomous decisions guided by business knowledge, and take actions to achieve defined objectives, all while maintaining human oversight and explainability.
Botminds' Agentic AI brings this intelligence directly into document workflows, transforming legal automation from extraction to execution. Rather than simply identifying what's in an NDA, the system actively reviews contracts against organizational standards, proposes compliant modifications, and learns continuously through human feedback loops. This isn't passive document processing, it’s an AI that functions as a collaborative legal analyst, operating with the autonomy of a skilled associate but at machine scale.
### The Technical Flow: Multi-Agent Orchestration for NDA Review
Botminds' architecture deploys five specialized agents that work in orchestrated sequence, each handling distinct cognitive tasks while maintaining system-wide coherence.
### Document Ingestion Agent
The workflow begins with intelligent document parsing. The Ingestion Agent processes NDAs regardless of format, Word documents with tracked changes, scanned PDFs, or native digital files, and transforms them into structured, clause-level representations. Botminds' document understanding pipeline applies deep learning models trained specifically on legal language to maintain semantic integrity while creating machine-readable structures that subsequent agents can reason about.
### Knowledge Alignment Agent
This is where comprehension becomes judgment. The Knowledge Alignment Agent compares each extracted clause against the organization's standard NDA knowledge base, the approved template language, mandatory provisions, prohibited terms, and acceptable variation ranges. Using advanced semantic similarity models, the agent identifies deviations not just through keyword matching but through meaning: recognizing when different wording expresses the same concept, when a clause is substantively missing despite similar language appearing elsewhere, or when new provisions introduce unacceptable risk.
### Modification Agent
Identification without action remains incomplete. The Modification Agent applies corrective intelligence autonomously, adding missing clauses, deleting problematic provisions, or rewriting language to align with organizational standards. Critically, it operates in "track changes" mode, ensuring every modification is transparent, attributable, and reversible. This preserves audit trails and allows human reviewers to understand not just what changed, but why.
### Review Agent
Autonomy requires accountability. The Review Agent presents AI-generated edits to human legal experts within an intuitive interface that contextualizes each change. When reviewers accept or reject modifications, that feedback flows directly into the model's reinforcement loop, continuously refining the system's understanding of organizational preferences, risk tolerance, and contextual exceptions that pure rule-based systems cannot capture.
### Collaboration & Loop Agent
Legal negotiation is inherently iterative. The Collaboration Agent manages the back-and-forth between internal and external legal teams, tracking vendor counterproposals and re-ingesting edited NDAs for compliance realignment. Each cycle strengthens the system's understanding of negotiation patterns, common vendor objections, and acceptable compromise language, building institutional knowledge that would traditionally exist only in the minds of senior legal counsel.

### Why This Architecture Matters
The multi-agent approach delivers capabilities that monolithic AI systems cannot achieve:
- Autonomy with Control: AI acts independently within enterprise-defined boundaries, proposing changes confidently while respecting mandatory human approval for final execution.
- Reusability: The same orchestration framework extends naturally to service-level agreements, master service agreements, employment contracts, or compliance audits without requiring complete system redesign.
- Transparency: Every modification includes traceable reasoning, version control, and audit logs that satisfy both internal governance and external regulatory requirements.
- Integration-Ready: The system plugs into existing document repositories, contract lifecycle management platforms, and email workflows, minimizing disruption while maximizing value capture.
### Business Foresight: Agentic AI as a Legal Operations Framework
This architecture transcends product features, it represents a blueprint for scalable legal intelligence across the enterprise. Legal teams evolve from task execution to oversight and governance, focusing on strategic judgment while delegating routine compliance verification to AI agents. CIOs and CTOs gain a platform approach, extending the same agentic infrastructure to any document-heavy function: procurement contract reviews, HR policy enforcement, regulatory filing preparation, or financial audit documentation.
The competitive advantage emerges not from marginal efficiency gains but from fundamentally redefining legal operations as a knowledge system rather than a labor pool.
### Closing Insight
Legal automation used to mean faster extraction. Now, with Botminds' Agentic AI, it means autonomous comprehension, correction, and collaboration. The shift from reactive automation to proactive intelligence defines the next wave of enterprise AI,and it's already here, transforming how organizations manage the contracts that underpin every business relationship. The question for technical leaders isn't whether agentic systems will reshape legal operations, but how quickly your organization will harness them to build institutional intelligence that compounds over time.
---
## Freedom, Candor, and Code: Inside the Botminds AI Culture
URL: https://www.botminds.ai/post/freedom-candor-and-code-inside-the-botminds-ai-culture
> Inside how Botminds works: a team of strong peers, candid feedback, and one operating rule — act in Botminds' best interest — instead of a rulebook.
Leading the pack in Artificial Intelligence means navigating a landscape where the map is redrawn every few months. In such a field, technology alone offers a fleeting advantage. The difference between leading and following is measured in ideas, speed, and execution. At Botminds AI, we know that our most significant competitive advantage isn't just our technology—it's the environment we've built for the brilliant people behind it.
Our culture isn't a list of perks written on a wall. It’s a living framework designed to empower great people to do their best work. It’s a culture built on trust, a passion for impact, and the freedom to solve complex challenges.

### Our Cultural Compass
We guide ourselves with a few core principles that shape how we work, collaborate, and innovate.
### 1. A Team of Exceptional Peers
We believe the most valuable benefit we can offer is a team of talented and driven colleagues. Great people are energized when surrounded by other great people. That’s why our hiring process is so deliberate. We don't just hire to fill a position; we hire individuals who elevate the entire team. This creates a virtuous cycle where high performance becomes the standard, and everyone is motivated by the collective expertise and passion in the room.
### 2. An Environment of Constructive Candor
The fastest path to the best solution is through open and honest dialogue. We foster an environment where principled feedback is shared freely, respectfully, and with the sole intention of helping each other and our ideas grow. We see candor as a sign of respect—it shows we care enough to engage deeply and challenge assumptions. This practice eliminates ambiguity and politics, allowing us to focus on what truly matters: building incredible solutions for our customers.
### 3. A Framework of Empowered Ownership
Top talent doesn't thrive in a system of rigid rules and bureaucracy. That's why we operate on a foundation of trust and favor **principles over policies**. Our central guiding principle is simple: **“Act in Botminds’ Best Interest.”**
This single idea empowers our team to make smart decisions without waiting for layers of approval.
- **Need to take time off?** We trust you to manage your schedule and take the vacation you need to stay energized.
- **Making a purchase for the team?** We trust you to spend company money thoughtfully, as if it were your own.
This framework replaces a heavy rulebook with something far more powerful: individual judgment and a shared sense of ownership.
### How We Build Our Team
Our hiring process is a reflection of our culture. It’s a two-way conversation designed to find a genuine, long-term fit.
### What We Look For: The High-Performance Mindset
Our interview process is engineered to identify people who will thrive in a culture of freedom and candor. It's less of a test and more of a two-way dialogue to see if we can do amazing work together.
### We Don't Fill Roles; We Raise the Bar
Every new hire must raise the average level of excellence on their team. We look for the "and" factor: deep technical skill **and** a creative mind; high ambition **and** deep humility. The goal isn't just to find someone who can do the job today, but someone who will grow, challenge, and elevate the entire team tomorrow.
### A Partnership in Discovery
We want to get to know the real you. Our interviews focus on collaborative problem-solving with real-world scenarios. This isn't about "gotcha" questions; it’s a practical dialogue that allows us both to understand how we might work together. It’s your chance to interview us, challenge our thinking, and see if our culture of ownership and candor is the right environment for you.
### Rewarding Excellence and Impact
To attract and retain the exceptional individuals who build our future, we are committed to providing highly competitive compensation. We believe in rewarding impact and ensuring that our team members are recognized for the immense value they create.
### Why Join Us?
We reward impact, celebrate curiosity, and create space for people to do their life’s best work. At Botminds, you won’t just be part of a company you’ll be part of a movement to redefine how AI transforms knowledge work.
Ready to be a part of our story? Explore our open positions here.
---
# Botminds Academy — full curriculum
## A1 · Agent anatomy
URL: https://www.botminds.ai/academy/a1
> Botminds Academy — Platform · Agents
# Agent anatomy
> **In one line.** What an agent actually is under the hood — the model, the persona, the harness, the context — so every tab in the agent editor stops being a form and starts being a decision.
> **You'll be able to.** Reason about agent behavior from first principles: why an agent answers well, drifts, refuses, or burns tokens — and which part of its anatomy to adjust.
## The parts
An agent is not a model. A model is a mind for rent; an agent is that mind hired into a job, with a role, materials, equipment and rules. Five parts:
| Part | What it is | Where you shape it |
|---|---|---|
| **Model** | The LLM that does the thinking. Swappable — the same agent definition can run on a different registered model, or on **Auto** routing. | [A2 · LLMs & services](/academy/a2) |
| **Persona** | The plain-language job description: role, task, tone, output contract, refusal rules. This is the highest-leverage text you will write on this platform. | Agent **Persona** tab |
| **Knowledge** | The collections the agent may read. Grounding and access boundary in one — attach nothing, and the agent knows nothing about your business. | Agent **Knowledge** tab, [D1](/academy/d1) |
| **Capabilities** | Tools, skills and MCP servers — what the agent can *do* beyond reading and writing text. | [A5](/academy/a5), [A6](/academy/a6), [A7](/academy/a7) |
| **Guard rails** | The rules layered onto every run. | [A8 · Guard rails](/academy/a8) |
Around those parts sits the **harness** — the platform machinery that turns a one-shot text model into a worker you can trust with a queue: it assembles the context for each run, executes tool calls, records the trace, scores confidence, and hands results to the lifecycle.
## What happens on a run
Every run — playground chat or production document — is the same loop:
1. **Assemble.** The harness builds the context: persona, the relevant slices of attached knowledge, the document or question at hand, and the schema it must fill.
2. **Think.** The model reasons over that context. If it decides it needs a capability — a lookup, a calculation, a search — it calls a tool, gets the result, and continues.
3. **Answer.** The output lands where the run came from: an answer with citations in chat, or schema fields with per-field **confidence** on a document.
4. **Record.** The full trace — inputs, tool calls, output, confidence, cost — is kept, which is why you can inspect any run after the fact.
The playground shows you this loop live; production runs it silently at volume. Same anatomy, same behavior — which is exactly why playground testing predicts production behavior.
## Context is the scarce resource
A model reads a finite window of text per run. The harness spends that budget for you — persona first, then the knowledge slices most relevant to the task, then the work itself. Two practical consequences:
- **Relevance beats volume.** Attaching ten collections "just in case" doesn't make an agent smarter; it makes retrieval noisier. Attach what the job needs.
- **The persona is always in the room.** It is read on every single run, which is why one precise sentence there outperforms a paragraph of vibes.
## Why agents misbehave — a diagnosis table
| Symptom | Usually means | Fix at |
|---|---|---|
| Confident nonsense | Answering beyond its grounding | Persona: require citations, demand refusal when unsupported; check Knowledge attachments |
| Right answer, wrong format | Output contract underspecified | Persona: state the format explicitly; schema field descriptions |
| Ignores its documents | Question outruns retrieval, or wrong collection attached | Knowledge tab; [D6 · Search & indexes](/academy/d6) |
| Slow or expensive | Over-tooled, or a heavier model than the job needs | Capabilities: remove unused tools; Model: try a lighter model — measure in the playground |
| Inconsistent across runs | Task too big for one worker | Split it: [teams & mesh](/academy/a11) or a [pipeline](/academy/a10) |
## One worker, then many
Everything above describes one agent. The platform's larger patterns are this same anatomy repeated: a [team or mesh](/academy/a11) is agents with a coordination layer; an [XFlow](/academy/a10) is agents with an orchestration layer; an [Agentic System](/academy/sol-sys) is a fleet of them over one domain model. Master the single worker first — the rest is arrangement.
## Where to go next
- Build one: [A3 · Your first agent](/academy/a3).
- The varieties of worker: [A4 · Agent varieties](/academy/a4).
- What the thinking runs on: [A2 · LLMs & services](/academy/a2).
---
## A10 · XFlows & pipelines
URL: https://www.botminds.ai/academy/a10
> Botminds Academy — Platform · Agents
# XFlows & pipelines
> **In one line.** What an XFlow is, when to build one instead of a single agent, and how to author, run, and debug one in the visual canvas.
> **You'll be able to.** Build a small extract → validate → write pipeline from the node palette, execute it, and read its run logs.
> **Where this lives.** `Studio ▸ Agent Builder ▸ Agents` (XFlows appear in the unified Agents list; the **+ Agent** picker offers **XFlow**). The same editor also has a home at `Studio ▸ Automation ▸ XFlow` (`automation/xflow`).
## Why it matters
An **XFlow is a processing pipeline** — a directed graph (a DAG) of operators that does work on your documents or data: fetch something, run an agent, query SQL, call an API, write a result. You build one when the work is **deterministic, multi-step, and reusable** — a fixed sequence you want to run the same way every time, over one document or a hundred thousand.
> **Watch out — the single most common newcomer mix-up.** An **XFlow is a pipeline of operators** (a *verb* that processes documents). A **Lifecycle / Stateflow** is the set of review **stages** a document moves through ([D3 · Taxonomy, lifecycle, tags & events](/academy/d3)). They are different objects in different tables. The codebase overloads the word "workflow" for both — the Academy never does. **XFlow = pipeline. Lifecycle = stages. Burn it in.**
### XFlow vs a single agent — which to reach for
| Build a… | When the work is… |
|---|---|
| **Single agent** ([A3](/academy/a3)) | One open-ended, judgement-heavy task — "read this and extract the fields", "answer this question". The agent decides how. |
| **XFlow (pipeline)** | A **fixed, ordered sequence of steps** — extract, then validate, then write to a table, then email on failure. You want it deterministic and repeatable, and you may want to reuse it across collections. |
An XFlow can call an agent as one of its steps (the **Agent Operator**), so you get the best of both: a deterministic spine with an AI step where judgement is needed.
> **Under the hood.** An XFlow is stored as `bm.workflows` + `bm.workflow_tasks` and runs in the Agent-Orchestrator as a Prefect flow. You never touch Prefect — you see nodes, edges, and runs. Every collection already has a system-seeded **ingestion XFlow** (and Knowledge collections add a vector-ingestion step); you build your own XFlows for downstream work.
## Reaching the editor
XFlows are part of the unified Agents list, so you create and open them the same way you do agents:
1. Go to `Studio ▸ Agent Builder ▸ Agents`.
2. To **create**: click **+ Agent** → in the picker choose **XFlow** → the **Add XFlow** dialog opens (name + description; see below). Save, and the **workflow-activity canvas** opens.
3. To **open** an existing one: click its row in the list. XFlows and agents share the list; the XFlow rows open the canvas editor instead of the agent editor.
> **Tip.** The same editor also lives standalone at `Studio ▸ Automation ▸ XFlow`, with its own left-rail list of XFlows. It's the identical canvas — use whichever entry point you prefer.
## The XFlow editor shell
```
┌ XFlows (L2) ──┐┌ Acme Extract Flow [ XFlow | Runs ] ┐
│ search… ││ Enable Auto-Refresh Save Discard Execute ▾ ⋮ │
│ ▸ Extract ││ ┌──────────────────────────────────────┐ ┌─ palette ────────────┐ │
│ ▸ Classify ││ │ ...... dotted canvas .......... │ │ Stages: (empty) │ │
│ ▸ Ingest (pin) ││ │ ┌──────────┐ ┌───────────┐ │ │ Python Library │ │
│ … ││ │ │ Agent │────▶│Conditional│ │ │ Agent Operator │ │
│ ││ │ │ Operator │ │ Operator │ │ │ Conditional Op. │ │
│ ││ │ └──────────┘ └────┬──────┘ │ │ SQL Operator │ │
│ ││ │ ┌────▼─────┐ │ │ Move To State │ │
│ [ + XFlow ] ││ │ │ Move To │ │ │ Vector Ingestion │ │
│ ││ │ │ State │ │ │ … (operators only) │ │
│ ││ │ └──────────┘ │ └──────────────────────┘ │
│ ││ │ orient / zoom in / zoom out │ │
└────────────────┘└─────────────────────────────────────────────────────────────────────┘
```
- **L2 left rail** — a searchable list of XFlows (name + description + pin icon). Footer **+ XFlow** to create; a per-row **⋮** menu offers Edit / Delete / Duplicate. *(Hidden when the editor is embedded in the Agents list — there the unified list is your L2.)*
- **L3 tabs** — **XFlow** (the canvas) and **Runs** (execution history).
- **Toolbar** — the controls that act on the whole XFlow:
| Control | What it does | Notes |
|---|---|---|
| **Enable** toggle | Turns the XFlow's **scheduled** run on/off. | Disabled while you have unsaved changes. |
| **Auto-Refresh** toggle | Live-refreshes the Runs tab (with a pulsing spinner). | Only on the **Runs** tab. |
| **Save** | Persists the graph + dialog settings. | Disabled unless something changed (dirty). |
| **Discard changes** | Reverts to the last saved version. | |
| **Execute** ▾ | Hover-menu: **Quick Run** / **Document Run** / **Custom Run**. | See "Running it". |
| **⋮ action-menu** | Publish · Edit · Duplicate · Pin / Unpin · Delete. | All permission-gated. |
> **Watch out.** XFlows whose name **starts and ends with `__`** are system-reserved (the seeded ingestion spine, for example). Non-super-admins don't get edit affordances on them. Don't name your own XFlows that way.
## The canvas
The XFlow tab is a directed-graph canvas. You build the pipeline by dragging nodes from the palette, configuring each, and connecting them with edges. An empty canvas prompts: *"No task found in flow. Drag and drop any task to get started."*
### The node palette — what you can actually drag today
The palette (top-right, draggable; expand/collapse with the expand icon) still groups nodes into three kinds — **Stage**, **Activity**, and **Functional / operator** — but the editor filters what it renders, so what you can drag onto the canvas today is narrower than the full catalogue:
- **Stage group** — currently **empty**. None of the coarse phase nodes (Manual Review, Sources, RPA Bots, Agent Flow, AI Pipeline) are surfaced as draggable tiles.
- **Activity group** — a **single** tile: **Python Library** (run a Studio-authored Python/Library snippet, [A13 · Library & bots](/academy/a13)). The other activity nodes (Export, Data Feeds, Conditional, Rescore Models, Regroup Summary, User Allocation) are not in the palette.
- **Functional / operator group** — rendered **in full**. These are the real workhorses you build pipelines from:
| Operator | Does | Operator | Does |
|---|---|---|---|
| **Agent Operator** | run an Agent as a step | **Conditional Operator** | branch on a condition |
| **SQL Operator** | run a SQL query | **Xflow Operator** | call another XFlow |
| **API Fetch** | make an HTTP/API call | **Iterator Operator** | loop over items |
| **Send Email** | send mail (To/Subject/Body) | **Bot Operator** | invoke an RPA Bot |
| **Move To State** | advance a doc's lifecycle stage | **Vector Ingestion** | chunk → embed → index for Knowledge |
| **Bash Operator** | run a shell command | **Agent Finetuning** | start a fine-tune step |
> **Reality check — the palette is filtered.** The data model defines a much larger node set (the full Stage and Activity nodes — Manual Review, Sources, Export, Conditional, and the rest). But the live editor restricts the rendered palette to the **operators above plus the single "Python Library" activity** (the Stage group renders empty). The [node reference](/academy/r4) catalogues the whole model and marks which nodes are surfaced vs present-but-filtered. Build pipelines from the operators above — they are what you can actually drop on the canvas.
> The **Move To State** operator is the *only* place a pipeline touches a Lifecycle — it pushes a document to a stage. The XFlow itself is still a pipeline, not a Lifecycle.
### The node card
Each node on the canvas shows an icon tile (coloured) + an inline-editable label and description. Watch for the **warning badge** — it means required parameters are missing; the run will be unhappy until you fill them. An optional footer shows a **doc count** (deep-links to those documents); expanding the card reveals the roles that can view it and its **Operator Type**. Hovering reveals action icons (permission-gated): start-connection, cancel-connection, **edit** (or double-click), and **delete**.
### Edges and canvas controls
- **Connect two nodes:** hover the source node, click its **start-connection** arrow, then click the target node. An arrow appears.
- **Edit an edge:** click the edge line → the **Edit Edge** dialog (Name, Description); edit or delete it there. Click the line again to disconnect.
- **Canvas controls** (bottom-right): **Switch Orientation**, **Zoom In**, **Zoom Out**. The legend bar adds **Zoom-to-window** and **Maximize/Normal** (which toggles palette visibility). The canvas auto-zooms to fit on your first click.
## Building a pipeline
1. **Open or create** the XFlow (above). In the **Add XFlow** dialog set a **Name** (required; duplicate names and reserved `__` names are rejected) and a **Description**. Under **Show Advanced Settings** you can also set **Concurrency Limit**, **Execution Profile** (size class), **Repeat Every** (the schedule), **Retries / Retry Delay**, the **Trigger** event types, and an **On Failure Notification** email. Save.
2. **Add nodes** — drag tiles from the palette onto the canvas. Each drop opens the **node config dialog** (`create-task-meta-info`).
3. **Configure a node** — the config dialog's fields are operator-specific (a SQL Operator asks for a query; an Agent Operator asks which agent; an API Fetch asks for a URL). Fill the required params so the warning badge clears. Re-open any node later via double-click or its edit icon.
4. **Connect edges** — wire the nodes in run order (start-connection arrow → target). The graph's direction *is* the execution order.
5. **Save** — the toolbar **Save** lights up while you have changes; click it to persist.
## Running it
### Execute
Click **Execute** ▾ and pick a mode:
| Mode | What you supply | Use it for |
|---|---|---|
| **Quick Run** | nothing | Fire the whole pipeline immediately. |
| **Document Run** | a `document_url` (or pick a file via the **drive** picker) | Run against one specific document. |
| **Custom Run** | free-text **Run Input** (JSON/params) | A one-off run with custom input. |
The run is queued and the **XFlow Progress overlay** appears, streaming live status (run id, engine URL) until it finishes.
### The Runs tab
Switch to **Runs** to see execution history. A filter bar lets you narrow by **Tags**, **Stage**, and **Date Range** (quick radios: Today / Yesterday / Week / Month / Custom). The run table shows:
- **Flow Name** (with copy-run-id / copy-document-id),
- a **Status** pill — completed / failed / running / paused / cancelled, each with an inline action (Retry / Resume / Cancel / Suspend / rerun) for its state,
- **Start Time** (sortable) and **Total Duration**.
Select rows to get a bulk toolbar (Retry / Pause / Resume / Cancel / Delete). Click a row to open a right sidenav (60%): header chips (`parent_run_id`, `flow_run_id`, `deployment_id`), a state badge, duration, and two tabs — **Task Logs** (expandable per-task rows with timestamped, level-coded lines) and **Logs** (the raw scrollable stream).
### Debugging a failed run
1. In **Runs**, find the run with a red **Status** pill.
2. Click it → open **Task Logs** in the sidenav and expand the task that stopped the chain (the failing operator).
3. Read the level-coded error lines; cross-check that operator's config in its node dialog.
4. Fix the node (or the upstream data), **Save**, then hit the inline **Retry** on the run.
> **Tip.** A run stuck at **queued** that never starts usually means the Prefect worker isn't running (locally, the worker container is down). It's an environment issue, not your pipeline.
> **Mesh mode.** When the editor runs in **Mesh mode**, the palette is restricted to exactly **XFlow Operator + Queue + Service**, and the Runs tab switches to a mesh **Run trace** (member timeline, queue-health banner, pub/sub **Baton trail**). That's the subject of [A11 · Teams & mesh](/academy/a11).
## How an XFlow gets triggered
You rarely run an XFlow only by hand. The production triggers:
- **As a collection's processing pipeline** — a collection's ingestion / secondary XFlows run per document as it arrives (set on the Job's **Secondary XFlows**, see [D4 · Ingestion & connectors](/academy/d4)).
- **On a schedule** — set **Repeat Every** in Advanced Settings and flip the **Enable** toggle; the XFlow then runs itself on that interval.
- **On an event** — the **Trigger** field (Add XFlow dialog) fires the pipeline on events like **Entity Ingestion** or a **Stage** change.
- **From a mesh** — a mesh wires the XFlow to other runnables as a durable pipeline segment ([A11](/academy/a11)).
## Try it yourself
Build a tiny three-node **extract → validate → write** pipeline:
1. `Studio ▸ Agent Builder ▸ Agents` → **+ Agent** → **XFlow**. Name it `Try Extract Validate`, add a description, **Save** — the canvas opens.
2. Drag an **Agent Operator** onto the canvas; configure it to call your extraction agent from [A3](/academy/a3). This is **extract**.
3. Drag a **Conditional Operator** (or a **Python Library** step) and configure a simple check — e.g. "is the total present?". This is **validate**. Connect **extract → validate** with an edge. *(Both of these are in the live palette — see the palette section above.)*
4. Drag a **Move To State** operator as **write** — advance the document to the next lifecycle stage. Connect **validate → write**. *(There is no "Export" tile in the current palette; use an operator that is actually draggable, such as Move To State or SQL Operator.)*
5. Confirm no node shows a warning badge, then **Save**.
6. Click **Execute ▾ → Document Run**, pick a sample document, and watch the **Progress overlay**.
7. Open the **Runs** tab, click your run, and read **Task Logs** for each of the three steps. If a step is red, fix its config and **Retry**.
You've now built, run, and inspected a real pipeline.
## Where to go next
- [A9 · AI Builder](/academy/a9) — trainable AI models, prediction reports, and the model-chaining AI Pipeline that the **AI Pipeline** stage node runs.
- [A11 · Teams & mesh](/academy/a11) — wire XFlows and agents into durable, restart-surviving meshes; the Queue / Service / pub-sub nodes and the mesh run trace.
- [XFlow node & operator reference](/academy/r4) — every node in the palette, the node card, edges, the Execute dialog, and the full Runs/Mesh-trace surfaces.
- [D3 · Taxonomy, lifecycle, tags & events](/academy/d3) — the Lifecycle/Stateflow an XFlow is *not*.
---
## A11 · Teams & mesh
URL: https://www.botminds.ai/academy/a11
> Botminds Academy — Platform · Agents
# Teams & mesh
> **In one line.** Two ways to compose many runnables when one agent isn't enough — an in-process
> **Multi-Agent Team** (a leader delegating to member agents) and a durable, restart-proof
> **Mesh** (a pipeline wiring runnables together by queues).
> **You'll be able to.** Build a 2-member team from the Subagents tab, recognise the Mesh
> designer, and decide between Team, Mesh, and XFlow for a given job.
> **Where this lives.** `Studio ▸ Agent Builder ▸ Agents` — the same gallery and **+ Agent**
> picker you already know.
## When one agent isn't enough
One agent is the right answer surprisingly often. Reach for composition only when a single agent
genuinely can't do the job well:
- **Specialists.** The work splits into distinct skills — an extractor, a fraud-checker, a
summariser — and you want each tuned and tested on its own, not crammed into one mega-prompt.
- **Parallelism.** Two independent checks (credit *and* compliance) can run at the same time
instead of one-after-the-other.
- **Long, durable, multi-stage automations.** The whole process takes minutes, has branches and
joins, and must **survive a restart** without losing its place.
The platform gives you two tools for this, and they are not the same thing. Learn the difference
once and you'll always pick the right one:
| | **Multi-Agent Team** | **Mesh** |
|---|---|---|
| **What it is** | One *leader* agent delegating to *member* agents | A *pipeline* wiring runnables by queues |
| **Runs where** | **In-process**, inside one agent run | **Durably**, across the orchestrator's bus |
| **Members are** | Other **agents** only | Any **runnable**: agent, XFlow, mesh, or Service |
| **Survives a restart?** | No (it's one live conversation) | **Yes** (batons are written to a durable bus) |
| **Reach for it when** | Several specialists must collaborate *right now* | A long, branching, multi-stage automation |
> **Under the hood.** A Team is a `TeamEx`/`SequentialFlow` built inside a single agent run in
> the orchestrator. A Mesh is a separate durable runtime (members hand **batons** over a
> Postgres-backed bus). That's why only the Mesh survives restarts — and why a Mesh member, but
> not a team member, can be an XFlow or a parked Service.
## Multi-Agent Teams — the Subagents tab
A Multi-Agent Team is just **an ordinary agent that has subagents**. You don't create a separate
"team" object — you add subagents to an agent on its **Subagents** tab, and that agent becomes
the **leader**. In the gallery it still carries the **A** kind badge (tooltip "Multi-Agent"),
and the **Kind** filter has a **Multi-Agent** option to find them.
The leader is the agent you're editing — its Persona and Instructions decide *how* it delegates
and synthesises. Each subagent row adds one **member agent**, picked from agents in the project.
The tab's empty state reads "Add a subagent to make this agent a coordinator."
| Control | What it does | Notes |
|---|---|---|
| **Coordination mode** | How the leader uses its members | The four modes below. Appears once you have at least one subagent. |
| **+ Add subagent** | Adds a member row | Adding the first one turns this agent into a coordinator/team leader. |
| **Agent** (per row) | Which existing agent is this member | The dropdown lists team-eligible agents in the project. |
| **Prefix instructions** | Extra instructions prepended for *this* member | Use it to tell one member how to behave inside the team. |
| **Reasoning** toggle | Lets this member use extended reasoning | Costs latency; turn on only where it earns its keep. |
| **Remove** (x) | Drops the member | Removing the last member makes the agent a plain single agent again. |
> Member approvals live on the **Governance ▸ Approvals** tab under **Team agents** — you can
> require human approval before the leader hands work to a specific member.
### The four team modes
**Coordination mode** is the single most important choice — it decides *how* the leader uses its
members:
| Mode | What the leader does | One-line example |
|---|---|---|
| **coordinate** | Delegates sub-tasks to members, then **synthesises** their answers into one | "Read this claim" → asks Extractor for fields *and* Policy-checker for coverage, then writes the recommendation. |
| **route** | Picks **one** member best suited to the request and hands off | A triage leader routes a billing question to the Billing agent, a returns question to the Returns agent. |
| **collaborate** | Runs **all** members **in parallel** on the same input, then combines | Three reviewers each red-flag a contract at once; the leader merges the flags. |
| **sequential** | Pipes output **member → member** in order | Extract → normalise → summarise, each step consuming the previous one's output. |
> **Watch out.** A team runs as **one in-process agent run** — it does *not* survive a restart,
> and every member is an **agent** (you can't drop an XFlow or a Service into a team). If you
> need either of those, you need a **Mesh**, not a team.
### Build one — a 2-member sequential team
1. Open `Studio ▸ Agent Builder ▸ Agents`. Select (or create) the agent you want as **leader** —
say *Claims Lead* — and click **Edit**.
2. Go to the **Subagents** tab. Set **Coordination mode** to **sequential**.
3. Click **+ Add subagent**. In **Agent**, pick your first specialist (e.g. *Field Extractor*).
In **Prefix**, add a line like "Extract every field; output JSON only."
4. Click **+ Add subagent** again. Pick the second specialist (e.g. *Risk Scorer*) and prefix it
"Read the extracted fields above and score risk 0–100."
5. Click **Save Agent**. Order matters in sequential mode — *Field Extractor* runs first, its
output feeds *Risk Scorer*.
6. Use the **Playground** pane (right side): send a sample document and watch the leader run the
two members in order.
## Mesh — the durable pipeline designer
A **Mesh** is a *durable pipeline* that wires **runnables** together by **queues**. Each node is
a **member** that references any runnable — an **agent**, an **XFlow**, another **mesh**, or a
**Service** — and members hand a small **baton** (the previous step's output) to the next over a
durable bus. Because the bus is durable, a mesh **survives a restart**: a baton mid-flight is not
lost. That is the whole reason Mesh exists and Teams don't cover it.
> **Advanced surface — always available.** The Mesh designer is the **XFlow designer in *mesh
> mode***, not a separate screen. It's an advanced surface, but it is not flag-gated:
> **+ Agent ▸ Mesh** is always offered whenever you can add an agent. In mesh mode the palette
> is reduced to exactly **XFlow Operator + Queue + Service** (Subscribe/Publish are XFlow-mode
> pub-sub operators, not mesh tiles), and Save/Run target `/api/mesh`. Treat this section as
> "recognise it and understand the model"; most builders ship Teams and XFlows long before they
> author a Mesh by hand. Intake can also *run* a mesh even when you didn't draw one.
From the **Agents** gallery footer, **+ Agent** opens a three-option picker:
| Option | Opens |
|---|---|
| **Agent** | The single/team agent builder. |
| **XFlow** | The XFlow create dialog → the visual pipeline designer ([XFlows & pipelines](/academy/a10)). |
| **Mesh** | The same create dialog in **mesh mode** — sets `meshMode`, palette = **XFlow + Queue + Service**, Save/Run → `/api/mesh`. |
A saved Mesh appears in the gallery with the **M** kind badge; selecting it swaps the right pane
to the embedded designer in mesh mode. The designer has **Mesh** and **Runs** tabs, **Save Mesh**
and **Run** actions, and a mesh-run status chip; members are the nodes, queues are the boxes
between them, and the baton is the output that hops.
| Control | What it does | Notes |
|---|---|---|
| **XFlow Operator** node | A **member** referencing a runnable | The member's "work" — an XFlow, agent, or mesh. |
| **Queue** node | The pipe between members | Node→queue = **publish**; queue→node = **subscribe**. Carries the **baton**. |
| **Service** node | A **parked** member | The member sits `awaiting` while an external worker does long work — see below. |
| **Save Mesh** | Persists the mesh | Targets `/api/mesh`. **MeshId is global**, not per-project — pick unique ids. |
| **Run** | Starts a mesh run | Delegates to `runMesh()`; results land in the **Runs** tab. |
### Behaviours to know — the 240 s limit, fan-out, fan-in
- **A member has a 240-second ceiling.** If a single step needs longer (a GPU model, OCR on a
200-page scan, an overnight batch, a slow partner API), it cannot be a normal member. Instead,
make it a **Service** ([LLMs & services](/academy/a2)): the member **parks** in an `awaiting`
state holding *no* worker, your external program pulls and does the work, then reports back
and the member resumes. Parking can wait minutes or hours without tying up platform resources.
- **Fan-out (1→N).** Two members subscribed to the *same* queue both receive the baton and run
in parallel — e.g. score-credit *and* check-fraud at once.
- **Fan-in (N→1).** One member with *two* incoming queues **waits for both** before it runs (a
join) — e.g. *decide* runs only after both credit and fraud have reported.
- **A run is done** when nothing is running, nothing is pending on the bus, and nothing is parked.
```
┌──────────┐
document ─────▶│ intake │ (member: XFlow)
└────┬─────┘
publishes baton
┌───────┴────────┐ fan-out: both subscribe to the same queue
┌─────▼─────┐ ┌──────▼──────┐
│ score │ │ check │ <- run in parallel
│ (XFlow) │ │ fraud │
└─────┬─────┘ │ (Service) │ <- parks <=24h, external worker does it
│ └──────┬──────┘
└──────┬──────────┘ fan-in: decide waits for BOTH
┌───▼────┐
│ decide │ (member: agent) -> writes the doc Summary
└────────┘
```
*Stretch (read-only):* open **+ Agent ▸ Mesh**, drop two **XFlow** nodes and a **Queue** between
them, and read the **Mesh** vs **Runs** tabs — don't save unless you mean to (MeshId is global).
The goal is to recognise the surface, not ship a mesh.
## How a team or mesh is run and observed
- **A Team** runs whenever its **leader agent** runs — from the **Playground**, as a collection's
intake agent, or wherever a single agent would run. There's no separate "team run"; you observe
it on the leader's **Runs** tab and watch the member hand-offs live in the Playground transcript.
- **A Mesh** runs from **Run** in the designer, or as a **collection's intake runnable** (intake
routes by kind: mesh → agent → xflow). Observe it on the designer's **Runs** tab in **mesh
mode**: you get a Mesh run list (status / run-id / doc / hops) and a readable **Run trace** — a
**member timeline** with per-member states (`done` / `failed` / `running` /
**`awaiting service`**), per-member **Show output** / **View full logs**, a **queue-health**
banner (queued vs stalled), and a **Baton trail** of pub/sub hops (delivered / queued / failed,
with expandable payloads and attempt counts).
For observing agent, xflow, and mesh crews as they run, see [Crew & evaluations](/academy/a12).
> **Tip.** The **`awaiting service`** dot in a Run trace is your friend: it tells you a member is
> parked on a Service and *waiting on your external worker*, not stuck. The Baton trail shows
> exactly which hop is in flight.
## Team vs Mesh vs XFlow — which do I reach for?
| Need | Use | Why |
|---|---|---|
| One job, several agent specialists collaborating *now* | **Multi-Agent Team** | In-process delegation; fastest to build (just the Subagents tab). |
| Deterministic, multi-step processing of each document (python, SQL, API, agent call) | **XFlow** ([A10](/academy/a10)) | A single pipeline of operators; no durable cross-runnable wiring needed. |
| Long, branching, multi-stage automation that must survive restarts | **Mesh** | Durable bus; members fan-out/fan-in; members can be XFlows/agents/meshes. |
| Any step over **240 s** (GPU/OCR/overnight/slow partner API) | **Mesh + Service** ([A2](/academy/a2)) | The member parks while an external worker pulls and does the work. |
| Pick one of several agents per request | **Team (route mode)** | Leader routes to the single best member. |
| Two independent checks at the same time, then a join | **Mesh (fan-out → fan-in)** | True parallel members with a durable join. |
> **Watch out.** Don't reach for a Mesh just because you have "several agents." If they
> collaborate inside one conversation and don't need durability, a **Team** is simpler. Mesh
> earns its complexity only when you need **durability, cross-runnable members, or true parallel
> fan-out/fan-in**.
## Where to go next
- [Library & bots](/academy/a13) — the reusable Python assets and RPA workers that mesh nodes
and tools draw on.
- [Your first agent](/academy/a3) — a single agent's anatomy, including the Subagents tab.
- [XFlows & pipelines](/academy/a10) — the pipeline primitive and the Runs tab in depth.
- [LLMs & services](/academy/a2) — long-running external work via parked Services.
---
## A12 · Crew & evaluations
URL: https://www.botminds.ai/academy/a12
> Botminds Academy — Platform · Agents
# Crew & evaluations
> **In one line.** Watch your agents work in real time on the collection's Crew tab, and prove they still work — against curated ground truth, on a schedule — with Evaluations.
> **You'll be able to.** Read the live crew view during a run, build a golden dataset, run an evaluation against any crew (agent, XFlow or mesh), and use baselines to catch regressions before your users do.
## Crew — the live view
A **crew** is the platform's umbrella word for whatever workforce is attached to a collection: a single agent, an XFlow, or a mesh. The **Crew** tab on the collection workspace merges "what is this collection?" and "who works it, right now?" into one screen:
1. **Identity strip** — the collection's title, a live `Ready / Crew working` status pill, and one row of vitals: documents, fields, stages, intake. A **Manage in Studio** link jumps to configuration.
2. **Pipeline rail** — the collection's stages as numbered nodes, tinting while work is in flight.
3. **The live crew** — KPI tiles, the crew stage with each member lighting up as it works, recent decisions, and recent runs.
> The Crew tab ships behind the `crewTab` release flag, default on; when off, the previous Overview and Agents tabs render unchanged.
This is the screen to keep open during a demo or a go-live: documents land, lanes light left to right, decisions accumulate — and when something stalls, you can see *which member* stalled instead of inferring it from a silent queue.
The Crew tab also hosts the **per-document step-log timeline**: click a document row and every ingestion step appears in order — including **each retry attempt as its own row**, attempt-numbered and carrying the full per-attempt error, so an admin can read "failed 1/3 → retrying → failed after 3" and tell a transient blip from a broken model config. A Knowledge collection's [Index Health](/academy/d6) **View logs** link jumps straight here.
## Evaluations — the proof
The live view tells you the crew is working. Evaluations tell you it is working *correctly* — and still working correctly after every prompt tweak, model upgrade, or upstream change.
`Studio ▸ Agent Builder ▸ Evaluations`
The system-under-test is any crew: a single agent, an XFlow, or a mesh. The loop:
1. **Golden dataset.** Curate documents whose correct outputs you know — drawn from human-verified annotations and reviewed corrections, not generated by a model. This is the asset that makes every later step honest.
2. **Evaluation run.** The crew re-processes the golden documents as if they were new; outputs are scored against the ground truth with hybrid metrics — deterministic checks (field accuracy, classification metrics, set precision/recall) plus LLM-judge scoring for narrative outputs (faithfulness, coverage), with the judge running on a different model family than the crew it judges.
3. **Baseline & regression.** A run can be pinned as the baseline; later runs compare against it, so "did last week's prompt change hurt extraction?" has a measured answer instead of an argument.
4. **Schedule it.** Evaluations run on a schedule, which turns them from a release ritual into a canary: quality drops show up in the report, not in a customer escalation.
## What each word means here
| Word | Meaning | Caught by |
|---|---|---|
| **Accuracy** | Output matches curated ground truth | Field and document scoring, classification metrics |
| **Inconsistency** | Same input produces different outputs run to run | Stability scoring over repeated runs |
| **Drift** | Quality or data distributions move over time on live traffic | Scheduled runs and monitoring over live telemetry |
## The habit that makes this pay
Treat the golden dataset like code: it grows with every incident. When a reviewer catches a wrong extraction, that document — with its corrected values — belongs in the dataset, so the mistake can never come back silently. Twenty well-chosen documents that cover your ugly cases beat two hundred easy ones.
Run an evaluation before every meaningful change ships: persona edits, model swaps, schema changes, new pipeline steps. The comparison against baseline is your regression gate.
## Where to go next
- The workforce being watched: [A11 · Teams & mesh](/academy/a11).
- Where reviewer corrections come from: [G2 · Human-in-the-loop](/academy/g2).
- The runs and logs underneath: [G4 · Observability](/academy/g4).
---
## A13 · Library & bots
URL: https://www.botminds.ai/academy/a13
> Botminds Academy — Platform · Agents
# Library & bots
> **In one line.** Two advanced Asset Builder surfaces: the **Library** (reusable sandboxed
> Python snippets you drop into pipeline nodes) and **Bots** (RPA workers that feed structured
> data in).
> **You'll be able to.** Write a tiny derivation function once and call it from any XFlow node,
> and recognise what an RPA Bot is and where its data lands.
> **Where this lives.** `Studio ▸ Asset Builder ▸ Library` and `Studio ▸ Asset Builder ▸ Bots`
> (`/studio/asset_builder/library`, `/studio/asset_builder/bots`).
## Why this corner exists
Most of this Academy is no-code. This page is the small, optional corner where a *little* code
buys a lot of reuse. When two XFlow nodes need the same bit of logic — normalise a date, reshape
a JSON payload, compute a derived field — you don't paste it twice. You author it **once** as a
**Library** item and reference it from every node that needs it. **Bots** are the other half of
this surface: pre-built RPA workers (think: a robot that opens an Excel file and types its rows
into the platform) that get structured data *in* without a connector. Both are advanced and
optional — skip this page until a pipeline actually needs them.
## The Library
### What a derivation library is (and isn't)
A **Library** item (full name: *derivation library*) is a **Studio-authored, sandboxed Python
callable** — a single function with the shape `def main(**kwargs)` — that you reuse inside XFlow
and mesh **nodes**. It is **not** a public PyPI package, not something you `pip install`, and not
a standalone service. It is a named snippet the platform runs in a sandbox when a pipeline node
calls it, passing the node's inputs in as `kwargs` and using the function's return value as the
node's output.
> **Under the hood.** Library items are stored in legacy Azure-Table storage and resolved by the
> orchestrator at run time. The contract is exactly one entry-point: `main(**kwargs)`. Keep the
> function pure and fast — it runs inside the pipeline's execution budget, not as a long-running
> worker. Long-running external work is a **Service** ([LLMs & services](/academy/a2)), not a
> Library.
### The page
```
┌ Library ──────────────────────┐┌ normalise_date v2 ┐
│ search Custom (Type) ││ │
│ ───────────────────────────── ││ Publish Edit Delete [ Convert To Tool ] │
│ ▸ normalise_date v2 ││ ──────────────────────────────────────────────────────── │
│ reshape a date to ISO ││ Access Level Private │
│ ▸ vendor_lookup v1 ││ Library Type Python (def main(**kwargs)) │
│ ▸ score_risk v3 ││ Version v2 │
│ … ││ │
│ ── No more libraries ── ││ │
│ [ + Library ] ││ │
└───────────────────────────────┘└──────────────────────────────────────────────────────────┘
```
The left rail is the searchable, lazily-loaded list of library items (server-side lazy-load
under the search). Each row shows the **name**, a **version chip** (V1/V2…), and a description;
items with history show an **"N Past Versions"** expander. The list ends with a *"No more
libraries"* marker; the empty state reads *"No Libraries found. Create new Library."* The details
panel shows the selected item's header actions plus the detail rows **Access Level**
(Public/Private), **Library Type** (icon + label), and **Version**. A **Delete** header action
removes the item.
| Control | What it does | Notes |
|---|---|---|
| **+ Library** (footer) | Opens the create-library editor | Permission-gated (`createLibrary`). |
| **Custom ▸ Type** filter | Narrows the list to chosen Library Types | Multi-select chips; **Clear** / **Apply**. |
| **N Past Versions** | Expands prior versions of an item | Each version is selectable and inspectable. |
| **Publish** | Publishes the item to a Hub | Ships the snippet for reuse elsewhere ([Hubs & distribution](/academy/v4)). |
| **Edit** | Opens the item for editing | Every edit creates a **new version**. |
| **Convert To Tool** | Wraps the library item as an agent **Tool** | Bridges Library → the agent world ([Tools & functions](/academy/a5)). |
### The Library Type options
You'll author **Python** most of the time — a sandboxed `def main(**kwargs)` callable, the focus
of this page — or **Function**, the Function flavour of a reusable callable. The type menu also
covers the other reusable-asset shapes the platform stores in the same place: **Prompt**,
**Javascript**, **Template**, **API Endpoint**, and **UI Card**, each holding the reusable asset
its name describes.
> **Tip.** When in doubt, you want **Python** (or **Function**). The other types exist so the
> Library can be the single catalogue for *all* reusable assets — and so any of them can be
> **Converted To Tool** for an agent to call.
### Create a Python library item
1. Go to `Studio ▸ Asset Builder ▸ Library`.
2. Click **+ Library** (footer, or the empty-state CTA).
3. Give it a **name** (e.g. `normalise_date`) and a short description.
4. Set **Library Type** to **Python**.
5. In the body, write a function with the required entry point:
```python
def main(**kwargs):
raw = kwargs.get("value", "")
# reshape, look up, compute
return {"normalised": raw.strip().upper()}
```
The node's inputs arrive as `kwargs`; whatever you `return` becomes the node's output.
6. Save. The item appears in the list with a **V1** chip.
### Calling it from an XFlow node
Libraries don't run on their own — a **pipeline node** invokes them. In the XFlow editor
([XFlows & pipelines](/academy/a10)), the **Python Library** node (palette) is the node that
calls a library item: drop it onto the canvas, open its config, and pick your library item. At
run time the platform passes the node's inputs in as `kwargs` and uses the return value
downstream. One snippet, every pipeline that needs it.
> **Watch out.** Editing a library item creates a **new version**. Nodes reference an item by
> identity — confirm which version a critical pipeline picks up before you change shared logic,
> or you may quietly alter every flow that calls it.
### Behaviours to know
- **Versioned.** Every edit bumps the version; old versions stay inspectable via *Past Versions*.
- **Access Level.** Items are **Private** by default; **Publish** is how a snippet leaves the
project.
- **Permission-gated.** **+ Library**, Edit, Delete, Publish and Convert To Tool each obey your
role.
- **Sandboxed and budgeted.** A Python item runs inside the pipeline's execution budget — keep it
small and side-effect-free; reach for a **Service** ([A2](/academy/a2)) for slow work.
## Bots (RPA)
A **Bot** is a **robotic-process-automation worker** whose job is to **feed structured data into
the platform** — most classically, an *Excel → datasheet* path: a robot opens a spreadsheet and
pushes its rows in as structured records, without you wiring up a connector for it. Bots are
managed on the **Bots** page so a solution builder can see which RPA processes exist and what
data they're producing.
The page is a two-pane view: a left rail listing the RPA processes/bots (with a loading state
while it fetches), and a bot card hosting a **bot-details** table that shows the structured data
the selected bot has produced — rows of fields, with a status per row. That table is the
substance of the page: the worker's *output*.
### How Bots relate to datasheets
The data a Bot feeds in lands as **structured rows** — the same flat, SQL-queryable shape as a
**Datasheet** ([Drive & datasheet](/academy/d5)). So the mental model is: a Bot is *an input
mechanism* for the structured-data layer, in parallel with materialising a datasheet from a View
or sourcing one from a spreadsheet/DB. Once the rows are in, an agent can query them with SQL
exactly as it would any datasheet.
> **Under the hood.** The Excel-from-bot path lands rows via the platform's RPA bot helper into a
> datasheet table — so downstream, bot-fed data is indistinguishable from any other datasheet.
> **By design, today.** The Bots surface is a thin management view — you inspect processes and
> the data they've produced. Authoring and operating the RPA robots themselves happens outside
> this page; treat Bots as *visibility* over RPA inputs, not a full RPA studio.
## Library vs Tool vs Skill — which do I reach for?
These three feel similar (all "reusable capability"), but they live in different worlds:
| You want… | Reach for | Why |
|---|---|---|
| A bit of logic reused across **pipeline nodes** (reshape, derive, normalise) | **Library** (this page) | It's the snippet a **Python Library** XFlow node runs. |
| A callable an **agent** can invoke during its reasoning (search, an API, a function) | **Tool / Function** ([A5](/academy/a5)) | Tools live in the agent's toolbelt, not in a pipeline node. |
| A named, catalogued **capability bundle** shared across many agents | **Skill / Skill Pack** ([A6](/academy/a6)) | Skills are higher-level, packaged, and discoverable across agents. |
> **Tip.** They're bridges, not silos: a Library item can be **Convert To Tool**-ed to hand it to
> an agent, and packaged capabilities flow up into Skills. Start at the lowest level that solves
> your problem — a Library snippet — and promote only when a real second consumer appears.
## Try it yourself
Author a trivial derivation and call it from a pipeline:
1. `Studio ▸ Asset Builder ▸ Library` → **+ Library**. Name it `shout`, set **Library Type** =
**Python**, body:
```python
def main(**kwargs):
return {"text": str(kwargs.get("text", "")).upper()}
```
Save — it appears as **V1**.
2. Open any XFlow (`Studio ▸ Automation ▸ XFlow`), drag a **Python Library** node onto the
canvas.
3. In the node config, select your `shout` library item and wire an input that supplies `text`.
4. **Execute** the flow with a sample input and confirm the node returns the upper-cased text.
5. Bonus: back on the Library page, select `shout` and click **Convert To Tool** — you've just
turned a pipeline snippet into something an agent can call.
## Where to go next
- [Shaping the experience](/academy/e7) — turn your built solution into the surfaces your
end-users actually see.
- [XFlows & pipelines](/academy/a10) — the **Python Library** node inside a pipeline.
- [Tools & functions](/academy/a5) — promoting a snippet to an agent capability.
- [Glossary](/academy/r0) — *Library / Derivation Library* and *Bot (RPA)* in one place.
---
## A2 · LLMs & services
URL: https://www.botminds.ai/academy/a2
> Botminds Academy — Platform · Agents
# LLMs & services
> **In one line.** Two Studio surfaces that supply an agent's engine: the **LLMs** page (which provider models your agents may run on) and the **Services** library (registering external long-running workers a mesh can hand jobs to).
> **You'll be able to.** Import a prebuilt provider model, register and **test** a custom one, understand how an agent selects a model, and recognise when a job belongs to a flag-gated async **Service**.
> **Where this lives.** `Studio ▸ Agent Builder ▸ LLMs` (`/studio/.../agent_builder/llms`) and `Studio ▸ Agent Builder ▸ Services` (`/studio/.../agent_builder/services`)
## Why it matters
Every agent needs an engine: a large-language model to think with. The **LLMs** page is where you tell the platform which provider models exist and how to reach them, so the agent's **Model** tab has something to pick. Most of the time the prebuilt models are enough; you import one and move on. You only come here to add a custom model when you have your own provider account, region, or deployment.
The **Services** library is a different, more advanced surface. It registers external long-running workers (a GPU model, an OCR farm, a slow partner API) that take longer than the platform's in-run time limit and so can't run as an ordinary step. It is flag-gated and only relevant once you are building meshes. Treat Part A as everyday and Part B as on-demand.
> **Watch out: two different "models".** This page's **LLM / Model** is a *provider model* (Azure OpenAI, Gemini, and so on), the thing an agent thinks with. That is **not** the **AI Model** of [AI Builder](/academy/a9), which is a *trainable extractor* you teach with corrected examples. Same English word, unrelated objects.
## Part A — LLMs
### What an LLM config is
An **LLM config** is one row that says: "this provider model exists and here is how to reach it." It bundles:
- a **provider** (Azure OpenAI, Azure AI Foundry, Google Gemini, AWS Bedrock, a Managed Gateway, ...),
- the **model name / deployment** (e.g. `gpt-4o`, `gemini-1.5-pro`),
- an **endpoint** (the URL the platform calls), and
- **credentials** (an API key or cloud identity), stored encrypted, never shown back.
Once a config exists and is **verified**, it appears in the **LLM Model** picker on every agent's **Model** tab.
> **Under the hood.** A config is a `bm.ai_models` row; the orchestrator decrypts its credentials at run time and builds the actual provider client. The agent only stores a *reference* to the config, not the secret.
### The LLMs page
```
┌ Studio ▸ Agent Builder ▸ LLMs ───────────────────────────────────────────────┐
│ ┌ LLMs ─────────────────┐ │ Detail — selected model │
│ │ [⇅ sort] [search] │ │ ┌──────────────────────────────────────────┐ │
│ │ ───────────────────── │ │ │ Model Provider: Azure OpenAI │ │
│ │ • gpt-4o (Azure) │◄─┤ │ (name, provider — read-only projection) │ │
│ │ • gemini-1.5-pro │ │ └──────────────────────────────────────────┘ │
│ │ • my-bedrock-claude │ │ │
│ │ … (server-paged) │ │ │
│ └───────────────────────┘ │ │
│ [ + Add Model ] ← footer button opens the import/add dialog │
└──────────────────────────────────────────────────────────────────────────────┘
```
A two-pane shell: a **server-paged list** of registered models on the left with a **sort toggle** (date to A-Z and back) and a **search** field, and a detail pane showing the selected model's **Model Provider**. If the project has no models yet, the empty state offers an **Add Model** call to action. The one action that matters is **+ Add Model** in the footer.
### The Add Model dialog — two tabs
**Tab 1 — Import LLM.** A card grid of prebuilt platform models. Each card shows the model and a chip: **Already Imported** or **Click to import**. Subscription-level defaults carry a **Default** badge. **Load More** pages through the catalogue. This is the one-click path.
**Tab 2 — Add New LLM.** The full form, for a custom model:
| Section | Field | What it does |
|---|---|---|
| **Provider & Model** | **Provider** (select) | Which provider family this model belongs to |
| | **Model** dropdown *(Managed Gateway / LiteLLM only)* | Pick from gateway-served models; empty-state **Retry** re-fetches |
| | **LLM Name** (text) *(all other providers)* | The model / deployment name you call |
| **Connection** *(non-gateway, provider-driven)* | **API Type** | Provider API flavour |
| | **Azure Endpoint** / **Endpoint** | The base URL the platform calls |
| | **AWS Access Key ID / Secret / Region** | Bedrock credentials |
| | **Client ID / API Key / Tenant ID / Authority / Scope** | Identity/key fields (masked, create-only) |
| | **API Version** | Provider API version string |
| | **Model ID** | Provider-side model/deployment id |
| **Options** | **Is Embedding** (toggle) | Marks this as an *embedding* model (for vectorising/RAG) rather than a chat model |
| **Footer** | **Test** | Validates the connection — required |
| | **Submit** | Saves the config — disabled until Test passes |
> **Test gates Submit.** You cannot save a custom LLM until **Test** reports *"Connection verified"*. This is deliberate: it stops a typo in an endpoint or a wrong key from silently breaking every agent that later selects the model.
> **Which fields appear depends on the provider.** Choose Azure and you get Azure Endpoint + API Version; choose AWS Bedrock and you get the three AWS fields; choose the **Managed Gateway (LiteLLM)** and the free-text name turns into a **Model** dropdown of what the gateway already serves (no endpoint or keys to enter at all).
### How agents pick a model
You don't bind a model here; you bind it on the agent's **Model** tab. There, **LLM Model** is a **multi-select**, and selecting more than one is a feature, not a mistake:
- The agent runs on a **pool** of the models you select.
- At run time the platform picks one and, if a call fails or rate-limits, **fails over** to another in the pool.
This page stocks the shelf; the agent's Model tab picks from it. Add a second model to a pool when you want resilience against a single provider hiccup. Full Model-tab behaviour (Agent Mode, thinking budget, sampling) is in [Your first agent](/academy/a3).
### Prebuilt vs custom
| Use the **prebuilt** models (Import tab) when... | Add a **custom** LLM (Add New tab) when... |
|---|---|
| You just need a capable general model | You must use **your own** Azure/Gemini/Bedrock account or region (data-residency, billing, quota) |
| You're prototyping or following a use-case | You have a **private deployment** or fine-tuned model at a specific endpoint |
| The Default-badged subscription model is fine | You need an **embedding** model the catalogue doesn't offer (set **Is Embedding**) |
> **Publishing note.** Credentials are **DECLARE-class**: when you package an agent or solution for the [Hub](/academy/v4), the model's endpoint and keys are never shipped. The package carries only a *requirement* ("needs an Azure-OpenAI class model"); whoever installs it supplies their own LLM config. Structure travels, secrets don't.
## Part B — Services (async, advanced)
> **Flag-gated.** The Services library and async services run only when **`BM_MESH_SERVICES_ENABLED`** is on. If you don't see **Services** in the Agent Builder rail, the flag is off; skip Part B. Nothing in Part A or your everyday agents depends on it.
### What a Service is
A **Service** is a registered external, long-running worker (a GPU inference model, a heavy OCR pipeline, a slow partner API) that exceeds the in-platform run-time limit: a mesh member must finish within roughly **240 seconds**. Work that can't fit that budget can't run as an ordinary step, so you register it as a Service instead.
The shape is **pull, not push**:
- A mesh member of kind **Service** doesn't do the work; it **parks** (status `awaiting`), holding no worker slot, and waits.
- Your external worker **pulls** the job over a tiny HTTP gateway — three verbs, **claim → complete / fail** — authenticated with a per-service secret (`svcsec_...`).
- When the worker reports back, the parked member wakes and the mesh continues.
Because the worker dials out to claim work, the platform never needs the worker's address or to reach into your network. That is what lets a Service safely be a GPU box in your own data-centre.
> **Under the hood.** The parked member consumes no Prefect/worker slot while `awaiting`, so a single slow Service can't starve the rest of a mesh run. A run is `done` only when nothing is running, pending, *or* awaiting.
### The Services library page
A menu-panel list (columns **name**, **service id**, **transport**) with a footer **+ Service** button. The empty state reads *"Register a long-running external service..."*. The detail pane has three tabs:
| Tab | What it shows |
|---|---|
| **Details** | The registration: **Service ID** (code, copy), **Transport** chip, **Binding** chip (if set), **Callback event** (when binding = callback), **Input mode**, **Result keys**, **Max wait (s)**, **Max retries**. The ⋯ menu offers **Edit · Rotate secret · Delete**. |
| **Runs** | Live invocations: `job_id`, a status pill (`submitted` / `claimed` / `done` / `failed` / `dead_letter`), attempt count, and the document, with **Refresh**. Empty: *"No invocations yet"*. |
| **Callbacks** | Inbound callback routing rows: outcome (`resumed` / `ambiguous` / `no_match` / `error`), event, document, duplicate count, job, and detail, with **Refresh**. Shows *why* a callback did or didn't resume a parked job. |
### The register dialog
| Field | What it does |
|---|---|
| **Service ID** (required) | The stable id your worker uses to claim jobs |
| **Name** | Human-friendly label |
| **Transport** | How jobs reach the worker: **mesh-bus** / **servicebus** / **redis** / **webhook** |
| **Input mode** | How the payload is passed: **baton** (inline) or **blob_ref** (a pointer to blob storage, for large inputs) |
| **Result keys** | Comma-separated names of the values the worker returns |
| **Callback type** | The inbound event type that resumes the job (when applicable) |
| **Max wait (s)** | How long the platform parks before giving up |
| **Max retries** | How many times to re-offer a failed job |
On success the dialog shows **"Service registered"** and reveals the service secret (`svcsec_...`) once.
> **The secret is shown once.** Copy `svcsec_...` immediately. If you lose it, **Rotate secret** on the Details tab issues a new one (and invalidates the old); there is no "show again".
### When you need a Service
A Service is only useful inside a **mesh**: in the mesh designer you add a member that references it (`{kind: "service", id}`), and when the baton reaches it, the member parks and your external worker takes over. Building the mesh itself is [Teams & mesh](/academy/a11).
| You **don't** need a Service when... | You **do** need a Service when... |
|---|---|
| The work finishes in seconds (ordinary tool / agent step) | The work takes **minutes**: GPU inference, large-batch OCR, a slow partner API |
| You can call an external API as a normal [Tool](/academy/a5) or [MCP server](/academy/a7) within the time limit | The worker must run on **your** hardware and **pull** jobs (no inbound access) |
| You're not building a mesh | You're building a **mesh** and one stage exceeds the ~240 s member ceiling |
## Try it yourself
**A — Import and verify an LLM** (everyone can do this):
1. Go to `Studio ▸ Agent Builder ▸ LLMs`, click **+ Add Model**, and on the **Import LLM** tab import a card marked **Click to import**. Confirm it flips to **Already Imported**.
2. Click **+ Add Model** again, switch to **Add New LLM**, pick a **Provider**, and watch the **Connection** fields change to match it.
3. Fill in the endpoint and credentials for a model you control, click **Test**, and note that **Submit stays disabled** until Test reports *"Connection verified"*. Then **Submit**.
4. Open any agent's **Model** tab and confirm your model is selectable. Add a second model to the pool to see failover in action.
**B — Register a Service** (only if you see the **Services** tab):
1. Click **+ Service**. Set a **Service ID**, pick a **Transport** (try `redis`), leave **Input mode** = `baton`, add a **Result key** or two, and a sensible **Max wait** / **Max retries**.
2. Save and **copy the `svcsec_...` secret** from the success state.
3. Check the **Details** tab, then peek at **Runs** and **Callbacks** (empty until a mesh invokes the service).
## Where to go next
- [Your first agent](/academy/a3) — the Model tab, pooling, failover.
- [XFlows & pipelines](/academy/a10) — the visual pipelines that string steps together.
- [Teams & mesh](/academy/a11) — where Services actually get wired in.
- [AI Builder](/academy/a9) — the *other* kind of "model": trainable extractors.
---
## A3 · Your first agent
URL: https://www.botminds.ai/academy/a3
> Botminds Academy — Platform · Agents
# Your first agent
> **In one line.** The Agents page and the agent editor, end to end: every tab, the playground, and how to wire an agent to a Collection so it actually does work.
> **You'll be able to.** Build a real, working agent from a blank form, test it live in the playground, and hand it a collection of documents to process.
> **Where this lives.** `Studio ▸ Agent Builder ▸ Agents` — route `/studio/.../agent_builder/agents`
## Why it matters
An **agent** is the unit of work on this platform: a configured AI worker you assemble from plain-language instructions, a model, some knowledge, a few tools, and the rules it must obey. You don't program it; you *describe* it. Everything else in this pillar (tools, skills, MCP, guard rails, teams, pipelines) is just deepening one of the tabs you'll meet here. Learn this surface well and the rest is detail.
We'll do three things: tour the **Agents page**, build an agent **tab by tab**, and **test it in the playground**, then point it at a Collection so it starts processing documents.
> **Under the hood.** The Agents page is *unified*: it lists single **Agents**, **Multi-Agent teams**, **XFlows**, and **Meshes** in one gallery. They're different kinds of "runnable", but you find and open all of them here. This page focuses on the single Agent; teams and meshes get [Teams & mesh](/academy/a11), pipelines get [XFlows & pipelines](/academy/a10).
## The Agents page
```
┌─ Studio ▸ Agent Builder ▸ Agents ───────────────────────────────────────────────────────────┐
│ ┌─ L2 LIST (left) ──────────────────────┐ │ ┌─ DETAIL / RUN PANE (right) ─────────────────┐ │
│ │ Agents [Kind ▾] [↕] [search] │ │ │ (selected agent) [ ⋮ ] │ │
│ │ Kind: All / Agent / Multi-Agent / │ │ │ ┌ Persona Model Knowledge Capabilities … ┐ │ │
│ │ XFlow / Mesh │ │ │ │ read-only projection of each tab │ │ │
│ │ ───────────────────────────────────── │ │ │ └─────────────────────────────────────────┘ │ │
│ │ [A] Invoice Extractor V3 ▾ │ │ │ [ Playground | Runs | Evaluation ] │ │
│ │ extracts + flags overdue … │ │ │ ┌─────────────────────────────────────────┐ │ │
│ │ ▸ 2 Past Versions │ │ │ │ chat with the agent, see tool calls, │ │ │
│ │ [A] Policy Q&A V1 │ │ │ │ metrics, HITL approval cards … │ │ │
│ │ [X] Nightly Filings Pipeline │ │ │ └─────────────────────────────────────────┘ │ │
│ │ [M] Claims Mesh │ │ │ │ │
│ │ ───────────────────────────────────── │ │ │ │ │
│ │ [ + Agent ▾ ] │ │ │ │ │
│ └───────────────────────────────────────┘ │ └──────────────────────────────────────────────┘ │
└───────────────────────────────────────────────────────────────────────────────────────────────┘
```
The left **L2 list** is the gallery; the right pane shows whichever item you select. Click an agent and the right pane shows its config tabs plus a live **Playground**; click an XFlow or Mesh and the right pane swaps to the embedded pipeline designer instead.
### What every control does
| Control | What it does | Notes |
|---|---|---|
| **Kind filter** (`mat-select`) | Filters the list to **All / Agent / Multi-Agent / XFlow / Mesh** | "Agent" is the default unit of work. |
| **Sort toggle** (↕) | Cycles **latest → A-Z → Z-A** | |
| **Kind badge** (left of each row) | **A** = agent or team, **X** = xflow, **M** = mesh | Hover for the full kind. |
| **Version chip** (`V3 ▾`) | A dropdown of the agent's saved versions (V1, V2 ... plus "Load more...", paged 10) | Only appears once an agent has more than one version. |
| **"N Past Versions"** expander | Lazily loads and lists prior versions as clickable rows | A spinner shows while it fetches. |
| **+ Agent** (footer ▾) | The create picker: **Agent / XFlow / Mesh** | Permission-gated. |
| **Row ⋮ menu** | **Publish / Edit / Delete / Import** (from Hub) | See below. |
| **Load More** | Appears only when the project has ≥ 1000 items | |
> **Tip.** The list auto-selects the first Agent when the page loads, so you usually land straight in a working agent. The moment you click a row yourself, that choice sticks; a late server refresh can't yank you elsewhere.
### The "+ Agent" picker and the row ⋮ menu
**+ Agent** opens the create picker: **Agent** (a single AI worker, opens the editor below), **XFlow** (a visual pipeline, [XFlows & pipelines](/academy/a10)), or **Mesh** (a durable multi-stage pipeline, [Teams & mesh](/academy/a11)).
| Row action | What it does | Notes |
|---|---|---|
| **Publish** | Pushes the agent to a **Hub** so other projects can install it | [Hubs & solutions](/academy/v4). |
| **Edit** | Opens the agent editor in edit mode | Permission **Edit Agent** / **Edit Multi Agent**. |
| **Delete** (red) | Confirm dialog, then removes the agent | Permission-gated. Destructive. |
| **Import** | Brings an agent **in** from a Hub | |
### Behaviours to know
- **Live sync.** The list re-fetches in place when anyone (a teammate, another tab, an automation) creates, edits, or deletes an agent; you see a small change toast. (Flag `realtimeResourceSync`.)
- **Deep links.** Selecting a row rewrites the URL to `agents/:kind/:id`; that link is shareable and bookmarkable. The Collection workspace's "Open in Agent Builder" button lands you here.
> **Flag-gated (the right pane).** When the `agentHarness` flag is **on** (the shipped default), the right pane is the **Agent Harness**: a "view = edit" mirror of the builder with read-only **Persona / Model / Knowledge / Capabilities / Output / Governance / Context / Team** tabs (each with an edit control that jumps into the real editor), plus operational **Playground / Runs / Evaluation** tabs. With the flag **off**, the right pane is the older three-tab view (**Details / Runs / Evaluation**). Either way, **+ Agent** and **Edit** open the same editor described next.
## Building an agent — the editor, tab by tab
Click **+ Agent ▸ Agent** (or **Edit** on a row). The editor opens as a full-window dialog: an 8-tab **builder pane** on the left, a live **playground pane** on the right, so you build and test without leaving the dialog. The divider collapses either pane (**Ctrl/Cmd + \** hides the playground; **Ctrl/Cmd + Shift + \** hides the builder), and your active tab and collapse state are remembered next time.
> **Two layouts exist.** The default is the new **tabbed builder** (`newAgentBuilder` flag, on by default). The older single-page editor (one long scrolling form) is still reachable; force it for a session with the URL query `?newBuilder=0`. Both edit the *same* agent; only the arrangement differs. This page teaches the default tabbed builder. The full legacy field order is in the [Agent Builder field reference](/academy/r1).
> **Watch out.** There is **no autosave** here. Your work lives only in the form until you click **Save Agent** (disabled while anything required is missing). Save before you close.
The exhaustive field-by-field list, every slider and range, is in the [Agent Builder field reference](/academy/r1); here is what each tab *means* and what to put there.
### Tab 1 — Persona
*Who the agent is.* Set the **Name**, a one-line **Description**, and the **Instructions**: the system prompt that is the soul of the agent. Write it like a job brief: who it is, what to do, how to behave, and what to return. A **field co-pilot** sits on the Instructions box; type a one-line seed and it drafts a fuller prompt you then refine. You can drop global variables with `{{scope.X}}`. This single field does more for quality than any slider.
### Tab 2 — Model
*What powers it, and how hard it thinks.* Pick one or more **LLM Models** (several = a failover pool; register models on the [LLMs page](/academy/a2)). Choose the **Agent Mode**: **Auto**, **Fast**, or **Thinking** (table below). If you pick Thinking, you can set a **thinking budget**. An **Advanced sampling** expander hides Temperature, Top P, Max tokens, and penalties; leave them at defaults unless you know why you're changing them (for extraction, keep Temperature low).
### Tab 3 — Knowledge
*What the agent may read.* Three sources, on sub-tabs: a **View** (a saved slice of a collection), a **Datasheet** (a SQL table), and, with the `knowledgeCollections` flag, **Knowledge collections** (whole indexed corpora, with a readiness dot so you know the index is built). Two locks tighten retrieval: **Knowledge lock** (answer *only* from attached knowledge) and **Exact-match lock** (exact rather than semantic matching). Scoping knowledge here is what stops an agent from "leaking" information it was never given.
### Tab 4 — Capabilities
*What the agent can do.* Four sections: **Tools** (callables — SQL search, retrievers, your own APIs; [Tools & functions](/academy/a5)), **MCP servers** ([MCP servers](/academy/a7)), **Skill Packs** and **Skills** ([Skills & skill packs](/academy/a6)). You **pin** the skills you want; a ghost list shows auto-discoverable in-scope skills with a **Pin** button, and a **"Restrict to pinned skills only"** checkbox locks the agent to exactly what you pinned.
### Tab 5 — Output
*The shape of the answer.* Mode cards at the top: **Table output**, **Standardization**, **Structured output**, **Section classification**, **Auto-annotate document**. **Structured output** is the extraction workhorse: switch it on and a sub-form appears where you pick the **Taxonomy/Learner** (the schema whose Fields to fill), choose the **Process unit** (Page / Section / Image), add **Labels** with per-field **Descriptions**, and turn on **Reasoning / Confidence Score / References**. Confidence per field is what later routes a document to human review. This is the tab that turns a chatty agent into a data extractor.
### Tab 6 — Governance
*The rules and the sign-offs.* Attach **Guard rails** (named policy objects; [Guard rails](/academy/a8)) and configure **Approvals**: per-tool and per-team-member human-in-the-loop checkpoints (see HITL below).
### Tab 7 — Context (Context Kernel)
*Advanced: what context gets assembled into each prompt.* A **Profile template** plus a **Sources** table (tiers + priorities), per-tier **token budgets**, a **truncation** strategy, and a **Run preview** that shows the final instructions and where the token budget was spent *before* you run anything. Most agents are fine on the default template; reach for this when an agent is over- or under-fed on context.
### Tab 8 — Subagents
*Turning this agent into a team leader.* Add **subagents** (member agents) and a **coordination mode**, and this agent becomes a coordinator that delegates. Leave it empty and it stays a single agent. Full coverage in [Teams & mesh](/academy/a11).
When the form is valid, click **Save Agent** (the footer shows "Saving...").
## Auto, Fast & Thinking mode
The **Agent Mode** (set on the Model tab) decides *how* the agent reasons:
| Mode | What it is | Pick it when |
|---|---|---|
| **Auto** | The default selectable option. The agent decides per question: Fast for simple/greeting/lookup messages, Thinking for analysis or multi-step work. | You want the best of both and don't need to guarantee one path. *Routing is still maturing; pick Fast or Thinking explicitly when you need predictable behaviour.* |
| **Fast** | A single pass; the model answers directly. Lowest latency and cost. | High-volume, well-bounded work: field extraction, classification, short answers. Most production agents. |
| **Thinking** | The model reasons step-by-step (optionally with a **thinking budget**) before answering. | Multi-step problems, analysis, judgement calls, anything where the *reasoning path* matters or quality beats speed. |
> **Tip.** Build and tune in **Thinking** mode to see the agent's reasoning, then switch to **Fast** for production once you trust it: same instructions at a fraction of the latency. (The legacy playground lets you flip the mode per run to compare; in the new builder, set the mode on the Model tab and re-save.)
## HITL — human-in-the-loop approval
Some steps shouldn't run unsupervised: posting to an external system, sending an email, anything costly or irreversible. **HITL** makes the agent pause at that step and wait for a person.
You configure it on **Governance ▸ Approvals** (per tool, and per team member). For each tool you set **Request approval** (on/off), the **Approval type** (**Form** or **Multi-Select**), and the **Approval card text** the reviewer reads. At run time the agent stops and surfaces a card with three choices: **Reject**, **Review** (leave feedback and send back), or **Approve & Execute**. You'll see those exact cards in the playground while testing, which is the whole point: rehearse the approval flow before any real user meets it.
## The Playground — how you test and iterate
The right pane is where a builder actually works. It has two tabs.
### Playground tab
A live chat with the agent you're building. It uses the current, *unsaved* form state, so you can tweak a tab and immediately see the effect.
1. Choose an **Input Type**: **Text** (just chat), **Document** (run against a picked document, with optional **Page Numbers**), or **Project**.
2. Optionally toggle **Enable Chat History** or attach files with **+**. (Set the **Agent Mode** on the Model tab; the new-builder playground has no per-run mode override — that lives in the legacy playground.)
3. Type your prompt in the **question** box and press **Enter** (or **Send**).
4. Watch the answer stream: **tool calls** as the agent invokes them, **thinking blocks** in Thinking mode, rendered **tables and charts**, and download links for attachments.
5. If a step needs approval, the **HITL card** appears right here (**Reject / Review / Approve & Execute**), so you can test the whole approval loop.
This tight loop — change a tab, re-run, read the result — is how you iterate an agent to "good".
### Task & metrics tab
Set up *measured* testing: provide a **Sample Input** and **Sample Output** and **Validate** the agent conforms; then in **Evaluation Rule Setup** pick a **Task** (or hit **Auto-Detect** to have the platform propose one) and choose the **Metrics** (Primary / Optional / Irrelevant) that define "good" for this agent. That feeds the **Evaluation** surface, so you can score the agent objectively rather than by eyeballing chats.
## Connecting the agent to a Collection
A great agent does nothing until it's given work. You hand it a stream of documents by making it a Collection's **intake agent**, assigned from the **Agents pane** of the [collection workspace](/academy/d1):
1. Go to the collection (`Studio ▸ Data Model ▸ Collections`, or its workspace) and open its **Agents** tab.
2. **Assign** your agent as the collection's intake/processing agent.
3. From now on, every document that lands in the collection — uploaded, pasted, or pulled in by a connector — is run by that agent automatically, filling the schema's Fields and entering the lifecycle.
> **Tip.** The collection's **Agents** tab also has an **"Open in Agent Builder"** link that deep-links straight back to this editor for the assigned agent, so you can jump between tuning the agent and watching it process documents without losing your place.
That's the heartbeat from [the platform in one picture](/academy/s1): the collection holds the work, the agent does it, and you watch it happen live.
## Try it yourself — build an "Invoice Extractor"
1. **Open the editor.** `Studio ▸ Agent Builder ▸ Agents` → **+ Agent ▸ Agent**.
2. **Persona tab.** **Name:** `Invoice Extractor`. **Description:** `Extracts header fields from vendor invoices and flags overdue ones.` For **Instructions**, use the field co-pilot with the seed *"Extract the key fields from a vendor invoice and flag it if the due date has passed"*, then edit the draft to read roughly: *You are an invoice-processing assistant. For each invoice, extract the vendor name, invoice number, invoice date, due date, and total amount. If the due date is in the past, set `is_overdue` to true. Return only what the document supports; never invent a value.*
3. **Model tab.** Pick your project's **LLM Model**. Set **Agent Mode = Thinking** for now, so you can watch its reasoning while testing. Leave Advanced sampling at defaults.
4. **Output tab.** Turn on **Structured output**. Choose your invoice **Taxonomy/Learner**, set **Process unit = Page**, and add **Labels** for `vendor_name`, `invoice_number`, `invoice_date`, `due_date`, `total_amount`, `is_overdue`, each with a short **Description** (e.g. *"The grand total including tax"*). Turn on **Confidence Score** and **References**.
5. **Governance tab** *(optional).* If your invoices feed an external system later, add an approval on the relevant tool so a human signs off before anything posts.
6. **Save.** Click **Save Agent**.
7. **Test in the playground.** Set **Input Type = Document**, pick a sample invoice (and a page if needed), press **Enter**. Watch the **Thinking** block, the extracted fields, the **confidence** per field, and the **References** back to the page. Then flip **Agent Mode = Fast** and re-run the same invoice: same fields, much quicker. That's your production setting.
8. **Iterate.** Wrong field? Sharpen its **Description** on the Output tab, re-run, repeat. When a few invoices come out clean, the agent is ready to be assigned to a collection. You'll wire it to a real invoice collection in [Invoice processing](/academy/uc-invoice).
You just built and validated a working extraction agent: no code, all configuration.
## Where to go next
- [Tools & functions](/academy/a5) — the Capabilities tab's tools.
- [Guard rails](/academy/a8) — the Governance tab's rules.
- [LLMs & services](/academy/a2) — register the models the Model tab lists.
- [Invoice processing](/academy/uc-invoice) — put this agent to work end to end.
---
## A4 · Agent varieties
URL: https://www.botminds.ai/academy/a4
> Botminds Academy — Platform · Agents
# Agent varieties
> **In one line.** Same anatomy, different jobs — the four working styles an agent takes on this platform, and how to pick the right one for the task in front of you.
> **You'll be able to.** Name the variety a problem calls for before you open the editor, so the persona, knowledge and wiring follow naturally.
## Why varieties matter
Every agent shares the same [anatomy](/academy/a1) — model, persona, knowledge, capabilities, guard rails. What changes is the *job contract*: what comes in, what must come out, and where the output lands. Get the variety right and the rest of the configuration writes itself. Get it wrong and you'll fight the persona for a week.
## The four working styles
### 1. Answering — the expert you ask
**In:** a question. **Out:** a grounded, cited answer. **Lands in:** chat.
The Agentic Search worker. Attach Knowledge collections, demand citations, instruct refusal when the documents don't contain the answer. Success is measured in trust: a user who clicks a citation and finds exactly the supporting passage comes back tomorrow.
Build it in [S3 · Your first 30 minutes](/academy/s3); harden it in [the Search pattern](/academy/sol-search).
### 2. Extracting — the analyst who fills forms
**In:** a document. **Out:** schema fields with per-field confidence. **Lands in:** the collection's records, visible in the [workspace](/academy/e2).
The workhorse of every [Workflow](/academy/sol-wf). The schema is its real contract — a well-described field ("total invoice amount including tax, as printed") outperforms any persona flourish. Confidence per field is what makes the human-in-the-loop gate possible: high goes through, low goes to [review](/academy/g2), and reviewer corrections become feedback.
An extraction agent is wired to its collection as the intake/processor — see [A3](/academy/a3) for the attachment step.
### 3. Deciding — the officer who rules on cases
**In:** an assembled record (often already extracted). **Out:** a decision with reasons — approve, hold, escalate, route. **Lands in:** the lifecycle stage, the record, the audit trail.
The variety that earns governance. Persona states the policy; guard rails state the boundaries; the lifecycle carries the verdict; the trace preserves the why. Decisions that matter route through [four-eyes approval](/academy/g2) — the agent recommends, a person disposes, and over time the straight-through share grows as trust accumulates.
### 4. Generating — the writer who produces artifacts
**In:** source records plus an instruction. **Out:** a produced artifact — a summary, a findings report, a client letter, a decision package. **Lands in:** the document's summary pane, an export, or a downstream system via the [Runtime API](/academy/v1).
Generation quality is grounding quality: a summarizer attached to the settled fields writes accurate summaries; one attached to nothing writes fiction. Keep the persona's output contract exact — length, sections, tone.
## Choosing, quickly
| The sentence in your head | Variety | Start |
|---|---|---|
| "People keep asking us…" | Answering | [sol-search](/academy/sol-search) |
| "Someone reads each one and types the values into…" | Extracting | [B3 · Invoice settlement](/academy/uc-invoice) |
| "Then a supervisor approves or kicks it back…" | Deciding | [G2 · Human-in-the-loop](/academy/g2) |
| "Then we write it up for…" | Generating | [A3 · Your first agent](/academy/a3) |
Real processes chain them: extract, then decide, then generate. That chain is exactly what [teams and meshes](/academy/a11) exist for — classify → validate → enrich → approve → summarize is four varieties holding a baton.
## Where to go next
- The shared machinery underneath: [A1 · Agent anatomy](/academy/a1).
- Chaining varieties into one engine: [A11 · Teams & mesh](/academy/a11).
- Proving a variety performs before it ships: [A12 · Crew & evaluations](/academy/a12).
---
## A5 · Tools & functions
URL: https://www.botminds.ai/academy/a5
> Botminds Academy — Platform · Agents
# Tools & functions
> **In one line.** A tool (the platform also calls it a function) is a callable an agent can
> invoke mid-conversation — built-in toolkits the platform wires up for you, and custom API
> tools you register yourself.
> **You'll be able to.** Register a custom API tool from a JSON input schema, give it default
> parameter values, and wire it onto an agent's **Capabilities** tab.
> **Where this lives.** `Studio ▸ Agent Builder ▸ Tools` (`/studio/.../agent_builder/tools`),
> plus the agent editor's **Capabilities** tab.
## Why agents need tools
An LLM on its own can only *talk*. The moment your agent needs to *do* something it can't reason
its way to from the prompt alone — look up a row in a table, fetch a live exchange rate, search
your knowledge corpus, call your order system — it needs a **tool**: a callable the agent can
invoke mid-conversation. The agent's model decides, turn by turn, whether to answer directly or
to call a tool first, read the result, and then answer. You don't program that decision — you
give the agent good tools with clear descriptions, and the model picks.
This page assumes [Core concepts](/academy/s2) and [Your first agent](/academy/a3). To use the
SQL search tool you'll want a [Datasheet](/academy/d5); for the knowledge retriever, a Knowledge
collection.
There are two families:
- **Built-in toolkits** — callables the platform wires up *for* you from configuration you
already did. The big two: **SQL search** over a [Datasheet](/academy/d5) (the agent writes
read-only SQL against your structured table) and the **knowledge retriever** over a Knowledge
collection (the agent embeds the question and pulls back cited chunks). You don't register
these on the Tools page — they switch on automatically when you attach a Datasheet or a
Knowledge collection on the agent's **Knowledge** tab.
- **Custom API tools** — callables *you* register on the Tools page: an HTTP endpoint plus a
description and a JSON input schema. This is how you teach an agent to call anything your
business already exposes over an API.
This page is about the second family — the Tools page — because that's the surface you operate.
> **Under the hood.** Every tool — built-in or custom — becomes a *validating function* the model
> can call: the input schema is turned into a checked function signature, so a malformed call is
> rejected before your API is ever hit. Built-in toolkits map to SQL / OpenSearch retriever
> toolkits; custom tools map to an API-call function. You never see this — but it's why the input
> schema matters so much.
## The Tools page
`Studio ▸ Agent Builder ▸ Tools` is a two-pane shell: a list of your tools on the left, the
selected tool's detail on the right. Creating or editing a tool opens a dialog over the top.
```
┌───────────────────────────┬─────────────────────────────────────────────────┐
│ Tools [⇅ sort] │ exchange-rate-lookup [ ⋮ ] │
│ ┌──────────────────────┐ │ Tool Name exchange-rate-lookup │
│ │ exchange-rate-lookup │◀│ Tool Description │
│ │ order-status │ │ "Look up today's FX rate between two ISO │
│ │ vendor-risk-score │ │ currency codes. Use when the user asks │
│ └──────────────────────┘ │ to convert two currencies." │
│ [ + Tool ] │ Snippet (generated function definition) │
│ (empty ⇒ "No tools…") │ ⋮ menu: Edit Delete │
└───────────────────────────┴─────────────────────────────────────────────────┘
```
The list is server-paged, so a **Load more** affordance appears when you have many tools. An
empty project shows a "No tools" empty state with an inline create CTA.
| Control | What it does | Notes |
|---|---|---|
| **Sort toggle** | Flips the list between newest-first and A–Z | Cosmetic only. |
| **+ Tool** (footer) | Opens the Add Tool dialog | Needs the **Add Tool** permission. |
| **Tool Name** (detail) | The tool's identifier | Shown to the agent. |
| **Tool Description** (detail) | The natural-language description the model reads | The single most important field — see below. |
| **Snippet** (detail) | The generated function definition | Read-only; for your reference. |
| **⋮ ▸ Edit** | Reopens the dialog in form view | Permission-gated. |
| **⋮ ▸ Delete** | Removes the tool | Destructive; confirm. Won't auto-detach from agents already using it. |
## The Add / Edit Tool dialog
**+ Tool** (or **⋮ ▸ Edit**) opens a wide dialog with two views. A brand-new tool starts in the
**import view** (pick a prebuilt one to start from); editing an existing tool jumps straight to
the **form view**.
### Import view — start from a prebuilt tool
When you create a tool with nothing selected, the dialog shows a gallery of prebuilt tool
libraries you can clone as a starting point:
- **Search** field — filter the cards by name.
- **Filter by type** — narrow the grid to a tool type: **API Endpoint**, **JavaScript**,
**Template**, **Prompt**, **Python**, **Agent**, **Agent Tool**, or **UI Card**.
- **Visibility** filter — show built-in vs your custom libraries.
- **Clear Filters** — reset both filters.
Each card shows an icon (by type), the library's name and description, a type chip, and a
**Built-In / Custom** chip; hovering reads "Click to import". Click a card to import it — the
dialog flips to the form view pre-filled from that library. No match shows "No libraries found".
For a plain HTTP lookup, filter to **API Endpoint** and pick the closest prebuilt card; you'll
usually only need to change the URL, the description, and the input schema.
> **Note.** Some prebuilt library types in the import grid (Agent / Agent Tool / UI Card) belong
> to adjacent builders and may not all be relevant to a simple API tool — for a plain HTTP
> lookup, stay in **API Endpoint**.
### Form view — define the tool
| Field | What it is | Why it matters |
|---|---|---|
| **Tool Name** | A short, stable identifier (e.g. `exchange-rate-lookup`) | Becomes the function name the model calls. Keep it lowercase-and-hyphens, descriptive. |
| **Tool Description** | One or two plain-English sentences: *what it does* and *when to use it* | The LLM reads this to decide whether to call the tool. A vague description = a tool the agent never calls (or calls wrongly). Say what it returns and the trigger condition. |
| **Code editor** | The tool's definition — the **API URL**, HTTP **method**, the **JSON input schema** (parameters and their types), and (where the prebuilt template provides them) **auth / headers** | The executable contract. The input schema is what becomes the validated function signature. |
| **Default parameter values** | Pin a fixed value for any input parameter, so the model doesn't have to supply it each call | The field-by-field part most builders miss — see below. |
### The input schema (the parameters)
The schema is a JSON object describing each input the tool accepts — name, type, and whether
it's required. Conceptually:
```jsonc
{
"from_currency": { "type": "string", "description": "ISO code, e.g. USD" },
"to_currency": { "type": "string", "description": "ISO code, e.g. EUR" },
"amount": { "type": "number", "description": "Amount to convert" }
}
```
At runtime the platform turns this into a validated function call: when the model decides to
call your tool, it must supply values matching these names and types. A call missing a required
field, or sending a string where a number is expected, is rejected before your API is hit — so a
confused model can't send garbage to your endpoint. Describe each parameter well: those
per-parameter descriptions guide the model just like the tool description guides *whether* to
call at all.
### Default parameter values
Below the name and description, this section lets you pin values the model should *not* have to
think about. Each row is:
- **Parameter** — a dropdown restricted to the parameters in your input schema (you can only
default a parameter that actually exists). A type chip shows that parameter's type.
- **Value** — a typed input matching the parameter's type: **string** → text box,
**integer / number** → numeric box, **boolean** → toggle, **sensitive** → a masked box with a
show/hide visibility toggle (use this for API keys and tokens). An **Insert variable** menu
lets you splice a `{{variable}}` placeholder (e.g. a project-scope value) into the value
instead of a literal.
- **Remove** (×) — drop the default. **Add default** adds another row.
Use defaults for the parts of the call that are constant for *this* tool — an API key, a fixed
`region`, a `version=2` flag — so the model only fills in the genuinely variable inputs.
> **Watch out.** Put credentials in a **sensitive** default, never in the plain description or
> the URL. Sensitive values are masked in the UI and treated as secrets.
**Save** writes the tool. Save is disabled until the required fields (Name, Description) are
present, and the input schema must parse. Once saved, the tool appears in the list and is
available to attach to any agent.
## Attaching a tool to an agent
A registered tool does nothing until an agent is told it may use it. You do that in the agent
editor, on the **Capabilities** tab:
1. Open `Studio ▸ Agent Builder ▸ Agents`, select your agent, and **Edit** it.
2. Go to the **Capabilities** tab.
3. Under **Tools**, click **+ Add tool**. A picker lists the tools registered on the Tools page.
4. Select your tool — it appears as a card under Tools (with a remove control). Add as many as
the job needs.
5. **Save Agent.**
That's the whole wiring: the tool is registered once (Tools page) and *attached* per agent
(Capabilities tab). The same tool can power many agents.
If a tool should require human sign-off before it runs (anything that *writes* to your systems),
configure an approval for it on the agent's **Governance** tab — the per-tool approval rows live
there. See [Guard rails](/academy/a8).
### Where the built-in toolkits come from
You won't find these on the Tools page — they switch on from the agent's **Knowledge** tab:
| Built-in toolkit | Turns on when… | What the agent can then do |
|---|---|---|
| **SQL search** | you attach a **Datasheet** on the Knowledge tab | Write read-only SQL against that structured table to answer data questions. |
| **Knowledge retriever** | you attach a **Knowledge collection** on the Knowledge tab | Embed the question, retrieve matching chunks, answer with citations. |
So: structured questions → attach a Datasheet (SQL toolkit); corpus questions → attach a
Knowledge collection (retriever); anything else your business exposes over HTTP → a custom API
tool from this page.
## Try it yourself
1. `Studio ▸ Agent Builder ▸ Tools` → **+ Tool**.
2. In the import grid, filter by type **API Endpoint** and import a GET-style card (or the
closest match). The dialog flips to form view.
3. Tool Name: `exchange-rate-lookup`.
4. Tool Description: *"Look up today's FX rate between two ISO currency codes. Use this whenever
the user asks to convert or compare amounts in two different currencies."* Notice it says
**what** and **when**.
5. In the code editor, point the **API URL** at your rate endpoint, set the **method** to GET,
and make the input schema declare `from_currency` (string) and `to_currency` (string), both
required.
6. In **Default parameter values**, add a row, pick (say) an `api_key` parameter, set its type
to **sensitive**, and paste the key — it'll be masked.
7. **Save.** The tool appears in the list with a Snippet on the right.
8. Open an agent → **Edit** → **Capabilities** → **+ Add tool** → pick `exchange-rate-lookup` →
**Save Agent**.
9. In the agent's playground, ask *"What's 100 USD in EUR today?"* and watch the transcript —
you should see a tool call to your endpoint, its result, then a grounded answer.
If the agent answers *without* calling the tool, your description is too weak — sharpen the "use
this when…" sentence and try again. That feedback loop is the whole craft of tools.
## Where to go next
- [Skills & skill packs](/academy/a6) — reusable, bundled capabilities, a step up from a single
tool.
- [Drive & Datasheet](/academy/d5) — build the Datasheet that the built-in SQL search toolkit
queries.
- [Your first agent](/academy/a3) — the Capabilities tab in full context.
- [Guard rails](/academy/a8) — per-tool approvals and safety filters.
---
## A6 · Skills & skill packs
URL: https://www.botminds.ai/academy/a6
> Botminds Academy — Platform · Agents
# Skills & skill packs
> **In one line.** A Skill is a reusable, parameterised capability — instructions plus the tools
> they need — and a Skill Pack bundles several so many agents can share one well-written
> capability.
> **You'll be able to.** Write a skill in the Skill Editor, group skills into a pack, and pin
> either onto an agent.
> **Where this lives.** `Studio ▸ Agent Builder ▸ Skills` (route `/studio/.../agent_builder/skills`).
## Why it matters
You will write the same instruction-plus-tool recipe again and again — "extract the fields off a
résumé", "summarise this contract clause", "look up a customer and draft a reply". A **Skill**
captures one such recipe *once*, as a named, reusable, parameterised capability, so every agent
can use it instead of you re-pasting a prompt into each one. A **Skill Pack** then bundles
related skills together so an agent can pick up a whole toolkit in a single click. Build the
capability well once; reuse it everywhere; fix it in one place.
This page assumes [Your first agent](/academy/a3) (the **Capabilities** tab) and
[Tools & functions](/academy/a5), so you know a *tool* from a *skill*.
### Skill vs tool — don't mix them up
A **tool** is a single low-level *callable* — one API endpoint, one SQL search, one function with
a JSON input schema. A **skill** is a *higher-level* capability: a named bundle of instructions
(a prompt body) plus the tools it needs, written so an agent knows *when* and *how* to use it.
Think of a tool as a verb and a skill as a small playbook that uses verbs.
| | **Tool / Function** | **Skill** | **Skill Pack** |
|---|---|---|---|
| **Granularity** | one callable | one reusable capability (prompt + tools) | a bundle of skills |
| **You author** | code/endpoint + input schema | a name, description, body (Markdown) | a list of member skills |
| **Reused by** | agents that call it | agents that pin it | agents that pin the pack |
| **Built in** | [A5](/academy/a5) | this page | this page |
> **Under the hood.** A skill's body is lazy-loaded — it's only read into the prompt when the
> agent actually invokes the skill, so pinning many skills stays cheap. A Skill Pack carries a
> list of member skill IDs and expands to those members at load time; the agent ends up with the
> same skills as if you'd pinned each one individually.
## The Skills surface
`Studio ▸ Agent Builder ▸ Skills` opens a two-tab builder: one tab for individual **Skills** and
one for **Skill Packs**. Both tabs use the same left-list / right-detail shape you've seen across
Agent Builder.
```
┌──────────────────── Studio ▸ Agent Builder ▸ Skills ─────────────────────┐
│ [ Skills | Skill Packs ] │
│ ┌── list ────────────────────────┐ ┌── detail / editor ──────────────┐ │
│ │ scope ▾ ⇅ sort search │ │ (Skills tab) → SKILL EDITOR │ │
│ │ extract-resume-fields │ │ (Skill Packs tab) → pack │ │
│ │ [Project] V3 ▾ │ │ detail, or "No Skill Pack │ │
│ │ summarise-clause [Platform] │ │ Selected" empty state │ │
│ │ [ + Skill ] / [ + Skill Pack ] │ │ │ │
│ └────────────────────────────────┘ └─────────────────────────────────┘ │
└──────────────────────────────────────────────────────────────────────────┘
```
| Control | What it does | Notes |
|---|---|---|
| **Skills** / **Skill Packs** tabs | Switch between authoring single skills and bundling packs | A spinner shows while packs load. |
| **Scope filter** (`All / Platform / Project`) | Narrows the list by where a skill lives | **Project** skills are yours; **Platform** skills are shipped by the platform (read-only). |
| **Sort toggle** | Flips order (date ⇄ A–Z) | — |
| **Search** | Reveals a field; filters the list by name | — |
| **Scope badge** (on each row) | Shows **Platform** or **Project** | Tells you at a glance whether you can edit it. |
| **Version chip** `V ▾` | A select of the version history (with "Load more") | Every save bumps the version; older ones stay selectable. |
| **+ Skill** | Opens the **Skill Editor** for a new skill | Permission-gated. |
| **+ Skill Pack** | Creates a new pack (right pane switches to create mode) | Permission-gated. |
> **RBAC.** Create/edit buttons appear only if your role has the relevant Agent Builder
> permission. Without it you can still browse and pin existing skills.
## The Skill Editor
Selecting a skill — or clicking **+ Skill** — opens the **Skill Editor** in the right pane. It
has a header strip and two tabs: **Form** (the everyday authoring surface) and **Markdown** (the
raw skill body, where the actual instructions live).
| Control | What it does | Notes |
|---|---|---|
| **‹ Back** | Returns to the Skills list | Unsaved edits are lost. |
| **Title** | Shows mode + `: ` (e.g. `Project: extract-resume-fields`) | Reads *New* / *Edit* / *View*. |
| **Read-only** badge | Marks a skill you cannot edit (Platform-, environment-, or subscription-scoped) | Hover for the reason; the editor becomes view-only. |
| **Sysadmin override** badge | Shows when a sysadmin is editing a normally-locked skill | Admin-only path. |
| **Reset to default** | Reverts a customised Platform skill to as-shipped | Sysadmin only; appears only when a Platform skill has been customised. |
| **Create / Update** | Saves the skill (creating it, or bumping its version) | Disabled unless the form is dirty *and* not read-only — there is no autosave. |
### Form tab — field by field
| Field | What it's for |
|---|---|
| **Name** | The skill's handle, lower-kebab style — e.g. `extract-resume-fields`. This is how agents and packs refer to it. |
| **Description** | One or two sentences stating **what it does and *when* to use it** — e.g. "Extract structured fields from a résumé; use when the document is a CV." The "use when…" half matters: it's the hint that tells an agent to reach for this skill. |
| **Tags** | Free-form labels for searching and grouping skills. |
| **In packs** | A chip strip of the Skill Packs this skill belongs to — add or remove pack membership right here, the mirror of editing from the pack side. |
| **Runtime fields** *(when applicable)* | For runtime/Python-backed skills only: **script path**, **packages**, **allowed domains**. Plain prompt-only skills won't show these. |
### Markdown tab — the body
The **Markdown** tab is the skill's body: the instructions the agent reads when it invokes the
skill, written as a Markdown document (the "SKILL.md" style). This is where you say, in plain
language, how to do the capability: the steps, the tools to call, the output format, the edge
cases. Parameters and inputs the skill expects are described here in the body. Keep it focused —
remember the body is only pulled into the prompt at the moment of use.
Write the **Description** for *discovery* (when should an agent pick this skill?) and the
**Markdown body** for *execution* (how does it do the job?). Mixing the two is the most common
authoring mistake.
### Behaviours to know
- **Save is explicit and version-bumping.** Each **Create/Update** writes a new version; the old
one stays selectable in the row's version chip. Nothing autosaves.
- **Scope is the Project.** Skills you author are **Project**-scoped — usable by agents in *this*
project. **Platform**-scoped skills are read-only here.
- **Read-only states are real.** If you opened a Platform/environment/subscription skill, the
**Create/Update** button stays disabled and a **Read-only** badge explains why. Clone-or-share
via the Hub instead of trying to edit in place.
## Skill Packs
A **Skill Pack** bundles related skills so an agent picks up the whole set at once. On the
**Skill Packs** tab the left pane lists packs (with the same scope/sort/search header); the
right pane is the pack detail.
| Control | What it does | Notes |
|---|---|---|
| **Pack card** | Shows name, scope badge, version badge, description | One per pack. |
| **▸ Skills (n)** expander | Lists the pack's child skills | Click to expand. |
| **+ Add skill to pack** | Adds a member skill to a writable pack | Only on packs you can edit. |
| **+ Skill Pack** | Creates a new pack | Right pane switches to create mode. |
| **Pack detail** (right) | Shows the member **Skills**, **Description**, **Versions**, and **Linked agents** | "Linked agents" tells you who's relying on this pack before you change it. |
### How a pack expands at load time
When an agent loads a pinned pack, the platform expands the pack into its member skills — the
agent behaves exactly as if you had pinned each member skill individually. So a pack is a
convenience wrapper: pin once, get the whole set; edit the pack's membership later, and every
agent that pinned it picks up the change next load.
> **Watch out.** Because a pack expands to its members, a skill can end up reaching an agent
> *both* directly (pinned) *and* via a pack. The agent's **Capabilities** tab flags this with an
> **"also in pack X"** collision badge so you're not surprised by the duplicate.
## Attaching a skill or pack to an agent
You don't attach skills here — you attach them on the **agent**, in the **Capabilities** tab of
the agent editor. That tab has four capability groups; two are about skills:
- **Skill Packs** — **+ Pin pack**; pinned packs show as cards labelled **"Pack"**, with the
member count (**N skills**) and a scope badge.
- **Skills** — **+ Pin skill** to pin an individual skill. Pinned skills show **Pinned** plus a
**runtime** badge and any **"also in pack X"** collision badge. A ghost list below offers the
in-scope skills the agent could auto-discover, each with its own **Pin** button.
- **"Restrict this agent to pinned skills only"** checkbox — when ticked, the agent may use
*only* the skills you explicitly pinned, ignoring auto-discoverable ones. Use it when you want
tight, predictable behaviour.
So the division of labour is: **author** skills and packs here; **pin** them onto an agent over
in [Capabilities](/academy/a3).
> **Coming soon / by design.** Sharing skills *across projects* (and importing skills others
> have published) is the job of the **Skills Hub** — covered in
> [Hubs & solutions](/academy/v4). Within a single project, everything on this page works today.
## Try it yourself
1. Go to `Studio ▸ Agent Builder ▸ Skills`. On the **Skills** tab, click **+ Skill**.
2. On the **Form** tab, set **Name** to `summarise-document` and **Description** to
*"Summarise a document into 3 bullet points; use when the user asks for a quick summary."*
Add a **Tag** like `summary`.
3. Switch to the **Markdown** tab and write a short body, e.g.: *"Read the supplied document.
Produce exactly three bullet points capturing the key facts. Keep each bullet under 20 words.
If the document is empty, say so."*
4. Click **Create**. Note the new **V1** chip on its row.
5. Switch to the **Skill Packs** tab → **+ Skill Pack**. Name it `Quick-Reads`, give it a
description, then use **+ Add skill** to add `summarise-document`. Save.
6. Open any agent, go to its **Capabilities** tab, and **+ Pin pack** → `Quick-Reads`. The pack
card shows **"Pack · 1 skill"**. Your skill is now live on that agent.
You've authored a reusable capability once and handed it to an agent — and you can hand the same
pack to ten more agents without rewriting a word.
## Where to go next
- [MCP servers](/academy/a7) — connect external tool servers an agent can call.
- [Your first agent](/academy/a3) — the **Capabilities** tab where you pin what you built here.
- [Hubs & solutions](/academy/v4) — share skills and whole solutions across projects.
- [Tools & functions](/academy/a5) — the single-callable layer skills build on.
---
## A7 · MCP servers
URL: https://www.botminds.ai/academy/a7
> Botminds Academy — Platform · Agents
# MCP servers
> **In one line.** Register an external **MCP server** so your agents can use the tools it exposes, and curate exactly which of those tools they are allowed to call.
> **You'll be able to.** Add an MCP server, discover its tools, filter the list down to the ones you want, and attach it to an agent.
> **Where this lives.** `Studio ▸ Agent Builder ▸ MCP Servers` (`/studio/.../agent_builder/mcp_servers`).
## Why it matters
A custom API tool ([A5 · Tools & functions](/academy/a5)) plugs in **one** function — you register its URL and input schema by hand, one tool at a time. An **MCP server** plugs in a whole *set* of tools at once.
**MCP** (Model-Context-Protocol) is an open standard for tool servers. Plenty of off-the-shelf servers already exist — for GitHub, Jira, a filesystem, a web-search provider, an internal service your team wrote. Each one exposes a menu of tools over a standard protocol. Register the server once and the platform asks it what tools it has (this is *tool discovery*), then lets you pick which of them your agents may use. You don't hand-write a schema per tool — the server describes them for you.
This page is about agents *consuming* MCP servers as capabilities. The flip side — external tools driving Botminds over MCP — lives at [V2](/academy/v2).
When to use which:
| | **Custom API tool** ([A5](/academy/a5)) | **MCP server** (this page) |
|---|---|---|
| You have… | one HTTP endpoint you control | an existing MCP-speaking server, often third-party |
| You register… | one tool, schema by hand | a server; its tools are auto-discovered |
| Number of tools | one per registration | many, from one registration — filter to taste |
| Reach for it when | a single bespoke call | a ready-made toolset (GitHub, search, files, a partner) |
> **Under the hood.** When you connect, the platform calls the server's `list_tools` to enumerate its tools. Today that discovery is **eager** — it happens on connect and can take several seconds per server (roughly ~20 s for a slow one), which is why the page makes you click **Load Tools** explicitly rather than probing every server automatically. A lazy, cached discovery is in design but not what ships today; plan for a short pause when you load a server's tools.
## The MCP Servers page
```
┌──────────────────── Studio ▸ Agent Builder ▸ MCP Servers ────────────────────┐
│ ┌─ Servers (L2) ──────────┐ │ ┌─ Detail (right pane) ─────────────────────┐ │
│ │ GitHub MCP ● ────┼─┼─│ ● GitHub MCP [HTTP+SSE] [From Environ.] │ │
│ │ Web Search ○ │ │ │ ⋮ menu │ │
│ │ Filesystem ● │ │ │ Tools (3 of 9 enabled) [Save filter]│ │
│ │ │ │ │ ┌────────────────────────────────────────┐│ │
│ │ │ │ │ │ [x] search_issues Find issues by query ││ │
│ │ │ │ │ │ [x] create_issue Open a new issue ││ │
│ │ │ │ │ │ [ ] delete_repo Delete a repository ││ │
│ │ │ │ │ │ [x] get_file Read a file's content││ │
│ │ │ │ │ └────────────────────────────────────────┘│ │
│ │ [ Add MCP Server ] │ │ │ [ Load Tools ] │ │
│ └──────────────────────────┘ │ └────────────────────────────────────────────┘ │
└───────────────────────────────────────────────────────────────────────────────┘
● = active ○ = inactive (status dot)
```
- **Left (L2 list)** — every MCP server registered for this project, with a **status dot** (filled ● = active, hollow ○ = inactive). The footer **Add MCP Server** button opens the registration dialog.
- **Right (detail pane)** — the selected server. Its header carries the **status dot**, the **name**, a **transport badge** (e.g. `HTTP+SSE`), and a **scope badge**. The **⋮** action menu holds **Edit** and **Delete**.
- **Tools section** — the heart of the page: a **Load Tools** button, then a checklist of the server's discovered tools (each a checkbox + name + description), an **"n of m enabled"** counter that updates live, and a **Save filter** button that appears when you've changed the selection.
### What every control does
| Control | What it does | Notes |
|---|---|---|
| **Status dot** (●/○) | Shows whether the server is marked **Active** | Set in the Add/Edit dialog's **Active** toggle |
| **Transport badge** | The protocol used to reach the server | `HTTP+SSE`, `Stdio`, or `WebSocket` |
| **Scope badge** | Where this server comes from | **Managed by platform** / **From Environment** / **From Subscription** — see below |
| **⋮ → Edit / Delete** | Edit settings or remove the server | **Disabled** for platform-/environment-/subscription-scoped servers (hover for the reason) |
| **Load Tools** | Connects to the server and discovers its tools via `list_tools` | The deliberate pause from the under-the-hood note happens here |
| **Tool checkbox** | Include this tool in the agent-visible set | Empty selection means **all tools** are exposed (see the walkthrough) |
| **Save filter** | Persists your tool selection | Appears only when the selection is dirty and the server isn't locked by scope |
> **Scope, and why some servers are read-only.** A server can be defined at a level above your project — **Managed by platform**, **From Environment**, or **From Subscription**. You can *use* those servers and pick their tools, but you can't **Edit** or **Delete** them (the menu items are disabled with a tooltip explaining why). Only servers you registered at the project level are fully editable.
### The tool states you'll see
When you click **Load Tools**, the section shows one of:
- **Loading** — discovery in progress (the pause).
- **Connection error** — the server couldn't be reached or rejected your credentials. Re-check the URL/command and auth in **Edit**.
- **No tools** — connected, but the server advertises nothing.
- **Idle** — before you've loaded, it reads *"Click Load Tools…"*.
- **Loaded** — the checklist, ready to filter.
### Walkthrough — register a server and expose two of its tools
1. Open `Studio ▸ Agent Builder ▸ MCP Servers`.
2. Click **Add MCP Server** (footer). The Add dialog opens (next section). Fill it in and **Save**.
3. Back on the page, select your new server in the left list.
4. Click **Load Tools**. Wait out the discovery pause; the tool checklist appears.
5. The counter reads, say, **"0 of 9 enabled"**. Tick the two tools you actually want — e.g. `search_issues` and `get_file`. The counter updates to **"2 of 9 enabled"**.
6. Click **Save filter**. Your agents that use this server will now see *only* those two tools.
> **Tip — empty filter means everything.** If you leave **every** box unchecked and don't filter, the server exposes **all** its tools. Filtering is opt-*in* to a subset — so always tick the few you want and **Save filter** rather than relying on "I unchecked the rest".
> **Watch out.** A discovered tool might be destructive (`delete_repo`, `drop_table`). The filter is your safety gate — leave dangerous tools **unchecked**. Then layer an approval on the agent side ([Guard rails and governance, A8](/academy/a8)) for anything that writes.
## The Add / Edit dialog
The registration form, field by field:
| Field | What it does | Notes |
|---|---|---|
| **Name** | Display name in the list and on the agent's card | Required |
| **Description** | Free-text note on what the server is for | Optional |
| **Transport Type** | How the platform reaches the server | One of **HTTP+SSE** / **Stdio** / **WebSocket**. Drives which connection field shows next |
| **Server URL** | The server's endpoint URL | Shown for **HTTP+SSE** and **WebSocket** transports |
| **Stdio Command** | The command line that launches a local server process | Shown for **Stdio** transport (e.g. an `npx …` launcher) |
| **Auth Type** | How to authenticate to the server | **None** / **Bearer Token** / **API Key** — drives the credential fields below |
| **Bearer Token** | The bearer secret | Shown when Auth = **Bearer Token**; masked |
| **Header name + value** | A custom auth header and its secret | Shown when Auth = **API Key**; value masked |
| **Active** | Whether the server is enabled (drives the status dot) | Toggle |
| **Test Connection** | *(Edit mode only)* Connect now and report the result | Shows **Connected — N tools** with tool chips, or the error |
| **Cancel / Save** (or **Update**) | Discard / persist | Save is disabled while the form is invalid or saving |
> **Tip.** In **Edit** mode, run **Test Connection** before you save — it confirms the URL and credentials work *and* previews the tool count, so you're not loading a dead server later.
## Attaching an MCP server to an agent
You don't run tools from this page — you make the server *available*, then wire it onto an agent. In the **Agent editor**, open the **Capabilities** tab (recap in [A3 · Your first agent](/academy/a3)):
1. Find the **MCP servers** section on the **Capabilities** tab.
2. Click **+ Add MCP server**. The menu lists your registered servers, each tagged with its **scope badge** (so you can tell a project server from a platform/environment one).
3. Pick the server. It appears as a card showing its status dot, URL/command, and transport.
4. **Save Agent.**
The agent now sees the tools you filtered to on the MCP Servers page — no more, no less. That filter is the contract between "what the server *can* do" and "what *this* platform exposes".
> **Coming soon / by design — publishing.** When you package an agent into a Hub solution ([V4](/academy/v4)), its MCP servers travel as a **DECLARE**: the *requirement* ("this agent needs a GitHub MCP server") ships, but the **endpoint and credentials never do**. Whoever installs the package supplies their own server and secrets. Treat MCP credentials as environment-local — they stay put.
## Try it yourself
Wire a real MCP server onto an agent end-to-end:
1. `Studio ▸ Agent Builder ▸ MCP Servers` → **Add MCP Server**.
2. **Name** it (e.g. "Web Search"), choose a **Transport Type**, fill the **Server URL** (or **Stdio Command**), set **Auth Type** + credentials if the server needs them, leave **Active** on, **Save**.
3. *(Optional, edit mode)* **Test Connection** — confirm **Connected — N tools**.
4. Select the server → **Load Tools** → tick **two** tools → **Save filter**. Confirm the counter reads **"2 of N enabled"**.
5. Open an agent → **Capabilities** tab → **MCP servers** → **+ Add MCP server** → pick it → **Save Agent**.
6. In the agent's **Playground**, ask something that needs one of those two tools and watch the tool call fire. Confirm the *other* (unticked) tools never appear.
## Recap
- An **MCP server** plugs a *whole set* of external tools into your agents over a standard protocol — reach for it over a custom API tool ([A5](/academy/a5)) when a ready-made toolset exists.
- Register one with **Add MCP Server**: **Name**, **Transport Type** (**HTTP+SSE / Stdio / WebSocket**), the matching **Server URL** *or* **Stdio Command**, **Auth Type** (**None / Bearer / API Key**) + credentials, and **Active**.
- **Load Tools** discovers the server's tools (an eager `list_tools` — expect a short pause). Tick the ones you want, **Save filter**; an empty filter exposes **all** tools.
- **Scope badges** (Managed by platform / From Environment / From Subscription) mark servers you can use but not edit/delete.
- Attach a server on the agent's **Capabilities** tab. On publish, MCP travels as a **DECLARE** — the endpoint and credentials **never** ship.
## Where to go next
- [Guard rails](/academy/a8) — constrain *what an agent does* with the tools you've just given it.
- [Tools & functions](/academy/a5) — the single-endpoint alternative, for when you don't have a whole MCP server.
- [Botminds as an MCP server](/academy/v2) — the flip side: external tools driving Botminds over MCP.
- [Hubs & solutions](/academy/v4) — how MCP servers (and their missing credentials) behave when you package and ship a solution.
---
## A8 · Guard rails
URL: https://www.botminds.ai/academy/a8
> Botminds Academy — Platform · Agents
# Guard rails
> **In one line.** A guard rail is a named, reusable policy — a short piece of instruction text — you author once in Studio and attach to any agent to keep it on-topic and safe.
> **You'll be able to.** Create a reusable guard rail, attach it to an agent's **Governance** tab, and reason about what it does (and doesn't) enforce.
> **Where this lives.** `Studio ▸ Agent Builder ▸ Guard Rails` (`/studio/.../agent_builder/guard_rail`). You attach them from any agent's **Governance** tab.
## Why it matters
An agent you ship to end-users will be asked things you never anticipated — off-topic questions, attempts to make it say something unsafe, requests that should produce a particular shape of answer. **Governance** is how you keep a configured agent inside the lines without rewriting its instructions every time.
A **guard rail** is the platform's reusable unit of governance: a **named policy** — a short piece of instruction text — that you author once and attach to as many agents as you like. "Stay strictly on the subject of company HR policy." "Never reveal internal pricing." "Always answer in formal British English." Each is a guard rail you write once and reuse.
Authoring them in one place (the Guard Rails page) instead of burying them in each agent's persona has three payoffs: **reuse** (one rule, many agents), **consistency** (every agent enforces the same wording), and **auditability** (a reviewer can read your governance policies as a list, not hunt through prompts). The wider policy side of governance — beyond per-agent rules — is covered in [G3](/academy/g3).
> **Under the hood.** A guard rail is stored as the `GuardRail` entity; at agent-build time the orchestrator resolves each attached guard rail's instruction text and **appends it to the agent's instructions**, then adds one "apply all guardrail rules to the final answer" instruction on top. See "How a guard rail runs" below — this detail matters for setting expectations.
## The Guard Rails page
`Studio ▸ Agent Builder ▸ Guard Rails` is the standard Agent Builder two-pane shell: a list of your guard rails on the left, a read-only detail panel on the right, and a dialog for create/edit.
```
┌ Guard Rails ─────────[ sort ⇅ ][ search ]┐┌ ──────[ ⋮ ]┐
│ ││ │
│ ● On-Topic: HR Only ││ Name │
│ Keep the agent answering only HR… ││ On-Topic: HR Only │
│ [Private] ← debug mode only ││ │
│ ││ Description │
│ No Internal Pricing ││ Keep the agent answering only HR… │
│ Never disclose internal price lists ││ │
│ ││ Access Level ← debug mode only │
│ Formal Tone ││ Private │
│ Always answer in formal British… ││ │
│ ││ Instructions │
│ … (Load More appears at ≥1000 rules) ││ You answer ONLY questions about the │
│ ││ company HR handbook. If asked about │
│ [ + Guard Rail ] ││ anything else, politely decline. │
└──────────────────────────────────────────┘└────────────────────────────────────────┘
```
- **Left — list.** Each row shows the guard rail's **name** and **description** (clamped). In **debug mode** only, a **Private** / **Public** access chip appears. The header carries a **sort toggle** (date ⇄ A-Z) and a **search** icon that reveals a search field (filters on name + description). A **+ Guard Rail** button sits in the footer; a **Load More** button appears only past 1000 rules.
- **Right — detail panel.** A read-only projection of the selected guard rail: **Name**, **Description**, **Access Level** (debug only), and **Instructions** (the policy text, shown pre-wrapped). Its header carries the **⋮ action menu**.
- **Empty state.** With no rules, the list shows "No Guard Rails found in the project" and (if you have permission) an inline **+ Guard Rail** button. A search with no hits shows "No Guard Rails found matching your search."
### What every control does
| Control | What it does | Notes |
|---|---|---|
| **Sort toggle** (⇅) | Switches the list between newest-first and A→Z. | Pure view state. |
| **Search** | Reveals a field; filters the list by name or description. | Close [x] clears it. |
| **+ Guard Rail** (footer / empty-state) | Opens the create dialog. | Needs the `Add Guard Rail` permission, or it's hidden. |
| **⋮ action menu** | Per-rule actions on the selected guard rail. | See next table. |
### The ⋮ action menu (on the selected rule)
| Action | What it does | Notes |
|---|---|---|
| **Publish** | Pushes this guard rail to the **Guard Rails Hub** to share/install elsewhere. | See [Hubs & solutions](/academy/v4). |
| **Edit** | Reopens the dialog in edit mode. | Needs the `Edit Guard Rail` permission. |
| **Delete** (red) | Confirms, then removes the guard rail. | Needs the `Delete Guard Rail` permission. Detaching from agents is your job — see "Behaviours to know". |
### The create / edit dialog
Click **+ Guard Rail** (or **Edit**) to open the dialog. It is short — a guard rail is just a named instruction — and every field is below.
| Field | Required | What it does | Notes |
|---|---|---|---|
| **Name** | Yes | The label you'll pick from on an agent's Governance tab. | Make it action-describing: "On-Topic: HR Only". |
| **Description** | Yes | A one-line summary for the list and detail panel. | **Max 200 characters.** |
| **Access Level** | — | Shows **Private** (project-only) vs **Public** (library) scope. | **Read-only**, and only visible in **debug mode** when editing. New guard rails default to **Private**. |
| **Instruction** | Yes | **The policy itself** — the natural-language rule the agent must follow. This is the whole point of the object. | Expandable textarea. Supports the **global-variable placeholder menu** — insert `{{scope.X}}` tokens to reference project variables. |
| **Cancel** / **Save** \| **Update** | — | Discards / persists. | **Save** is disabled while the form is invalid or saving. Label is **Save** when creating, **Update** when editing. There is no autosave. |
> **Tip — write the instruction as a direct order to the agent.** It is pasted verbatim into the agent's instructions, so phrase it the way you'd phrase a persona rule: *"You answer ONLY questions about the company HR handbook. If asked about anything else, politely say you can only help with HR topics."* Be explicit about both the boundary **and** the fallback behaviour when the boundary is hit.
> **Coming soon / by design — the richer guard-rail model.** You may expect a guard rail to have a **type**, an **input-vs-output** switch, a structured **rule/condition**, or an **action-on-violation** (block / rewrite / warn). In the current build a guard rail is **only** a name + description + a single instruction. There is no input/output toggle, no condition builder, and no per-violation action selector on the screen — those are not shipped. Author guard rails as plain-language policy text today.
### Behaviours to know
- **Realtime sync.** The list reloads in place when a guard rail is created/updated/deleted elsewhere (another tab, a teammate, an automation) — no manual refresh.
- **Save is explicit.** No autosave; the dialog persists only on **Save** / **Update**, and only when valid.
- **Access Level is fixed at create.** The Private↔Public choice isn't editable in this dialog (it's a read-only display in debug mode). Treat new guard rails as **Private** to the project.
- **Deleting doesn't detach.** Removing a guard rail does not walk back through agents that referenced it — re-check those agents' Governance tabs.
## Attaching a guard rail to an agent
A guard rail does nothing until an agent references it. You wire that on the agent itself, not here.
Open `Studio ▸ Agent Builder ▸ Agents`, edit an agent, and go to the **Governance** tab (recap in [A3 · Your first agent](/academy/a3)). Its **Guard rails** section is the attach point:
1. Click **+ Add** under **Guard rails**.
2. Pick one or more of your authored guard rails from the picker.
3. Each selected rule appears as a **shield chip** with a remove (×). The empty state is a dashed placeholder.
4. **Save Agent** (footer). The attachment is part of the agent's saved config.
> **Under the hood.** On the legacy agent layout this same section is labelled **Guard Rails Configuration** on the main form; on the new builder it lives on the **Governance** tab alongside **Approvals**. Both write the same list of guard-rail references onto the agent. Adding/removing here is RBAC-gated (`Add Guard Rail In Agent` / `…In Multi Agent`).
## How a guard rail runs (briefly)
When the agent is built for a run, the orchestrator:
1. Fetches the instruction text of every guard rail attached to the agent.
2. **Appends each one to the agent's instructions**, then adds a single "apply all these rules to the final answer, return one clean result" orchestrator instruction.
3. The agent then runs its normal loop (model ⇄ tools) with those rules now part of its standing instructions.
> **Watch out — enforcement is advisory, not a hard filter.** A guard rail is **prompt-level guidance**: it strongly steers the model, but the platform does **not** independently read the model's output back and block it if a rule is broken. A capable model will respect a clear instruction; treat guard rails as governance you can rely on for *steering*, not as a guaranteed gate. For anything that *must* be blocked, layer it: a clear guard rail **plus** a human-approval step (Governance ▸ Approvals, [A3](/academy/a3)) **plus** a tightly-scoped knowledge base.
## Governance best practices
- **One rule, one concern.** A guard rail per concern (topic boundary, tone, a forbidden disclosure) reads better and reuses better than one giant rule.
- **Name for the picker.** You'll choose these by name on the Governance tab — "No Internal Pricing" beats "GR-2".
- **State the boundary *and* the fallback.** "Only answer X; if asked anything else, politely decline" — don't leave the off-path behaviour to chance.
- **Reuse across agents.** Author once; attach the same rule everywhere it applies. Edit it once and every agent inherits the change on its next run.
- **Don't rely on a guard rail to *block*.** Pair safety-critical rules with a human-approval step.
- **Keep them on-topic with knowledge scope.** A topic-boundary guard rail works best alongside a narrow Knowledge collection ([D1](/academy/d1)) so the agent has little off-topic material to draw on anyway.
## Sharing via the Hub
Built a guard rail your other projects need? The detail panel's **⋮ ▸ Publish** pushes it to the **Guard Rails Hub**, and other projects install it like any shared object — governance policy travels as reusable structure. Full publish/install workflow is in [Hubs & solutions](/academy/v4).
## Try it yourself
Add an **output topic-boundary** to an HR assistant so it stays on subject:
1. Go to `Studio ▸ Agent Builder ▸ Guard Rails` and click **+ Guard Rail**.
2. **Name:** `On-Topic: HR Only`.
3. **Description:** `Keep the agent answering only HR-handbook questions.` (≤200 chars.)
4. **Instruction:**
> You answer ONLY questions about the company HR handbook (leave, benefits, conduct, payroll policy). If the user asks about anything else — coding, news, general trivia, other departments — politely reply that you can only help with HR topics and invite an HR question.
5. **Save.** Confirm it shows in the list and that its detail panel renders your instruction.
6. Go to `Agents`, edit your HR assistant, open the **Governance** tab, click **+ Add** under **Guard rails**, select **On-Topic: HR Only**, and **Save Agent**.
7. In the **Playground**, ask an off-topic question ("write me a Python script"). The agent should decline and steer you back to HR. (If it doesn't, sharpen the instruction's wording — it's prompt-level steering.)
## Recap
- A **guard rail** is a reusable, named **policy** — a single instruction — authored at `Studio ▸ Agent Builder ▸ Guard Rails` and attached to agents for governance.
- The create/edit dialog has exactly four meaningful fields: **Name** (req), **Description** (req, ≤200), **Access Level** (read-only, debug-only), and **Instruction** (req, the policy, supports `{{variables}}`).
- You **attach** guard rails on an agent's **Governance** tab (**+ Add** → shield chips); they're saved as part of the agent's config.
- At run time each rule's text is **appended to the agent's instructions** — enforcement is **advisory steering, not a hard output filter**, so pair safety-critical rules with human approval.
- Guard rails can be **published to the Hub** for reuse across projects.
- The "type / input-vs-output / condition / action-on-violation" model is **not shipped** — guard rails are plain-language policy text today.
## Where to go next
- [LLMs & services](/academy/a2) — the models that power your agents (and the services that extend them).
- [Your first agent](/academy/a3) — the Governance tab in full context, alongside Approvals.
- [Governance policies](/academy/g3) — the platform-wide policy side of governance, beyond per-agent guard rails.
- [Hubs & solutions](/academy/v4) — publish and install guard rails (and everything else) across projects.
---
## A9 · AI Builder
URL: https://www.botminds.ai/academy/a9
> Botminds Academy — Platform · Agents
# AI Builder
> **In one line.** Three Studio surfaces — **AI Models**, **Prediction Report**, and **AI Pipeline** — that let you train and improve the platform's own extraction models from the corrections your reviewers make.
> **You'll be able to.** Recognise when to train an AI Model instead of leaning on an LLM agent, trigger a training run from corrected documents, read an accuracy report to decide if a model is good enough, and chain models into a pipeline.
> **Where this lives.** `Studio ▸ AI Builder` — three sub-pages: **AI Models** (`/studio/.../ai_builder/ai_models`, the default), **Prediction Report** (`/studio/.../ai_builder/reports`), and **AI Pipeline** (`/studio/.../ai_builder/ai_pipeline`).
## Why it matters
There are two kinds of "model" on this platform, and AI Builder is about the one people forget. An **LLM** ([A2 · LLMs & services](/academy/a2)) is a general-purpose large language model you rent from a provider and prompt — it reasons from instructions and never learns from you. An **AI Model** is the platform's own trainable extractor: it starts knowing nothing about your documents and gets better every time a reviewer corrects a field. The LLM is hired talent; the AI Model is an apprentice you train on the job.
> **Watch out — the word "model" is overloaded.** Throughout this page, **AI Model** means the trainable extraction model (a training job owned by a **Learner**). It is not the LLM that powers a chat agent. When in doubt: an LLM is configured on an agent's **Model** tab; an AI Model is trained here, in AI Builder.
### The learning loop
You have met every piece of this loop in [S2 · Core concepts](/academy/s2), [E3 · Document detail](/academy/e3), and [D1 · Collections & schema](/academy/d1). AI Builder is where it closes:
```
Documents Reviewer corrects Learner
extracted by ---> fields on the ---> (owns the Labels
an agent Document Detail and the AI Model)
Training pane | train
v
Accuracy goes up <--- re-predict <--- AI MODEL (V1 -> V2 -> V3)
(Prediction Report) future docs a trained extractor
```
Read it clockwise: an agent extracts fields against the schema (the **Learner** and its **Labels/Fields**). A reviewer reads the document and corrects the wrong values in the **Training** pane — and every correction saves back to the label. Those corrected documents are the labelled examples an AI Model trains on. After training, the model predicts future documents more accurately, and a **Prediction Report** tells you by how much.
> **Under the hood.** Each correction writes a confidence-scored value into the document's labels. A training run feeds those labelled examples to the platform's extractor (the `AIModel` the **Learner** owns) and re-scores it; the result is a new **version** (V1 → V2 → V3). The LLM is never touched by any of this.
### When to train an AI Model vs. just use the LLM agent
| Reach for… | When… |
|---|---|
| **An LLM agent alone** ([A3](/academy/a3)) | You're starting out, volumes are low, document layouts vary wildly, or the field needs reasoning/judgement. The LLM is good out-of-the-box and needs no training data. |
| **A trained AI Model** | You have a **repeating, high-volume** document type (the same invoice layouts, the same form), you've already corrected dozens of them, and you want faster, cheaper, more consistent extraction that improves measurably over time. |
In practice you use both: the LLM agent gets you running on day one and generates the first corrections; once you have a corpus of corrected documents, you train an AI Model to specialise. You do not have to choose up front.
## AI Models
Browse, inspect, and train the platform's extractors — organised by Learner, with full version history. The page uses the standard Studio list + detail split: a left rail of models (grouped by the **Taxonomy / Learner** you filter to) and a right detail panel of read-only rows for the selected model. Each list row shows the model name, a **version chip** (V1/V2…), a relative time, and a **status icon** whose tooltip tells you the last training result — succeeded, failed, or still running. When training succeeded, the detail panel shows a **Metrics** row; a failed run surfaces the failure reason in the tooltip.
### What every control does
| Control | What it does | Notes |
|---|---|---|
| **Taxonomy filter** (header dropdown) | Scopes the list to one **Learner** (or "All Taxonomy"). | Every model belongs to a Learner. |
| **Refresh** | Re-fetches the list. | Use after a training run finishes. |
| **Model row** | One trained extractor: name + version chip + relative time + status icon. | Developers also see a Sherlock/debug link. |
| **N Past Versions** (expander) | Lists prior versions of a multi-version model; each is selectable to inspect. | Versioning is how the learning loop is recorded over time. |
| **+ Model** | Opens the training form (`initiateTrainingForm`) — start a new training run from the corrected/labelled documents. | The main way to train. Permission-gated. |
| **Upload** | Imports an offline / externally-trained model instead of training one here. | For models trained elsewhere. |
| **Load more** | Pages in more models (server-side lazy load). | |
| **⋮ menu** | **Create Taxonomy out of this model** (when training succeeded) · **Push model to children** (when the model is exported). | Version/manage actions live here. |
The detail panel has many conditional rows — only those relevant to the selected model show. The ones you'll read most often:
| Detail row | Tells you |
|---|---|
| **Model Name** (+ version) | Which model and which version you're inspecting. |
| **Type** (chips) | What it does: **Classification**, **Extraction**, **Numerical**, plus modifiers like *Rich Text Included*, *Dataset only*, *Imported Model*. |
| **Labels Included** / **Mapped Label Names** | Which **Fields** this model predicts, and how they map to its internal names. |
| **Predicted Segments / Stages** | Where in the document and lifecycle it operates. |
| **Neutrals / Keywords for Neutrals** | Negative/neutral examples used to sharpen the model. |
| **Children Included** | Child bots rolled into this model (accordion). |
| **Metrics** | Accuracy figures — shown only when the last training succeeded. |
> **Under the hood.** The remaining rows (Bulk Label Rules drive-url, Parent logs, Rule-based Model Rules, Widget Input/Primary/Output columns) are for advanced / rule-based models. You can safely ignore them while learning; they appear only when a model actually uses them.
### Walkthrough — train a model from corrected documents
This ties straight back to the review-and-correct loop in [E3 · Document detail](/academy/e3).
1. **First, produce training data.** In the consumer app, open several documents and use the **Training Mode** toggle on the Document Detail page to correct the extracted fields. Each correction saves back to its **Label** — that's a labelled example. Do at least a handful; more corrected documents make a better model.
2. In Studio, go to `Studio ▸ AI Builder ▸ AI Models`.
3. Set the **Taxonomy** dropdown to the **Learner** whose Fields you've been correcting (the same Learner your collection's schema uses).
4. Click **+ Model**. The training form opens.
5. Give the run a **name** and confirm the **Labels** to include and the model **Type** (Extraction for field-pulling; Classification for routing; Numerical for numbers).
6. Start the run. The new model appears in the list with a "training…" status icon; the tooltip reports progress, then success or failure. Hit **Refresh** to update.
7. When it succeeds, select it — the detail panel now shows a **Metrics** row. To judge whether it's actually good enough, go to the **Prediction Report** page (next section).
### Behaviours to know
- **Empty state.** With no models yet you see *"You haven't created any AI Model to preview"* plus **+ Model** and **Upload**. Training data must exist first — a model with nothing to learn from won't help.
- **Versions are immutable history.** Re-training doesn't overwrite V1; it creates V2. You can always inspect or roll back to an earlier version via **N Past Versions**.
- **Permission-gated.** **+ Model** and the **⋮** actions only appear if your role allows them.
## Prediction Report
A model's **Metrics** row gives you a quick read, but a **Prediction Report** is the real verdict: it compares a **prediction project** (documents the model predicted) against a **reference project** (documents with known-correct answers) and scores them field by field. Selecting a report in the left list renders it on the right: an overall accuracy figure, then a table of **accuracy and precision per Field/Label** — so you can see which fields the model nails and which it struggles with. A `due_date` lagging at 71% tells you exactly where to send more corrected examples.
### The Add Report form
Click **+ Report** (permission `ai_builder/Add Report`) to open the form. Alongside a **Name**, a **Report Type** dropdown, and **Save**, cover these:
| Field | What it does |
|---|---|
| **Prediction Project URL** | The project whose **predicted** documents you're scoring. |
| **Reference Project URL** | The project holding the **known-correct** ("ground truth") answers to compare against. |
| **Comparison Type** (dropdown) | How values are matched (the classification-type comparison mode). |
| **Case Sensitive** (toggle) | Whether `Acme` and `acme` count as a match. Off for most text fields. |
| **Ignore special characters** (toggle) | Strips punctuation/symbols before comparing — useful for IDs and amounts. |
| **Label selection** | Pick exactly which **Fields** to score; selected fields show as chips. Leave broad to score everything, or narrow to the few fields you care about. |
### How to read it — is the model good enough?
1. **Look at overall accuracy first** for a gut check, then ignore it — averages hide problems.
2. **Scan the per-field rows.** A model can be 92% overall yet useless on the one field that matters. Sort your attention by business importance, not by the average.
3. **Accuracy vs. precision.** *Accuracy* = how often the field is right overall. *Precision* = when the model does answer, how often it's correct. A field with high precision but low accuracy is cautious (misses some, but trustworthy when it speaks); low precision means it guesses wrong — more dangerous, because a reviewer must catch it.
4. **Decide the threshold per field.** For a field that auto-advances a document, you want it high. For a field a human always eyeballs anyway, lower is fine.
5. **If a field is weak, feed it more corrected examples**, re-train (a new version), and run the report again. That iteration is the job.
> **Tip.** Keep a small, stable reference project of correctly-answered documents as your "exam". Re-pointing each new model version's report at the *same* reference makes versions directly comparable — you can see V3 beat V2 on the exact same documents.
> **Watch out.** A high score on documents the model trained on means nothing — that's just memorising. Always score against a reference set the model has not seen to get an honest number.
## AI Pipeline
Sometimes one model isn't enough: you might **classify** a document first (which form is this?), then run the **extraction** model that matches that class, then a **numerical** model on the amounts. An **AI Pipeline** chains models into that ordered sequence so the platform runs them as one unit. The left rail lists your pipelines; selecting one shows the ordered **chain-model-list** on the left half and the details of whichever chained model you click on the right. An L3 action menu (top-right) manages the selected pipeline.
| Control | What it does |
|---|---|
| **Add models to AI Pipeline** | The primary action (`addChainerModel`) on an empty pipeline — opens the dialog to add the first model. |
| **add-chain-model** dialog | Adds an existing **AI Model** as the next step in the chain. |
| **add-model-pipeline** dialog | Adds an entire **pipeline** as a step — i.e. chain pipelines inside pipelines for reuse. |
| **update-version** | Bumps a chained model to a newer trained version without rebuilding the chain. |
| **View Chainer JSON** (toggle) | Swaps the right pane for the raw chainer definition (`chainer-json`) — the advanced/exact view of the chain order and config. |
> **Under the hood.** A pipeline you build here is also available as the **AI Pipeline** stage node inside the [XFlow editor](/academy/a10) — that's how a chained extractor gets wired into a collection's processing pipeline.
> **By design.** Treat AI Pipeline as the advanced surface. Most solutions get all the accuracy they need from a single well-trained model. Reach for chaining only when a real classify-then-extract problem demands it; don't build a pipeline just because you can.
## How this connects to an agent's Output tab
This closes the circle back to [A3 · Your first agent](/academy/a3). An agent extracts data by pointing its **Output** tab (the **Structured output** mode) at a **Taxonomy / Learner** — the schema whose **Fields** to fill. That same Learner is what owns the **AI Model** you train here. The two surfaces are two ends of one pipe:
- The agent's **Output** tab decides *which Fields* get extracted and routes low-confidence ones to human review.
- **AI Builder** improves *how accurately* those Fields get filled, by training on the corrections reviewers make.
You don't re-wire the agent when you train a model — the agent already targets the Learner, and a better-trained Learner simply produces better extractions on the next document. The agent stays the same; its apprentice just gets smarter.
## Try it yourself
Review the accuracy of a model after correcting a few documents — the whole loop in miniature:
1. Pick a Processing collection you've used before (e.g. the **Invoice Extractor** from [A3](/academy/a3)). Open 5–10 documents in the consumer app and use **Training Mode** to correct the extracted fields. Aim to fix at least a couple of `due_date` or `total` values.
2. Go to `Studio ▸ AI Builder ▸ AI Models`. Set the **Taxonomy** filter to that collection's **Learner**.
3. Click **+ Model**, name the run, confirm the **Labels** and **Type: Extraction**, and start it. **Refresh** until the status icon shows success.
4. Switch to **Prediction Report**. Click **+ Report**, name it, set the **Prediction** and **Reference Project URLs**, pick your **Fields** in **Label selection**, and **Save**.
5. Read the per-field table. Which field is weakest? That's your next batch of corrections. Correct a few more documents, train a **V2**, and run the same report again — watch the number move.
If the weak field improved after more corrections, you've felt the learning loop work end-to-end. That's the entire point of AI Builder.
## Where to go next
- [A11 · Teams & mesh](/academy/a11) — wire several runnables into durable multi-stage automations.
- [E3 · Document detail](/academy/e3) — master the Training-Mode correction surface that feeds everything here.
- [A10 · XFlows & pipelines](/academy/a10) — the **AI Pipeline** stage node that drops a chained model into a collection's processing pipeline.
- [Glossary](/academy/r0) — **AI Model**, **Learner**, **Taxonomy**, **Label/Field**.
---
## D1 · Collections & schema
URL: https://www.botminds.ai/academy/d1
> Botminds Academy — Platform · Data
# Collections & schema
> **In one line.** What a Collection is in practice, how to create one, and how to give it a **schema** — the fields the platform will extract from every document.
> **You'll be able to.** Create a Processing collection from scratch and define its fields, ready for documents to flow in.
> **Where this lives.** `Studio ▸ Data Model ▸ Collections`
## Why it matters
A **Collection** is the operational home for **one type of record** — "Vendor Invoices", "HR Policies", "Support Tickets". Everything downstream hangs off it: documents land *in* a collection, an agent *works* it, your end-users *read* it. And before any of that, you give it a **schema** — the list of fields the platform pulls out of each document. The schema is the single most important thing you author here, because **the schema drives extraction**: the platform's extraction agents read your field list to know *what to pull out*. No field, no extracted value.
> **Vocabulary.** The UI says **Collection**; the API/URL still say `Entity` / `RelationalEntity` / `EntityId`. A **Learner** (a.k.a. **Taxonomy** / **Data Capture** group) is the trainable extractor that owns a group of fields. A **Label** is one field (the UI shows it as a **Field**). A **Schema** = "a Learner plus its Labels" — not a separate object. Keep the [Glossary](/academy/r0) open.
Every collection sits on two independent axes:
- **Category — *why it exists*:** **Processing** (decide on each document — review stages, field extraction, an agent acts on each one) or **Knowledge** (a passive corpus, auto-indexed so agents can read and cite it). The categories have a dedicated page: [Collection types](/academy/d2).
- **Kind — *who works it*:** **Agent** (an AI agent processes it) or **Human** (a person's work queue, like the Inbox).
> **Status.** The explicit **Knowledge** category, its auto-vectorise-on-ingest behaviour, and the **Index Health** tab are shipped release features behind the `knowledgeCollections` flag (default **on**; environments can switch it off as a kill-switch, which hides every Knowledge surface). **Processing** collections need no flag — that is what the walkthrough below builds.
## The Collections workspace
**Menu path:** `Studio ▸ Data Model ▸ Collections`.
This is a **master-detail** surface: a list of every collection on the left, and a detail pane on the right that shows the selected collection's seven (or eight) tabs.
- **Left rail** lists collections by name. **Parent/child** collections are shown as indented nesting (a child sits under its parent, with a coloured left border by depth). A star marks the **Primary/Default** collection — the project's default ingestion target. Click a row to load it on the right.
- **Right pane** shows the selected collection's name, a row-action menu, and the **tab strip**.
### What every control does
| Control | What it does | Notes |
|---|---|---|
| **+ Collection** (rail footer) | Opens the **Create Collection** modal | Always present, even when the list is empty. Backend still enforces create permission. |
| Row **⋮ ▸ Edit** | Re-opens the collection in the editor | Hidden when the `collectionsUnified` flag is on — there the **General** tab *is* the editor. |
| Row **⋮ ▸ Delete** | Deletes the collection (confirm) | Flag `collectionWorkbench`. Warns by name if the collection has **child collections**. |
| **+ Taxonomy** (pane header) | Opens **Create Taxonomy** scoped to the selected collection | A shortcut to add a Learner without opening the Schema tab first. |
| Empty state | "No Collection found in the project" + **+ Collection** | Shown before you create your first. |
> **Tip — deep-links.** A consumer "Edit in Studio" link arrives as `…?selectedEntityId=` and pre-selects that collection for you. You don't need to hunt for it in the list.
> **Flag-gated layout.** With `collectionWorkbench` **on**, the right pane is the tabbed workbench described below. With it **off**, you get a flat, read-only details panel instead (EntityName, Description, copyable EntityId, created/updated by + date, an IsPrimary toggle, and Independent-Queue status). This page teaches the tabbed workbench.
### The right-pane tabs — what each one is and where it's covered
The detail pane embeds seven tabs (eight for Knowledge collections). Each non-General tab is the **exact same page** you can also reach as a standalone `model_data/*` route — here they're just mounted inline.
| Tab | What it's for | Covered in |
|---|---|---|
| **General** | The collection's settings — *this is also the create/edit form* | This page, below |
| **Schema** | Define the fields to extract (Learners + Labels) | **This page** |
| **Lifecycle** | The review **stages** documents move through | [Taxonomy, lifecycle, tags & events](/academy/d3) |
| **Tags** | The project's free-form tag set applied to records | [Taxonomy, lifecycle, tags & events](/academy/d3) |
| **Events** | Webhooks / emails / Slack fired on document or stage events | [Taxonomy, lifecycle, tags & events](/academy/d3) |
| **Ingestion** | Where this collection's documents come from | [Ingestion & connectors](/academy/d4) |
| **Agents** | Assign the **Worker** (Intake Agent) and watch it run | [Your first agent](/academy/a3) |
| **Index Health** | Vectorisation health, per-cause failure groups, retries and reindex — **Knowledge collections only** | [Search, indexes & vectorization](/academy/d6) |
> **Two agent-collection relationships.** A **Worker** (the *Intake Agent*) runs on each document — you set it on the **Agents** tab. A **Reader** searches the collection's index — you set that on the *Knowledge* tab in Agent Builder, not here. Don't confuse the two.
## Creating a collection — the General tab
Click **+ Collection** (or open the **General** tab of an existing one). The same form serves as both **Create** and **Edit**, and as the inline General tab. **Save** is disabled while the form is invalid; in modal mode a **Close** button appears.
You only need **four** decisions to get a working Processing collection — the rest are optional accordions with sensible defaults.
### The key settings groups (summary)
| Group | What you set | Required? |
|---|---|---|
| **Purpose** | The collection **category** — **Processing**, **Knowledge**, or **Structured** (see [Collection types](/academy/d2); picker behind flag `knowledgeCollections`). **Immutable after create** (shown as a read-only chip on edit). | Pick one |
| **Knowledge settings** | **Search model** (the embedding model — **required**; the first available model is preselected on create and Save is blocked without one), chunk size (default **2000**), chunk overlap (default **10**). An **Advanced ingestion settings** foldout adds **Index location** (Shared vs Project index), page/document summaries, and OCR for scans. Expanded by default on create. Only when Purpose = Knowledge. | Pick the Search model |
| **Collection Name** | The display name | Yes |
| **Description** | What it holds | Yes |
| **Allowed Ingestion Types** | Whitelist which source types may feed this collection (Upload, Cloud, connectors, Form Templates) | Optional |
| **Default View** | A starting column view (only if any exist) | Optional |
| **Parent Collection** | Make this a **child** of another collection — reveals label-mapping accordions. **Disabled once set** (no re-parenting). | Optional |
| **Enrich / Dashboards / Independent Queue** | Advanced accordions (enrich-xflow triggers, per-collection dashboards, dedicated queue) | Optional |
| **Set as Primary** | Make this the project's default ingestion target (exactly one per project) | Optional |
The **full field-by-field table** — every accordion, every child-mapping row, every default — is in the [Schema field reference](/academy/r3).
> **Watch out — Category is permanent.** You choose **Processing** or **Knowledge** *once*, at create time. After that it shows as a read-only chip and **cannot be changed**. Pick deliberately.
> **Under the hood — where intake assignment lives.** There used to be an "Assign to" / Intake-Agent picker on this form. It was **removed** — you now pick the working agent on the **Agents** tab ([Your first agent](/academy/a3)). So the create form defines *the shape and the rules*; the **Agents** tab assigns *the worker*.
## The Schema tab — defining what to extract
This is the heart of the page. **Menu path:** select a collection, then **Schema** (or standalone `model_data/taxonomy`).
### How schema drives extraction
When a document arrives, the platform's extraction agents look at the collection's schema and extract a value for **each Label**. A Label called `invoice_total` (with a currency validation) tells the agent "find the total and pull it out as money." Remove the Label and that value is simply never captured. So authoring the schema *is* authoring the extraction. (For a child collection, a parent's extracted Labels can auto-derive the child's records via label mapping — see [Taxonomy, lifecycle, tags & events](/academy/d3).)
A schema is a small tree:
- **Learner** (a.k.a. Taxonomy / Data Capture) — the trainable extractor on the collection
- **Label** (UI: "Field") — one extractable value: a name plus behaviour
- **child Label** — a column, when the parent Label is a table/record
### Layout — master-detail
```
┌──────────────────────────────┐ ┌──────────────────────────────────────────────┐
│ Taxonomy [type ▾] [search] │ │ Invoice Header [+ Label] [⋮ Edit] │
│ ──────────────────────────── │ │ Labels | Details │
│ * Invoice Header (primary) │ │ ───────── │
│ Invoice Line Items │ │ invoice_number text │
│ │ │ invoice_date date │
│ │ │ total_amount currency │
│ ────────────────────────── │ │ line_items ▸ table (3 child fields) │
│ [ Taxonomy ] [ Import ] │ │ │
└──────────────────────────────┘ └──────────────────────────────────────────────┘
```
- **Left list** — every **Learner** (Name + Description); a star marks the **Primary** Learner. A **type filter** (`All · Custom · Default · Imported`) and a **search** icon narrow the list.
- **Footer** — **Taxonomy** (create a new Learner) and **Import** (import a Learner). Empty state: "No Taxonomies found. Create new Taxonomy."
- **Right pane** (a Learner selected) — **+ Label** (top-right, on the **Labels** sub-tab) and an action menu with **Edit** (edit the Learner). Two sub-tabs: **Labels** (a hierarchical field tree) and **Details** (the Learner's metadata).
| Control | What it does |
|---|---|
| **Taxonomy** (footer) | Opens **Create Taxonomy** — defines a new Learner (the field group) |
| **Import** (footer) | Imports a Learner from a bottom-sheet |
| **type ▾** filter | Filters the Learner list: All / Custom / Default / Imported |
| **+ Label** | Opens the **field editor** (add a field to the selected Learner) |
| **⋮ ▸ Edit** | Edits the selected Learner |
### Adding a Learner (Create Taxonomy)
A Learner groups the fields and is the thing that can be *trained* later. To create one, click **Taxonomy** and fill:
| Field | Notes |
|---|---|
| **Taxonomy Name** (required) | Non-empty; duplicate names rejected |
| **Description** (required) | |
| **Type** (required) | What it classifies/extracts — for whole-document field extraction pick **DocumentClassification** |
| **Entity** (required) | Which collection it belongs to (pre-filled to the one you're on) |
The full list of Learner **Types** (`DocumentClassification`, `TableClassification`, `ImageAnnotation`, and more) is in the [Schema field reference](/academy/r3).
### Adding a Field (Label) — the field editor
Select a Learner, then **+ Label**. The editor has two tabs — **Add label** and **Import labels**.
- **Label Name** and **Description** are the only required inputs — and for most fields they're all you need.
- **Show Advanced Settings** reveals six accordions (summarised below).
- **Add** saves the field and keeps the dialog open (handy for entering several in a row); **Add and exit** saves and closes.
### Field types — how a Label becomes text, number, currency, date, boolean or a table
There is **no single "type" dropdown**. A field's shape comes from a combination of a **validation rule** (in *View Config*) and **Record Config**. In practice you produce these shapes:
| Shape | How you get it |
|---|---|
| **Text** | A Label with no special validation (the default) |
| **Number** | Label + a numeric validation rule (View Config ▸ Validation) |
| **Currency / amount** | Numeric validation, optionally **Enable Total Field** |
| **Date** | A date validation rule |
| **Boolean / yes-no** | A validation rule limiting to two values |
| **Single-select / enum** | A validation rule listing allowed values |
| **Table / line-items** | **Is Record** (Record Config) + child Labels as columns |
| **Masked / sensitive** | **Mask Values** toggle (Toggles) |
> **Tip.** 90% of fields are "a Label + a validation rule." The one shape that's different is a **table/line-items** field: turn on **Is Record**, then add child Labels — each child becomes a column.
The exhaustive enumeration of every shape and every validation option is in the [Schema field reference](/academy/r3).
### The six advanced accordions (summary)
You'll rarely need these for a first build — here's what each is for. The full control-by-control list is in the [Schema field reference](/academy/r3).
| Accordion | In one line |
|---|---|
| **Table Styling** | Header/body background and text colours for a table field |
| **Contextual Insights** | Real-time derivation (RTD) and aggregation widgets |
| **Record Config** | Make the field a **table** (Is Record), define columns, grouping, widths |
| **Toggles / Features** | **Mask Values**, Expand Label Values, Enrich Label |
| **Lookup Config** | Derive/refresh a value from another label or source |
| **View Config** | **Validation rules** (this is where number/date/boolean/enum live), sort, totals |
### Bulk import of fields
The **Import labels** tab takes `.txt`, `.xlsx`, `.tsv` or `.csv`. Parent/child nesting is expressed by **indentation** (text) or **columns** (spreadsheet), so you can stand up a whole table-with-columns in one go, then **Upload & Create**.
> **Tip.** For a large schema, build the field list in a spreadsheet first (one column per nesting level) and import it — far faster than clicking **+ Label** dozens of times.
### Behaviours to know
- **Required fields:** Learner Name + Description; Label Name + Description. **Save/Submit/Add** stay disabled until they're filled.
- **Duplicate names** are rejected (Learner level).
- The **Schema** tab and the standalone `model_data/taxonomy` route are the **same surface** — edits in one are edits in the collection.
## Try it yourself
Build a **Vendor Invoices** Processing collection with four fields. (~5 minutes.)
1. Go to `Studio ▸ Data Model ▸ Collections`. Click **+ Collection**.
2. **Purpose:** leave/select **Processing**. **Collection Name:** `Vendor Invoices`. **Description:** `Incoming supplier invoices for approval`. Leave everything else default. Click **Save**.
3. Your collection appears in the left rail. Select it, open the **Schema** tab.
4. Click **Taxonomy**. **Name:** `Invoice Header`, **Description:** `Top-level invoice fields`, **Type:** `DocumentClassification`, **Entity:** `Vendor Invoices`. **Submit**.
5. Select **Invoice Header**, click **+ Label**. Add these four, using **Add** between each and **Add and exit** on the last:
- `invoice_number` — *Description:* `The supplier's invoice number`. (Plain text — no advanced settings.)
- `invoice_date` — open **View Config**, add a **date** validation rule.
- `vendor_name` — plain text.
- `total_amount` — open **View Config**, add a **numeric** validation rule (currency).
6. Confirm all four show in the **Labels** tree under **Invoice Header**.
You now have a Processing collection whose extraction agent knows to pull four fields from every invoice. In [Ingestion & connectors](/academy/d4) you'll feed it documents; in [Your first agent](/academy/a3) you'll assign the agent that extracts them. The full end-to-end build is [Invoice processing](/academy/uc-invoice).
> **Bonus.** Add a fifth field `line_items` as a **table**: in the editor open **Record Config**, turn on **Is Record**, then add child Labels `description`, `quantity`, `unit_price` as its columns.
## Recap
- A **Collection** is the typed home for one kind of record, at `Studio ▸ Data Model ▸ Collections` — a **master-detail** workspace (collection rail + tabbed detail pane).
- Create one from **+ Collection** / the **General** tab: pick **Processing** vs **Knowledge** (flag `knowledgeCollections`, **immutable after create**), name it, describe it. Everything else is optional accordions with defaults.
- The detail pane has up to **eight tabs**: **General** + **Schema** (this page), Lifecycle / Tags / Events, Ingestion, Agents, and **Index Health** (Knowledge collections only).
- The **Schema** tab defines **Learners** (field groups) and **Labels** (fields). **Schema drives extraction** — the agent extracts exactly the Labels you define.
- A field's **type** comes from its **validation rule** + **Record Config**, not a single dropdown. Tables use **Is Record** + child Labels. **Import labels** stands up a big schema fast.
## Where to go next
- [Taxonomy, lifecycle, tags & events](/academy/d3) — the other Data-Model tabs: review stages, tags, and webhooks.
- [Ingestion & connectors](/academy/d4) — get documents *into* your new collection.
- [Your first agent](/academy/a3) — assign the Worker that extracts your fields (the **Agents** tab).
- [Invoice processing](/academy/uc-invoice) — this collection, built end to end.
---
## D2 · Collection types
URL: https://www.botminds.ai/academy/d2
> Botminds Academy — Platform · Data
# Collection types
> **In one line.** The Category you pick at creation decides how a collection behaves for the rest of its life — Processing moves work, Knowledge grounds answers, Structured holds rows.
> **You'll be able to.** Pick the right category on the first try, and know why the choice is permanent.
## The decision that comes first
`Studio ▸ Data Model ▸ Collections ▸ + Collection` asks you one load-bearing question: **Category**. Everything else about a collection can evolve — schema, lifecycle, sources — but the category is fixed once created (the editor shows it as a read-only chip afterwards, and the server enforces it). Thirty seconds of thought here saves a rebuild later.
## The three categories
### Processing — work in flight
The default. Each document is a *case*: it arrives, gets worked by the crew, walks the [lifecycle](/academy/d3) stage by stage, and ends settled. Everything the [Workflow pattern](/academy/sol-wf) needs lives here — schema to fill, stages to walk, confidence gates, review routing.
Choose it when the sentence is *"each one of these must be handled."* Invoices, claims, applications, contracts under review, support tickets.
### Knowledge — reference that answers
Documents become readable knowledge the moment they land. No lifecycle, no stages, no settling — a Knowledge collection is a library, not a queue. Attach it to an agent's **Knowledge** tab and you get grounded, cited answers; this is the entire foundation of [Agentic Search](/academy/sol-search).
Choose it when the sentence is *"people should be able to ask about these."* Policies, manuals, product docs, past decisions worth consulting.
> Knowledge is a shipped release feature (`knowledgeCollections`, default on). If an environment has switched it off as a kill-switch, the Knowledge option won't appear at creation.
Add a Knowledge schema when your users also ask counting questions — facts then land in a [Datasheet](/academy/d5) and the agent can answer "how many policies mention retention?" with SQL rather than prose.
### Structured — records, not pages
Rows with fields, not documents with pages: vendor masters, rate tables, reference lists, results produced by agents. Structured collections are what [structured-source ingestion](/academy/d4) fills (each row of an imported sheet becomes a record, updated in place on re-import), and what structured display surfaces like [Pages & cards](/academy/e6) render as tiles, rows and tables.
You don't have to type the schema by hand: the create form's schema designer has an **Upload file** mode — drop in a spreadsheet and it infers the fields from the columns, with a live preview (multi-sheet workbooks let you pick the sheet) and an optional *"Import the data too"* toggle to bring the rows in at the same time. Later imports into the grid preflight every row and show ready-vs-problem counts before anything is committed.
Choose it when the sentence is *"this is really a table."*
## Side by side
| | Processing | Knowledge | Structured |
|---|---|---|---|
| Unit | Document as a case | Document as reference | Row as a record |
| Lifecycle | Yes — the point of it | No | No |
| Typical writer | Ingestion + extraction crew | Upload or connector | Sheet import or agents |
| Typical reader | Operators in the [workspace](/academy/e2) | Agents answering in [chat](/academy/e4) | Cards, dashboards, exports |
| Solution shape | [Workflow](/academy/sol-wf) | [Search](/academy/sol-search) | Both, as supporting data |
One system usually mixes all three: a lending build keeps applications in Processing, underwriting guidelines in Knowledge, and rate sheets in Structured — and its agents read across them.
(A fourth, flag-gated purpose also exists — **Dataset (Evaluation)**: golden documents with verified expected outputs, used only by [evaluations](/academy/a12) and excluded from product views.)
## The special one you don't create
The **Inbox** is a system-owned, human-kind collection: it holds the work routed to people by confidence gates and review rules. You'll meet it in [G2 · Human-in-the-loop](/academy/g2); you can't delete it, and you don't need to manage it.
## Where to go next
- Shape what's inside: [D1 · Collections & schema](/academy/d1).
- Get documents flowing in: [D4 · Ingestion & connectors](/academy/d4).
- The stages Processing documents walk: [D3 · Taxonomy, lifecycle, tags & events](/academy/d3).
---
## D3 · Taxonomy, lifecycle, tags & events
URL: https://www.botminds.ai/academy/d3
> Botminds Academy — Platform · Data
# Taxonomy, lifecycle, tags & events
> **In one line.** The four configuration tabs inside a Collection that turn raw documents into classified, reviewed, decided, and reported-on records: **Taxonomy**, **Lifecycle**, **Tags**, and **Events**.
> **You'll be able to.** Read and edit a collection's classification labels, design the review stages a document moves through (including auto-decide rules), tag records, and fire an external webhook when a document changes stage.
> **Where this lives.** `Studio ▸ Data Model ▸ Collections ▸ ` — then the **Taxonomy** (Schema), **Lifecycle**, **Tags**, and **Events** tabs in the right pane.
## Why it matters
[Collections & schema](/academy/d1) gave you a Collection and a schema — the *shape* of a record. This page gives the record a *life*. Once a document lands, four things decide what happens to it: how it's **classified** (Taxonomy), the **stages** it moves through and who reviews it (Lifecycle), the **tags** people stick on it (Tags), and the **external systems** told about it (Events). Three of these tabs are short; **Lifecycle is the big one**, because that is where "AI extracted some fields" becomes "the business made an auditable decision."
> **Watch out — the one confusion to avoid.** A **Lifecycle / Stateflow** is the set of *stages a document moves through* (Intake → Review → Approved…). An **XFlow** is a *pipeline of operators* that does processing work. They are different objects; the codebase unhelpfully calls both "workflow." This whole page is about **Lifecycle**, not XFlow. XFlows are covered in [XFlows & pipelines](/academy/a10).
## Taxonomy (Schema) tab — classification vs extraction
You met this tab in [Collections & schema](/academy/d1) as the place you define **Learners** (trainable extractors) and their **Labels** (fields). Here we focus on one specific use of it: **classification**.
There are two jobs a Learner can do, and the difference is the **Type** you pick when you create it:
| Job | What it produces | Learner **Type** to choose |
|---|---|---|
| **Extraction** | Pulls a *value* out of the document — `invoice_total`, `due_date`. | A field/record/table type. |
| **Classification** | Assigns the document (or a page/section) to a *category* — "this is an Invoice", "this page is a Cover Letter". | **Document / Page / Section / Table Classification**. |
A **classification label** is just a Label living under a *Classification*-type Learner: its name is a category the document can be sorted into (e.g. `Contract`, `Invoice`, `Statement`). Classification results are what drive routing later (a **Conditional** lifecycle stage can branch on them — see Lifecycle below).
### Creating a classification label
`Studio ▸ Data Model ▸ Collections ▸ ▸ Schema` (or the **+ Taxonomy** header button):
1. Click **Taxonomy** (footer) to open **Create Taxonomy**. Give it a **Name** and **Description**.
2. Set **Type** to one of **Document / Page / Section / Table Classification**, pick the **Entity** (collection), and **Submit**.
3. Select the new Learner, open the **Labels** sub-tab, click **+ Label**.
4. Enter the category as the **Label Name** (e.g. `Invoice`) and a **Description** (both required).
5. **Show Advanced Settings** reveals the same six accordions as any label (Table Styling, Contextual Insights, Record Config, Toggles, Lookup Config, View Config). For a plain classification label you rarely need them — leave defaults.
6. **Add** (keep going) or **Add and exit**.
### Bulk import
On the Label dialog switch to the **Import labels** tab to load many categories at once: drag-drop or **Choose File** a `.txt / .xlsx / .tsv / .csv`; parent-to-child hierarchy is expressed by indentation (text) or columns (spreadsheet); **Upload & Create**.
> **Tip.** Keep classification Learners small and flat — one Learner per decision ("Document type", "Risk band") with a handful of labels each. It reads better in the Conditional stage editor.
The full field-by-field reference for every label advanced option lives in [Collections & schema](/academy/d1); this page doesn't repeat it.
## Lifecycle tab — the stages a document moves through
This is the heart of the page.
A **Lifecycle** (a *Stateflow*) is an ordered set of **stages**, with role-gated edges between them. Every document in a Processing collection carries a **current stage**. Moving a document from one stage to the next is the unit of progress — and **every move is written to an audit trail** (`document_workflow_history`). A "decision" on the platform isn't a separate object; it's simply read back from that trail of stage moves. That is the whole point of the Lifecycle: it turns AI output into an **auditable business decision**.
### The default: the 8-stage Four-Eyes flow
Every new Processing collection is **seeded** with the **Four-Eyes** lifecycle. Its motto: *AI recommends, two humans confirm, the platform remembers.* (How the humans in it actually receive and work their queue is [Human-in-the-loop](/academy/g2).)
| # | Stage | Type | Role that handles it | Sends to Inbox? |
|---|---|---|---|---|
| 1 | **Intake** | Start | everyone | no — system assigns on ingest |
| 2 | **AI Processing** | In-progress | everyone | no — the intake agent is running |
| 3 | **AI Recommendation** | In-progress | everyone | no — branches by confidence / policy |
| 4 | **L1 Review** | In-progress | L1-Reviewer (also visible to L2-Approver) | **yes** — first human eye |
| 5 | **L2 Approval** | In-progress | L2-Approver | **yes** — second human eye (the gate) |
| 6 | **Needs Info** | In-progress | everyone | **yes** — Inbox stage; awaits more info, then re-runs AI Processing |
| 7 | **Approved** | End | everyone | no — terminal (approved) |
| 8 | **Declined** | End | everyone | no — terminal (declined) |
```
Intake (Start)
│ auto on ingest
▼
AI Processing ◄──────────── re-runs when info arrives ──┐
│ agent done │
▼ │
AI Recommendation Needs Info (Inbox)
│ ▲
├─ policy ON & confidence passes: auto-decide │
│ skips both reviewers ──► Approved / Declined │ needs-info
│ │
└─ low confidence / always ──► L1 Review (Inbox, L1-Reviewer)
│ approve ├ reject ──► Declined
▼ └ needs-info ─┘
L2 Approval (Inbox, L2-Approver)
├ approve ──► Approved (End, terminal)
└ reject ──► Declined (End, terminal)
```
> **Under the hood.** The Four-Eyes seed creates **exactly two** reviewer roles — `L1-Reviewer` (bound to L1 Review) and `L2-Approver` (bound to both review stages) — alongside the lifecycle. (`Admin` exists as a general project role, but it is *not* part of the Four-Eyes seed.) The seeded stages ship with `ViewedByRoleIds` **null** (open to all); gating is expressed the inverse way — each role carries the stage ids it handles — and you assign any further per-stage gating yourself via **Can be viewed by** (`ViewedByRoleIds`). Roles are covered in [Security & governance](/academy/g1).
### Layout of the Lifecycle tab
- **Left "Lifecycle" panel** — lists the collection's stateflows by Name + Description; a star marks the **Primary**. Row menu: **Edit** / **Delete** (Delete is hidden for the Primary). Footer **+ Lifecycle** to add one.
- **Right pane** — the **stage graph** (`WorkflowGraphComponent`; drag to reorder, click a stage to open the State editor), a **legend** strip (Start / Conditional / End markers), and — for Processing collections — the **Auto-Decide policy card**.
### What every control does
**Lifecycle (stateflow) level — the *+ Lifecycle* / Edit dialog:**
| Control | What it does | Notes |
|---|---|---|
| **Name / Description** | Identify the lifecycle. | Required. |
| **Entity** | Which collection it belongs to. | Prefilled to the current collection. |
| **Set as Primary** | Makes this the default lifecycle for the collection. | Exactly one Primary. |
| **Allow Back Propagation** | Lets documents move *backwards* to an earlier stage. | E.g. L2 sends back to L1. |
| **Include StateFlow Change Message** | Prompts for a note when a document changes stage. | Captured in the audit trail. |
| **Disable Show Stage History** | Hides the per-document stage history. | Default off (history shown). |
**Stage level — the *Create / Edit State* dialog:**
| Control | What it does | Notes |
|---|---|---|
| **State Name / Description / Final Name** | Name the stage. | Final Name is the label shown when terminal. |
| **Workflow State** | `Start` / `In-progress` / `End`. | Exactly one Start, one End. |
| **Send to Inbox (human review)** | Routes documents reaching this stage to the human work queue (Inbox). | This is `IncludeManualIntervention` — what makes a stage a *review* stage. Routing detail: [Human-in-the-loop](/academy/g2). |
| **Can be moved to** | Target stages — the outgoing edges. | Multi-select. |
| **Can be viewed by** | Roles allowed to see/act on documents here. | `ViewedByRoleIds`; empty = all roles. |
| **Legend** | A coloured tag on the graph; inline **Create New Legend** (Name + colour). | Cosmetic + grouping. |
| **Document View Type / history-visibility** | Display options. | — |
| **Automation Type** | The action this stage runs *on entry* (11 types). | Summarised next. |
### What a stage can do: the 11 automation types
A stage isn't only a waiting room — on entry it can trigger one **Automation**. The picker offers 11 types. Briefly:
- **Agent Flow** — run an agent/agent-team on the doc. **AI Pipeline** — run an AI pipeline. **Rescore** — refresh confidence scores. **Ingestion** — pull data from sources. **Export** — push the doc out via an export template. **Events** — fire the collection's webhooks. **RPA Bots** — hand to an RPA bot. **Conditional** — branch to different next-stages by label value. **Auto Allocate Users** — auto-assign reviewers. **Auto Derivation** — compute/auto-fill labels. **Regroup Summary** — refresh roll-up summaries.
The **Conditional** type is the workhorse for routing: "if `document_type = Invoice`, go to Invoice Review." Each type is configured with its own fields and toggles.
### The Auto-Decide policy card (Processing collections)
Below the graph sits the **Auto-Decide policy** card — a single knob that lets the platform **auto-approve (or auto-decline) clean documents** without sending them through L1 + L2. It is **OFF by default**; even when on, it only fires when the agent's confidence and flags pass.
| Field | Default | Meaning |
|---|---|---|
| **Enabled** | `false` | Master switch. Off means every document visits L1 and L2. |
| **Min Confidence** | `0.92` | Agent confidence floor required to auto-promote. |
| **Require Zero Flags** | `true` | If any flag is open on the doc, no auto-promote. |
| **Max Amount** | `null` | A dollar-amount ceiling; `null` = no cap. (Reads from **Amount Field**.) |
| **Applies To** | `both` | Which verdicts may auto-fire: `approve` / `decline` / `both`. |
The card shows a plain-English preview, e.g. *"Auto-approve when AI confidence ≥ 0.92 AND zero flags AND amount ≤ $500k."* The safest first step most operators take is **Enabled = true, Applies To = approve** — auto-approve clean cases, always keep human eyes on declines.
> **Under the hood.** Auto-decide is evaluated in the orchestrator, never spoofing a user: an auto-decided document's audit row shows actor `AI/auto` plus the confidence; a normal AI handoff shows `AI/recommended`. The audit trail stays truthful.
### Validation rules
Before you can switch stateflows or save, the lifecycle must be a valid graph:
- Exactly **one Start** and **one End** stage.
- At least one **Start → End** path.
- **No** unterminating cycles.
- A stage **can't be deleted** while documents currently sit in it.
If it's invalid you get the toast *"Please validate the workflow before proceeding."*
> **Watch out — Reset to default is destructive.** The **Reset to default** action rebuilds the Four-Eyes flow and is gated behind a confirm-by-EntityId prompt. Don't use it to "clean up" a lifecycle that already has live documents.
### How stages move a document (and produce the decision)
Putting it together for one document:
1. It lands in **Intake** (Start) automatically on ingest.
2. The intake agent runs (**AI Processing**), extracts fields against the schema with a confidence per field, then sits at **AI Recommendation**.
3. If Auto-Decide is ON and the doc passes, it jumps straight to **Approved/Declined**. Otherwise it routes to **L1 Review** and is **sent to the Inbox** ([Human-in-the-loop](/academy/g2) covers what the reviewer sees there).
4. A reviewer with the **L1-Reviewer** role acts; approve sends it to **L2 Approval**, reject ends it, or it goes to **Needs Info** — also an Inbox stage, which re-runs AI Processing once more info arrives.
5. **L2 Approval** (the second eye) finalises it to **Approved** or **Declined**.
6. **Every** one of these moves appended a row to the audit trail. The "decision" is that trail — who moved it, when, with what note, at what confidence.
## Tags tab — free-form labels people stick on records
`Studio ▸ Data Model ▸ Collections ▸ ▸ Tags`.
Tags are a small, project-wide set of free-form labels your reviewers apply to documents (internally the code calls them "Error Types"). Use them to mark things like `Duplicate`, `Missing PO`, `Wrong Vendor` — anything you want to filter or report on later that isn't an extracted field.
- A simple **table**: each tag's **Name** plus **Edit** and **Delete** (Delete confirms "Delete ?").
- **+ Tag** opens the **Add/Edit** dialog: one **Tag name** field (required; rejects duplicates with "Tag name already exist") and **Save**.
- Empty state: *"No tags found in the project"* with a **Tag** button.
That's the whole tab — tags are deliberately simple. Reviewers apply them on the document detail surface ([Document detail](/academy/e3)).
## Events tab — fire a webhook when something changes
`Studio ▸ Data Model ▸ Collections ▸ ▸ Events`.
An **Event** is a subscription that fires an **external action** (an HTTP **webhook**, an **email**, a **Slack** message, …) when something happens to a document — a **lifecycle stage change**, a label change, an ingestion failure, and so on. This is how you tell *your* systems that the platform did something: "POST to our ERP the moment an invoice reaches Approved."
- **Left "Events" panel** — lists events by Name + trigger; row menu **View Event / Edit / Delete**; footer **+ Event**.
- **Right details panel** — shows the event's trigger types, action type, and action details (Webhook URL / email To+Subject / Slack URL).
### Creating an Event
Open **+ Event** (the **Create/Edit Event Details** dialog):
| Control | What it does | Notes |
|---|---|---|
| **Name** | Identify the event. | Required. |
| **Events** (triggers) | The trigger types — multi-select (Stage change, label change, Ingestion failure, Callback, …). | "Document" reads as your record noun. |
| **Entity** | The collection. | Prefilled. |
| **Workflow + Stage** | When a stage-change trigger is chosen, scope it to a specific **lifecycle** and **stage(s)**. | This is the lifecycle-to-events link. |
| **Jobs** (Ingestion-Failure only) | Which ingestion jobs to watch; empty = all. | — |
| **Callback types** (Callback trigger only) | Which callbacks fire it. | — |
| **Actions** (`+ Add Action`) | One or more actions, each with a **Notification Type**: **Webhook** (URL), **Email** (To + Subject), **Slack** (URL), etc. | An event can fire several actions. |
| **Show Advanced Settings** | **Check SLA Breach** + **SLA Time (sec)**, **Check File Upload**, **Alert Frequency (min)**, label filters, user filter. | Use SLA fields to alert when a doc sits too long. |
### Walkthrough — webhook on "Approved"
1. Events tab, then **+ Event**. **Name**: `Notify ERP on Approved`.
2. **Events** trigger — choose the **stage-change** trigger.
3. **Workflow** — `Four-Eyes`; **Stage** — `Approved`.
4. **+ Add Action** — Notification Type **Webhook** — paste your endpoint `https://erp.example.com/bm-hook`.
5. (Optional) **Show Advanced Settings** — set **Check SLA Breach** + **SLA Time** if you also want a late-document alert.
6. **Save.** From now on, every document that reaches **Approved** POSTs to your endpoint.
> **Tip.** Two ways to fire a webhook on a stage change: an **Event** here (declarative, recommended) *or* an **Events**-type **automation** on the stage itself (Lifecycle tab). Prefer the Event subscription unless you specifically need it bound to stage *entry* inside the graph.
## Try it yourself
Pick **one** of these on a Processing collection (e.g. the Invoices collection from [Collections & schema](/academy/d1)):
**A — an "auto-approve under $500" rule.** Open the **Lifecycle** tab, then the **Auto-Decide policy** card. Set **Enabled = true**, **Applies To = approve**, **Max Amount = 500** (and set the **Amount Field** to your total label, e.g. `invoice_total`). Save. Confirm the preview reads roughly *"Auto-approve when AI confidence ≥ 0.92 AND zero flags AND amount ≤ $500."* Now clean invoices under $500 skip both reviewers; everything else still goes through L1 + L2.
**B — a webhook on approval.** Follow the Events walkthrough above to POST to a test endpoint (use a free request-bin URL) when a document reaches **Approved**. Drive one document to Approved and check the bin received the call.
Either way, open the document's stage history afterwards and notice the **audit trail** — that's your decision record.
## Recap
- The **Taxonomy/Schema** tab also defines **classification** labels (Document/Page/Section Classification Learners) — categories used later for routing.
- A **Lifecycle / Stateflow** is the ordered **stages** a document moves through; new Processing collections are seeded with the **8-stage Four-Eyes** flow (Intake → AI Processing → AI Recommendation → L1 Review → L2 Approval → Needs Info → Approved/Declined).
- A stage has a **type** (Start/In-progress/End), **edges** (Can be moved to), **role-gating** (Can be viewed by / `ViewedByRoleIds`), a **Send-to-Inbox** flag (`IncludeManualIntervention`), and one of **11 Automation Types** it runs on entry.
- The **Auto-Decide policy** card auto-approves/declines clean docs (OFF by default; confidence + flags + amount cap gate it).
- **Every stage move is written to an audit trail** — the platform's "decision" *is* that trail.
- **Tags** are a simple free-form label set; **Events** fire webhooks/email/Slack on stage or label changes.
- **Lifecycle ≠ XFlow.** This page was Lifecycle.
## Where to go next
- [Dashboards & Inbox](/academy/e5) — where the humans you route to in L1/L2 actually do the reviewing.
- [Human-in-the-loop](/academy/g2) — how Inbox routing and review assignment work end to end.
- [Security & governance](/academy/g1) — the seeded Four-Eyes roles (`L1-Reviewer`, `L2-Approver`) that stage-gating depends on, and project roles like `Admin`.
- [XFlows & pipelines](/academy/a10) — the *other* "workflow": processing pipelines, not document stages.
---
## D4 · Ingestion & connectors
URL: https://www.botminds.ai/academy/d4
> Botminds Academy — Platform · Data
# Ingestion & connectors
> **In one line.** How documents get into a collection — upload, crawl, feed, or form — and how processed results get out through Export.
> **You'll be able to.** Wire a reusable connection to an external system, schedule a job that pulls documents into a collection, run a one-shot upload, watch a run, and set up an export.
> **Where this lives.** `Studio ▸ Connector` — the **Ingestion**, **Output**, and **Input Form** screens.
## Why it matters
A solution is only as good as the documents flowing through it. The **Connector** section of Studio is the loading dock: it is where you connect to SharePoint, a Google/internal Drive, a mailbox, or a public data feed; schedule pulls; drop in one-off uploads; and, on the way out, configure how finished documents are **exported** back to your systems. Everything here feeds the collections you built in [Collections & schema](/academy/d1). Get the model right once and you rarely think about it again — documents just arrive, show a "Processing…" chip, and fill in.
## The model: Connector vs Job vs Run
This is the single idea that makes the whole section make sense. From [Core concepts](/academy/s2):
| Term | What it is | Glossary role | Example |
|---|---|---|---|
| **Connector** | A tested **connection** — credentials + a target system | identity | "Our Finance SharePoint" |
| **Job** | A **scoped, scheduled fetch** — a connector + a scope + a schedule + a target collection | scope | "The `/Invoices` library, every 6 hours, into *Vendor Invoices*" |
| **Run** | One **execution** of a job (or an upload) — the history record | — | "Tuesday 06:00 run: 14 new, 2 duplicates" |
You build a connector **once** and reuse it across many jobs. A job is where you say *which* documents, *how often*, and *where they land*. A run is what you inspect when you want to know what happened.
> **Under the hood.** When a document arrives — by upload, crawl, feed, or form — the backend creates the document row *immediately* with status **Processing…** (so it appears in the list at once), stores the raw bytes, and hands off to the orchestrator. The orchestrator runs the collection's **ingestion XFlow** (fetch the bytes, assemble the document, write it to Postgres), then extraction agents fill in the schema fields. A single progress row drives the chip you see climbing to 100%. For a **Knowledge** collection, the intake instead **chunks, embeds, and indexes** the document for search (standalone image files go through vision page summaries when Image mode is on, else fail with a clear "no readable text" reason) — watch it on the collection's **Index Health** tab ([Search, indexes & vectorization](/academy/d6)). The chain stalls at "queued" if the background worker isn't running — the usual cause of a doc stuck at 0%.
> **The default Ingestion screen.** The modern Ingestion screen this page teaches is **Sources v3** — the Connector / Job / Run model. It is simply *the* Ingestion screen in Studio: the rail entry `Studio ▸ Connector ▸ Ingestion` is hardwired to the `connector/sources-v3` route; there is no flag to flip to reach it. The legacy single-source wizard still exists but is deep-link-only (see below). The separately-scoped **`ingestionV3`** flag, default **on**, governs the *consumer* document-list **+ Data** upload button — not this Studio rail entry.
## The Ingestion screen (Sources v3)
`Studio ▸ Connector ▸ Ingestion`. One screen, three tabs. It is also embedded inside a collection's own **Ingestion** tab, where one extra **Add-Data settings** toolbar button appears.
```
┌─ Ingestion ─────────────────────────────────────────────────────────────────┐
│ [ Upload ] [ + Connector ] [ + Job ] (Add-Data │
│ settings*) │
│ ┌──────────┬────────────┬────────┐ │
│ │ Jobs ▸ │ Connectors │ Runs │ ← three tabs (Jobs is default) │
│ └──────────┴────────────┴────────┘ │
│ │
│ Invoices nightly on Finance SP · cron 0 6 * * * · next 06:00 · active │
│ [ Run now ] [ Pause ] [ edit ] [ delete ] │
│ Contracts drip on Botminds Drive · every 6h · next 12:00 · active │
│ [ Run now ] [ Pause ] [ edit ] [ delete ] │
│ ────────────────────────────────────────────────────────────────────── │
│ * Add-Data settings appears only when embedded in a collection's tab. │
└──────────────────────────────────────────────────────────────────────────────┘
```
- **Toolbar (top-right):** **Upload** (one-shot drop), **+ Connector** (the connection wizard), **+ Job** (the primary action — schedule a pull). When embedded in a collection, an **Add-Data settings** button also appears.
- **Tabs:** **Jobs** (scheduled pulls — the default tab), **Connectors** (your saved connections), **Runs** (execution history). The body shows `Loading…` while fetching.
- Each row carries a kind icon: SharePoint, Email, Drive, Public Feed, or a generic package icon for anything else.
### What every control does
| Tab | Row shows | Row actions |
|---|---|---|
| **Jobs** | kind icon + job name + "on `` · `` · next `` · active/paused" | **Run now**, **Pause/Resume**, **edit**, **delete** (confirms; *run history is preserved*) |
| **Connectors** | icon + name + "`` · active/paused · test OK/failed/never · used by N jobs" | **Reconnect** (only when the last test failed — SharePoint only today), **Test** (live test + latency), **Pause/Resume**, **delete** (disabled with a tooltip if jobs still use it — *delete the jobs first*) |
| **Runs** | When · Trigger · Status · funnel counters | row click opens the **Run detail** dialog |
**Empty states.** Jobs: *"No jobs yet · Click + Job to schedule one. (You'll need a Connector first.)"* — Connectors: *"No connectors yet"*. The order matters: **a connector must exist before a job can use it.**
### The Runs tab and Run detail
The Runs table tracks each execution with a **funnel** of counters — the eight stages a batch of items passes through:
`Enum` (enumerated) → `Fetch` (downloaded) → `New` → `Upd` (updated) → `Dup` (duplicate, skipped) → `Disp` (dispatched to pipeline) → `Merge` → `Fail`.
Status colours: completed is green, partial amber, failed red. Click a row to open the **Run detail** dialog (1000px): pipeline-summary chips (Enumerate → Fetch → New → Updated → Duplicate → Dispatch → Merge), the status + failed count + last error, then a per-item **event log** (When · Stage · Item · Status · Message) so you can see exactly which file failed and why.
> **Tip.** `Dup` climbing on a recurring job is normal and *good* — it means dedup is working and you are not re-processing files you already have.
## The Add-Connector wizard
`+ Connector` opens a 900px wizard. There are **six kinds**, and the number of steps varies by kind: SharePoint has **3 steps** (kind → auth pattern → form); every other kind has **2 steps** (kind → form — the auth-pattern step is skipped). SharePoint's auth-pattern step offers two tiles: **Quick** (connect with Microsoft — SMB / pilots) and **Enterprise** (use your own Entra app — enterprise IT).
Step 1 is a tile grid of the six kinds:
| Kind | Tile | Use it for |
|---|---|---|
| **SharePoint** | "Pull docs from a SharePoint site" | Microsoft 365 document libraries |
| **Email (IMAP)** | "Pull docs from a mailbox" | Gmail / Outlook / generic IMAP inboxes |
| **Botminds Drive** | "Pull docs from this project's internal drive. No setup needed" | Files already inside the project's Drive |
| **Public Feed** | "Pull from public gov data sources (SEC, CFPB, Federal Register)" | Curated public data feeds |
| **Datasheet** | "Re-ingest rows from a datasheet in this project as documents" | Turning [Datasheet](/academy/d5) rows into documents |
| **Azure Blob Storage** | "Ingest from an Azure Blob container" | Files in your own Azure storage |
The per-kind credential forms and their test rules are enumerated in the [Connector catalog](/academy/r2) — this page teaches the shape; the catalog enumerates every field.
### Behaviours to know
- **Test-before-save.** Email, Public Feed, Drive, Azure Blob, and SharePoint-Enterprise connectors **cannot be saved until a live connection test passes** (a platform invariant). Editing any field after a green test *clears* it — you must re-test. (Datasheet is the exception: it's internal — just pick the datasheet and name it.)
- **SharePoint Quick** has no Save button — it completes through the **Connect with Microsoft** OAuth popup. A closed popup reads as "Sign-in cancelled"; a blocked popup shows a warning.
- **Edit / Reconnect** jumps straight to the form step, pre-filled — but **secrets are never pre-filled**; re-enter them. The stepper is hidden in edit mode.
## The Add-Job wizard
`+ Job` is the primary action — this is where documents actually start flowing. **Three steps** (editing an existing job locks the connector, dropping it to two):
1. **Pick a connector** — choose from the project's **active** connectors (radio rows with kind icon + test status + "used by N jobs"). No connectors? The wizard tells you to *"Cancel and create a Connector first."* Hidden when editing.
2. **Scope & metadata mapping** — the **Job name** (required), then a **kind-specific scope** (the folder/library/mailbox/feed slice to pull), the **Target collection** (a real dropdown of your project's collections — never free text; "Default" is always present), and optional **Secondary XFlows** (comma-separated pipelines that run after each item is registered). Scope fields per kind:
- **SharePoint** — Document library (with **Test Drive** to resolve a name to a stable id), Folder path, File extensions, Recursive, Max docs/run, plus a **"Pull metadata from SharePoint?"** toggle that reveals a **metadata-mapping** grid (map a taxonomy field to a SharePoint column; **Discover columns** lists the available columns).
- **Email** — Folder (default INBOX), Include attachments, Max docs/run.
- **Drive** — Folder (read-only; **Browse…** opens a picker), Extensions filter, Recursive, **"Explode structured rows"** (Excel/CSV/JSON → one document *per row*, with an optional **Unique ID column**), Max docs/run.
- **Public Feed** — fields rendered dynamically from the feed's own shape.
- **Azure Blob** — Container, Folder path (blob prefix), Extensions filter, Recursive.
- **Datasheet** — Document granularity (one document per row / whole sheet), Max rows/run. New and edited rows are picked up automatically each run.
3. **Schedule** — choose **On-demand only** (you press Run now), **Recurring** (every N Seconds/Minutes/Hours/Days), or a **Cron expression** (+ timezone). Public feeds also offer preset chips (Hourly / Every 6h / Daily 9am UTC / Weekly Mon 9am / On-demand). A live **"Next 5 runs"** preview confirms your schedule before you save.
The final button reads **Create job** (or **Save changes** when editing).
### Scheduling, drip, and dedup
- **Scheduling** is per-job. A scheduled job fires on its cadence; **Run now** triggers it immediately regardless of schedule.
- **Drip** — public feeds (and other recurring jobs) pull only *new* items each run rather than re-downloading the whole source; the feed's drip behaviour is described on its tile.
- **Dedup** — each run reports `Dup` for items it has seen before, so a recurring job is safe to run often without reprocessing. For **exploded structured rows**, set a **Unique ID column** as the business key; leave it blank and the platform dedups on a content hash.
## The Upload modal (one-shot)
The **Upload** toolbar button opens a 720px modal for ad-hoc files — no connector or job needed:
1. **Drag-drop or browse** multiple files. The list shows each file with its size, a remove control, and **Clear all**.
2. If multi-file grouping is on, a note explains the files are *"grouped into one document set (first file primary)."*
3. Choose the **Target collection** (unless it is pre-filled by context).
4. **Submit** opens a result panel — complete / partial / failed, *"N of M registered, K failed"*, the run id, and a per-file breakdown (docId on success, error on failure). **Done** closes.
> **Tip.** Use Upload to smoke-test a new collection's schema before you wire a recurring job — drop in five representative files, watch them process, fix the schema, then automate.
## Legacy Ingestion (the old path)
Before Sources v3 there was a single-source wizard at route `connector/sources` — no longer wired to the Ingestion rail entry, reachable by deep link only. It bundled per-source config, an annotator, document-property metadata, and a crawl-job history page. It still works, but **all new builds use v3** — the Connector/Job/Run model above is the going-forward shape. Don't start new work in the legacy wizard.
## Export — getting results out
`Studio ▸ Connector ▸ Output` (route `connector/output`). Ingestion is the loading dock; **Export** is the shipping dock — it pushes *processed* documents (with their extracted data, optionally split or bookmarked) out to Azure Blob storage or the Botminds Drive.
The screen is a standard list + details split: the left rail lists your exports, the right panel shows the selected export's details — **Type**, **Taxonomy** (the fields included, as chips), **Storage Type** (Azure Blob or Botminds Drive), and **Storage Details** (account + container, or the drive URL), with edit/delete row actions. Empty state: *"Setup an export to see more details"* plus **+ Export**.
### The Add Export dialog
`+ Export` opens a dialog whose fields **change based on the Export Type** you pick — choose the type first, the rest follows. Always present: a **Name**, the **Export Type**, and the **destination** (External Sources: Azure Blob → Storage Name/Key/Container, or Botminds Drive → drive URL).
The notable toggles for a **split/bookmark** export type:
- **Split Input Document**, **Split on Sequential Values**, **Split By Start Page** — break one input PDF into several output files.
- **Grouped Bookmark**, **First Value As Bookmark**, **Group By Label**, **Order Date** — build bookmarks/structure in the output.
- **Suffix for document name** — append a value to output filenames.
And **common** toggles across types: **Export current-job docs only**, **Add date-wise folders**, **Add document-wise folders**, **Export input document** (ship the original alongside results), **Delete input document from project** (clean up after export). **Save** is disabled while the form is invalid. The full per-type field matrix is in the [Connector catalog](/academy/r2).
## Input Form — capturing structured input directly
`Studio ▸ Connector ▸ Input Form` (route `connector/form_template`, visible when enabled for your project). Sometimes you don't have documents at all — you want a person to **type** structured input that becomes a record. The **Input Form** builder defines those form templates, in the familiar list + details split. Empty state: *"No Form. Add new form to process"* plus **+ Add Form**.
Every template has a **Name**, **Description**, and a **Type**:
- **Create Source** — the form *creates documents/records*. You build its **Columns** (a repeatable list): each column has a **Name**, a **Type** (Text / Multiline / Checkbox / Dropdown / Radio), a **Label** (mapped to a taxonomy field, grouped by taxonomy), and flags **Required**, **Is Title**, **Is Template**. Each column can carry **rules** (Field + Value conditions that show/validate it). A **Use Excel** shortcut lets you define columns from a spreadsheet instead. If a column is **Is Template**, a **Templates** section appears (Value + an Export Template + a Rendering Template).
- **Publish Template** — a seed/launch form rather than a record-creator. Its **Sub Type** is either **Connector** (pick an ingestion seed page) or **Global Variables** (pick variables to expose).
Submit with **Create** (or **Update** when editing). The full field/rule reference is in the [Connector catalog](/academy/r2).
## Try it yourself
**Goal: a recurring Drive-folder job that feeds a collection.**
1. Open `Studio ▸ Connector ▸ Ingestion` — the rail lands you on Sources v3 directly.
2. Click **+ Connector**, pick **Botminds Drive**. Give it a display name, click **Test connection** (it reports a sub-folder count), then **Save connector**. No credentials needed.
3. Click **+ Job**. Step 1: select your new Drive connector.
4. Step 2: name it (e.g. *"Contracts intake"*), click **Browse…** and pick a folder, set **Extensions** to `pdf`, tick **Recursive**, and choose your **Target collection**.
5. Step 3: pick **Recurring → every 6 Hours**. Check the **Next 5 runs** preview, then **Create job**.
6. Back on the **Jobs** tab, click **Run now** on your job. Switch to the **Runs** tab and watch the funnel counters fill; click the run to open **Run detail** and confirm each file landed.
*Faster variant:* skip connectors entirely — click **Upload**, drag in a batch of PDFs, pick the target collection, **Submit**, and watch the result panel.
## Recap
- **Connector = identity** (a tested connection), **Job = scope** (a scheduled, targeted pull), **Run = history** (one execution, with a funnel + event log).
- The modern **Ingestion** screen is **Sources v3** — the default Studio rail entry, with **Jobs / Connectors / Runs** tabs; the legacy single-source wizard is deep-link-only.
- Build a **connector first** (six kinds; most require a passing **test before save**), then a **job** (connector → scope + mapping → schedule), or just **Upload** one-shot files.
- **Scheduling** is per-job; **drip** pulls only new items; **dedup** reports `Dup` and is keyed by a Unique ID column for exploded rows.
- **Export** (`Connector ▸ Output`) ships processed results out; **Input Form** (`Connector ▸ Input Form`) captures structured input directly.
## Where to go next
- [Drive & datasheet](/academy/d5) — the internal Drive a Drive connector reads from, and the SQL datasheet layer.
- [Use case: invoice processing](/academy/uc-invoice) — a full ingest-to-export loop, end to end.
- [Connector catalog](/academy/r2) — every connector kind's fields, the full Export field matrix, and the Input Form column/rule reference.
- [Collections & schema](/academy/d1) — the collections your jobs target.
---
## D5 · Drive & datasheet
URL: https://www.botminds.ai/academy/d5
> Botminds Academy — Platform · Data
# Drive & datasheet
> **In one line.** The platform's two storage substrates: **Drive** (raw files in folders) and **Datasheet** (structured data as a flat SQL table).
> **You'll be able to.** Upload and organise project files in Drive, create a Datasheet from a database/spreadsheet/API or from a View, read its data and system columns, and understand how an agent queries it with SQL.
> **Where this lives.** `Studio ▸ Data Model ▸ Drive` and `Studio ▸ Data Model ▸ Data` (Datasheet).
## Why it matters
A Collection is the *typed* home for documents — it has a schema, a lifecycle, agents. But two kinds of data don't fit that mould. Sometimes you just need **a place to put raw files** (a pile of PDFs to ingest later, a reference spreadsheet, an export). That's **Drive**. And sometimes you need **structured rows you can query with SQL** — a lookup table of vendor codes, a feed of rows from your ERP, or a flattened copy of what your agents extracted. That's a **Datasheet**.
Think of them as the substrate beneath Collections: Drive is the **file system**, Datasheet is the **database table**. Both live under `Studio ▸ Data Model`, alongside Collections — they are *inputs to* and *outputs from* collections, not collections themselves.
## Drive — project file storage
**Purpose.** Drive is a folder tree + file browser over your project's Botminds Storage. You upload raw files here, organise them in folders, and — most importantly — a **Drive connector can pull from it** during ingestion, so Drive is a common *staging area* for documents on their way into a Collection.
**Where this lives.** `Studio ▸ Data Model ▸ Drive`.
### Layout
- **Left "Storage" rail** — a **Home** button plus a recursive, indented **folder tree**. Carets expand/collapse folders; click a folder to open it in the right pane.
- **Right pane** — a **breadcrumb trail** (Home ▸ … ▸ current folder), a **Total** file count, a **Search by name** box, the toolbar (below), and the **file table**.
- **File table** — columns **Name** (with a type icon), **Date**, **Size**, plus per-row **Download** and **Copy Path** actions. Folders sort first. Single-click selects a row (checkbox); double-click opens a folder. Long lists page with **Load More**.
- **Empty state** — "There is no files and folder available in this Folder" with an **Add Documents** button.
### What every control does
| Control | What it does | Notes |
|---|---|---|
| **Search by name** | Filters the current view by filename | Name match, current folder |
| **Refresh** | Re-reads the current folder from storage | Use after an upload or external change |
| **Delete selected** | Deletes the checked files/folders | Destructive — see Watch out below |
| **Upload Progress** | Opens the in-flight upload tracker | For large/many-file uploads |
| **Copy Path** | Copies the storage path of the selection (toolbar) or of one file (per row) | Handy for wiring a connector to a folder |
| **Add Folder** | Creates a new sub-folder in the current folder | Name it, confirm |
| **Add Documents** | Uploads files into the current folder | The primary upload action |
### Walkthrough — stage files for ingestion
1. Open `Studio ▸ Data Model ▸ Drive`.
2. In the Storage rail, click **Home**, then **Add Folder** and name it (e.g. `Invoices`).
3. Double-click into the new folder. Click **Add Documents** and select your PDFs.
4. Watch the **Upload Progress** tracker; when it finishes, click **Refresh** to see the rows.
5. Click **Copy Path** on the folder — you now have the path to point a Drive *connector* at when you set up ingestion.
### How Drive relates to ingestion
Drive on its own just *stores* files — nothing processes them. To get files from Drive **into a Collection**, you create a **Drive connector** and a **Source/Job** scoped to a Drive folder; the job fetches the files and runs them through the collection's ingestion XFlow. Drive is the staging area; the connector is the conveyor belt. Connectors, sources, and jobs are covered in [Ingestion & connectors](/academy/d4).
> **Tip.** Keep an `_exports` or `_staging` folder convention so it is obvious which folders a connector is watching versus which are just human drop-zones.
> **Watch out.** **Delete selected** removes files from storage. If a connector or a document already references a file, deleting it from Drive can leave the downstream record orphaned. Delete from Drive only files that haven't been ingested, or that you're sure nothing points at.
## Datasheet ("Data") — the structured-data layer
**Purpose.** A **Datasheet** is a flat **SQL table** — the platform's structured-data layer. Each Datasheet is materialised as a real backing table that an agent can query directly with SQL. You use a Datasheet when you need *rows and columns* rather than documents: a lookup table, an external feed, or a flattened copy of extracted data.
A Datasheet gets its rows in one of two ways:
- **Sourced** from an external **source connection** — a database, a spreadsheet, or an API response is pulled in and written to the table.
- **Materialised from a View** — a saved, filtered slice of a Collection's documents (its extracted labels become columns) is flattened into the table. Views are covered in [Shaping the experience](/academy/e7).
**Where this lives.** `Studio ▸ Data Model ▸ Data`.
### Layout
```
┌──────────────────────────────────────────────────────────────────────────────────┐
│ [ Datasheets | Sources ] │ Vendor Master │
│ ─────────────── refresh │ ─────────────────────────────────────────────────────│
│ Vendor Master ◀── │ [ Data | Details | Run Info ] │
│ Q2 Invoices (View) ok │ ────── │
│ ERP Feed warn │ [ Filter ] "vendor_status" = 'active' [ Apply Query ]│
│ │ ┌───────────────────────────────────────────────────┐ │
│ │ │ vendor_code │ name │ _BM_STATUS │ _BM_RUN_ID │ │
│ │ │ ACME-01 │ Acme Inc │ OK │ 9f3… │ │
│ │ │ GLBX-04 │ Globex │ OK │ 9f3… │ │
│ │ └───────────────────────────────────────────────────┘ │
│ ───────────────────── │ │
│ [ + Datasheet ] │ │
└──────────────────────────────────────────────────────────────────────────────────┘
```
- **Left rail — two tabs.** **Datasheets** lists your datasheets (each shows name + description and a **status icon/tooltip**), with a **Refresh** button at the top and a **+ Datasheet** button in the footer. **Sources** lists the **source connections** (the DB/spreadsheet/API bindings that feed datasheets); selecting one opens its view/edit/delete details.
- **Right pane (a Datasheet selected) — three sub-tabs.** **Data** shows the rows in a data table over the backing table; a **Filter** toggle reveals a **SQL query** box where you type a condition like `"column" = 'value'` and click **Apply Query**. **Details** is the datasheet's editable metadata. **Run Info** is execution history, with an **Exclude Empty Runs** checkbox to hide runs that produced no rows.
- **Empty states** — "No Datasheet found in the project", "No sources found in the project", and "You haven't selected datasheet…" (nothing selected yet).
### What every control does
| Control | What it does | Notes |
|---|---|---|
| **Datasheets** tab | Lists datasheets; select one to load the right pane | Status icon shows last-run health |
| **Sources** tab | Lists source connections (DB / spreadsheet / API) | Where a datasheet's data comes from |
| **+ Datasheet** | Opens the add-datasheet flow | See walkthrough below |
| **Filter** toggle | Reveals the SQL query box on the **Data** sub-tab | Quoted-column syntax: `"col" = 'value'` |
| **Run Info** sub-tab | Shows run history | **Exclude Empty Runs** hides no-row runs |
### The system columns
Every Datasheet carries three platform-managed **system columns** alongside your data columns. You don't create or edit them — the platform stamps them so it can track *where each row came from*:
| Column | Meaning |
|---|---|
| `_BM_STATUS` | The row's processing status (e.g. OK / pending / error) |
| `_BM_RUN_ID` | Which materialisation/refresh run produced the row |
| `_BM_JOB_ID` | Which ingestion job the row is associated with |
> **Under the hood.** The backing table is named like `DATA_SHEET_{id}_{guid}`. When you filter on the **Data** tab you are issuing SQL against that table; the same table is what an agent's SQL tool reads. The system columns let the platform reconcile rows across re-runs without duplicating them.
### Walkthrough — add a Datasheet from a source connection
1. Open `Studio ▸ Data Model ▸ Data`.
2. Click **+ Datasheet** (footer of the left rail) to open the add-datasheet dialog.
3. Give the datasheet a **name** and **description**.
4. Choose its **source**: either pick/create a **source connection** (a database, spreadsheet, or API binding — the same connections listed under the **Sources** tab), **or** point it at an existing **View** to materialise that View's columns into the table.
5. Confirm. The datasheet appears in the list with a status icon; open it and check the **Data** tab for rows and **Run Info** for the first run.
6. To add a *source connection* on its own, switch to the **Sources** tab and create one there — then it is available to bind from any datasheet.
> **Tip.** Filter on the **Data** tab to sanity-check your data *before* you wire an agent to it: if `"vendor_status" = 'active'` returns the rows you expect, the agent's SQL tool will too.
### How agents query a Datasheet
The whole point of a Datasheet is that an **agent can read it with SQL**. When you give an agent a **SQL tool** (a SQL toolkit pointed at a datasheet), the agent writes queries against the backing table to answer questions or look values up mid-task — "what's the approved credit limit for vendor `ACME-01`?" becomes a `SELECT` the agent runs itself.
This is how **structured chat** works too: an agent backed by a datasheet answers questions by querying rows rather than retrieving document chunks. You'll wire the SQL tool in [Tools & functions](/academy/a5), and see structured (data-backed) chat in [Chat & search](/academy/e4).
> **Under the hood.** An agent's *capability* is data-driven by its config: bind a `datasheet_id` and it becomes a **SQL agent**; bind a `view_id` and it becomes a search agent; bind neither and it's a general agent. The datasheet binding is literally what turns on the SQL tool.
## When to use Drive vs Datasheet vs a Collection
These three look adjacent in the menu but solve different problems. Pick by the *shape* of your data and what you need to do with it:
| Need | Use | Why |
|---|---|---|
| Store/organise **raw files** (PDFs, images, exports) | **Drive** | A file system. No schema, no querying — just files in folders. |
| **Structured rows** you'll query with SQL (lookups, feeds, flattened extracts) | **Datasheet** | A flat SQL table an agent can `SELECT` from. No documents, no lifecycle. |
| **Documents** you extract from, review, and decide on — or a corpus you answer over | **Collection** | The full typed home: schema, lifecycle, agents, surfaces. The hero object. |
Rules of thumb:
- If a human or a connector needs to **drop files** somewhere — **Drive**.
- If an agent needs to **look something up** in tabular data — **Datasheet**.
- If you need **per-record extraction, review, or Q&A** — **Collection**.
- Data often flows **Drive → (connector) → Collection → (View) → Datasheet**: files land in Drive, a connector ingests them into a Collection, a View flattens the extracted fields, and a Datasheet materialises that View for an agent to query. It can also flow back: a **Datasheet connector** ([Ingestion & connectors](/academy/d4)) re-ingests a datasheet's rows as documents, and picks up new/edited rows automatically.
## Try it yourself
1. In **Drive**, create a folder `staging`, upload two PDFs into it, then **Copy Path** on the folder. You've just prepared a target for a Drive connector ([Ingestion & connectors](/academy/d4)).
2. In **Data**, click **+ Datasheet** and create one — either materialise it from a View you already have, or bind a small spreadsheet as a source connection.
3. Open the new datasheet's **Data** tab, toggle **Filter**, and run a query like `"_BM_STATUS" = 'OK'`. Note how the three `_BM_*` system columns appear next to your own columns.
4. Open **Run Info** and tick **Exclude Empty Runs** — confirm you only see runs that produced rows.
If you got rows back from your filter, that same table is now ready for an agent's SQL tool.
## Recap
- **Drive** (`Data Model ▸ Drive`) is project **file storage**: a folder tree + file browser with upload, new-folder, move/delete, download, and copy-path actions. A **Drive connector** can pull files from it into a Collection during ingestion.
- **Datasheet** (`Data Model ▸ Data`) is a flat **SQL table** — the structured-data layer. The left rail has **Datasheets** and **Sources** tabs; a selected datasheet shows **Data** / **Details** / **Run Info** sub-tabs, with a **Filter → SQL query → Apply Query** box on Data.
- A Datasheet is either **sourced** from a DB/spreadsheet/API connection **or materialised from a View**, and always carries the system columns **`_BM_STATUS` / `_BM_RUN_ID` / `_BM_JOB_ID`**.
- Agents read a Datasheet by SQL via a **SQL tool** — the foundation of structured chat.
- Choose **Drive** for raw files, **Datasheet** for queryable rows, **Collection** for documents you process or answer over.
## Where to go next
- [Your first agent](/academy/a3) — build the worker that will use this data.
- [Tools & functions](/academy/a5) — wire a SQL tool to a Datasheet.
- [Ingestion & connectors](/academy/d4) — point a Drive connector at a Drive folder.
- [Glossary](/academy/r0) — **Drive**, **Datasheet**, **View** definitions.
---
## D6 · Search, indexes & vectorization
URL: https://www.botminds.ai/academy/d6
> Botminds Academy — Platform · Data
# Search, indexes & vectorization
> **In one line.** How a document becomes findable — chunked, embedded and indexed on arrival — and how a question becomes an answer scoped to exactly the knowledge you attached.
> **You'll be able to.** Reason about retrieval quality: why an agent finds a passage or misses it, and which kind of question needs the vector index versus the datasheet.
## Two kinds of question, two engines
Everything a user asks lands on one of two engines, and knowing which is which explains most retrieval behavior:
| Question | Engine | Example |
|---|---|---|
| **Reading** — "what does it say about X?" | The **vector index**: the query is embedded and KNN-matched against document chunks | "What is our retention policy for contractor records?" |
| **Counting** — "how many / which ones?" | The **datasheet**: SQL over structured fields | "How many contracts expire in Q3?" |
A great assistant handles both — which is why a Knowledge collection can carry a Knowledge schema feeding a [Datasheet](/academy/d5) alongside its vectorized text.
## What happens when a document lands
For a [Knowledge collection](/academy/d2), indexing is part of arrival, not a separate chore:
1. **Extract** — text comes out of the file (PDF, Office formats included). Standalone images and text-free scans go through vision/OCR page summaries when those are enabled in Knowledge settings — otherwise they fail with a clear "no readable text" reason rather than indexing garbage.
2. **Chunk** — the text is split into overlapping passages sized for retrieval.
3. **Embed** — each chunk becomes a vector using the collection's configured **Search model**.
4. **Index** — vectors land in the search index, keyed to their project and document.
From then on the document is *query-ready*: any agent with the collection attached can retrieve its passages. Updates re-index; deletions evict their vectors, and a scheduled reconciler heals gaps so the index converges with the collection even after failures.
## Index Health — watching the corpus
A Knowledge collection's **Index Health** tab is where you check that arrival actually worked. It leads with the reassuring number — *"N of M documents indexed and searchable"* — over a segmented **ready / processing / failed** bar, plus the Search model in use and a warning if anything has been processing for more than 30 minutes.
Failures are never dumped raw. A **Needs attention** list groups failed documents **by cause** — model access issue, no Search model selected, no readable text, rate-limited, timed out — each group with one plain "what to do" line and the real file names (no error dumps, no document ids). Fix the cause, then **Retry** a document, a group, or **Retry all**. Admins additionally get a **View logs** link per document that jumps to the Crew step-log timeline, where every retry attempt is visible with its full error ([Crew & evaluations](/academy/a12)).
**Reindex collection** re-chunks and re-embeds *every* document. It now asks for confirmation first, stating exactly how many documents will be re-processed: search stays available while it runs, but it re-consumes embedding quota and can take a while — reach for it only after fixing a model/config issue or to rebuild the index.
## Scope is the safety property
Retrieval is never global. When an agent answers, the KNN match is filtered to the collections attached on its **Knowledge** tab — an agent literally cannot retrieve from content you didn't attach. This is the same boundary that makes [per-audience agents](/academy/sol-search) safe: separate collections, separate agents, no leakage by construction.
## Why an agent misses a passage — a diagnosis table
| Symptom | Likely cause | Fix |
|---|---|---|
| "The documents don't contain that" — but they do | The passage exists but scored below the retrieved top-K; question phrased far from the text | Ask more specifically; keep collections focused so relevant chunks aren't crowded out |
| Answers from the wrong document | Multiple similar documents attached; retrieval is honest, attachment is too broad | Split collections by audience or domain; attach precisely |
| A freshly added document isn't found | Indexing still in flight — or it failed | Check **Index Health**: wait if it's processing, follow the grouped cause + Retry if it failed |
| Counting question answered vaguely | It went to the vector index, not the datasheet | Add a Knowledge schema so facts land in the [Datasheet](/academy/d5) |
## Practical tuning
- **Focused collections retrieve better.** Ten collections attached "just in case" dilute every query; attach what the agent's job needs.
- **Titles and structure matter.** Well-titled sections chunk into self-explanatory passages; a 40-page wall of text chunks into ambiguity.
- **Test retrieval in the playground.** Ask the exact questions your users will ask and click the citations — the fastest way to see what the index is actually returning.
## Where to go next
- The collection category that makes all this automatic: [D2 · Collection types](/academy/d2).
- The user-facing surface on top: [E4 · Chat & search experience](/academy/e4).
- Structured facts and SQL answers: [D5 · Drive & datasheet](/academy/d5).
---
## E1 · Getting oriented
URL: https://www.botminds.ai/academy/e1
> Botminds Academy — Platform · Experience
# Getting oriented
> **In one line.** How to sign in, land on the Command Deck, jump into any project, navigate the consumer app, jump in and out of Studio, and find the Lab feature-flag menu.
> **You'll be able to.** Land in any project, recognise every part of the chrome, and switch confidently between the end-user app and the builder's Studio.
> **Where this lives.** The login page, the **Command Deck** at `/`, and the top nav inside any project.
## Why it matters
From here on you are in the product, clicking real screens. The single biggest source of early confusion is navigation — builders get lost between workspaces, projects, the consumer tabs, and Studio, and waste time hunting for a screen that was one click away. This page is the map. Read it once and you'll always know where you are and how to get anywhere else.
A quick vocabulary reminder (full list in the [Glossary](/academy/r0); the agent-and-collection model is in [Core concepts](/academy/s2)):
- A **Workspace** is a tenant (the API calls it a *Subscription*). It contains projects, members, and billing.
- A **Project** is one solution — its collections, agents, and surfaces (the API calls it a *finon*). You always work *inside* one project at a time.
- **Studio** is where you *build* the solution; the **consumer app** is what your end-users *use*.
## Signing in
The login surface is at `/profile/login`. It is **per-tenant skinned** — the platform picks a login layout from a family of components (a plain default, plus several customer-branded ones) based on the tenant's configuration. The fields and flow are the same; only the branding changes.
| Control | What it does | Notes |
|---|---|---|
| **Sign in** | Authenticates and lands you on the **Command Deck** at `/`. | Email/password is the default path for most tenants. |
| **Forgot password?** | Sends a reset link (`/profile/resetpassword`). | |
| **SSO / Okta** | Federated login (`/profile/okta`, `/profile/external-login`). | Only shown when the tenant has it configured. |
| **2FA / OTP** | A second-factor step shown inline during login (an OTP entry / QR-enrolment modal — no separate route). | Only appears if the tenant enforces it. |
> **Tip.** If your screen looks different from a colleague's — different colours, a customer logo, an SSO-only button — that's expected. The login page is the most heavily branded surface on the platform.
> **Watch out.** Some tenants ship with a default password and a **forced password-change** guard. If you're prompted to set a new password immediately after first sign-in, that's the guard — set a strong one and continue.
## The Command Deck — where you land
Signing in drops you on the **Command Deck** at `/` — an intent-first home that spans *all* your workspaces. Instead of a wall of workspace folders, it asks *what do you want to do?* (The old workspace-wall landing is retired on the main host; subdomain-hosted tenants keep the classic per-workspace project listing.)
| Section | What it does | Notes |
|---|---|---|
| **Command box** | The "What do you want to do?" bar — click it, or press **Ctrl K / ⌘K** from anywhere, to open the global command palette. | Results are grouped **Actions · Navigate · Projects · Workspaces**; jump to any project or run a command without touching the mouse. |
| **Jump back in** | Cards for your recently visited projects, across every workspace (each carries a workspace colour dot + status). | Click a card to land back in that project. |
| **Needs you** | Your live queue — review tasks and sign-offs waiting on *you*, plus unread notifications. | Rows clear themselves as you act on them. |
| **Browse everything →** | Opens the **Browse (Atlas) overlay** — the full workspace-and-project browser (below). | Also reachable at `/workspaces`. |
A brand-new account with no workspaces sees a welcome state instead, with outcome chips: create a project, open the Academy, ask Piper for a tour.
### The Browse (Atlas) overlay — the full inventory
**Browse everything** (or navigating to `/workspaces`) opens the Atlas overlay: one search box across **all workspaces and projects**, above a two-pane browser — workspaces on the left, the selected workspace's projects on the right.
| Control | What it does | Notes |
|---|---|---|
| **Search box** | One query across workspaces *and* projects. | **↑/↓** to move, **↵** to open, **Esc** to close. |
| **Workspace row** | Click to load its projects on the right. | Shows a project count; each row carries **★ pin** and **⚙ settings** (→ `/{workspace}/_settings`). |
| **Project card** | Click to **open** the project — drops you into its landing surface. | Shows a document count and a *recent* chip; the landing surface may be Documents, a dashboard, or another configured page. |
| **+ Project** | Create a project in the selected workspace. | Admins/creators. |
| **+ Workspace** | Opens **Create Workspace**. | Super/system admins only. |
> **Tip.** Old bookmarks keep working: `/{workspace}` now redirects to `/workspaces?ws=` — the Browse overlay scoped to that one workspace.
**Walkthrough — open your first project.** Sign in; you land on the deck. If your project is in **Jump back in**, click its card. Otherwise press **Ctrl K** and type its name, or click **Browse everything**, pick the workspace on the left, then click the project card. You're now inside the project, looking at its consumer landing surface.
> **Tip.** The **logo** (top-left) is the universal escape hatch: from anywhere in the product it returns you to the Command Deck. The thin spark bar under the nav is the click-feedback indicator — every navigation visibly reacts while the next screen loads.
### Create Project and Create Workspace
You usually open an existing project. When you do need new ones:
- **Create Project** launches a guided create-project flow — from the Atlas overlay's **+ Project** (in the selected workspace), or the palette's **Create project…** action (on the deck it first asks you to pick the workspace). You can also start one from a Hub solution. The mechanics live in [Studio orientation](/academy/s2).
- **Create Workspace** (**+ Workspace** in the Atlas overlay, super/system admins only) opens a small dialog:
| Field | Rule |
|---|---|
| **Workspace Name** | lowercase letters / digits / underscore; no leading underscore; no spaces. |
| **Subscription Type** | radio — *General* or *Demo/Customer* (restricted to certain admin roles). |
| **Template** | optional — pick a starter UI config when more than one exists. |
**Create** is disabled until the name is valid, and shows "Creating…" while it provisions.
> **Watch out.** Creating a workspace is a tenant-level act, usually done once by an administrator. As a solution builder you'll almost always work *inside* a workspace someone has already set up — you create **projects**, not workspaces.
## Inside a project: the consumer navigation
Open a project and the **top navigation bar** is the constant chrome around everything. It has three clusters: **left** (identity / how you got here), **centre** (the configurable tab row), and **right** (tools and your account).
**Left cluster**
| Control | What it does | Notes |
|---|---|---|
| **Workspace logo** | The universal escape hatch — returns you to the **Command Deck** at `/` from anywhere. | Anonymous (public-share) sessions keep their scoped landing instead. |
| **Project name** | Click returns you to the project's landing surface. | When a left sidebar is active, this region shows the active **View** name plus a help-info icon. |
**Centre — the tab row** (the heart of the consumer app)
| Tab | Goes to | What it's for |
|---|---|---|
| **Overview / Dashboard** | `_dashboard` | Project analytics widgets. One button per configured dashboard. See [Dashboards and inbox](/academy/e5). |
| **Chat** | `_chat` | Ask questions over the project, grounded in cited documents. |
| **Search** | `_search` | Natural-language / semantic search across the project. |
| **Documents** | `_view/` | The document table — the consumer's main work surface. See [Document workspace](/academy/e2). |
| **Collection / View tabs** | `_view/` | One tab per collection and per saved **View** (a saved column+filter slice). |
| **External Links** | (a configured URL) | Opens a link the project author wired in. |
| **More** (overflow menu) | — | Appears when there are more than ~6 tabs; selecting an item promotes it into the visible row. |
> **Watch out — the tab row is configurable and role-gated.** What you see is *not* fixed. Each tab appears only when the project enables it **and** your role allows it. A project can hide Chat, Search, or Dashboard entirely; a "client" role sees fewer tabs than a builder. Don't assume a tab is missing because it's broken — it may simply be turned off for this project or your role. [Security and governance](/academy/g1) covers who-sees-what.
> **Under the hood.** The platform's word for a Collection in some consumer code is *Entity* (`RelationalEntities`), and a tab labelled **Entity** in a generic project is really a collection tab. We always say **Collection**. The default unnamed View is hidden from the tab row, which is why you see *Documents* rather than a "Default" tab.
**Right cluster**
| Control | What it does | Notes |
|---|---|---|
| **Co-pilot** | Opens a project-level chat assistant (modal, dock, or floating). | Only when the project enables it. |
| **Studio** (gear icon) | Enters Studio for this project (the builder). | Admins/creators only; hidden if the project disables Studio. |
| **Share** (link icon) | Copies the current page URL to share. | Only when share links are enabled. |
| **Notifications** (bell icon) | Opens a notifications popover; a green dot marks new items. | |
| **Account menu** (avatar) | Your account menu — see below. | |
**The account menu.** Click your avatar at the far right:
- **Your name** — your **Profile** (`/profile`): name, mobile, avatar, change password.
- **Admin** — the platform Admin shell (`/admin`). **Super/system admins only.**
- **Strangler flags** — the **Lab** feature-flag submenu. **Super/system admins only** — covered below.
- **Version** — the current build stamp.
- **Logout** — signs out (warns you first if an automation is still running).
> **Flag-gated.** A **"Try the new home"** link may appear in this cluster. It switches you to the emerging **Agent OS** landing, and only shows when the tenant's `agentOsDemo` environment flag *and* the per-browser `agentOsTryNewHome` lab flag are both on. Agent OS is still rolling out — see [What is Botminds](/academy/s1). Don't build on it yet.
**The project switcher.** There is **no dedicated project dropdown** in the top bar. To switch projects, press **Ctrl K / ⌘K** and type the project's name — the palette jumps you straight there — or click the **logo** (far left) to return to the Command Deck and pick from **Jump back in** or **Browse**. Either round-trip *is* the project switcher — simple and always available.
## Studio vs consumer — and how to move between them
You'll cross this boundary constantly, so make it a reflex.
| | **Consumer app** | **Studio** |
|---|---|---|
| **URL** | `///…` | `///studio/…` |
| **For** | *Doing* the work — review documents, chat, search, dashboards. | *Building* the solution — define collections, agents, pipelines, security. |
| **Who** | Everyone with access. | Builders (admins/creators). |
| **Enter via** | Open a project from the deck (**Jump back in**, **Ctrl K**, or **Browse**); or the **Project name** in the nav. | The **Studio** gear, top-right in the consumer nav. |
| **Leave via** | — | Studio's own chrome links back to the consumer app; the logo returns to the deck. |
This is the single picture to keep in your head — everything you'll touch hangs off it:
```
┌──────────────────────────────────────┐
SIGN IN ─────> │ COMMAND DECK (/) │
/profile/login │ Ctrl K palette · Jump back in │
│ Needs you · Browse (Atlas) overlay │
└───────────────┬──────────────────────┘
open a project │ (logo = back to the deck)
┌───────────────────────┴─────────────────────────────┐
│ PROJECT │
│ ///... │
│ │
│ ┌─ CONSUMER APP ───────────┐ ┌─ STUDIO ─────────┐ │
│ │ top-nav tabs: │ │ left rail: │ │
│ │ Overview / Dashboard │<>│ Agent Builder │ │
│ │ Chat · Search │ │ Data Model │ │
│ │ Documents │ │ Connectors │ │
│ │ Collection / View tabs │ │ AI / Assets │ │
│ │ Inbox (human queue) │ │ Search · Chat │ │
│ └──────────────────────────┘ │ Intelligence │ │
│ ┌─ AGENT OS (emerging) ────┐ │ Security · Hubs │ │
│ │ agent-first landing home │ └──────────────────┘ │
│ └──────────────────────────┘ │
└────────────┬───────────────────────┬────────────────┘
│ │
account menu (avatar) account menu (super/system admin)
/profile — your account /admin — platform admin shell
Strangler flags (the Lab)
plus: Notifications · Share · Co-pilot
```
## Roles in brief — who sees what
The platform is heavily role-gated, so two people can open the *same* project and see different tabs, buttons, and menus. The big tiers:
| Tier | Sees roughly |
|---|---|
| **Client / consumer role** | The narrowest view — documents, maybe chat/search; **no** Studio, no dashboards by default, no admin. |
| **Builder / creator** | The consumer app **plus** the Studio door and most build surfaces. This is you. |
| **Subscription admin** | Builder, plus workspace settings (members, module config). |
| **Super / system admin** | Everything, including the **Admin** shell and the **Lab** flag menu. |
This is a sketch, not the contract. The exact, permission-by-permission breakdown — and how a workspace admin tunes it — is [Security and governance](/academy/g1).
## The Lab — feature-flag menu
The platform ships new surfaces behind **feature flags** (internally "strangler" flags) so they can roll out safely. The **Lab** menu is where an admin flips them on or off to preview or fall back.
**Where it is and who can see it.** Account menu (avatar) → **Strangler flags**. It is gated to **super/system admins** — the same gate as the **Admin** link. Subscription admins and consumers do **not** see it.
| Element | What it does |
|---|---|
| **Group headers** | Flags are grouped: *Ingestion, Studio & Collections, Runtime & API, Diagnostics, Session*. |
| **Row toggle** (on/off dot) | Each row shows its on-state, title, and a "default ON/OFF" tag (marked when you've overridden it). Hover for a tooltip explaining what it is, what on/off mean, when it applies, and safety. |
| **Override-count badge** | How many flags differ from this environment's baseline. |
| **Reset all to defaults** | Clears every override you've set. |
**To toggle a flag:** open the account menu, hover **Strangler flags**, find the flag (groups are in a fixed order; read the hover tooltip if unsure), and click its row. The change takes effect immediately (some flags note "applies after reload").
> **Watch out — overrides are per-browser, not per-user or per-project.** A flag you flip is stored only in *your* browser's local storage (`bm_lab_`) — nothing is sent to the server. Your teammate, your phone, and your other laptop will not see the change. This is for previewing and debugging, not for configuring the product for others.
- **Precedence** (high → low): a `?ff_=1|0` URL override → your per-browser setting → the server baseline → the baked default.
- **No silent drift.** When the server build changes, all your per-browser overrides are wiped, so a stale flag can't haunt you across releases. Setting a flag *equal* to the baseline removes the override rather than pinning it.
- **Debug Mode** (`enableDebugMode`) is session-only and resets on every page reload.
Most flags are **ON-by-default kill-switches** — OFF restores the previous proven behaviour byte-for-byte. The handful worth knowing as a builder:
| Flag | Group | Default | What it gives you |
|---|---|---|---|
| `knowledgeCollections` | Studio & Collections | ON | Knowledge-corpus collections: purpose picker, auto-indexing, an Index Health tab. |
| `addDataModes` | Ingestion | ON | The per-collection **+ Add Data** launcher (Upload / Paste text / Fill a form / Connect a source). |
| `studioRailV2` | Studio & Collections | ON | The 7-section Studio left rail. |
| `newAgentBuilder` / `agentHarness` | Runtime & API | ON | The modern tabbed Agent Builder and its mirrored view-edit harness. |
| `meshDesigner` | Studio & Collections | ON | Surfaces **mesh** runnables in the XFlow designer. |
| `summaryV2` | Ingestion | ON | The redesigned document Summary panel. |
| `agentOsTryNewHome` | Runtime & API | OFF | Shows the **Try the new home** link to Agent OS (needs the env flag too). |
The complete table — all 29 flags, every group, what each turns on — lives in the Feature-Flags Reference.
## Try it yourself
With the product open:
1. Sign in and **identify your tier** from the right-cluster icons: do you see a **Studio** gear? A **Strangler flags** entry under the avatar? That tells you whether you're a builder or an admin.
2. From the deck, **open a project** (Jump back in, or **Ctrl K** and type its name), then click the **logo** to bounce back to the deck, then open it again. You've just used the project switcher.
3. Inside the project, **name three tabs** in the centre row and predict where each goes (`_chat`, `_search`, `_dashboard`, `_view/…`).
4. Click **Studio**, confirm the URL now contains `/studio/`, then navigate back to the consumer app.
## Where to go next
- [Document workspace](/academy/e2) — open a collection's document list and review a real document.
- [Studio orientation](/academy/s2) — walk the Studio left rail you glimpsed here.
- [Dashboards and inbox](/academy/e5) — the analytics and human-queue surfaces in the consumer app.
- [Security and governance](/academy/g1) — the authoritative roles-and-permissions model.
---
## E2 · Document workspace
URL: https://www.botminds.ai/academy/e2
> Botminds Academy — Platform · Experience
# Document workspace
> **In one line.** The consumer **Documents** surface — the filtered, View-driven table your end-users live in every day.
> **You'll be able to.** Read the layout, switch Views, sort/group/select rows, run bulk actions from the **Options** menu, and get a document into the system by uploading it.
> **Where this lives.** The **Documents** tab — a project's root surface (`/{subscription}/{project}/`, with the saved-View routes `_view/:viewId` underneath it).
## Why it matters
This is the screen end-users open first and close last. Everything you build in Studio — the fields you extract, the Views you define, the upload connectors — *surfaces here* as columns, tabs, and rows. If you understand the Document Workspace, you understand what your solution actually feels like to the people using it. And almost every control on it is **configurable per project and per role**, so two projects rarely look identical — knowing *which* control is *which* lets you shape that experience deliberately (see [Shaping the experience](/academy/e7)).
A note on vocabulary. A **Collection** is a typed home for one kind of record (see [Core concepts](/academy/s2)). A **View** is a *saved, filtered slice* of a collection's documents, with its own columns. The Document Workspace is where users **consume** Views; you **define** them in Studio. Keep "Lifecycle" (a document's review stages) and "XFlow" (a processing pipeline) firmly apart — neither is what this screen is.
## The Documents surface
The classic Documents surface is a two-pane split: a **filter/folder pane** on the left and the **documents table** on the right, separated by a draggable resizer. (The left/right order can be swapped per project, so don't be surprised if you see it mirrored.)
```
DOCUMENT WORKSPACE (the Documents tab)
┌───────────────────────────────────────────────────────────────────────────┐
│ TOP NAV: Logo | Project | [Overview][Chat][Search][Documents][Invoices] │
├────────────────┬──────────────────────────────────────────────────────────┤
│ FILTER PANE │ TOOLBAR: [+ Invoice] [+ Add Data] [refresh] [activity] │
│ (~20%, collap- │ [grid/table] [date range] [Options menu] │
│ ses via tune) │ chips: [Status: New x] [Date: last 30d x] │
│ ├──────────────────────────────────────────────────────────┤
│ Views / │ stats widgets (optional strip) │
│ folders ├────────────────────────────────────────────┬─────────────┤
│ date range │ DOCUMENTS TABLE (columns from active View) │ activity │
│ label / meta │ [ ] Title Status Total Date │ panel │
│ filters │ [ ] Invoice_001 New $1,240 Jun-12 │ (optional) │
│ │ [ ] Invoice_002 Approved $880 Jun-11 │ │
│ │ [ ] Invoice_003 Processing… 64% Jun-13 │ │
│ │ … rows deep-link to the document detail … │ │
└────────────────┴────────────────────────────────────────────┴─────────────┘
```
**The four regions:**
- **Top nav** — the constant project chrome. The centre tab row shows one tab per surface the project enables: **Overview/Dashboard**, **Chat**, **Search**, one **Documents/Collection** tab per collection, **plus one tab per saved View**. The active View's name also shows up near the project name. Which tabs appear is flag- and role-gated.
- **Filter pane** (left, ~20% of the width, collapsible via the **tune** toggle) — View and folder navigation, a date-range filter, and label/metadata filters. Hidden entirely on projects configured to hide it.
- **Toolbar** (top of the right pane) — actions over the whole list: add/upload, refresh, the activity panel, the grid/table switch, a date-range filter, and **Options**.
- **Documents table** (the body) — the rows themselves, with an optional right-hand **activity panel** and an optional **stats widgets** strip above.
### What every control does
| Region | Control | What it does | Notes |
|---|---|---|---|
| Filter pane | **Views / folders list** | Switch between saved Views; folder Views expand sub-menus | Each View is a saved slice; `_view/:viewId` |
| Filter pane | **Date range** | Limit the list to documents in a date window | |
| Filter pane | **Label / meta filters** | Filter rows by an extracted field's value | Drives the **filter chips** above the table |
| Filter pane | **tune** toggle | Collapse/expand the whole filter pane | Also reachable from the toolbar |
| Toolbar | **+ {Collection}** | Add one new document to this collection | Label is the collection's name, e.g. **+ Invoice** |
| Toolbar | **+ Add Data** | Open the add-data modal — upload files or connect a source | Flag-gated (the add-data launcher) |
| Toolbar | **Refresh** | Silently reload the list | Progress also updates live on its own |
| Toolbar | **Activity** toggle | Show the right-side **Active / Recent / Failed** panel | Failed items have an inline **Retry** |
| Toolbar | **grid / table** switch | Switch between the table and the card **grid** | Only when the project enables card view |
| Toolbar | **date range** | A date-range filter in the toolbar | Appears when the View's query asks for it |
| Toolbar | **Options** (vertical-dots menu) | The bulk-action + View-settings hub (see below) | Most items are role/flag-gated |
| Above table | **Filter chips** | Show applied filters; click the x to remove, or reset all | Up to 4 shown inline |
| Above table | **Stats widgets** | Summary counts/charts for the current slice | Hidden when the project hides the stats pane |
| Table | **Row** | Click to open the **document detail** page | Deep-link to `/:docId`; can be disabled per project |
| Table | **Row checkbox** | Select rows for a bulk action | Multi-select feeds the **Options** actions |
| Table | **Column header** | Sort by that column | Columns, sort, and grouping are all View-defined |
| Table | **Progress chip** | A live **"Processing… to done"** indicator per row | Climbs to 100%, then the fields appear |
| Table | **Row ⋮ menu** | Per-document actions: **Download** and **Audit trail** (plus admin-only delete) | **Audit trail** opens the document's timeline side-sheet — see [Document detail](/academy/e3) |
### The documents table, in depth
The single most important thing to understand: **the table's columns are not fixed — they come from the active View.** A View declares a display name, an icon, a column set, a sort, and a grouping. Switch View and the same documents re-render with different columns. The columns you see are largely your **extracted fields**: if your collection's schema pulls out `invoice_total`, `vendor_name`, and `due_date`, those appear as table columns (alongside built-ins like Title, Status, Score, and Date). This is the direct payoff of the schema you design in [Collections and schema](/academy/d1).
- **Sorting** — click a column header. Which columns are sortable, and the default sort, are set by the View.
- **Grouping** — rows can be grouped (e.g. by status or a lookup field); grouping is toggled from **Options** (**Enable/Disable {Collection} Grouping**) and configured by the View.
- **The progress chip** — when a document is still being worked, its row shows a live **"Processing…"** chip with a percentage that climbs in real time. When it reaches done, the extracted-field cells fill in and a status/score appears. A small **automation-pending** indicator marks rows where an agent is still running.
- **Row selection** — the leading checkbox selects rows. Selection is what most **Options** bulk actions operate on (some need at least two rows, e.g. creating a Doc Set).
- **Opening a document** — clicking a row deep-links to the **document detail** page, where the viewer and the extracted-data summary live (see [Document detail](/academy/e3)). Row deep-linking can be disabled per project.
### The Options menu — bulk actions plus View management
The **Options** menu (the vertical-dots button, top-right of the toolbar) is the workspace's command hub. It's grouped, and **almost every item is gated by your role and the project's flags** — a read-only consumer sees a short menu; an admin sees the lot. The four groups:
| Group | Items | What they're for |
|---|---|---|
| **Doc Set** | Create **{Collection} Set** (needs 2+ selected), Remove Set, Enable/Disable Set Edit | Treat several documents as one unit |
| **View settings** | Edit Columns, Edit Query (admin), Enable/Disable Row Deeplink, Edit View, **Save View**, **Save View as**, Allowed Roles, Delete View | Define and manage Views *from the consumer side* |
| **Export / assignment** | **Export** (download the list), Assign User, Assign State, Change Priority, Update {Lookup} Values, **Rescore**, **Compare {Collection}** | Move work and re-derive data in bulk |
| **Action menus** | Enable/Disable Grouping, Enable/Disable Training Mode, Show/Hide Filter Pane, Enable/Disable Download, Configure Widgets, Show/Hide Stats Pane, Update Collection Mappings (super-admin) | Toggle workspace features |
> **Tip.** **Export** downloads exactly the slice you're looking at — the current View's columns, with your filters applied. Filter first, export second, and you get a clean spreadsheet of just the documents you care about.
> **Watch out.** **Save View** *overwrites* the View you're on. To keep the original and branch off, use **Save View as** — it forks a new named View instead. **Delete View** is destructive and admin-gated.
### Saved Views — switching, folders, and where they come from
A **View** is a saved, filtered slice of a collection: a set of columns plus a filter/query, persisted together. Each non-default View shows up as its **own tab** in the top nav and lives at the route `_view/:viewId` (folder Views add a level: `_view/:folderName/:viewId`). The "Default" View is hidden from the tab row — it's the unnamed baseline.
As an end-user, switching Views is how you change what you're looking at:
1. Click a **View tab** in the top nav, or pick a View in the filter pane — the table re-renders with that View's columns and filters; the URL becomes `_view/:viewId`.
2. **Folder Views** group related Views under a sub-menu — expand the folder, then pick a View inside it.
3. To make a quick personal slice, set your filters, then **Options > Save View as** and name it. **Allowed Roles** controls who else can see a named View.
> **Under the hood.** A View is stored as a `ColumnViewTemplate` (`ColumnViewId`); the `_view/:viewId` routes *are* those saved templates. "Save View as" forks a new template.
**Builders define Views in Studio; users consume them here.** The handful of View-edit items in the **Options** menu let admins tweak a View from the consumer side, but the deliberate work of designing Views — which columns, which default filters, which roles — is a Studio task; that's [Shaping the experience](/academy/e7). For now: know that the columns and tabs you see were *defined elsewhere*, and that you can switch between them freely.
## Getting a document in: the upload flow
A document enters the workspace one of two ways from the UI — and many more via connectors, which you'll meet later.
1. Click **+ {Collection}** (e.g. **+ Invoice**) for a single document, or **+ Add Data** to open the add-data modal, *or* simply **drag files onto the list** — a full-pane **"Drop files to upload"** target appears while you drag.
2. The file uploads to the backend (large files are chunked). A new row appears immediately with a **"Processing…"** chip.
3. The platform ingests it — fetch, assemble, then the intake agent extracts fields against the collection's schema — streaming progress the whole time. The chip climbs to 100%.
4. The extracted-field cells fill in, a status/score appears, and (for a Processing collection) the document enters its **Lifecycle** at the first stage.
> **Under the hood.** That fetch, assemble, extract sequence is the collection's **ingestion** pipeline. "Ingestion" is the umbrella term for getting a document from raw bytes to a fully indexed, field-extracted record. You don't configure it here — you watch its result.
You then click the row to open the **document detail** page and review what was extracted ([Document detail](/academy/e3)). To *ask questions* across many documents instead of opening one, use **Chat** and **Search** ([Chat and search](/academy/e4)).
## Behaviours to know
- **Real-time progress.** Rows update live — the **"Processing…"** chip climbs, fields appear, status flips — without a manual refresh. The **Activity** panel surfaces **Active / Recent / Failed** runs, and **Failed** rows offer an inline **Retry**.
- **Heavy flag- and role-gating.** Which tabs, toolbar buttons, and **Options** items appear depends on the project's configuration *and* your role. A client/anonymous role sees far less than an admin. If a control on this page isn't on your screen, it's almost certainly gated off for your project or role — not missing. This is by design; shaping it is [Shaping the experience](/academy/e7).
- **Grid vs table.** Card-view projects render a **grid** instead of the table; the **grid/table** toggle switches between them when both are enabled.
- **The Inbox is a special case.** A human work-queue collection renders an **Inbox list** here instead of the standard table — same surface, different body. (Covered with Lifecycle/review.)
- **Empty states.** A brand-new or fully-filtered-out View shows an empty list; a project with no documents yet shows nothing until you upload one. If you filtered everything away, clear the **chips** (reset-all) to get your rows back.
> **Flag-gated.** The **+ Add Data** launcher, the card **grid** view, the **activity** panel, **Similar Documents**, and most **Options** bulk actions are individually gated. Treat their presence as project-specific, never guaranteed.
## Try it yourself
On a project that has at least one document collection:
1. Open the **Documents** tab and read the **column headers** — each extracted-field column is a field from your schema. Note two of them.
2. Apply a **label filter** and a **date range** in the filter pane; watch the **chips** appear.
3. Sort by a column, then switch to a different **View tab** and notice the columns change. The URL is now `_view/:viewId`.
4. **Options > Save View as**, name it (e.g. *My recent invoices*), confirm it appears as a new tab, then switch back.
5. **Upload** a document (drag a file onto the list) and watch the **"Processing…"** chip climb to done. When the fields appear, click the row to peek at the detail page.
6. Open **Options** and note which items are greyed or absent — that's your role and the project's flags talking.
If the columns made sense as "my extracted fields", and you could switch Views and upload a doc, you own this screen.
## Where to go next
- [Document detail](/academy/e3) — open a row: the viewer, the extracted-data summary, and the review/correct loop.
- [Chat and search](/academy/e4) — ask questions across documents instead of reading them one by one.
- [Shaping the experience](/academy/e7) — define the Views, columns, and flags that *make* this workspace look the way it does.
- [Collections and schema](/academy/d1) — where the columns and fields come from.
---
## E3 · Document detail
URL: https://www.botminds.ai/academy/e3
> Botminds Academy — Platform · Experience
# Document detail
> **In one line.** The single-document page where a person reads one document and reviews, corrects, and signs off on what the agent extracted.
> **You'll be able to.** Open any document, navigate its pages, read every extracted field next to its source, fix a wrong value, and advance the document through its review stage.
> **Where this lives.** Consumer app — open any document from the list; route `//:docId`.
## Why it matters
The document table ([Document workspace](/academy/e2)) is the *list*. This page is the *work*. It is where the human-in-the-loop part of "AI recommends, two humans confirm" actually happens: a person opens a document, sees the agent's extracted fields side-by-side with the original, corrects anything wrong, and pushes the document forward in its lifecycle. Every correction you make here is also a teaching signal — it is the raw material the [AI Builder](/academy/a9) later trains on. Get comfortable here; it is the page your reviewers will live in.
> **Under the hood.** The code calls this the **Campaign page** (`modules/documents/pages/campaign-page/`). You will never see that word in the UI — we call it the **Document Detail**.
## The route
| You navigate to… | URL shape | Opens at… |
|---|---|---|
| A document | `//:docId` | the document, first page |
| A specific page | `//:docId/:pn` | page `:pn` |
| A specific segment | `//:docId/:pn/:segId` | page `:pn`, scrolled to segment `:segId` |
The deeper forms are how **deep-links** work. When chat cites a source ([Chat & search](/academy/e4)) or you click an extracted field, the platform builds one of these URLs so the document opens *exactly* on the relevant page or segment — not just "the document somewhere".
> **Watch out.** Access is guarded (`DocumentAccessActiveGuard`). If a document has been deactivated or you lack the role to see it, the page refuses to load rather than showing a blank viewer. That is expected, not a bug.
## The layout
The page is a **split view**: the document itself on one side, everything the agent produced on the other. A draggable divider (the resizer) sets the balance; you can collapse either side to focus.
```
DOCUMENT DETAIL — split view (//:docId)
+--------------------------------------------------------------------------+
| Back [Invoice_001 v][Invoice_002] find < Page 3 of 12 > ... more | <- doc header
+---------------------------------------+----------------------------------+
| DOCUMENT PANE (viewer / annotator) | SUMMARY PANE |
| +---------------------------------+ | [Summary][Training][Page Prev] | <- tabs
| | PDF / HTML / docx / xlsx / image| | filter v |
| | ## highlighted extraction ## |<-+-> Vendor : Acme Corp ->seg | <- click field
| | (click a field -> it scrolls & | | Invoice No : INV-001 ->seg | jumps the
| | highlights its source here) | | Total : $1,240.00 (edit) | viewer
| | | | Date : 2026-06-11 |
| +---------------------------------+ | > per-doc dashboard widgets |
| [workflow stepper / action pane] | | <- stage advance
+---------------------------------------+----------------------------------+
```
> **Tip.** If the panes feel backwards (summary on the left), your project has the **`SwapSummaryAndDocumentPane`** option set. The *function* of each pane is unchanged — only the side. Some projects also swap them in the list view; both are intentional.
Around the split you may also see, when the project enables them:
- A thin **document info bar** across the top (`document-info-bar`) with title/metadata.
- A **Doc-Set sidebar** when this document is part of a Doc Set — a group of documents treated as one (see [Document workspace](/academy/e2)).
- An **in-page chat** pane and a collapsible **doc-search results** strip (covered under the Summary tabs and [Chat & search](/academy/e4)).
- For "generated content" collections, a **rich-text editor** instead of a read-only viewer.
- For entity-dashboard documents, a **dashboard** renders in place of the viewer.
This page teaches the common case — a real document in a Processing collection. The specialised renderers are flagged where they appear.
> **Under the hood.** A solution can also *compose its own* document page from **document workbench cards** on an experience page — including a native summary-pane card (no iframes, per-card skins, and the same review loop: inline edit, comments, formula fields) — see [Pages & cards](/academy/e6). Same values, same save paths; only the layout is yours.
## Document pane — the viewer
### What every control does
The pane has a header row of controls and a viewer body that changes with the file type.
| Control | What it does | Notes |
|---|---|---|
| **Back / Close** | Return to the document list, or close an embedded view | |
| **Document tabs** | Pinned documents as tabs, with an overflow menu of the rest | Lets you flip between several open documents without going back to the list |
| **Copy DocId / Title** | Copies the document's id or title to the clipboard | Handy for support tickets and deep-links |
| **In-doc search** | Find text inside *this* document | Appears when the **DocumentSearch** action is enabled |
| **Audit trail** (clock icon) | Opens the document's **timeline side-sheet** — everything that ever happened to this document | Also in each row's ⋮ menu on the list; see "Advancing the lifecycle" below |
| **Prev / Next** | Move to the previous/next document in the list | Can be **locked** until you complete the current one (`documentCompletionLock`) — a deliberate "finish before you move on" guard |
| **Page selector** | A "Page X of N" dropdown you can type into to jump | The fastest way around a long PDF |
| **Page up / down** | Step a page at a time | Used in image/annotation mode |
| **Add Document** | Upload another document into the collection without leaving | |
| **Similar Documents** | Shows documents like this one | Only with **`EnableSimilarDocuments`** |
| **Document Chat toggle** | Opens the in-page chat *about this document* | See [Chat & search](/academy/e4) |
| **Workflow collapse/expand** | Show or hide the stage/action stepper | See "Advancing the lifecycle" below |
| **Highlight-Copy toggle** | Lets you select-and-copy highlighted regions | |
| **Training Mode toggle** | Switches into the correct-and-teach annotation mode | Feeds the trainable model — [AI Builder](/academy/a9) |
| **More Options** (tune) | Annotation-mode and viewer options | |
| **Expand / Minimize** | Give the viewer the whole width, or shrink it back | |
> **Flag-gated.** **Similar Documents** (`EnableSimilarDocuments`), in-doc search (`DocumentSearch`), and the floating agent-chat widget (`ShowFloatingChat`) each appear only when their option is set on the project. If you don't see one, your project hasn't enabled it.
### File-type dispatch
The viewer picks a renderer from the file type — you don't choose it:
| File type | Renderer | What you get |
|---|---|---|
| PDF, HTML, structured-row | The **annotator** (`html-panel`) | Page view with highlightable, clickable segments |
| `.docx` | Docx viewer | Rendered document |
| `.xlsx` | Spreadsheet viewer | Rendered sheet |
| Image (png/jpg/…) | Image viewer, plus a thumbnail rail in annotation mode | Zoomable image with page thumbnails |
| Unsupported | Not-found message plus **Download** | Always at least downloadable |
The PDF/HTML **annotator** is the one to know. Its page is divided into **segments** — the highlightable blocks the platform parses the document into. Each extracted field is anchored to one of these segments, which is what makes the next part work.
### Deep-link highlight — the field-to-source link
This is the single most important interaction on the page:
1. In the Summary pane, click an extracted value — say **Total : $1,240.00**.
2. The viewer scrolls to the exact segment that value came from and **highlights** it.
The highlight is colour-matched to the field (a segment-colour pipe drives it). The reverse is also wired: opening the page at `/:docId/:pn/:segId` lands you on that segment directly. This is how a reviewer verifies an extraction in one click instead of hunting through twelve pages — *the agent shows its work.*
> **Tip.** Always click through a few fields to their source before approving a document. The highlight tells you *where* the agent read the value, which is the fastest way to catch a mis-read (e.g. it grabbed a subtotal instead of the grand total).
### Behaviours to know (viewer)
- **Loading skeleton.** The viewer shows a skeleton until the file URL is ready; large files take a moment.
- **Completion lock.** When **Next** is locked, finish the current document's required action first — the lock releases when the stage advances.
- **Live updates.** If you open a document while it is still **Processing…**, the viewer and fields fill in as the agent finishes — you do not need to refresh.
## Summary pane — reading and correcting extracted data
This is where the agent's output lives, in a tabbed pane. The fields you see here are defined by the collection's schema — [Collections & schema](/academy/d1).
| Tab | What it shows | When it appears |
|---|---|---|
| **Summary** | The extracted-field list — every label key → value, each anchored to a source segment | Always |
| **Training** | The correct-and-teach annotation surface (with a "create taxonomy" empty state if no schema exists yet) | In **Training Mode** |
| **Page Preview** | The document's pages grouped by the labels found on them | When enabled |
| **Custom dashboard tab(s)** | Per-document dashboard widgets you (or an admin) pin in | When the project defines per-doc dashboards |
Custom dashboard tabs are pinnable and, for admins, editable — rename, set auto-refresh, add a widget, save. The tab's overflow menu offers an "app store" to pick or create a dashboard, and edit/delete (admin only).
### The extracted-field list (Summary tab)
At the top is a **filter** box (`search-filter`) to narrow a long field list. Below it, each field is one row showing the **field name**, its **value**, and a link back to its **source segment**. Where the platform reports a value as low-confidence or mismatched, it is **flagged** so your eye goes straight to the fields that need a human.
> **Under the hood.** Every extracted value carries a **confidence** score (`0..1`, stored in `document_attributes`). That number is what marks a field "needs review" and what routes a whole document to the Inbox queue. You don't set it — the extractor does — but it is why some fields shout for attention and others don't. See [Core concepts](/academy/s2).
### The review-and-correct loop
This is the core task of the page:
1. **Read** the flagged (low-confidence) fields first — they're the ones the agent is unsure of.
2. **Verify** each by clicking its value to highlight the source in the viewer.
3. **Correct** a wrong value by editing it in place; your edit **saves back to the label**.
4. **Re-derive** dependent values when needed: **Update {Lookup} Values** recomputes lookup-driven fields, and **Rescore** re-runs scoring against the corrected data. (These also live in the list-view overflow menu for bulk use — see [Document workspace](/academy/e2).)
5. **Advance** the document once you're satisfied (next section).
Every correction is captured. Beyond fixing *this* document, those corrections are the labelled examples the **trainable extraction model** (the "AI Model", distinct from the LLM) learns from — so the agent extracts that field better next time. **Training Mode** (the viewer toggle and the **Training** tab) is the dedicated surface for doing this deliberately. The full training loop — how corrections become a better model, and how to read prediction reports — is [AI Builder](/academy/a9).
> **Role-gated.** A **subscription-viewer** role gets a **read-only** summary — they can read every field but cannot edit, correct, or advance. Editing requires a reviewer/annotator role. If your fields won't edit, check your role before assuming a bug.
Below the field list, **per-document dashboard widgets** (`widgets-pane`) render any collection-defined metrics for this one document.
## Advancing the lifecycle — the action pane
A Processing document doesn't just get read — it gets **moved through its review stages** (Intake → AI Processing → AI Recommendation → L1 Review → L2 Approval → Approved/Declined; see [Taxonomy & lifecycle](/academy/d3)). The page surfaces this as a **workflow action pane** — a stepper down one side (`left-action-pane` / `right-action-pane`), shown in full-focus mode or whenever the document's stage is configured for it.
From the action pane a reviewer performs the **stage transition** — the platform's word for "approve and send to the next stage", "send back / Needs Info", or "reject". Which actions you see depends on:
- **The stage** the document is in (an L1 reviewer sees different choices than an L2 approver).
- **Your role** (each transition is role-gated — this is the "two humans confirm" rule made real).
Every transition is written to the document's **audit trail**; a "decision" is simply read back from that trail (there is no separate decision object). Advancing a document is exactly how it leaves your **Inbox** review queue ([Dashboards & inbox](/academy/e5)) — the Inbox *is* a collection of documents waiting at a stage, and acting here removes it from that queue.
You can read that whole story yourself: the **Audit trail** button (clock icon in the document header; also in a row's ⋮ menu on the list) opens a side-sheet **timeline** of everything that happened to this document — uploads, agent runs, human edits, stage moves, downloads — grouped by phase (ingestion, automated processing, human review), each event attributed to its actor (**human / agent / system / API key**) with expandable before/after detail and filters. External systems can pull the same trail over the [Runtime API](/academy/v1).
> **Watch out.** Stage transitions are the consequential clicks on this page. **Reject** and **Approve** are usually irreversible by you (they hand the document to the next stage or close it out). Verify your corrected fields *before* you advance, not after.
### Other document actions
Depending on the project's enabled **DocumentActions**, you may also have:
| Action | What it does | Notes |
|---|---|---|
| **Download** | Download the original file | Can be disabled per project (`Enable/Disable Download`) |
| **Export** | Export this document's extracted data | Bulk export is in the list overflow menu |
| **Reprocess / Rescore** | Re-run extraction / re-score against the current schema | Use after a schema change or a correction |
| **Document Chat** | Ask questions about this document | [Chat & search](/academy/e4) |
| **Similar Documents** | Find look-alikes | Flag-gated |
Because actions are flag- and role-driven, two reviewers on differently-configured projects can see different buttons here. That is by design — see [Document workspace](/academy/e2) for how a project decides which **DocumentActions** to expose.
## Behaviours to know
- **Live as it processes.** Open a still-processing document and watch fields appear and the progress settle without a refresh — the page streams updates.
- **Everything is gated.** Tabs, action buttons, and even editability depend on `selectedBot.*` flags **and** your role. "I don't have that button" usually means "not enabled / not my role", not "broken".
- **Empty / processing states.** Each pane shows a **skeleton** until `selectedDoc` loads; Training Mode shows a *create-taxonomy* empty state when the collection has no schema yet.
- **Guided tour.** Some projects attach a walkthrough (``) that points out these controls the first time you arrive.
## Try it yourself
On a Processing collection with at least one extracted document:
1. From the document list, click any row to open it at `//:docId`.
2. In the **Summary** tab, find a field and **click its value** — confirm the viewer scrolls and highlights the source segment.
3. Use the **page selector** to jump to "Page X of N", then come back.
4. Pick a low-confidence (flagged) field, click through to verify it against the source, then **edit the value** and watch it save.
5. Run **Rescore** (or **Update {Lookup} Values**) and note any dependent fields change.
6. Open the **workflow action pane** and read — *don't necessarily click* — the available stage transitions for your role. Notice they match the document's current stage.
7. *(Optional, if you have a reviewer role on a test document)* advance the document one stage and confirm it leaves your Inbox.
## Recap
- The **Document Detail** (`//:docId`, code name *Campaign page*) is a **split view**: the **document pane** (viewer/annotator) and the **summary pane** (extracted data).
- The viewer **dispatches by file type** (PDF/HTML annotator, docx, xlsx, image, or download-only) and supports page navigation, segments, and **deep-link highlights**.
- Clicking an extracted field **highlights its source segment** — the agent shows its work; the reverse `/:docId/:pn/:segId` deep-link lands you on a segment directly.
- The **Summary** tab lists every extracted field with its value, source link, and **confidence flag**; you **edit in place to correct**, and **Rescore / Update Lookup** re-derive dependents.
- Corrections feed the **trainable model** — Training Mode here, the full loop in [AI Builder](/academy/a9).
- The **action pane** performs **stage transitions** (role- and stage-gated, audit-logged), which is how a document advances its lifecycle and leaves the Inbox.
- The **Audit trail** button opens a per-document **timeline side-sheet** — phase-grouped, actor-attributed, with before/after detail.
- Almost everything is **flag- and role-gated** and updates **live** as processing finishes.
## Where to go next
- [Chat & search](/academy/e4) — ask questions over documents and follow the citations that deep-link straight back to this page.
- [Dashboards & inbox](/academy/e5) — the review *queue* that feeds this page.
- [Taxonomy & lifecycle](/academy/d3) — design the stages the action pane advances through.
- [AI Builder](/academy/a9) — where your corrections become a better model.
---
## E4 · Chat & search experience
URL: https://www.botminds.ai/academy/e4
> Botminds Academy — Platform · Experience
# Chat & search experience
> **In one line.** The two ways an end-user asks questions over their documents — conversational **Chat** (with cited answers) and query-driven **Search** (ranked results) — and how a builder turns them on.
> **You'll be able to.** Walk a user through asking a grounded, cited question; read every control on the Chat and Search surfaces; and know which builder switch enables each.
> **Where this lives.** Consumer app: the **Chat** tab (`App ▸ Chat`) and the **Search** tab (`App ▸ Search`). Builder config is in Studio — see [Shaping the experience](/academy/e7).
## Why it matters
The document pages ([Document workspace](/academy/e2), [Document detail](/academy/e3)) were about *processing* documents — extracting fields, moving them through review. This is the other half of the platform: letting people **ask questions** of a body of documents and get answers back. That is what a **Knowledge collection** exists for. There are exactly two surfaces for it, and they answer different needs:
| | **Chat** | **Search** |
|---|---|---|
| **Shape** | A conversation — you ask, it answers, you follow up | A query box — you ask once, you get a ranked list |
| **Answer** | A written answer, **grounded with citations** back to source documents | A list of matching documents/passages, with the best answer highlighted |
| **Best for** | "Explain it to me", "compare these two policies", multi-step reasoning | "Find me the document that says X", scanning many hits |
| **Memory** | Multi-turn — it remembers the conversation | Stateless per query (but keeps a **search history**) |
Same underlying retrieval; different end-user experience. Teach a user *Chat* when they want an answer in words, *Search* when they want to find and open the right document.
> **Status — coming soon / by design.** Knowledge collections — and the *auto-vectorise-on-ingest* that makes a document answerable the moment it lands — are **partly forward-looking** in the current build (see the callout in [What is Botminds](/academy/s1)). The Chat and Search surfaces below are **shipped and live**; what is still rolling out is the automatic "every doc auto-becomes knowledge" wiring. Until then a builder may need to attach knowledge and run vectorisation deliberately ([Collections & schema](/academy/d1)).
## Chat
> **One engine, four places.** The platform has *one* chat engine that surfaces in several containers: the full-page **Chat** tab, a **Project Co-pilot** modal launched from the nav, an embedded **doc-chat** pane on a single document, and a **floating agent widget**. They share the same controls — learn it once here and you know all four. (The retired global "Piper" assistant is dormant; the newer **Global Co-pilot dock** is its replacement.)
### Layout
```
CHAT (App > Chat)
+---------------+----------------------------------------------------------+
| CONVERSATION | +- You ---------------------------------------------+ |
| RAIL | | Which of our policies cover remote work? | |
| + New chat | +---------------------------------------------------+ |
| Search chats | +- Assistant ---------------------------------------+ |
| ----------- | | Three policies address remote work ... [1][2] | |
| Today | | References: [1] Remote-Work.pdf p.3 | |
| . Remote... | | [2] Travel-Policy.pdf p.1 | |
| . Leave... | | up / down copy speak | |
| Yesterday | +---------------------------------------------------+ |
| . Expenses | Follow-ups: [ Does it cover contractors? ] |
| ----------- | thinking... 62% (Agent Build Log >) |
| profile | +---------------------------------------------------+ |
| | | Ask a question... [Send] | |
+---------------+--+---------------------------------------------------+---+
```
- **Conversation rail** (left) — **+ New chat**, **Search chats**, and the **history** of past conversations grouped by day. A user profile link sits at the foot.
- **Message thread** (centre) — alternating **you** bubbles and **assistant** bubbles.
- **Composer** (bottom) — the question box, with **Send**. On an empty chat it shows **suggested/default questions** to get the user started.
### What every control does
| Control | What it does | Notes |
|---|---|---|
| **Ask a question** box | Type a question, press **Send** | On an empty chat, **suggested questions** (the project's **default questions**) appear above/in the box as one-click starters |
| Assistant answer | A written, streaming answer | Renders rich content: markdown, **tables** (with CSV export), **charts**, code blocks |
| **References** chips | Numbered **citations** — `[1] [2] …` — one per source document | Clicking a chip **deep-links into the document at the cited page**. This is *how chat proves its answer.* |
| **Thumbs up / down** feedback | Rate an answer | Plus **copy** and **speak** (read aloud) on each answer. Feedback trains/flags quality. |
| **Follow-up** chips | Suggested next questions | One click asks them — this is what makes Chat *conversational*. |
| **Regenerate** | Re-runs the last question | Use when an answer was weak. |
| **thinking…** footer | A sticky status while the agent works | Animated dots plus a progress %/heading; an optional **Agent Build Log** shows the live tool steps the agent is taking. |
| **+ New chat** | Starts a fresh conversation | Clears context so a new topic doesn't inherit the old one. |
| **Search chats** | Finds an earlier conversation in the history | History persists per user. |
| Output / Query toggle | Shows the answer *or* the underlying query the agent ran | Only when the project enables answer **transparency**. |
### Walkthrough — ask a grounded question
1. Open `App ▸ Chat`.
2. The empty chat shows **suggested questions**. Either click one, or type your own in the **Ask a question** box — e.g. *"Which of our policies cover remote work?"* — and press **Send**.
3. Watch the **thinking…** footer: the agent embeds your question, retrieves matching passages, and composes an answer. (Expand the **Agent Build Log** if you want to see each step.)
4. Read the streamed answer. Note the **[1] [2]** markers and the **References** block beneath it.
5. **Click a reference chip** — the source document opens at the exact cited page so you can verify the claim. This round-trip back to the source is the whole point of grounded chat.
6. Click a **follow-up** chip (or type your own) to continue the thread — the assistant remembers what you already discussed.
7. Give the answer a **thumbs up or down**. That feedback is recorded for the builder to review.
### Behaviours to know
- **Connection / streaming states.** Answers stream token-by-token. If the connection drops you'll see **"Reconnecting…"** or **"Connection lost — Reconnect"**; an unanswered question offers **"Try again"**. None of this loses your conversation.
- **Human-in-the-loop (HITL).** If the agent is configured to pause for a human, chat shows a **pending-interrupt card** — **Approve**, **Review** (with feedback), or **Reject**, with editable arguments. The conversation resumes once you decide. Present only when the agent's workflow defines an interrupt; most read-only knowledge agents never show it.
- **The four containers.** The same controls appear in the **Co-pilot** modal, the per-document **doc-chat** pane, and the **floating agent widget** (the only place a user picks *which* agent to talk to at runtime). If you learned the Chat tab, you've learned them all.
- **It only knows what it was given.** A chat agent answers over the **Knowledge collections attached on its Knowledge tab** — nothing else. No attachment, no answer (see the builder section below).
## Search
### Layout
Search has two states on the one tab:
- **Search home** — a hero prompt ("Hi there, What Can I Help With?") with the query box, a **Select meta fields** picker, a **Select a view** picker, the **Search** button, and three **prompt-hint cards**.
- **Search results** — after you search: the query bar with a **Clear** control, a **"Showing: N of M Results"** count, a **Search history** toggle, the ranked results list (matching passage highlighted, thumbs up/down per result), **Refine search**, and **Load more**.
### What every control does
| Control | What it does | Notes |
|---|---|---|
| **Search hero** | The "Hi there, What Can I Help With?" prompt box | The landing state of the Search tab. |
| **Select meta fields** | Choose which extracted fields to search/return | Has Select-All / Unselect-All. |
| **Select a view** | Scope the search to a saved **View** | Reuses the same **Views** from your document lists ([Shaping the experience](/academy/e7)). |
| **Prompt-hint cards** | Three example queries | One click runs them — onboarding for new users. |
| **Search** button | Runs the query | Switches the page into the results state. |
| **Results list** | Ranked matching documents/passages, with the answer-key passage highlighted | Each result deep-links to its document. |
| **Thumbs up / down** per result | Vote a result up or down | Tunes relevance / records feedback. |
| **Load more** | Pages in the next batch of results | Counts up toward the total **"Showing: N of M Results"**. |
| **Refine search** | Narrow by annotations, keywords, or labels | Layer constraints without retyping the query. |
| **Search history** | Re-open a past search | Toggled from the results header. |
| **Clear** | Empties the query | Returns you to the hero. |
### Walkthrough — find the right document
1. Open `App ▸ Search`.
2. (Optional) narrow the scope: pick a **View** in **Select a view**, and/or pick **meta fields**.
3. Type a query — e.g. *"remote work policy"* — and press **Search** (or click a hint card).
4. Scan the **results list**: the matching passage is highlighted in each hit, ranked best-first.
5. **Thumbs-up or down** the results to record relevance feedback.
6. **Load more** to page further, or **Refine search** to add a keyword/label constraint.
7. Click a result to open the source document; reopen earlier queries from **Search history**.
### Behaviours to know
- **Search reuses Views.** "Select a view" is the *same* View object you build for document lists in [Shaping the experience](/academy/e7) — a Search scope is just a saved slice.
- **It's feedback-driven.** Per-result voting is first-class here; encourage users to thumb results so relevance improves.
> **Under the hood — how a Knowledge collection answers.** When a user asks a question (Chat or Search), the platform **embeds** the query into a vector, then does a **KNN (nearest-neighbour) match** against the **vector index** — but *scoped to the attached collection only* (filtered by the collection's id, so a 100-document corpus and a 100,000-document corpus answer just as fast, and unattached corpora can never leak in). The closest passages are handed to the LLM as context, which writes the answer and attaches a **citation** back to each source passage — that's where the **References** chips come from. A **structured** question ("how many invoices over $10k?") takes a different path: it runs read-only **SQL** against the collection's Knowledge **Datasheet** instead of vector search. As noted above, the chunk → embed → index step that *fills* the vector index is the partly forward-looking piece; the retrieval and citation behaviour is live. Skippable, but it explains why citations are trustworthy: the answer is *grounded* in passages actually retrieved from your documents, not invented.
## How a builder turns these on
You don't write code for any of this — you configure it. The essentials, with their home pages:
| To do this… | Go to… | Page |
|---|---|---|
| Let an agent **answer over a corpus** | Attach a **Knowledge collection** on the agent's **Knowledge** tab | [Your first agent](/academy/a3) — *required, or it has nothing to read* |
| Build / vectorise the **Knowledge collection** | Data Model — create the collection, set its category to Knowledge | [Collections & schema](/academy/d1) |
| Set **default / suggested questions**, transparency, feedback | Studio ▸ **Chat settings** | [Shaping the experience](/academy/e7) |
| Configure **Search settings** and the **Views** that scope it | Studio ▸ **Search settings** / **Views** | [Shaping the experience](/academy/e7) |
| Show or hide the Chat / Search tabs entirely | Project flags (`DisableChat`, `DisableSearch`) | [Shaping the experience](/academy/e7) |
> **Watch out.** The single most common "why won't it answer?" mistake: the **Knowledge collection was never attached to the agent's Knowledge tab.** No attachment = no retrieval = a vague, source-less answer. Always check the Knowledge tab first ([Your first agent](/academy/a3)).
## Try it yourself
Using a project that already has a Knowledge collection attached (the [Policy assistant use case](/academy/uc-policy) builds one end-to-end):
1. Open `App ▸ Chat`, click a **suggested question**, and watch it stream.
2. **Click a References chip** — confirm it opens the cited document at the right page.
3. Ask a **follow-up** chip, then a fresh question after **+ New chat** — notice the second one has no memory of the first.
4. Give one answer a **thumbs down**.
5. Now open `App ▸ Search`, run the *same* question, scope it with **Select a view**, **thumbs-up** the best hit, and **Load more**.
6. Compare the two experiences: which felt better for "explain it to me", which for "find the doc"?
## Recap
- Two surfaces ask questions over documents: **Chat** (conversational, multi-turn, cited answers) and **Search** (query → ranked results). Same retrieval, different experience.
- **Chat** gives written answers grounded with **citation** chips that deep-link back to the source page; it has conversation **history**, **suggested/follow-up** questions, **thumbs up/down** feedback, a **thinking** footer, streaming/reconnect states, and (if configured) **HITL** approve/reject cards.
- **One chat engine** surfaces in **four containers** (Chat tab, Co-pilot, doc-chat, floating widget).
- **Search** offers a hero prompt, **View**-scoped results, per-result voting, **Load more**, **Refine search**, and **Search history**.
- Under the hood: the query is **embedded** and **KNN-matched** against the **vector index**, scoped to the attached **Knowledge collection**, and grounded with **citations**; structured questions hit a SQL **Datasheet**. (Auto-vectorisation is partly forward-looking.)
- A builder must **attach a Knowledge collection on the agent's Knowledge tab** ([Your first agent](/academy/a3)) and tune Chat/Search settings in [Shaping the experience](/academy/e7) — no code required.
## Where to go next
- [Collections & schema](/academy/d1) — build the Knowledge collection these surfaces answer over.
- [Shaping the experience](/academy/e7) — turn Chat/Search on, set default questions, and define the Views that scope Search.
- [Your first agent](/academy/a3) — the Knowledge tab where a corpus gets attached to an agent.
- [Policy assistant](/academy/uc-policy) — build chat-over-a-corpus end to end.
---
## E5 · Dashboards & inbox
URL: https://www.botminds.ai/academy/e5
> Botminds Academy — Platform · Experience
# Dashboards & inbox
> **In one line.** The two consumer surfaces where work becomes visible and actionable — the
> **Dashboard** (analytics over your project) and the **Inbox** (the queue of everything waiting
> on a person).
> **You'll be able to.** Read a project's Dashboard, find the right widget, and triage the Inbox —
> knowing exactly where each item gets acted on (not inside the Inbox).
> **Where this lives.** Consumer app: `App ▸ Overview/Dashboard` (route `_dashboard`) and
> `App ▸ Inbox` (route `inbox`).
## Two surfaces, opposite questions
Earlier pages worked one document at a time. This page zooms out to the whole project. Two
surfaces do that, and they answer opposite questions:
- The **Dashboard** answers *"how is the whole pile doing?"* — counts, charts, trends.
- The **Inbox** answers *"what is waiting on me right now?"* — a worklist of human tasks.
Both are **consumer** surfaces — what your end-users see and use. You, the builder, configure
what they show from Studio. Knowing the consumer side first tells you what you're configuring
toward. If you're new here, [What is Botminds](/academy/s1) and [Core concepts](/academy/s2)
give you the vocabulary this page assumes.
> **Tip.** A common newcomer mistake is to treat the Inbox like an approval screen. It isn't —
> it's a pointer list. The Inbox half of this page makes that concrete.
## The Dashboard
**Purpose:** project analytics — the bird's-eye view of your documents and the work done on them.
It lives at the **Overview / Dashboard** tab in the top nav (route `_dashboard`). If a project
configures more than one dashboard, each gets its own button, and the URL carries
`?did=` to pick which one.
> **Flag-gated and role-gated.** The Dashboard tab is hidden when the project sets the
> `DisableDashBoard` flag, and it is not shown to the `client` role at all. If a consumer can't
> see "Overview", that's why — it's intentional, per-project, per-role configuration. See
> [Security & governance](/academy/g1) for how roles gate surfaces.
### Two modes
The Dashboard surface has two modes, and which one you land in depends on how the project is set
up.
```
DASHBOARD — landing mode (role cards) DASHBOARD — regular mode (a dashboard)
┌──────────────────────────────────┐ ┌────────────────────────────────────────┐
│ Who are you here as? │ │ [Operations][Finance][Quality] + edit │ ← dashboard tabs
│ ┌────────┐ ┌────────┐ ┌───────┐ │ ├────────────────────────────────────────┤
│ │Reviewer│ │Approver│ │Analyst│ │ │ ┌───────┐ ┌───────┐ ┌───────────────┐ │
│ └────────┘ └────────┘ └───────┘ │ │ │ 1,240 │ │ Chart │ │ Status donut │ │
│ (pick a role → its landing view)│ │ │ Docs │ │ │ │ │ │
└──────────────────────────────────┘ │ └───────┘ └───────┘ └───────────────┘ │
│ ┌──────────────────┐ ┌─────────────┐ │
│ │Query-builder tbl │ │ Error types │ │
│ └──────────────────┘ └─────────────┘ │
└────────────────────────────────────────┘
```
- **Landing mode** shows **role cards** — pick the role you're acting as, and the dashboard
tailored to that role opens. Use this when one project serves several audiences (a reviewer
and a finance analyst want different numbers).
- **Regular mode** drops you straight into a dashboard: a row of **dashboard tabs** (pinnable,
favouritable, up to 5 visible) over a grid of widgets.
If a project has no dashboard yet, you'll see the empty state — *"There is no dashboard… Create
a new dashboard"* — and, for subscription admins only, a plus button to make one.
### What every control does
| Control | What it does | Notes |
|---|---|---|
| **Dashboard tabs** | Switch between configured dashboards | Pin / favourite; max 5 visible; each can carry an uploaded icon |
| **Widget grid** | The analytics themselves — one tile per widget | Resizable / draggable in edit mode (admins) |
| **Per-widget date range** | Restrict a widget to a time window | Lives on the widget, via its query-builder — not a single global date control |
| **Per-widget filters** | Query-builder conditions feeding the widget | Configured in Studio; the consumer reads the result |
| **Auto-refresh** | Re-pull the dashboard's data on an interval | Set per dashboard |
| **Edit mode** | Add / rename / delete / rearrange widgets | Admin only; a guard warns you on unsaved edits if you navigate away |
### What kinds of widgets exist
A dashboard is a grid of widgets, rendered by the shared widget engine. The platform ships
several categories — you pick and configure them in Studio; on the consumer side you just read
them:
- **Counts / stat tiles** — a single big number ("1,240 documents", "37 overdue").
- **Charts** — bar / line / donut style visualisations of a metric over time or by category.
- **Status & error-type breakdowns** — how documents distribute across lifecycle stages or
failure reasons.
- **Tables** — including a **query-builder table** (rows from a saved query) and a **chat-table**
(a table produced by asking a question).
- **Navigation widgets** — tiles that link onward to a filtered list or another surface.
> **Under the hood.** Each widget fetches its own data (`getWidgetDetails`). Large dashboards can
> issue dozens of these calls and load slowly — a known performance characteristic. If a consumer
> dashboard feels sluggish, that's the cause, not a hang.
The exhaustive widget catalogue, and how you build and configure each one, lives with the
builder side — see [Shaping the experience](/academy/e7).
### Pack tabs — action dashboards on the classic shell
A project can also mount a card-based **pack** as an *additional* tab in the top nav, next to
Dashboard / Inbox / Data — the classic tabs stay untouched. This is how hybrid **action
dashboards** ship: instead of read-only widgets, a pack tab opens card pages such as worklist
inboxes with **Review / Approve** actions, drillable document lists (age / SLA / confidence
columns), and KPI or heat-matrix strips — every drill lands on real filtered data. Pack tabs
are stored **server-side per project**, so every browser (and every teammate) sees the same
tabs. The card layer behind them is covered in [Pages & cards](/academy/e6).
### Behaviours to know
- **Consumers read; builders configure.** Everything on a dashboard was defined in Studio (see
[Shaping the experience](/academy/e7)). A consumer can switch dashboards, pick a role card,
and (if an admin) edit — but the design of the analytics is a build-time act.
- **Unsaved-edit guard.** If you're in edit mode and try to leave with unsaved changes, the
`can-deactivate` guard stops you and asks first.
- **It's role-aware.** What an analyst sees and what a reviewer sees can be two entirely
different dashboards behind the same tab — that's the point of role cards.
## The Inbox
**Purpose:** the per-project queue of everything waiting on a person. Where AI hands work back
to humans — reviews, approvals, "needs info", triage, and tasks all land here in one list.
### The one thing to understand first
> **Watch out — the Inbox does not act on items.** The Inbox is **read + snooze + dismiss
> only.** There is no approve, reject, or edit button inside the Inbox. Each row is a pointer to
> a document sitting in a human review stage. To actually decide on it, you click **Open**,
> which takes you to the wrapped document, and you act there using its normal lifecycle UI (the
> Summary pane, the workflow stepper). When you advance the document, the Inbox item resolves
> itself.
Internalise that and the rest of the Inbox is simple. The Inbox is a worklist, not a workspace.
### How items get here
Two concepts from earlier pages meet in the Inbox:
- The Inbox is a **Human-kind collection** — recall from [Core concepts](/academy/s2) that a
collection's Kind is either **Agent** (an AI works it) or **Human** (it's a person's work
queue). The Inbox is the canonical Human-kind collection.
- Items appear because a document's **Lifecycle** reached a stage configured to **"send to
inbox."** When a document enters that human stage, the server creates an **InboxNote** that
wraps the source document (it remembers the source collection, the document id, and the
stage). You design that behaviour when you build the lifecycle — see
[Taxonomy, lifecycle, tags & events](/academy/d3).
The **Inbox** tab lives in the consumer app (route `inbox`). It can also appear as an Inbox
collection tab inside the project — either way opens the same queue.
### Header, stats, and filters
The header reads **"Inbox · Human intake"** with the subtitle *"Everything waiting on a person
in this project."* Beside it: an **"N open"** count chip, and a red **"N overdue"** chip that
appears only when some item's due date is in the past.
| Control | Options | What it does |
|---|---|---|
| **Scope** segment | **My items** (default) · **Everyone** | Whose items to show — yours, or the whole project's |
| **Status** segment | **Open** (default) · **Snoozed** · **Done** | Which lifecycle state of the notes to list |
| **Refresh** | — | Re-loads the current scope + status |
### The type sections
Items are grouped into fixed-order sections; a section only appears when it has items. Each
header reads `{label} · {count}`:
| # | Section | Meaning |
|---|---|---|
| 1 | **Needs Approval** | An approval decision is required |
| 2 | **Needs Review** | A human review is required |
| 3 | **Needs Info** | Something is missing / sent back for information |
| 4 | **To Triage** | Unclassified, needs routing |
| 5 | **Tasks** | A general to-do |
### The item card and its actions
Each card shows:
- **Headline** — the note's title (e.g. *"Invoice 4471 needs sign-off"*). High-priority notes
get a red left border.
- **Provenance line** — `wraps ▸ {collection} · {sourceDocId} · {stage}` — tells you exactly
which document and which stage produced this item.
- **Meta line** — who it's assigned to (if anyone), an age label (`20m` / `3h` / `1d`), and an
optional amount (e.g. `$12,400`).
| Action | What it does | Available when |
|---|---|---|
| **Open** | Navigates to the wrapped document — where you actually review/approve/edit | Only when the item has a source document |
| **Snooze** | Hides the item for a while (default 60 minutes), then it returns | Always |
| **Dismiss** | Removes the item from the queue | Always |
> **Watch out.** There is no claim/assign and no approve/reject/edit here. Assignment is
> displayed (the note carries an assignee) but not edited in the Inbox. All real action happens
> on the wrapped document — click **Open** and use the document's lifecycle UI (see
> [The document detail page](/academy/e3)).
### Behaviours to know
- **Snooze / Dismiss are optimistic.** When you snooze an open item, it disappears from the Open
view immediately, then reappears in **Snoozed** — you don't wait for a round-trip.
- **The badge count is best-effort.** A small count on the Inbox nav entry is a quick estimate,
not a guaranteed-exact number.
- **Items self-resolve.** You don't mark an Inbox note "done" by hand for normal work —
advancing the wrapped document past its human stage resolves the note for you.
- **Empty state.** When nothing is waiting: a check-circle and *"You're all caught up."* with
*"New review, approval, and triage items appear here automatically."*
## Try it yourself
You'll need a project with at least one document parked in a human review stage — any use case
that routes to review will produce one, e.g. [Support intake & triage](/academy/uc-triage).
1. Open the **Inbox** tab. Read the **"N open"** chip and note whether an overdue chip is
showing.
2. Flip **Scope** to **Everyone** — does the list grow? That tells you whether other people have
pending work too.
3. Find an item and read its provenance line. Which collection and which stage did it come from?
That's your proof that a Lifecycle stage "sent it to the inbox."
4. Click **Snooze** on one item, then switch **Status** to **Snoozed** — confirm it moved there.
5. Click **Open** on another item. Notice you leave the Inbox entirely and land on the document
detail page — that is where you'd approve or edit. Don't actually decide; just observe that
the Inbox handed you off.
If step 5 surprised you, re-read "The one thing to understand first."
## Where to go next
- [The document detail page](/academy/e3) — the wrapped document is where reviews and approvals
actually happen.
- [Shaping the experience](/academy/e7) — build the dashboards, widgets, and Views that feed
these surfaces.
- [Taxonomy, lifecycle, tags & events](/academy/d3) — how a lifecycle stage "sends to inbox."
- [Security & governance](/academy/g1) — how roles gate the Dashboard and other surfaces.
---
## E6 · Pages & cards
URL: https://www.botminds.ai/academy/e6
> Botminds Academy — Platform · Experience
# Pages & cards
> **In one line.** Purpose-built screens without code: compose pages from cards in the experience designer, bundle them into packs, and let structured data render itself.
> **Where this lives.** `Studio ▸ Experience ▸ Pages` (designer), `Studio ▸ Experience ▸ Packs`, and `Studio ▸ Experience ▸ Cards` (the card library); rendered pages serve under the `/x` route tree.
## Why pages exist
The [workspace](/academy/e2), [chat](/academy/e4) and [dashboards](/academy/e5) cover most operations out of the box. Pages are for the screens that are *yours*: a lending review workbench, a vendor scorecard, a landing page for one team's slice of the work. Instead of waiting for custom UI development, you compose them.
> The v2 experience renderer ships as a release flag (`experienceRenderer`, default on; off is the kill-switch). Packs have their own flag layered on top.
## Cards — the unit of composition
A page is a layout of **cards**. Each card binds to platform data and renders it appropriately:
- **Document cards** — the document workbench family: cards that surface a document's fields, summary, and actions on the document page itself, so a reviewer's working view carries exactly the panels their process needs. The native summary-pane card supports the full review loop — inline edit, comments, formula fields — and takes a card-level **skin** so the same pane can be restyled per solution.
- **Structured cards** — point one at a [Structured collection](/academy/d2) and it reads the schema and infers the right presentation: a few records with images become tiles, records with a dominant text field become rows, wide records become a table. You choose the collection; the card works out the shape.
- **Chart and metric cards** — counts and breakdowns over collections, the same data dashboards draw from.
The design principle across all of them: **cards bind to the domain model, not to copies of it.** A card shows the same records, fields and lifecycle stages the rest of the platform sees, live.
### The card library
`Studio ▸ Experience ▸ Cards` is the browsable catalog of every card — ~44 cards in 7 categories, searchable, each with when-to-use guidance, a placement wireframe, its data lineage and configuration, and a **Use this card** jump straight into the Pages designer. It's the same catalog the designer's palette draws from, so it can never drift; start here when you're not sure which card fits.
## The designer
`Studio ▸ Experience ▸ Pages` is a no-code editor: add cards, arrange the layout, bind each card to its collection or view, preview, publish. Cards that take a skin get a **skin gallery** in the designer — click a skin for a live preview. Published pages render for consumers under `/x/...` — fast, native, and themed to your workspace branding ([E7](/academy/e7)). On pages with side-by-side panes, the gap between panes is a **draggable resizer**: each user's widths persist across visits, and a double-click resets to the authored layout.
## Packs — pages that know each other
A single page is a screen; a **pack** is a journey. `Studio ▸ Experience ▸ Packs` bundles a curated set of pages and connects them — a click on a record in one page opens the detail page for it — then lets you walk the whole journey in a **Try it** preview before you hand it to users.
Use a pack when a team's workflow spans screens: a queue page, a detail workbench, a summary dashboard, connected in the order the work actually flows.
## When to use what
| You need | Reach for |
|---|---|
| Browse and act on documents | The [workspace](/academy/e2) — it's already built |
| Numbers over everything | [Dashboards](/academy/e5) |
| A screen shaped like one team's process | A **page** of cards |
| A connected multi-screen journey | A **pack** |
| The same thing outside the app shell | [Embed & share](/academy/v3) |
## Where to go next
- Branding and layout for what you build: [E7 · Shaping the experience](/academy/e7).
- The structured collections cards love: [D2 · Collection types](/academy/d2).
- Shipping an experience to another workspace: [V4 · Hubs & distribution](/academy/v4).
---
## E7 · Shaping the experience
URL: https://www.botminds.ai/academy/e7
> Botminds Academy — Platform · Experience
# Shaping the experience
> **In one line.** The four Studio surfaces — **Project**, **Search**, **Chat**, and
> **Intelligence** — where you configure exactly what your end-users see in the consumer app.
> **You'll be able to.** Brand the runtime, define the saved **Views** your users switch
> between, set the chat's default questions and behaviour, and configure the dashboards they
> read.
> **Where this lives.** `Studio ▸ Project`, `Studio ▸ Search`, `Studio ▸ Chat`,
> `Studio ▸ Intelligence`.
## Why it matters
The builder pages before this one taught you to define the work — collections, agents,
pipelines. This page is the other half: shaping what the people doing the work actually see.
The same project can feel like a polished invoice cockpit or an unbranded data dump depending
on these four surfaces; a builder who skips them ships a working-but-confusing app.
The mental model is simple: **you configure here; your users consume there.** A saved **View**
defined in Search settings is the dropdown your reviewers pick from in
[The document workspace](/academy/e2). A chat **Default Question** is the clickable starter in
[Chat & search](/academy/e4). A widget added in Intelligence is a tile on the dashboard in
[Dashboards & inbox](/academy/e5). You'll want [Studio orientation](/academy/s2) and a project
with at least one collection ([Collections & schema](/academy/d1)) before working through this.
> **Flag-gated grouping (routes unchanged).** With the `studioRailV2` flag on, the rail regroups
> **Project / Search / Chat / Intelligence** under a single **"Experience"** section, and
> Search/Chat collapse into one leaf each with in-page tabs; with it off, the legacy rail lists
> every sub-item separately. The routes and controls are identical either way. The Experience
> section also carries the **Pages · Packs · Cards** leaves — the composable-page surfaces
> covered in [Pages & cards](/academy/e6) — with Intelligence appearing as the **Analytics** leaf.
> **Under the hood.** Almost every field on these screens is wrapped in a
> `*botModulePermission` gate, so a teammate who "can't see a tab" is usually missing a role
> action, not hitting a bug — fix it in Access Roles ([Security & governance](/academy/g1)). A
> small red dot on a tab label means unsaved changes; navigating away warns you.
## Project ▸ Overview
**Where:** `Studio ▸ Project ▸ Overview`.
Your project's identity and its foundational settings. It's a thin tab-bar shell: pick a tab,
fill the shared form, **Save**.
| Tab | What it configures |
|---|---|
| **Project Overview** | The project's top-level identity (name, description, the basics that label it everywhere). |
| **Landing Page** | What the consumer app opens to — the first thing a user sees on entering the project. |
| **Universal Template** | A shared template applied across the project's documents. |
| **Concept Settings** | Project-level concept/extraction configuration. |
| **Ingestion Settings** | Project-wide ingestion defaults (complements per-connector settings — see [Ingestion & connectors](/academy/d4)). |
| **Global Variables** | Named values reusable across the project's configuration. |
> **Watch out.** Which tabs appear is filtered by your role's visible-menu config; a missing tab
> may be hidden for your role rather than absent. The set above is the full default.
Behaviours to know:
- **The active tab is remembered in the URL.** Switching tabs writes `#activeTab=`, so a
deep link or a refresh reopens the same tab — handy for sending a teammate straight to
"Global Variables".
- **Unsaved-change guard.** A dirty tab shows a red dot and leaving the page warns you.
Switching to a different project clears the dirty state.
- **Inline help.** The info bubble on each tab is keyed to that tab — context help on click.
## Project ▸ Appearance
**Where:** `Studio ▸ Project ▸ Appearance`.
Where Overview sets what the project is, Appearance sets how the runtime looks — branding,
theme, logos, and the layout of the document page, navigation, and panes your users see.
| Tab | What it configures |
|---|---|
| **`` Page** | The document page — its theme, logos, branding. The label is dynamic: it shows your project's entity name, e.g. "Invoice Page" or "Contract Page", not literally "Documents Page". |
| **Navigation Menu** | The consumer app's left navigation. |
| **Summary Pane** | The summary panel beside a document. |
| **Action Pane** | The action panel (its own dedicated editor). |
| **Document List** | How the document list/grid renders. Card templates take `<>` placeholders, including the uploader (`<>` / `<>` / `<>`) and `<>` (formatted with the workspace's date format). |
| **Label Categories** | Grouping of labels for display. Always visible, regardless of role config. |
Behaviours to know:
- **Lazy-loaded tabs.** Each tab's body only mounts the first time you open it, then stays
mounted (just hidden) — switching back is instant and in-progress edits survive the switch.
Expect a brief load on first open of a tab.
- **The dynamic first tab** reflects your configured entity name — rename the entity to "Claim"
and you get "Claim Page".
- **Same red-dot and URL-fragment behaviour** as Overview, including the Action Pane's separate dirty flag.
> **Tip.** Logos and theme set here are also what a published **Solution** can carry forward —
> get the branding right before you package the project in [Hubs & solutions](/academy/v4).
## Search settings
**Where:** `Studio ▸ Search`. Under `studioRailV2` this is one rail leaf with in-page tabs; in
the legacy rail the tabs are separate items.
Search settings configure the **Search** experience from [Chat & search](/academy/e4). Three
visible tabs — **General** (how search behaves for end-users), **Audit** (a read log of search
activity, lazy-loads on first open), **Feedback** (the same audit table, filtered to user
feedback on search results) — plus **Views**, the most important thing here for a builder.
> **Under the hood.** The tab bar only renders under `studioRailV2`; one component switches its
> body by route `data.type` (`general` / `audit` / `feedback` / `views`). The **Views** type is
> deliberately not in this tab bar — you reach it from the Data Model, described next.
### Views — define what your end-users browse
A **View** is a saved, named, filtered slice of a collection's documents, with chosen columns —
exactly the dropdown your reviewers switch between in [The document workspace](/academy/e2)
("All Invoices" vs "Overdue Invoices" vs "My Queue"). This screen is where a builder defines
those Views. Each View is either a **Project** template (shared, role-scoped) or a **User**
template (personal). The Views table lists what exists; empty, it reads *"No views to show /
Please create a view to see the details"*:
| Column | What it tells you |
|---|---|
| **Name** | The View's display name — what users see in the View dropdown. |
| **Description** | A short note (truncated past ~50 chars, full text on hover). |
| **Created By** | The email of whoever created it. |
| **Has Dashboards** | Green **Yes** / red **No** — whether the View has dashboards attached. |
| **Type** | **Project** (shared) or **User** (personal) chip. |
| **Allowed roles** | Colour-coded role chips — which roles may see this View ("-" if unrestricted). |
| **Action** | An info icon (tooltip *"Check what does each view contains"*) opening a **View Details** side-popup from which you can open or delete the View. |
> **Watch out.** **Delete** is permanent and asks *"Are you sure you want to delete
> <name>?"* first. The **Action** column itself only appears if your role has the
> *"Action in Search views"* permission — another role-gate, not a missing feature.
**Walkthrough — defining a Project View.** The Views table lives in Search settings, but the
create/edit action is launched from the collection's **Data Model** ([Collections &
schema](/academy/d1)) — that's where the collection's columns and filters are in front of you:
1. Open the collection in `Studio ▸ Data Model` and start a new **View**.
2. **Name** it (this becomes the dropdown label) and add a one-line **Description**.
3. **Pick columns** — which extracted fields (Labels) show as columns, in what order.
4. **Set filters** — e.g. *status = Overdue*, *amount > 10,000* — so the View only lists
matching documents.
5. Choose **Type**: a **Project** View (shared) or a **User** View (just yours).
6. For a Project View, set **Allowed roles** so only the right people see it.
7. **Save.** The View now appears in the table above and in the consumer **View dropdown**.
The same Views also feed the **View Widget** on dashboards (see Intelligence, below) and are
the "View" that agents and hub imports rebind to — a good View pays off in several places.
## Chat settings
**Where:** `Studio ▸ Chat`. Like Search, one rail leaf with in-page tabs under `studioRailV2`;
legacy shows separate items.
Chat settings configure the **Chat** experience from [Chat & search](/academy/e4). It mirrors
Search but with three tabs and no Views: **General**, **Audit** (a read log of chat activity),
**Feedback** (that table filtered to user feedback). **General** is the big one:
| Control | What it does |
|---|---|
| **Default Questions** | A reorderable list of starter prompts shown in the chat. Drag to reorder, add a question after any row, blank rows are dropped on save. **Pin default questions** keeps them visible. These are the clickable starters your users see in [Chat & search](/academy/e4). |
| **Chat Greeting Text / Tagline Text / Placeholder / Disclaimer** | The opening greeting, the short tagline under the chat (hideable), the grey hint text inside the message box, and the disclaimer line. |
| **Disable Chat Questions** | Hide the default questions entirely. |
| **Enable Question Preview** | Preview a suggested question before sending. |
| **Hide Chat References / Tagline** | Toggle the citations panel and tagline off. |
| **Project / Document Prompt** | The prompt template used for project-wide vs single-document chat. |
> **Under the hood.** Saving **General** clears the unsaved-change dot on its own (it emits a
> "saved" signal) — unlike Search settings, no lingering red dot after a successful save. Default
> questions are stored as `DefaultChatQuestions`; the pin toggle as `PinDefaultChatQuestions`.
> **Tip.** Good default questions are the cheapest UX win on the platform. Write three or four
> that match what your users actually ask ("What's overdue?", "Summarise this contract's risks")
> — they double as documentation and as a demo script.
## Intelligence ▸ Dashboards
**Where:** `Studio ▸ Intelligence`.
Where you configure the dashboards your end-users read in [Dashboards & inbox](/academy/e5). A
menu + details split:
```
┌─ Intelligence ────────────────────────────────────────────────────────────┐
│ Dashboards (menu) │ < selected dashboard's widgets > │
│ Operations │ Name [ Overdue by Vendor ] │
│ Quality │ Description … │
│ Overdue Watch < sel │ UseCache [ on ] EnableMaximize [ off ] │
│ (empty: no dashboards) │ TemplateId [Query Widget] ChartType [donut] │
│ │ [ Open live dashboard ] │
└───────────────────────────────────────────────────────────────────────────┘
```
| Region | What it does |
|---|---|
| **Dashboards menu** (left) | Lists each dashboard by name + info message. Empty until you create one. |
| **Details panel** (right) | On selecting a dashboard, shows its first widget and lets you inspect each widget's settings (Name, Description, **UseCache**, **EnableMaximizeOption**, TemplateId, ChartType, QuickActions). |
| **Open live dashboard** | Jumps to the running dashboard (`/_dashboard?did=`) — the exact view your end-users get. |
### Adding widgets and charts
Building a dashboard is: add a widget, pick its template, optionally pick a chart type, point
it at data, save. The catalog is 31 widget templates and roughly 20 chart types, in categories:
| Category | Use it for | Examples |
|---|---|---|
| **KPI / single-number** | One headline metric | Documents Count, Label Instance Count, State, QC Widget, Error Metrics |
| **Table / multi-row** | A list of labels, stages, users, or rows | Multi Label View, Multi Stage, Multi User Stages, **View Widget**, Datasheet Widget |
| **Query / analytics** | An insight you draw as a chart | **Query Widget**, Dynamic Widget, Ingestion Summary, Sessions, Source / Source Instance |
| **Agentic / AI** | AI-built or conversational tiles | **Agentic Widget**, Chat Widget, Document Summary |
| **Layout / content** | Shape the dashboard itself or embed content | Filter Widget, Navigation, Multi Widgets, Rich Text Editor, Static HTML |
Chart-capable widgets (notably **Query Widget**) offer a **Chart Type** picker: line, area, bar
and stacked-bar variants, pie, donut/semidonut, gauge, meter, funnel, heatmap, map, and bubble —
or none, to keep the raw table.
> **Tip.** The **Agentic Widget** lets you describe a tile in plain language and have AI build
> it — the fastest way to a first chart when you're not sure which template fits.
> **Not currently shipped.** Two widgets are commented out in source — **Users** and **Infra
> Cost Widget** — so they won't appear in the picker. Don't promise them to end-users.
## Try it yourself
A small, real end-to-end: give your invoice reviewers an **Overdue Invoices** View and a chat
starter question that matches it.
**Part A — define the View (Search/Data Model):**
1. Open your invoices collection in `Studio ▸ Data Model` and create a new **View**.
2. Name it **`Overdue Invoices`**; description **`Invoices past their due date, awaiting action`**.
3. Add columns: **Vendor**, **Invoice Total**, **Due Date**, **Status**.
4. Add a filter: **Status = Overdue** (or **Due Date < today**, if you have that field).
5. Set **Type = Project** and **Allowed roles = Reviewer**. **Save.**
6. Open `Studio ▸ Search ▸ Views` (or the legacy Views item) and confirm **Overdue Invoices**
appears with **Type = Project** and the **Reviewer** chip.
**Part B — add the matching chat starter (Chat):**
7. Go to `Studio ▸ Chat ▸ General`.
8. Under **Default Questions**, add **`Which invoices are overdue?`** and tick **Pin default
questions**. **Save** — the red dot should clear on save.
**Verify as a consumer:** open the project's consumer app as a Reviewer. The **View dropdown**
now offers *Overdue Invoices*; the chat opens with *"Which invoices are overdue?"* as a
clickable starter. You just configured, end to end, something your users consume.
> **Bonus.** In `Studio ▸ Intelligence`, add a **View Widget** pointed at your new *Overdue
> Invoices* View — the same slice shows up as a dashboard tile too.
## Where to go next
- [Security & governance](/academy/g1) — the Access Roles that gate every field and tab you just touched, plus Users, Activity, Audit, and config freeze.
- [Hubs & solutions](/academy/v4) — package this whole experience (branding, Views, dashboards) as a publishable Solution.
- [Embed & share](/academy/v3) — putting these surfaces in front of users outside the app: share links and embeds.
- [Dashboards & inbox](/academy/e5) — revisit the consumer side now that you've seen the controls.
---
## G1 · Access & roles
URL: https://www.botminds.ai/academy/g1
> Botminds Academy — Platform · Governance
# Access & roles
> **In one line.** How you control who can see and do what — users, Access Roles, and the stage gates they enforce.
> **You'll be able to.** Add a user, build an Access Role, and gate a lifecycle stage to it.
> **Where this lives.** `Studio ▸ Security` (**Users** · **Access Roles**).
## Why access control matters
A solution that works is only half-built; a solution other people can be *trusted* to run is finished. On this platform, access control does two jobs:
- **Roles gate access.** A **Role** (the platform's **RBAC** unit) decides which buttons, fields, and Studio pages a user even sees — almost every control in Studio is hidden behind a role check (`*botModulePermission`). If a colleague "can't see a button," it's nearly always a missing role grant, not a bug.
- **Roles gate the lifecycle.** The same roles decide who may act on a document at each **stage** of its review flow. This is how "AI recommends, two humans confirm" actually gets enforced ([D3 · Taxonomy, lifecycle, tags & events](/academy/d3)).
The third leg — the immutable record of who did what — is the audit trail, covered in [G5 · Audit & compliance](/academy/g5).
> **Under the hood.** Security lives under the permission section key `'security'`. The footer **+** buttons and row-action menus on the Users and Access Roles surfaces only render for **Subscription Admins** or the **Project Creator** — if you don't see them, you're neither.
## Users
`Studio ▸ Security ▸ Users` — the people who are in this project and the roles they hold. Users must already exist in the **subscription**; this page adds them to the *project* and assigns their roles.
The layout is a master/detail split: a **menu panel** lists every user (full name + email); selecting one fills the **details panel** on the right. The Access Roles page (below) uses the same split.
```
┌──────────────────────────┬──────────────────────────────────────────────┐
│ Users │ Amy Anderson │
│ ────────────────────── │ ───────────────────────────────────────── │
│ Amy Anderson │ Full Name Amy Anderson │
│ amy@acme.com <──┤ User Name amy@acme.com │
│ Bob Brown │ Roles L1-Reviewer, QA (i) │
│ bob@acme.com │ Active [ on ] (i) │
│ … │ │
│ ────────────────────── │ │
│ [ + User ] │ [ Edit ] [ Delete ]│
└──────────────────────────┴──────────────────────────────────────────────┘
```
### What every control does
| Control | What it does | Notes |
|---|---|---|
| **Roles** | The Access Roles this user holds. | Tooltip `SUS03`. Edit via **Edit** (or assign from a role's own *Users in Access Roles* field). |
| **Active** toggle | Soft-activates/inactivates the user in this project (flips `IsInactive`). | Tooltip `SUS04`. A **soft** inactivate — not a hard delete. |
| **+ User** (footer) | Opens the **Add User** dialog to add someone to the project and pick their roles. | Gated `['security','Add User','Users']`. Admin / Creator only. |
| **Edit** (row) | Re-opens the same dialog as **Edit User**. | Gated `['security','Edit','Users']`. |
| **Delete** (row) | Removes the user from the project (confirm *"Do you want to remove this user from the project?"*). | Gated `['security','Delete','Users']`. **Hidden for Subscription Admins and the Project Creator** — you can't delete the people who own the project. |
### Walkthrough — add a user
1. Open `Studio ▸ Security ▸ Users`.
2. Click **+ User**.
3. Enter the person's email (they must exist in the subscription) and pick one or more **Roles**.
4. Save. The list refreshes and they appear with their roles.
> **Tip.** You can leave a user role-less now and assign them later from **Access Roles ▸ Users in Access Roles** — handy when you're building roles before you know who fills them.
## Access Roles
`Studio ▸ Security ▸ Access Roles` — **the core RBAC model**, and the most important security surface. Everything else (stage gates, hidden buttons, document visibility) resolves against the roles you define here.
Same master/detail layout: a **roles menu panel** (role names) and a **details panel** showing the selected role's Name, resolved **Role Actions**, **Entities** (chips), and **User Emails** (chips). You can deep-link a specific role with `?roleId=`.
### The model in one paragraph
A **Role** = a **Name** + an **Entity** (collection) scope + a **Stage** scope + a set of capability **Actions** + **Allowed Studio Pages** + document/training/summary action grants + optional **label/content filters**. Two of those provide **feature-level** security (Actions and Studio Pages — the `*botModulePermission` gates), and the label/content filters provide **row/label-level** security (which documents and fields a role can even see). Saving a role updates the project's roles in the shared signal, so Studio **re-gates immediately**.
### The Add / Edit Role form
Click **+ Role** to open the dialog. It has **basic** fields (always shown) and **advanced** fields (behind a **Show Advanced Settings** link):
| Field | Layer | What it grants |
|---|---|---|
| **Role Name*** | basic | The role's name. |
| **Entity*** | basic | The collection(s) the role applies to. **Changing it filters the Stage list.** |
| **Stage** | basic | Which lifecycle stages the role works in. |
| **Users in Access Roles** | basic | Assign users to this role here. |
| **Select action(s) for this role** | advanced | The core capability grant (`AllowedActionIds`). |
| **Label selection** | advanced | Which fields the role may *train* on. |
| **Label Content Filter** | advanced | Row-level filter — show only docs where a label = a value. |
| **Training Icons** | advanced | Which annotation tools the role sees. |
| **Allowed Document Actions** | advanced | Per-document operations allowed. |
| **Allowed Studio Pages** | advanced | Which Studio sections the role can open. |
| **Allowed Summary Pane Actions** | advanced | Lookup Update / Re-Group Summary. |
This is a deliberately summarised view. The full field-by-field reference — every control, its help code, what it stores, and quick recipes — is [R5 · RBAC permission reference](/academy/r5). Read it before you build a real role.
## How roles gate lifecycle stages
A lifecycle **stage** has a **Can be viewed by** setting (stored as `ViewedByRoleIds`). The roles you list there are the *only* roles that can see and act on documents resting in that stage (leave it empty and every role can). So gating a stage is a two-step move:
1. Create the role here (e.g. **L1-Reviewer**, Entity = your collection).
2. On the stage, set **Can be viewed by** = that role.
The seeded **Four-Eyes** flow ships exactly this **L1-Reviewer / L2-Approver pattern**: the **L1 Review** stage is gated to `L1-Reviewer` (the first human eye) and the **L2 Approval** stage — the final gate — to `L2-Approver` (the second eye). Two roles, two gated stages, four eyes before approval.
> **Watch out.** **Delete** warns *"Users and workflow stages mapped to this role (if any), will no longer exist…"*. Deleting a role also removes it from any stage gate that referenced it — which can silently leave a stage with an empty `ViewedByRoleIds` (visible to **everyone**). Re-check your stage gates after deleting a role.
## The Access Overview page
`Admin ▸ General ▸ Access Overview` answers the question audits always start with: *who can get into what, right now?* It is a subscription-level map of users and their access across projects — the place to review the whole surface at once rather than project by project. Each user is badged by how they sign in — **SSO** or **Password** — and a sign-in filter isolates exactly the password-only accounts, the question every SSO rollout ends on. It can also act: from a user's detail pane, **⋮ ▸ Generate credentials…** recovers a locked-out or bounced-invite user on the spot — email them a reset link, or share a one-time temporary password (shown once; their live sessions are killed). Use it for periodic access reviews and before offboarding; use `Studio ▸ Security` (above) to actually change grants inside a project.
> **Note.** `/admin` itself no longer opens on a page catalogue — it lands on the **Action Center**, a self-clearing to-do list of setup gaps, incidents, and access risks (a last-admin-standing warning is one of its checks). The admin rail is three sections — **General / Infrastructure / Utility** — with Access Overview under General.
## Try it yourself
Create an **L1-Reviewer** role and gate a review stage to it. (Assumes a Processing collection with a lifecycle — e.g. the one from [UC · Invoice processing](/academy/uc-invoice).)
1. Go to `Studio ▸ Security ▸ Access Roles` and click **+ Role**.
2. **Role Name** = `L1-Reviewer`. **Entity** = your collection (e.g. *Invoices*).
3. Click **Show Advanced Settings**. Under **Select action(s) for this role**, grant the review actions a first-line reviewer needs; add the relevant **Allowed Document Actions**. Leave **Allowed Studio Pages** empty if this is a consumer-only reviewer.
4. Optionally add the user(s) under **Users in Access Roles**. **Create**.
5. Now go to `Studio ▸ Data Model ▸ Lifecycle`, edit your **L1 Review** stage, and set **Can be viewed by** = **L1-Reviewer**. Save.
6. Sign in as that user (or check the Inbox): documents at **L1 Review** are now visible and actionable only to L1-Reviewers (plus any other roles you listed). You've gated a lifecycle stage with RBAC.
## Recap
- A **Role** is the RBAC unit: Name + **Entity** scope + **Stage** scope + capability **Actions** + **Allowed Studio Pages** + label/content filters — feature-level *and* row/label-level security.
- **Users** assigns people to roles; **+ User / Edit / Delete** are Admin/Creator-gated, and the **Active** toggle is a soft inactivate.
- Roles gate lifecycle stages via **Can be viewed by** (`ViewedByRoleIds`); the seeded Four-Eyes flow is the **L1-Reviewer / L2-Approver** pattern.
- Deleting a role can silently un-gate a stage — always re-check stage gates after a delete.
## Where to go next
- [R5 · RBAC permission reference](/academy/r5) — the full Access Role permission matrix: every field, help code, stored key, and quick recipes.
- [D3 · Taxonomy, lifecycle, tags & events](/academy/d3) — the stage model and **Can be viewed by** gating that roles plug into.
- [G5 · Audit & compliance](/academy/g5) — the trail that proves who did what.
- [G3 · Policy & guard rails](/academy/g3) — the soft-governance layer that sits on top of hard RBAC.
---
## G2 · Human-in-the-loop
URL: https://www.botminds.ai/academy/g2
> Botminds Academy — Platform · Governance
# Human-in-the-loop
> **In one line.** Agents do the volume, humans do the judgment — human-in-the-loop is the
> machinery that decides which documents a person must see, queues them, captures the
> correction, and records the decision, so you can trust the ninety percent nobody looked at.
> **You'll be able to.** Trace a document from the confidence gate to the Inbox to a reviewer's
> sign-off, and configure the three controls that govern all of it: the Auto-Decide policy, the
> per-stage **Send to Inbox** flag, and the role-gated four-eyes stages.
## Why the loop exists
An agent that processes ten thousand invoices a day is only useful if someone can answer the
question "why should I believe it?" Our answer is structural, not statistical: the platform
never asks you to trust the model. It asks you to trust a process — one where AI recommends,
confidence decides who looks, two humans confirm anything that matters, and every step is
written down. The agent supplies throughput; the human supplies judgment; the lifecycle is the
contract between them.
This division of labour is deliberate. If every document routes to a person you have built a
manual queue with extra steps. If none do, you have removed the safety net. The whole design
of human-in-the-loop is about routing *only the doubtful documents* to a person — and shrinking
that set over time.
## The confidence gate — what routes, and why
Every Processing collection is seeded with the eight-stage **Four-Eyes** lifecycle
(Intake → AI Processing → AI Recommendation → L1 Review → L2 Approval → Needs Info →
Approved / Declined — the full stage reference is in
[Taxonomy, lifecycle, tags & events](/academy/d3)). The fork in that road is
**AI Recommendation**: after the intake agent extracts fields, each field carries a
confidence score (`0..1`), and the document's route depends on whether it clears the bar.
```
AI Recommendation
│
├─ Auto-Decide ON and the doc passes (confidence ≥ 0.92,
│ zero open flags, under the amount cap)
│ └──► Approved / Declined straight-through; audit actor: AI/auto
│
└─ everything else ──► L1 Review (Inbox) ──► L2 Approval (Inbox) ──► Approved / Declined
│ ▲
▼ │ info arrives — re-runs AI Processing
Needs Info (Inbox)
```
Three kinds of documents reach a human: low-confidence extractions, documents with open
flags (a failed validation, a mismatch), and anything the Auto-Decide policy is not allowed
to touch. Clean documents settle themselves; doubtful ones wait for a person. That is the
exception policy, and tuning it is most of the craft of running a workflow
([the Workflow pattern](/academy/sol-wf) walks the full build).
## The Inbox — the queue
Documents that hit a human stage land in the **Inbox** (`App ▸ Inbox`) — the canonical
Human-kind collection ([Core concepts](/academy/s2)), the one list of everything waiting on a
person in the project. When a document enters a stage whose **Send to Inbox (human review)**
toggle is on, the server creates an **InboxNote** that wraps the source document — it carries
the source collection, the document id, and the stage, and shows them on the card's
provenance line.
Items group into fixed sections — **Needs Approval**, **Needs Review**, **Needs Info**,
**To Triage**, **Tasks** — with a **My items / Everyone** scope filter and an
**Open / Snoozed / Done** status filter.
> **Watch out — the Inbox does not act on items.** It is read + snooze + dismiss only. There
> is no approve, reject, or edit button in the Inbox. Each card is a pointer: click **Open**
> and you land on the wrapped document, where the real work happens. When you advance the
> document past its human stage, the Inbox item resolves itself — you never mark it done by
> hand.
Full queue mechanics — cards, snooze behaviour, empty states — are in
[Dashboards & inbox](/academy/e5).
## The reviewer's loop — correct, approve, teach
The work happens on the document detail page ([E3](/academy/e3)) — the split view with the
document on one side and the extracted fields on the other. A reviewer's loop is four moves:
1. **Read the flagged fields first.** Low-confidence values are flagged so your eye goes
straight to what the agent is unsure of.
2. **Verify against the source.** Click a value and the viewer scrolls to the exact segment
it came from and highlights it — the agent shows its work. This is how you catch a
mis-read (a subtotal grabbed instead of the grand total) in one click.
3. **Correct in place.** Edit the wrong value; it saves back to the label. **Rescore** and
**Update {Lookup} Values** re-derive anything that depends on it.
4. **Advance.** From the workflow action pane, perform the stage transition — approve
forward, send back **Needs Info**, or reject.
The part builders underestimate: step 3 is not just fixing one document. Every correction is
a labelled example the trainable extraction model learns from, so the agent extracts that
field better next time. Reviewing *is* training. A review queue that shrinks over months is
the visible result of corrections made today.
> **Role-gated.** A subscription-viewer role gets a read-only summary — every field visible,
> nothing editable, no stage transitions. If fields will not edit, check the role before
> assuming a bug. Roles are covered in [Access & roles](/academy/g1).
## Four eyes for decisions that matter
For consequential decisions, one reviewer is not enough — the Four-Eyes lifecycle enforces
two. **L1 Review** is the first human eye; **L2 Approval** is the second, and the gate. The
seed creates exactly two reviewer roles — `L1-Reviewer` (bound to L1 Review) and
`L2-Approver` (bound to both review stages) — and each stage's **Can be viewed by** control
(`ViewedByRoleIds`) lets you tighten gating further. Because the transitions are role-gated,
no single person can push a document from intake to approved. That is the four-eyes rule made
structural rather than procedural.
Two details worth internalising:
- **Declined is terminal.** The lifecycle has two End stages — **Approved** and **Declined**.
A rejection is not a soft state to be quietly reversed; it closes the document out, on the
record. If the process genuinely needs a way back, model it explicitly — **Needs Info**
loops a document back through AI Processing when information arrives, and
**Allow Back Propagation** on the lifecycle lets L2 send a document back to L1.
- **Sign-off is also an API.** The same stage transition a reviewer performs in the UI can be
performed programmatically through the Runtime API ([V1](/academy/v1)) — same gate, same
audit row — for teams that integrate approval into their own systems.
## Straight-through processing — and how its share grows
Below the stage graph on the **Lifecycle** tab sits the **Auto-Decide policy** card — the
single knob for straight-through processing. It is **off by default**: until you enable it,
every document visits L1 and L2. Switched on, it auto-promotes documents that pass all its
gates:
| Field | Default | Meaning |
|---|---|---|
| **Enabled** | `false` | Master switch. |
| **Min Confidence** | `0.92` | Agent confidence floor required to auto-promote. |
| **Require Zero Flags** | `true` | Any open flag on the document blocks auto-promotion. |
| **Max Amount** | `null` | A monetary ceiling, read from the **Amount Field**; `null` = no cap. |
| **Applies To** | `both` | Which verdicts may auto-fire: `approve` / `decline` / `both`. |
The card previews the policy in plain English — *"Auto-approve when AI confidence ≥ 0.92 AND
zero flags AND amount ≤ $500k."* The safest opening move is **Enabled = true, Applies To =
approve**: auto-approve clean cases, keep human eyes on every decline.
The straight-through share is not fixed — it compounds. Corrections from the reviewer's loop
train the extractor, trained extractors produce higher confidence, and higher confidence
pushes more documents past the gate. A workflow that starts at full manual review and ends
with most volume straight-through, humans handling only genuine exceptions, is the system
working as designed. The review-rate trend is worth a dashboard widget
([Dashboards & inbox](/academy/e5)): a falling rate is your model improving; a rising one is
an early warning that something upstream changed.
## What gets recorded
Every stage move — human or automatic — appends a row to the document's audit trail
(`document_workflow_history`): who moved it, when, from which stage to which, with what note.
There is no separate "decision" object on the platform; the decision *is* that trail, read
back. Auto-decide never spoofs a user: an auto-decided move is recorded under the
`auto-decide` system actor with the confidence in its reason, and every audit row stores an
**actor kind** — human, agent, system, or api-key — so a machine's move can never read as a
person's. The whole story is one click away: the document's **Audit trail** side-sheet shows
the full timeline, stage moves included. When an auditor asks who approved an invoice and on
what basis, the answer is a query, not an investigation — the full compliance picture is
[Audit & compliance](/academy/g5).
## The three places you configure it
Everything above reduces to three controls, all reachable from
`Studio ▸ Data Model ▸ Collections ▸ `:
| # | What you are setting | Where | The control |
|---|---|---|---|
| 1 | The straight-through gate | **Lifecycle** tab, below the stage graph | The **Auto-Decide policy** card — **Enabled**, **Min Confidence**, **Require Zero Flags**, **Max Amount**, **Applies To** |
| 2 | Which stages queue for a human | Each stage's **Create / Edit State** dialog | **Send to Inbox (human review)** — this is `IncludeManualIntervention`, the flag that makes a stage a review stage |
| 3 | Who may act at each gate | The same stage dialog | **Can be viewed by** (`ViewedByRoleIds`) plus the `L1-Reviewer` / `L2-Approver` roles on the four-eyes stages |
Set those three deliberately and you have defined the entire human contract of your workflow:
what skips people, what waits for them, and who is allowed to decide.
## Where to go next
- [Taxonomy, lifecycle, tags & events](/academy/d3) — the full Lifecycle tab reference the
three controls live in.
- [Document detail](/academy/e3) — the page your reviewers will live in.
- [Audit & compliance](/academy/g5) — the record every stage move leaves behind.
- [Invoice processing](/academy/uc-invoice) — a worked build where this loop runs end to end.
---
## G3 · Policy & guard rails
URL: https://www.botminds.ai/academy/g3
> Botminds Academy — Platform · Governance
# Policy & guard rails
> **In one line.** A guard rail is a named policy — a short piece of instruction text you author once and attach to as many agents as you like; this page is the governance discipline around them, and [A8 · Guard rails](/academy/a8) is the mechanics.
> **You'll be able to.** Decide what belongs in a policy, scope it correctly, and set a review rhythm — with an honest view of what enforcement means today.
> **Where this lives.** `Studio ▸ Agent Builder ▸ Guard Rails`; you attach policies from any agent's **Governance** tab.
## Policy as a first-class object
"Stay strictly on the subject of company HR policy." "Never reveal internal pricing." "Always answer in formal British English." Each of those is a guard rail: one rule, written once, reused everywhere.
Authoring policies in one place — instead of burying them in each agent's persona prompt — buys three things:
- **Reuse.** One rule, many agents.
- **Consistency.** Every agent enforces the same wording, not five paraphrases of it.
- **Auditability.** A reviewer can read your governance policies as a list, not hunt through prompts. Treat the Guard Rails page as your policy register: the place someone checks what rules your agents operate under.
## What enforcement means today
Be honest with yourself and your stakeholders about the mechanism.
> **Watch out — enforcement is advisory, not a hard filter.** A guard rail is **prompt-level guidance**: at agent-build time its instruction text is **appended to the agent's instructions**. It strongly steers the model, but the platform does **not** independently read the model's output back and block it if a rule is broken. A capable model will respect a clear instruction; treat guard rails as governance you can rely on for *steering*, not as a guaranteed gate. For anything that *must* be blocked, layer it: a clear guard rail **plus** a human-approval step **plus** a tightly-scoped knowledge base.
> **By design, today.** There is no rule **type**, no input-vs-output switch, no structured condition builder, and no action-on-violation (block / rewrite / warn) in the current build. A guard rail is a name + description + a single instruction — author policy as plain-language text.
The hard boundaries on this platform live elsewhere: **RBAC** decides who can see and do what ([G1 · Access & roles](/academy/g1)), and **lifecycle stage gates** decide who signs off before work leaves a stage ([D3 · Taxonomy, lifecycle, tags & events](/academy/d3)). Guard rails are the soft layer on top of that hard layer — use each for what it is.
## Writing policy that works
- **One rule, one concern.** A guard rail per concern — topic boundary, tone, a forbidden disclosure — reads better and reuses better than one giant rule.
- **Write it like an instruction, not a mission statement.** The text goes straight into the agent's instructions; vague aspiration steers nothing.
- **Don't rely on a guard rail to block.** Pair safety-critical rules with a human-approval step ([G2 · Human-in-the-loop](/academy/g2)).
- **Shrink the temptation.** A topic-boundary rule works best alongside a narrow Knowledge collection, so the agent has little off-topic material to draw on anyway.
## Scope and review cadence
- **Scope: private by default.** New guard rails are **Private** to the project. A policy your other projects need can be **published** to the **Guard Rails Hub** and installed elsewhere, so governance travels as reusable structure ([V4 · Hubs & solutions](/academy/v4)).
- **Apply across agents deliberately.** A guard rail does nothing until an agent references it — attaching the same rule to every agent in scope is what turns a sentence into policy. Wire it on each agent's **Governance** tab.
- **Review the register, not just the agents.** Because policies live as one list, a periodic read-through of the Guard Rails page is a cheap governance review: is every rule still true, still worded tightly, still attached where it should be?
- **Deleting doesn't detach.** Removing a guard rail does not walk back through the agents that referenced it — re-check those agents' Governance tabs after a delete, the same discipline as re-checking stage gates after deleting a role.
## Recap
- A guard rail = a **named, reusable policy** authored once and attached to many agents; the Guard Rails page is your auditable policy register.
- Enforcement today is **advisory prompt-appending**, not an output filter — layer human approval and scoped knowledge for anything that must be blocked.
- Hard control is RBAC and stage gates; guard rails are the soft steering layer above them.
- One rule per concern, private by default, publish to the Hub for cross-project reuse, and re-check attachments after deletes.
## Where to go next
- [A8 · Guard rails](/academy/a8) — the full mechanics: the authoring page, every control, and how a rule runs.
- [G2 · Human-in-the-loop](/academy/g2) — the approval step that turns advisory policy into a real gate.
- [G1 · Access & roles](/academy/g1) — the hard-enforcement layer underneath.
- [V4 · Hubs & solutions](/academy/v4) — publishing a policy for reuse across projects.
---
## G4 · Observability
URL: https://www.botminds.ai/academy/g4
> Botminds Academy — Platform · Governance
# Observability
> **In one line.** Every run leaves a trace — what ran, what it read, what it called, what it cost, what it decided — and knowing where each trace lives turns "the AI did something weird" into a five-minute diagnosis.
> **You'll be able to.** Answer the three operational questions on any live solution: is it working now, what exactly happened on that run, and is quality holding over time.
## Is it working right now?
Start where the work is:
- **The Crew tab** on a collection ([A12](/academy/a12)) — the live view: status pill, pipeline rail, each crew member lighting up as it works, recent decisions and runs. If a demo or go-live has a single pane of glass, this is it.
- **The workspace** ([E2](/academy/e2)) — lifecycle stages are a queue-depth readout: a growing `In review` pile or documents stuck in `New` tells you where the process is jammed.
- **Dashboards** ([E5](/academy/e5)) — throughput, exceptions and aging over time, for the people who own the process rather than the plumbing.
## What exactly happened on that run?
Every execution is recorded, at the level you need:
| Trace | Where | What it answers |
|---|---|---|
| **Agent run trace** | The agent's **Runs** (and the playground, live) | The full loop: inputs, tool calls, output, per-field confidence, token cost, latency |
| **XFlow runs** | `Studio ▸ Automation ▸ XFlow ▸ (flow) ▸ Runs` | Which node ran, with what parameters, what each produced, where it failed |
| **Mesh baton trail** | The crew view for mesh-worked collections | Which member handed what to whom, and where the baton stopped |
| **Document history** | The document's detail pane ([E3](/academy/e3)) | What was extracted, corrected, decided — and by whom or what |
| **Chat & search audit** | `Studio ▸ Search ▸ Audit` and `Studio ▸ Chat ▸ Audit` | What users asked, what was answered, what was retrieved |
The habit that pays: when an output looks wrong, open the run trace *first*. Nine times out of ten the trace shows the cause directly — a missing attachment, a tool that returned nothing, a low-confidence field that should have routed to review.
## Is quality holding over time?
Point-in-time traces don't catch slow drift. Two instruments do:
- **Evaluations** ([A12](/academy/a12)) — scheduled scored runs against golden datasets, compared to a pinned baseline. This is your regression gate for prompt, model and pipeline changes.
- **Review-rate trends** — the share of documents routing to human review is a quality signal in itself: rising review rates mean confidence is dropping somewhere upstream, and the review queue tells you which fields.
## Cost is part of observability
Run traces carry token usage and cost. When a solution gets expensive, the traces show which agent, which step, and usually why — an over-attached knowledge tab or a heavier model than the job needs ([A1](/academy/a1) has the diagnosis table). Measure before switching models; the playground makes the comparison cheap. Environment-wide spend lives in the admin console below.
## The platform-level console
Everything above is per-project. Platform admins (the System Admin role) get a whole-environment console at `Admin ▸ General ▸ Observability` — and `/admin` itself lands on the **Action Center**, a self-clearing to-do list of setup gaps, incidents, and cost breaches. The pages that matter most:
| Page | What it answers |
|---|---|
| **Pulse** | Live platform health at a glance. |
| **Pages · APIs · DB Ops · Jobs · Exceptions** | Performance and error drill-downs — from a slow route down to the offending query or stack trace. |
| **Cost** | LLM gateway spend from the durable daily rollup — usage, health, and spend per workspace and model. |
| **Infra** | What the environment actually runs on: Azure inventory with live health, node/DB/cache metrics, and the real cloud bill (month-to-date + forecast), pulled read-only from Azure. Local stacks show an honest estimate instead. |
| **Budgets · Retention** | Spend envelopes that warn before the invoice, and the data-retention dials. |
## The escalation path, in order
1. **Crew tab** — is work moving?
2. **The stuck document's history** — where did it stop?
3. **The run trace** — what did the worker actually do?
4. **The audit surfaces** — what have users been experiencing?
5. **Evaluations** — did a recent change move quality?
Learn this ladder once and most "something's wrong" reports resolve without an engineer.
## Where to go next
- The live view in depth: [A12 · Crew & evaluations](/academy/a12).
- The queues humans work: [G2 · Human-in-the-loop](/academy/g2).
- The record that satisfies auditors: [G5 · Audit & compliance](/academy/g5).
---
## G5 · Audit & compliance
URL: https://www.botminds.ai/academy/g5
> Botminds Academy — Platform · Governance
# Audit & compliance
> **In one line.** What gets recorded where — the usage log, the immutable audit trail — and how you version, freeze, and publish a solution's configuration so an auditor can trust it.
> **You'll be able to.** Read and export the audit trail, pull one document's complete timeline, tell Activity from Audit, snapshot and freeze a project's configuration, and publish it as a Solution.
> **Where this lives.** `Studio ▸ Security` (**Activity** · **Audit**), the **Audit trail** sheet on any document, and `Studio ▸ Project ▸ Version Control` / `Studio ▸ Project ▸ Publish`.
## Two logs, two questions
The platform keeps two separate records, and mixing them up wastes time:
- **Activity** = usage analytics. "How much time did reviewers spend, on what, and how many annotations did they make?"
- **Audit** = the compliance trail. "Who touched what, when?" — the legal record.
Reach for **Audit** when someone asks a compliance question. (Run traces — what an agent or pipeline actually did — are a third record, covered in [G4 · Observability](/academy/g4).)
## Activity
`Studio ▸ Security ▸ Activity` — an **operational usage log** of document sessions. This is *usage analytics*, not the compliance audit.
The layout is a **Group-By tab strip** on top, a filter bar, then a virtual-scrolled table with **Load more** and **Export**.
| Control | What it does |
|---|---|
| **Group By** (4 modes) | Re-shapes the table: **Session Logs** (raw, ungrouped), **Documents**, **Users**, **Document Stages**. Each mode swaps the columns — e.g. *Documents* shows Title / User Count / Sessions Count / Annotations Count / Active Time / Session Time, with time shown as `total (Avg x)`. |
| **Filters** | Document-name search, **User emails** multi-select, **Workflow stages** multi-select, and a **time range** date-time picker. A **clear-filter** resets all. |
| **Export** | Downloads the activity logs. |
| **Row download** | Per-row download of that entry's logs (opens a result URL). |
| **Load more** | Pages through more rows. |
> **Under the hood.** The word "Document" in the headings is rewritten to your project's entity name (so for an Invoices project you'll see "Invoice"). Times are humanized and localized to your subscription's date format.
## Audit
`Studio ▸ Security ▸ Audit` — **the security / compliance audit trail.** Every access, create, update, delete, and download is recorded here — and so are **export runs** and **notification sends** (with per-recipient delivery status), so the trail has no silent endings: a document's story runs from arrival all the way to the export or email that left the building. This is the immutable record of *who did what to which document*, and the record you hand an auditor.
The layout is a filter bar over a shared audit table with four columns: **UserEmail**, **LogTime**, **AreaType**, **Description**.
| Control | What it does |
|---|---|
| **Document-name search** | Free-text filter on document name. |
| **User emails** | Restrict to specific users. |
| **Learner → Label** | Pick a Learner; the **Label** list cascades from it. |
| **Category / Sub-category** | Filter by collection category (admin/system templates excluded). |
| **Operation** | The event type: **Access**, **Create**, **Update**, **Delete**, **Download**. |
| **Time range** | A date-time window. |
| **Export** | Export the filtered audit rows (through the audit table). |
### Behaviours to know
- **Deep-link filters.** The audit page accepts a `?filterquery=` JSON parameter, so other screens can jump *into* the audit pre-filtered (for example, from a document straight to "everything that happened to this document"). When you arrive via such a link, the filters are already set.
- **Actor identity is stored, not guessed.** Every row records *what kind of actor* acted — **human**, **agent**, **system**, or **api-key** — stamped when the row is written. "A person did this" vs "automation did this" is a stored fact.
- **Rows are immutable, retention is policy.** Once written, an audit row cannot be rewritten through the write path (re-sending the same event is a no-op). Rows are kept forever unless an admin deliberately configures a retention window (`AuditLogRetentionDays`).
- **It's a compliance record.** The audit log is a read-only history — you filter and export it, you don't edit it. Treat it as the authoritative answer to "prove who approved this."
### The per-document Audit trail
"What exactly happened to this document?" used to be a database question; now it's a click. The **Audit trail** side-sheet — opened from a document row's **⋮** menu or the clock button in the document header — federates the seven underlying stores (workflow history, label edits, agent runs, xflow steps, mesh runs, ingestion phases, and the audit log — exports and notifications included) into one newest-first timeline. Events group by phase — **Ingestion · Processing · Review · Output · Error** — each with an actor chip (human / agent / system / api-key), a plain-language summary, and expandable before/after detail; a `{ } Sources` lens shows which stores answered, and a sick source is flagged as unavailable rather than silently missing. **Export CSV** downloads the loaded trail for an auditor. External systems can pull the same timeline through the Runtime API (`GET /api/runtime/v1/documents/{docId}/audit`) — and reading the trail is itself audited.
## Version Control
`Studio ▸ Project ▸ Version Control` — Git-style history, snapshots, and **freeze** governance for your project's **configuration** (not its documents).
A card with a **freeze-status chip** floating top-right and a 3-tab group below it. The chip shows green **Active** (`lock_open`) or red **Frozen** (`lock`); its tooltip is *"click to manage"* and clicking it jumps you straight to the **Governance** tab.
```
┌───────────────────────────────────────────────────────────[ Active ]─┐
│ [ History ] [ Snapshots ] [ Governance ] │
│ ────────────────────────────────────────────────────────────────── │
│ History: │
│ * a1b2c3d amy@acme.com 2026-06-12 14:02 "tighten L2 gate" │
│ * 9f8e7d6 bob@acme.com 2026-06-10 09:15 "add region filter" │
│ └─ select a commit → diff panel + [ Rollback ] │
│ [ Commit… ] │
└──────────────────────────────────────────────────────────────────────┘
```
| Tab | Help | What it does |
|---|---|---|
| **History** | `VC001` | Lists configuration **commits/tags** (sha, author, timestamp). Select one to load a **diff panel**; supports **Rollback** and a **Commit** modal to record a new checkpoint with a message. |
| **Snapshots** | `VC002` | **Export** config snapshots — a **compact** export or a **full/heavy** one — tracks your recent exports, and lets you **restore** a configuration from a snapshot. |
| **Governance** | `VC003` | **Freeze / Unfreeze** the project. Freeze locks configuration; unfreezing opens a confirm modal. Shows a **freeze audit log** of every Freeze/Unfreeze event. |
### The freeze concept
**Freezing** a project marks its configuration as locked (`FreezeConfig`). Once frozen, the History and Snapshots tabs receive that flag and **gate destructive actions** — so nobody can quietly rewrite a configuration you've blessed for production. Unfreeze when you genuinely need to change it, then re-freeze. The chip is always visible on this page, so you can tell a project's freeze state at a glance.
> **Tip.** A good rhythm: **commit** at each meaningful config milestone, **snapshot** before a risky change (so you can restore), and **freeze** once a solution is stable and shipping.
## Publish
`Studio ▸ Project ▸ Publish` — package the **whole project** as a reusable, published **Solution / Template**: a logo, name, description, tags, dashboards, and which Studio tabs appear in the template tour. The natural endpoint of the governance rhythm: version it, freeze it, then ship the blessed configuration. Where the package then goes — hubs, signing, installing — is [V4 · Hubs & solutions](/academy/v4).
| Field | What it does / rules |
|---|---|
| **Logo** | Either **upload** an image (max **2 MB**, max **1024×1024 px**, validated in-browser) or pick one of up to 4 **default images**. |
| **Solution Name*** | Required, max 100 chars; letters/numbers/`_`, must not start with `_`. |
| **Description*** | Required; rich-text (bold/italic/links). |
| **Tags** | Up to **10** tags from suggestions or custom; **at least 1 tag is required to Publish**. |
| **Overview Template** | Binds a dashboard as the published overview (clearable). |
| **Input form** | Adds **Publish Template** form templates; drag to reorder. |
| **How To Templates** | Adds dashboards as "how-to" guides; drag to reorder. |
| **Publisher Name** | Your name or org (max 100 chars). |
| **Template Setup Tabs** | Choose which Studio **modules and features** ship in the template tour (see below). |
### Template Setup Tabs
Each subscription-enabled Studio **module** appears as a card with a parent **slide-toggle**; toggling the parent cascades to all its children. Clicking a module's label opens a **Module Feature Popup** — chips **All / Enabled / Disabled** (with counts), a feature search, and a flat list of every nested feature, each with its own toggle. This is how you decide exactly which parts of Studio a *recipient* of your published solution will see. On save, three tabs are **always** appended — **Overview**, **Configurator**, **How To** — the template-tour defaults.
### Draft vs Publish vs admin Update
| Action | Who | What happens |
|---|---|---|
| **Save** (draft) | builder | Saves a **draft** (status *Saved*) — your work-in-progress publish config. Drafts auto-load next time you open this page. |
| **Publish** | builder | Publishes the solution live (status *Active*). **Disabled unless the form is valid AND at least one tag is set.** |
| **Update** | admin | When this same form is opened from the admin Solutions catalog (admin mode), the primary button becomes **Update** and the Publish button is hidden. |
> **Under the hood.** The exact same component runs in *builder mode* here and in *admin mode* from the Solutions admin catalog — which is why "Publish" (builder) and "Update" (admin) are the same screen with a different primary action.
## Recap
- **Activity** = usage analytics (group by Session / Documents / Users / Stages, filter, export); **Audit** = the immutable compliance trail (Access / Create / Update / Delete / Download, plus exports and notification sends), actor-kind stamped, unrewritable, retention-by-policy, deep-linkable via `?filterquery=`, exportable for auditors.
- The per-document **Audit trail** sheet (and its Runtime API twin) federates every store into one phase-grouped, actor-attributed timeline — with CSV export.
- **Version Control** = commits/diffs/rollback (History), export/restore (Snapshots), and **freeze/unfreeze** with its own freeze audit log (Governance).
- Commit at milestones, snapshot before risky changes, freeze what ships.
- **Publish** packages the whole project as a Solution — logo, tags, Template Setup Tabs; draft via **Save**, go live via **Publish**.
## Where to go next
- [V4 · Hubs & solutions](/academy/v4) — where a published Solution goes: the Hub, signing, and installing into another project.
- [UC · Package & ship](/academy/uc-ship) — the end-to-end packaging walkthrough.
- [G1 · Access & roles](/academy/g1) — the roles whose actions this trail records.
- [G4 · Observability](/academy/g4) — run traces: what the *machine* did, alongside what the *users* did.
---
## Botminds Academy
URL: https://www.botminds.ai/academy
> Botminds Academy chapter
# Botminds Academy
> **Hire an expert agent. Give it a collection of work. Watch it think.**
> That sentence is the whole platform. This academy teaches you to do it at any scale — no code required.
Everything here is written for builders, not spectators. Every chapter ends with something you can click, and every solution is one you can ship. If you read nothing else, read [What is Botminds](/academy/s1) and then spend [your first 30 minutes](/academy/s3) actually building.
## Three ways in
| If you want to… | Start at |
|---|---|
| Understand what the platform is and why it exists | [S1 · What is Botminds](/academy/s1) |
| Build something real in half an hour | [S3 · Your first 30 minutes](/academy/s3) |
| Look up what a specific screen or control does | The **Platform** pillars in the sidebar |
## The platform does three things
Every solution you will ever build on Botminds is one of three shapes — a ladder of ambition. Find your goal, start at that rung.
| Level | Shape | What it is | Example |
|---|---|---|---|
| 1 | [**Agentic Search**](/academy/sol-search) | Conversational, cited answers over your documents and data | A policy assistant that answers with sources |
| 2 | [**Agentic Workflow**](/academy/sol-wf) | A multi-step automation that processes work and decides, with humans on the edge cases | Invoice settlement, claims triage |
| 3 | [**Agentic System**](/academy/sol-sys) | A governed domain brain: many collections, an agent fleet, compliance and reporting together | A loan origination platform |
Each level composes the one below it. Learn level 1 and you already know a third of level 3.
## Built from four pillars
Whatever the shape, you assemble it from the same four pillars. Learn them once; recombine them forever.
| Pillar | What it covers | Start |
|---|---|---|
| **Agents** | The workers: models, instructions, tools, skills, guard rails, pipelines, teams | [A1 · Agent anatomy](/academy/a1) |
| **Data** | The work and the knowledge: collections, schema, lifecycle, ingestion | [D1 · Collections & schema](/academy/d1) |
| **Experience** | What your users see: workspace, chat, dashboards, pages | [E1 · Getting oriented](/academy/e1) |
| **Governance** | What keeps it safe: access, human review, policy, audit | [G1 · Access & roles](/academy/g1) |
## How this academy is organized
- **Start Here** — three short chapters: what the platform is, the concepts that carry everything else, and a guided first build.
- **Platform** — the reference toolkit, one pillar at a time. What every screen is for and what every control does.
- **Solutions** — the three shapes, each with worked builds you follow click by click, easiest first.
- **Developer** — the platform from the outside: Runtime API, MCP, embedding, distribution.
- **Reference** — the glossary and the exhaustive field-by-field appendices.
You do not need to read it in order. The sidebar is the map; the search box above it finds anything by name.
---
## R0 · Glossary
URL: https://www.botminds.ai/academy/r0
> Botminds Academy — Reference
# Glossary
A one-paragraph definition of every term in the Academy, plus the old "wire" name where the UI was renamed. Skim it once now; come back whenever a word is unfamiliar. Terms are grouped, not alphabetised, so related ideas sit together.
> **Naming drift — read this first.** The platform has been renamed in place several times. The **UI and this Academy** use the new names; the **API/URLs/database** still carry the old ones. They are the same thing. The big three:
>
> | The Academy says | The code/URL says |
> |---|---|
> | **Project** | `finon` (`FinonId`, `api/finon/*`) |
> | **Collection** | `Entity` (`RelationalEntity`, `EntityId`) |
> | **XFlow** | `Workflow` (`bm.workflows`) — *but a "Lifecycle/Stateflow" is a different thing; see below* |
---
## The containers
- **Subscription** — The tenant / billing boundary; a workspace owner. Holds Projects, users, roles, and payment. The outer scoping ring on every request.
- **Project** *(code: finon)* — The workspace you build inside. Owns Collections, Agents, XFlows, Connectors, taxonomy, dashboards, roles. Almost everything is scoped to one Project.
- **Collection** *(formerly: Entity)* — The operational home for **one type of record** in a Project — its schema, pipelines, lifecycle, and surfaces. Has two independent axes: **Category** (Processing vs Knowledge — *why it exists*) and **Kind** (Agent vs Human — *who works it*). See [D1 · Collections & schema](/academy/d1).
- **Document** — One ingested record (PDF, crawled page, pasted text, form submission). Exists in the list *before* extraction finishes (you see a "Processing…" chip), then fills in with extracted fields, sections, and lifecycle history.
## Collection flavours
- **Processing collection** — Each document moves through review **stages**, an agent extracts and scores its fields, humans confirm, a decision is recorded. The "decide on each document" case (invoices, claims, contracts).
- **Knowledge collection** — Each document is turned into searchable knowledge (chunked, embedded, indexed) so agents can *read and cite* it. The "answer questions over a corpus" case (handbooks, manuals, FAQs). *Partly forward-looking in the current build — see [D2 · Collection types](/academy/d2).*
## The schema (what to pull out)
- **Taxonomy** — The extraction schema as a tree: **Learner → Collection → Label**.
- **Learner** — A trainable extractor / schema container attached to a Collection; the top of the schema tree.
- **Label** *(UI: Field)* — A single extractable field (a name + a type, e.g. `invoice_total` / currency). The thing an agent fills in and a human can correct. "Field" is the UI word; "Label" is the storage word — same thing.
- **Schema** — Not a separate object: a schema **is** a Learner plus its set of Labels. An agent's output targets a schema.
## The lifecycle (how a document moves)
- **Lifecycle / Stateflow** *(also: Workflow stages)* — The ordered **stages** a document passes through in a Processing collection, with role-gated transitions between them. **This is NOT an XFlow.** The default is the 8-stage **Four-Eyes** flow.
- **Four-Eyes flow** — The default lifecycle seeded on new Processing collections: Intake → AI Processing → AI Recommendation → L1 Review → L2 Approval → Needs Info → Approved / Declined. "AI recommends, two humans confirm, the platform remembers."
- **Stage** — One step in a lifecycle. Can require human review, be gated to specific roles, and trigger automations.
- **Decision** — Not a stored object: a decision is *inferred* from the document's stage history (the audit trail).
## The workforce (runnables — things that execute)
- **Agent** — A configured LLM-backed worker: instructions + model + tools + skills + MCP + guard rails + knowledge + (optional) sub-agents. Built from a config row at runtime. See [A1 · Agent anatomy](/academy/a1).
- **Agent mode (Auto / Fast / Thinking)** — How an agent executes, picked on the agent's **Model** tab. **Fast** = a low-latency tool-use loop. **Thinking** = extended reasoning with human-in-the-loop support. **Auto** (the default option in the picker) lets the platform route between Fast and Thinking per request; the routing behaviour is still maturing, so pick Fast or Thinking explicitly when you need predictable behaviour.
- **Multi-agent Team** — One leader agent delegating to member agents *in-process*. Modes: **coordinate** (delegate + synthesise), **route** (pick one member), **collaborate** (all in parallel), **sequential** (pipe member-to-member).
- **Mesh** — A **durable, restart-surviving pipeline** wiring runnables (agents, XFlows, other meshes, Services) together by queues/topics over a database-backed bus. For long, multi-step, fault-tolerant automations. A mesh member has a 240-second ceiling; longer work must be a **Service**.
- **XFlow** *(code: Workflow)* — A visual **pipeline**: a graph of **operators** (a Python step, an agent call, a SQL query, an API call, a vector-ingestion step…). The reusable "verb" that processes documents. *Distinct from a Lifecycle/Stateflow, which is the document's stage machine.* See [A10 · XFlows & pipelines](/academy/a10).
## Capabilities (what a runnable can use)
- **Tool / Function** — A callable an agent can invoke: either a built-in toolkit (SQL search, knowledge retriever) or a custom API tool you register with a URL + input schema.
- **Skill** — A reusable, parameterised capability (a named prompt/tool bundle) an agent can call. Catalogued per-Project.
- **Skill Pack** — A bundle of Skills that expands to its members when loaded.
- **MCP Server** — A Model-Context-Protocol server that exposes a set of *external* tools to an agent over a transport (HTTP/stdio), with its own auth. See [A7 · MCP servers](/academy/a7).
- **Guard Rail** — An input/output validation or safety filter attached to an agent. See [A8 · Guard rails](/academy/a8).
- **LLM / Model** — A concrete provider model instance (Azure OpenAI, Gemini, …) configured with an endpoint + credentials. Agents pick one (with failover).
- **AI Model** *(trainable extractor)* — Distinct from an LLM: the platform's own trainable extraction model that a Learner trains against labelled examples and scores with accuracy reports.
## Data & integration
- **Connector** — An identity binding to an external data source (SharePoint, Drive, a public feed). *Connector = identity.* See [D4 · Ingestion & connectors](/academy/d4).
- **Source / Job** — A scoped instance of a Connector ("the `/Legal` folder of Drive connector X") that owns scheduling, drip, and dedup. *Job = scope.*
- **Event / Webhook** — A Collection-level subscription that fires on lifecycle/label changes, calling out to an external URL.
- **View** — A saved, filtered projection over a Collection's documents — a named query that surfaces extracted labels as columns. End-users pick Views to slice the document list.
- **Datasheet** — A flat SQL table (the platform's structured-data layer), sourced from databases/spreadsheets/APIs *or* materialised from a document View. Agents query it by SQL. See [D5 · Drive & datasheet](/academy/d5).
- **Drive** — Project file storage: a folder tree + file browser for raw files.
- **Service (async)** — A registered **external** long-running worker (GPU model, OCR, slow partner API) that exceeds the mesh's 240-second limit. It **pulls** jobs from the platform over a small HTTP gateway. *Flag-gated.*
- **Library / Derivation Library** — Studio-authored sandboxed Python callables reused inside XFlow/mesh nodes. Not a public package — a private snippet store.
- **Bot (RPA)** — A robotic-process-automation worker that feeds structured data into the platform (e.g. an Excel-from-bot path into a datasheet).
## Distribution
- **Solution** — A bundled, exportable Project recipe (collections + pipelines + skills + dashboards) shipped as a package that creates a **new** project elsewhere.
- **Object Package** — A newer, finer-grained package: publish a single agent / team / mesh into an **existing** project. *Partly forward-looking — see [V4 · Hubs & distribution](/academy/v4).*
- **Hub** — The registries that Solutions and Object Packages publish to and install from: the per-object tabs and Solutions catalog in `Studio ▸ Hubs`, plus the external, **signed** Solution Hub.
- **EMBED / DECLARE / REBIND** — How a package handles each dependency on install: **EMBED** = ship the config by value; **DECLARE** = require an environment capability, never ship it (e.g. a model class); **REBIND** = a project-local data dependency wired up at install (e.g. which Knowledge collection to attach). *The rule: structure travels, data doesn't.*
## Surfaces & roles
- **Studio** — The no-code builder: a left rail of sections (Agent Builder, Data Model, Connector, AI/Asset Builder, Search, Chat, Intelligence, Security, Hubs).
- **Consumer App** — What end-users see: document lists, the viewer, chat, search, dashboards, the inbox.
- **Agent OS** — A newer agent-first consumer landing (Home / Agents / Work / Live), partly flag-gated. See [S2 · Core concepts](/academy/s2).
- **Inbox** — The human-in-the-loop work queue: items needing a person land here; the actual review happens on the underlying document.
- **Role** — A named set of permissions in a Project (e.g. `L1-Reviewer`, `L2-Approver`, `Admin`). Lifecycle stages are gated to roles. See [G1 · Access & roles](/academy/g1).
- **Lab flag / Feature flag** — A toggle (mostly in an admin "lab" menu) that turns on in-progress surfaces. Pages name the flag whenever a feature is gated.
## Three apps
- **Backend (BE, .NET)** — System of record + control plane: auth, CRUD, uploads, lifecycle, audit, RBAC. Postgres is canonical.
- **Agent-Orchestrator (AO, Python)** — Execution plane: runs XFlows (as Prefect flows), agents (Fast/Thinking), teams, meshes, vector ingestion, chat streaming.
- **Frontend (FE, Angular)** — Studio + consumer surfaces. Pure client.
---
*Next: [S2 · Core concepts — the two heroes](/academy/s2), which connects all of these into one picture you can hold in your head.*
---
## R1 · Agent-builder field reference
URL: https://www.botminds.ai/academy/r1
> Botminds Academy — Reference
# Agent-builder field reference
This reference enumerates every field in the agent editor, tab by tab — for both the current tabbed builder and the legacy single-page editor it replaced. The concepts behind the fields (what each tab is for, how to build a working agent) are taught in [Your first agent](/academy/a3); come here when you need the exact name, type, range, or behavior of a control. Both layouts read and write the same agent object — the field names below are identical, only the arrangement differs. Save is always explicit (a **Save Agent** button, never autosave) and is disabled while the form is invalid.
## Which layout am I looking at?
The editor renders one of two layouts, switched by the `newAgentBuilder` flag.
| Layout | Shown when | Shape |
|---|---|---|
| **New tabbed builder** (default) | `newAgentBuilder` ON — the shipped default | 8-tab builder pane + a split **Playground** pane. `data-testid="agent-builder-new-shell"`. |
| **Legacy single-page editor** | `newAgentBuilder` OFF, or URL `?newBuilder=0` | One scrolling 30% form on the left + 70% playground on the right. `data-testid="agent-builder-legacy"`. |
> **Flag-gated (override).** You can force a layout for one browser session with the URL query `?newBuilder=1` (new) or `?newBuilder=0` (legacy). This is per-session and overrides the baked default. The separate `agentHarness` flag changes only the Agents right-pane (the view-equals-edit mirror), not this editor — see [Your first agent](/academy/a3).
## The current tabbed builder
The builder pane carries an 8-tab strip. Each tab below lists every form control, what it does, and what a builder should put there.
### Tab 1 — Persona
Who the agent is and what it does, in plain language.
| Field | Type | What it does / what to put |
|---|---|---|
| **Name** | text (required) | The agent's display name across Studio and lists. Keep it task-named: "Invoice Extractor". |
| **Description** | textarea | One or two lines a teammate can scan. Surfaces in the Agents list row. |
| **Instructions** | 14-row textarea (required) | The system prompt / persona — the heart of the agent. Says who it is, what to do, how to behave, what to return. Supports global-variable placeholders `{{scope.X}}`. |
| **Field co-pilot** | inline button on Instructions | Type a one-line seed ("extract invoice fields and flag overdue ones") and it expands a fuller draft you then edit. |
### Tab 2 — Model
Which LLM powers the agent and how it reasons.
| Field | Type | What it does / what to put |
|---|---|---|
| **LLM Model** | multi-select | One or more of the project's registered models. Multiple selections form a failover pool. |
| **Agent Mode** | select | **Auto** / **Fast** / **Thinking**. **Auto** is the first, default-selectable option — the agent routes per question (Fast for simple lookups, Thinking for analysis); routing is still maturing, so pick Fast or Thinking explicitly for predictable behavior. **Fast** = single-pass, low latency; **Thinking** = multi-step reasoning before answering. |
| **Enable thinking budget** | toggle | Caps how much reasoning the model may spend (Thinking mode). |
| **Thinking budget** | slider (−1 to 24576) | Token budget for reasoning. −1 = uncapped / model default; higher = more deliberation, more cost and latency. |
| **Advanced sampling** (expander) | — | Tune output randomness — leave default unless you have a reason. |
| ↳ Temperature | slider (0–2) | Higher = more varied wording. For extraction, keep low (0–0.3). |
| ↳ Top P | slider | Nucleus sampling cap. |
| ↳ Max tokens | number (0–4000) | Hard cap on answer length. |
| ↳ Frequency penalty | slider (−2 to 2) | Discourages repeated tokens. |
| ↳ Presence penalty | slider (−2 to 2) | Discourages repeating topics. |
| ↳ Seed | number | Fix for reproducible outputs while testing. |
### Tab 3 — Knowledge
What the agent is allowed to read. Three source sub-tabs.
| Sub-tab / field | Type | What it does / what to put |
|---|---|---|
| **Views** ▸ View | select | A saved, filtered slice of a collection the agent may query. |
| **Views** ▸ Filter by view | toggle | Restrict the agent to only the documents inside that View. |
| **Datasheets** ▸ Datasheet | select | A SQL table the agent may query. |
| **Knowledge collections** ▸ select | multi-select (flag-gated) | Attach Knowledge-corpus collections (writes `KnowledgeCollectionIdsStr`). Shows the attached list and a readiness dot per collection. Visible only with the `knowledgeCollections` flag. |
| **Knowledge lock** | toggle | The agent answers only from attached knowledge — no general world knowledge. |
| **Exact-match lock** | toggle | Forces exact-match retrieval rather than semantic similarity. |
### Tab 4 — Capabilities
What the agent can do — its tools, MCP connections, and skills.
| Section / field | What it does / what to put |
|---|---|
| **Tools** — + Add tool | Opens the tool picker; selected tools render as cards (remove per card). A tool is a callable: SQL search, a retriever, a custom API. |
| **MCP servers** — + Add MCP server | Menu of registered MCP servers (each tagged with a scope badge — From Environment / From Subscription). Cards show the connection. |
| **Skill Packs** — + Pin pack | Pin a reusable skill bundle. Cards show "Pack", N skills, scope badge. |
| **Skills** — + Pin skill | Pin individual skills. Cards show a **Pinned** badge, the runtime, and an "also in pack X" collision badge if a pinned skill is already in a pinned pack. |
| **Restrict this agent to pinned skills only** | Checkbox. When on, the agent may use only pinned skills — it ignores otherwise-discoverable in-scope skills. |
| **Ghost list** | A faint list of auto-discoverable in-scope skills, each with a **Pin** button — promote a discovered skill to a pinned one. |
### Tab 5 — Output
The shape of what the agent returns. Five mode cards at the top (toggles).
| Field | Type | What it does / what to put |
|---|---|---|
| **Table output** | mode toggle | Return rows/columns rather than prose. |
| **Standardization** | mode toggle | Normalize values to a canonical form (single-agent only). |
| **Structured output** | mode toggle (permission-gated) | Extract typed fields against a schema — turns on the sub-form below. This is the invoice/extraction mode. See [Schema](/academy/d1) for building the schema itself. |
| **Section classification** | mode toggle | Classify each section of the document. |
| **Auto-annotate document** | mode toggle | Write extracted values back as annotations on the source document. |
| **Taxonomy / Learner** (`LearnerId`) | searchable select | (Structured) the schema whose Labels/Fields the agent fills. |
| **Without Hierarchy / Select All labels** | checkboxes | (Structured) shortcuts for flat schemas / extracting every label. |
| **Process unit** | segmented (Page / Section / Image) | (Structured) the chunk the agent reasons over at a time. |
| **Merge pages** | toggle | (Structured) treat multi-page docs as one unit. |
| **Images per batch / Parallel batches** | numbers | (Structured, image unit) throughput controls. |
| **Send text with images** | toggle | (Structured, image unit) include OCR text alongside page images. |
| **Quality check agent** | toggle + instructions | (Structured) a second pass that QC-checks the extraction. |
| **Labels** list — Add / Add all | rows | (Structured) per-field rows: **Label** select + **Description** (the per-field instruction that most improves accuracy). |
| **Enable Reasoning / Confidence Score / References** | toggles | (Structured) return the why, a 0–1 confidence per field, and source citations. Confidence drives "needs review" routing. |
| **Limit rows** (`NoOfRows`) | number | Cap rows returned (table/structured). |
| **Use download filename** | toggle | Name exports from the source filename. |
### Tab 6 — Governance
The rules the agent must obey, and where a human signs off.
| Section / field | What it does / what to put |
|---|---|
| **Guard rails** — + Add | Attach named policy objects (chips, removable). |
| **Approvals ▸ Tools (n)** | Per-tool rows: approval state (**Approval required** / **Auto**), a settings icon to tune the HITL prompt (type **Form** / **Multi-Select** + approval-card text), and an enable toggle. |
| **Approvals ▸ Team agents (n)** | Per-member approval toggle. Disabled unless the agent has team members (Subagents tab). |
### Tab 7 — Context (Context Kernel)
Fine control over what context gets assembled into each prompt. Advanced — the **Profile template** default is fine for most agents.
| Section / field | What it does / what to put |
|---|---|
| **Profile template** | A named context recipe; editing any field flips it to "Custom". |
| **Sources** table | Per provider: On checkbox, Source, **Tier** (1/2/3), **Priority** (0–100). Tier-1 sources are spent first. |
| **Variables allowed** | Scope chips (checkboxes) — which `{{scope.X}}` variables the agent may read. |
| **Token budgets** | Per-tier token caps (Tier 1/2/3 number inputs). |
| **Truncation** | **Strategy** (auto / last_messages / summary_compact), Max prompt tokens, Recent turns kept, History rows fetched, Summariser model (when summary_compact). |
| **Preview** — Run preview | Renders the final assembled instructions, spend-by-tier, and which blocks were kept or dropped — before you ever run the agent. |
### Tab 8 — Subagents
Turning this agent into a team coordinator that delegates to member agents.
| Section / field | What it does / what to put |
|---|---|
| **Coordination mode** | Select (shown when at least one subagent exists) — how the leader sequences members. |
| **Subagents** list (`AgentTeams` form array) — + Add subagent | Per row: **Agent** select (team-tagged agents), **Prefix instructions** textarea (member-specific guidance), **Reasoning** toggle, remove. |
| Empty state | No subagents = a normal single agent. Adding the first subagent makes it a coordinator. |
### Save footer, persistence, and keyboard
- **Save Agent** — disabled when the form is invalid; shows "Saving…" while in flight. No autosave.
- Active tab and pane-collapse states persist in `localStorage` (`agent-builder.activeTab`, `.playgroundState`, `.builderState`).
- **Ctrl/Cmd + \** toggles the Playground pane; **Ctrl/Cmd + Shift + \** toggles the builder pane (never both collapsed at once).
## The shared Playground pane
A two-tab group — **Playground** | **Task & metrics** — identical in both layouts.
### Playground tab
| Control | What it does |
|---|---|
| **Chat transcript** | Markdown answers, tables, charts, thinking blocks, tool-attachment download links. |
| **HITL approval panels** | When a tool/step needs sign-off: **Reject** / **Review** (leave feedback) / **Approve & Execute**. |
| **Input Type** radios | **Text** / **Document** / **Project** — what the agent runs against. |
| **Agent Mode** menu (legacy playground only) | **Fast** / **Thinking** — override per run while testing. The new-builder playground pane has no mode control; set the mode on the Model tab instead. |
| **Enable Chat History** | Toggle — carry prior turns into context. |
| **Document picker** / **Page Numbers** | (Document input) pick a doc and optional page range. |
| **Attachment** (+) | Attach photos and files inline. |
| **Question textarea** | Your prompt. **Enter** to send. |
| **Send** | Runs the agent and streams the answer. |
### Task & metrics tab
| Section | What it does |
|---|---|
| **Input & Output Formats** (accordion) | Sample Input + Sample Output + **Validate** (checks the output conforms). |
| **Evaluation Rule Setup** | **Freeze Task & Metrics** toggle; **Task** select + **Auto-Detect** (analyses your agent and proposes a task); **Metrics** grouped **Primary / Optional / Irrelevant** checkboxes with descriptions. Feeds the Evaluation surface. |
## The legacy single-page editor (`newAgentBuilder` OFF)
Same object, one scrolling left-hand form (about 30%) + the playground (about 70%). Field order, top to bottom:
| Field / section | Notes (maps to which new tab) |
|---|---|
| **Name** (required), **Description** | → Persona |
| **Select the LLM Model** (`LlmModel`, multi-select) | → Model |
| **(Multi-agent) Mode** select + **Agent Team** (`AgentTeams` form array) | → Subagents. Each row: Reasoning toggle, optional Human-approval card (approval-card text via the settings icon), Agent dropdown (grouped Agents / Multi Agents), Prefix textarea, add/remove. |
| **Instructions** (expandable, required, `{{scope.X}}` menu) | → Persona |
| **Tools Configuration** — Add Tools | → Capabilities. Selected tools = cards with a per-tool HITL/approval control. |
| **Guard Rails Configuration** — + Add (permission-gated) | → Governance. Shield chips, dashed empty state. |
| **MCP Servers** — Add MCP Server | → Capabilities. Cards show status dot, URL/command, transport + scope badges. |
| **Knowledge Base Configuration** (tabs **Views** / **Datasheet**) | → Knowledge. Hidden when structured-output / multi-agent / standardization. |
| Toggles: **Filter By View**, **Table Output**, **Standardization** (single), **Structured Output** (permission-gated) | → Knowledge / Output |
| **Structured Output sub-form** | → Output. Taxonomy (`LearnerId`), Without Hierarchy / Select All, **LabelList** (Label + Description), **Process Unit** (Page/Section/Image) + Merge Pages, Images per batch / Parallel batches + Quality Check button, Send Text With Images, Enable Reasoning / Confidence Score / References, Section Classification Agent toggle. |
| **Knowledge Lock** / **Exact Match Lock** toggles | → Knowledge |
| **Advanced Settings** accordion (`AdvancedConfig`) | → Model. Temperature (0–0.9), Maximum Length (0–4000), Top P, Frequency/Presence Penalty (−2 to 2), Relevant Docs / Number of Shards (standardization), Seed, Limit rows (`NoOfRows`), Use download filename, Update Index, **Enable Thinking Budget** + Thinking Budget slider (−1 to 24576). |
| **Save Agent** (sticky, permission-gated, disabled when invalid) | Footer. |
> **Watch out.** The legacy form caps **Temperature at 0–0.9**; the new builder's Advanced sampling allows **0–2**. Same underlying field — the new UI just exposes the wider range.
## HITL approvals — one dialog, two homes
Human-in-the-loop approvals are configured by the same approval-card dialog in two places: the legacy per-tool cards and the new **Governance ▸ Approvals** tab. Either way you set: **Request approval** (enable), **Approval type** (Form / Multi-Select), and the **Approval card text** the reviewer sees. At run time the agent pauses at that step and surfaces a Reject / Review / Approve & Execute panel in the Playground (and in the live consumer run).
## `botHelpInfo` anchor codes
Nearly every field carries a stable `botHelpInfo` code (e.g. `ABA01`, `ABT04`, `AB003`) used for in-app help. They make durable cross-references; if a label is renamed in a release, the code is the stable identifier.
---
## R2 · Connector catalog
URL: https://www.botminds.ai/academy/r2
> Botminds Academy — Reference
# Connector catalog
This reference enumerates every field, kind, and toggle across the Connector surfaces: the Add-Connector wizard, the Add-Job wizard, the Upload modal, the Runs history, the Export dialog, and Input Form templates. The concepts — the Connector vs Job vs Run model and the shape of each screen — are taught in [Ingestion & connectors](/academy/d4); open this page when you need the full field list.
## How to read this
- Fields marked **(req)** are required to advance. Everything else is optional.
- **Test-before-save** kinds cannot be saved until a live connection test passes; editing any field after a green test clears it (re-test). This is a platform invariant.
- Routes are project-scoped: real URLs are `///studio/connector/`.
## Add-Connector wizard
The wizard is 900px. Step count varies: **SharePoint = 3 steps** (kind → auth pattern → form); **every other kind = 2 steps** (kind → form; the auth-pattern step is skipped). Edit/Reconnect mode jumps straight to the form step, pre-filled — **secrets are never pre-filled** — and the stepper is hidden.
### Step 1 — kind tiles (six kinds)
| Kind | Tile copy |
|---|---|
| **SharePoint** | "Pull docs from a SharePoint site" |
| **Email (IMAP)** | "Pull docs from a mailbox" |
| **Botminds Drive** | "Pull docs from this project's internal drive. No setup needed" |
| **Public Feed** | "Pull from public gov data sources (SEC, CFPB, Federal Register)" |
| **Datasheet** | "Re-ingest rows from a datasheet in this project as documents" |
| **Azure Blob Storage** | "Ingest from an Azure Blob container" |
### Step 2 — SharePoint auth pattern (SharePoint only)
Two tiles; the rest of the wizard differs per choice:
| Pattern | What it means | Best for |
|---|---|---|
| **Quick** | "Connect with Microsoft" — the platform handles app registration + consent | SMB / pilots |
| **Enterprise** | "Use my own Entra app" — you paste your own client ID/secret | Enterprise IT |
### Step 3 forms — by kind
**SharePoint · Quick**
| Field | Notes |
|---|---|
| Display name **(req)** | |
| SharePoint site URL **(req)** | On blur, a URL preview chip shows host / site / folder hint |
| **Connect with Microsoft** button | Opens an OAuth popup. App-only token, `Sites.Selected` read-only consent. Popup closed → "Sign-in cancelled"; blocked popup → warning. There is no Save button — the connector completes through the popup callback. |
**SharePoint · Enterprise**
| Field | Notes |
|---|---|
| Display name | Optional — defaults to the site name |
| Site URL **(req)** | |
| Tenant ID **(req)** | GUID |
| Client ID **(req)** | GUID |
| Client secret **(req)** | Password field |
| **Test connection** | Enabled only when all four credential fields are present and Tenant/Client look like GUIDs. Returns pass/fail + latency + an amber hint on failure. Editing any field clears a green test. A duplicate site shows an amber banner: **Cancel** / **Create anyway**. |
| **Save connector** | Enabled only after a clean test with no edits since. |
**Botminds Drive**
| Field | Notes |
|---|---|
| Display name **(req)** | |
| (info box) | "No credentials — the folder is chosen per-Job." |
| **Test connection** | Shows sub-folder count + last-modified date. |
| **Save connector** | |
**Public Feed**
| Field | Notes |
|---|---|
| (feed registry) | Lazy-loaded; a search box filters; tiles grouped by category. **Live** tiles are selectable (primary border); coming-soon tiles are greyed/disabled with tooltip "Available in a future release". Each tile shows icon, name, description, drip description, license + use-case chips. |
| Connector name | Defaults to the feed name |
| **Test connection** | Shows the feed's last item date |
| **Save connector** | Identity is config-only (`{feedId}`) — no credentials |
**Email (IMAP)**
| Field | Notes |
|---|---|
| Display name **(req)** | |
| Email type **(req)** | Gmail / Outlook / Generic IMAP |
| Host **(req)** · Port **(req)** | |
| Username **(req)** · Password **(req)** | |
| **Test connection** → **Create connector** | Save gated on a clean test. |
**Azure Blob Storage**
| Field | Notes |
|---|---|
| Display name **(req)** | |
| **Authentication mode** **(req)** | **Account key** (→ Storage account name + Account key) · **SAS token** (→ Storage account name + SAS token) · **Connection string** (→ Connection string). Secret fields are password inputs. |
| **Test connection** | Pass/fail + latency. Save gated on a clean test; editing any field clears it. |
| (info) | Container, folder path + extensions are configured **per-Job**, not here. |
**Datasheet**
| Field | Notes |
|---|---|
| **Datasheet** **(req)** | Dropdown of this project's datasheets. Empty state explains you must create a datasheet first. |
| Display name **(req)** | |
| (no test) | Internal — identity is `{datasheetId}` only; no credentials, no connection test. A Job on it re-ingests rows as documents; datasheet edits also auto-trigger re-ingestion. |
### Wizard footer
`← Back` (disabled at step 1 / in edit) · `Cancel` · `Next →` / `Save` / `Create` (label per kind).
## Add-Job wizard
3 steps (editing locks the connector → 2 steps).
### Step 1 — pick connector
Radio list of the project's **active** connectors: kind icon + test status + "used by N jobs". Empty → "Cancel and create a Connector first." Hidden in edit mode.
### Step 2 — name + scope + target
- **Job name (req)** — required to advance.
- **Target entity** dropdown **(req)** — real project collections, id-valued (never free text; legacy name values auto-heal; "Default" always present).
- **Secondary XFlows** — comma-separated; each runs after an item is registered.
Kind-specific scope:
| Kind | Scope fields |
|---|---|
| **SharePoint** | Document library (name or driveId — **Test Drive** resolves a name to a stable driveId, with pass/warn + hint) · Folder path (relative to library root; `/` = whole library) · File extensions (space/comma) · Recursive · Max docs per run · **"Pull metadata from SharePoint?"** toggle → pick Taxonomy → mapping rows (Taxonomy label ↔ SharePoint column) with **Discover columns** (lists Display/Internal/Type; click an internal name to copy), **Add all**, **+ Add mapping**, per-row remove |
| **Email** | Folder (default INBOX) · Include attachments · Max docs per run |
| **Drive** | Folder (read-only + **Browse…** picker) · Extensions filter (blank = all) · Recursive · **"Explode structured rows"** (Excel/CSV/JSON → one doc per row) → reveals **Unique ID column** (row business key; blank = content-hash) · Max docs per run |
| **Public Feed** | Fields rendered dynamically from the feed's `scopeShape` (text / multicheckbox / number) |
| **Azure Blob** | Container · Folder path (optional blob prefix, e.g. `invoices/2026`) · Extensions filter (blank = all) · Recursive |
| **Datasheet** | **Document granularity** (One document per row / One document for the whole sheet) · **Max rows per run** (batch cap; continuation drains the rest). New + edited rows are picked up automatically each run. |
### Step 3 — schedule
| Option | Detail |
|---|---|
| **On-demand only** | Runs only via **Run now** |
| **Recurring (every N units)** | Value + Seconds / Minutes / Hours / Days |
| **Cron expression** | `m h dom mon dow` + Timezone |
| Public-feed presets | Hourly / Every 6h / Daily 9am UTC / Weekly Mon 9am / On-demand chips |
| **Next 5 runs** | Live preview of the resolved schedule |
Create button: **Create job** / **Save changes** (edit).
## Upload modal
720px, one-shot — no connector or job:
- Drag-drop or browse (multi-file). List shows each file + size + remove + **Clear all**.
- Multi-file grouping (when enabled): "grouped into one document set (first file primary)".
- **Target-entity** dropdown (unless pre-filled by context).
- **Submit** → result panel: complete / partial / failed · "N of M registered, K failed" · run id · per-file docId or error rows. **Done** closes.
## Runs and run detail
**Runs table** columns: When · Trigger (Upload / On-demand / Scheduled) · Status (completed = green / partial = amber / failed = red / else blue) · the funnel counters `Enum / Fetch / New / Upd / Dup / Disp / Merge / Fail` · chevron.
**Run detail** dialog (1000px): pipeline-summary chips (Enumerate → Fetch → New → Updated → Duplicate → Dispatch → Merge), status + failed count + last error, then a per-item event-log table (When · Stage · Item · Status · Message).
## Export — Add Export dialog
Surface: `Studio ▸ Connector ▸ Output` (`connector/output`). List + details split. Empty → "Setup an export to see more details" + **+ Export**. Details rows: **Type** · **Taxonomy** (chips) · **Storage Type** (Azure Blob / Botminds Drive) · **Storage Details** (Azure: account + container; Drive: drive URL). Row actions: edit / delete.
The Add Export dialog is heavily permission-gated; fields appear conditionally on **Export Type**.
### Always present
| Field | Notes |
|---|---|
| Name | |
| **Export Type** | Drives the rest of the form |
| **External Sources** (destination) | `0` = **Azure Blob** → Storage Name / Key / Container · `1` = **Botminds Drive** → drive-url |
### Conditional on Export Type
| Type | Extra fields |
|---|---|
| Type 0 | Custom Taxonomy multi-select + Custom Template URL (drive-url) |
| Type 2 | Views dropdown |
| Other types | Label selection + selected-label chips |
### Type-1 (split / bookmark) toggles
Split Input Document · Split on Sequential Values · Split By Start Page · Grouped Bookmark · First Value As Bookmark · Group By Label · Order Date (dropdown) · Suffix for document name.
### Common toggles (across types)
Export current-job docs only (type 2) · Add date-wise folders · Add document-wise folders · Export input document · Delete input document from project.
**Save** is disabled while the form is invalid.
## Input Form — Add Form Template dialog
Surface: `Studio ▸ Connector ▸ Input Form` (`connector/form_template`; visible when the form-template surface is enabled for the project). List + details split. Empty → "No Form. Add new form to process" + **+ Add Form** (permission `connector/addTemplate`).
| Field | Notes |
|---|---|
| Name · Description | |
| **Type** | **Create Source** or **Publish Template** |
### Publish Template
| Field | Notes |
|---|---|
| **Sub Type** | **Connector** → pick an ingestion seed-page dropdown · **Global Variables** → multi-select variables |
### Create Source — Columns builder
A **Use Excel** checkbox swaps the per-column rows for a single drive-url (ExcelDriveUrl). Otherwise, each column row:
| Field | Notes |
|---|---|
| Name | |
| **Type** | Text / Multiline / Checkbox / Dropdown / Radio |
| **Label** | Taxonomy-grouped optgroups |
| Value | Dropdown type only |
| Required · Is Title · Is Template | Flags |
| **+ rule** | Nested Rules rows: Field + Value (add/remove) |
| add / remove column | |
If a column is **Is Template**, a **Templates** section appears: Value + **Export Template** + **Rendering Template** (both drive-urls).
Submit: **Create** / **Update**.
## Legacy ingestion (deep-link only)
> **Status.** Route `connector/sources` is no longer wired to the Ingestion rail entry — that always opens Sources v3; this route is deep-link only. It is the old single create-source wizard plus a source-details page. The `add` route is guarded: if the project has `HideAddDataSource`, it navigates back. New builds use v3.
---
## R3 · Schema field reference
URL: https://www.botminds.ai/academy/r3
> Botminds Academy — Reference
# Schema field reference
This reference enumerates every field of the create-collection form, the create-Taxonomy (Learner) dialog, and the create-Label field editor — including all six advanced accordions and the bulk label import. The concepts and the narrative walkthrough live in [Collections & schema](/academy/d1); open this page when you need the full list.
> **Vocabulary reminder.** A **Collection** is a typed home for one kind of record (the code calls it `Entity`/`RelationalEntity`). A **Learner** is the trainable extractor that owns a set of fields (the UI/old docs also call it a **Taxonomy** or **Data Capture** group). A **Label** is one extractable field (the UI calls it a **Field**). A **Schema** is "a Learner plus its Labels" — it is not a separate object.
## Create-collection / General-tab form
The same form is the **Create Collection** modal *and* (when the `collectionsUnified` flag is on) the inline **General** tab. Top to bottom:
| # | Field | Type | Required | Notes |
|---|---|---|---|---|
| 1 | **Purpose** | radio (create-only) | — | **Knowledge** vs **Processing**. On edit it is a read-only Knowledge/Processing chip — **category is immutable after create**. |
| 2 | **Knowledge settings** | accordion | — | Only when Purpose = Knowledge. **Embedding model** (text; blank = project default), **Chunk size** (number, default **2000**), **Chunk overlap** (number, default **10**). Collapsed, defaults fine. |
| 3 | **Collection Name** | text | yes | The display name. |
| 4 | **Description** | textarea | yes | What this collection holds. |
| 5 | **Allowed Ingestion Types** | multi-select (grouped) | — | Whitelists which source types may feed this collection — Upload, Cloud, Connector kinds, dynamically-loaded connectors, and Form Templates (shown as `FT_`). |
| 6 | **Default View** | select | — | Appears only if column-view templates exist. *None* or a named column view. |
| 7 | **Parent Collection** | select | — | Permission-gated (`Parent Collection`). *None* or another collection → makes this a **child collection**. **Disabled once set** (no re-parenting). Reveals the mapping accordions below. |
| 8 | **Enrich Collection Configuration** | accordion | — | **Enrich Xflow** (select: None + project xflows); **Enrich Labels** (`+` rows: Learner + Label); **Flow Trigger Conditional** (`+` rows: Learner + Label + **Value**) — fires the enrich xflow only when the label equals the value. |
| 9 | **Collection Dashboards** | accordion | — | Per-collection dashboard configuration. |
| 10 | **Independent Queue** | accordion (edit-only) | — | If not configured → **Create IQ Request** link; else shows status (Enabled / Disabled / Request Pending / Request Denied) with Enable/Disable buttons. |
| 11 | **Set as Primary** | slide-toggle | — | Exactly **one** Primary collection per project — the default ingestion target. |
> **Flag.** The **Purpose** radio (row 1) is gated by the `knowledgeCollections` flag.
> **Under the hood — where intake assignment went.** The old "Assign to" / Intake-Agent picker was removed from this form. You now pick the worker agent on the **Agents** tab. Internally the picked agent is written to `SecondaryXflowIds[0]` while `PrimaryXflowId` stays a hidden system seed (`__bm_default_ingestion__`).
### Child-collection mapping (revealed when a Parent Collection is chosen)
- **Dependant Configuration ▸ Primary Mapping** — a Source (parent Learner + parent Label) `=>` Target (this collection's Learner + Label) row. Auto-populated/disabled when parented. This wires how a parent's extracted Label becomes a child record.
- **Additional Label Mappings** (sub-accordion, `+` adds rows) — more Source `=>` Target Learner/Label pairs; each row deletable.
## Create-Taxonomy (Learner) dialog
Opened from the **+ Taxonomy** header button or the Schema tab's footer **Taxonomy** button.
| Field | Type | Required | Notes |
|---|---|---|---|
| **Taxonomy Name** | text | yes | Non-empty; duplicate names rejected. |
| **Description** | text | yes | |
| **Type** (`LearnerKind`) | select | yes | What this Learner classifies/extracts — see below. |
| **Entity** | select | yes | Which Collection this Learner belongs to. |
**Submit** is disabled until valid.
### Learner Type (`LearnerKind`) values selectable in the dialog
`SectionClassification` · `PageClassification` · `DocumentClassification` · `TableClassification` · `TableRelationExtraction` · `HtmlRelevancy` · `CellIdentification` · `RowClassification` · `ColumnIdentification` · `ImageAnnotation` · `CellContext`
> **Note.** `Segmentation` and `QuestionGeneration` are valid kinds in the model but are **excluded** from this picker — you will not see them. For most extraction work you want **DocumentClassification** (one Learner per document type) and let its Labels do the field work.
## Create-Label — the field editor
The dialog has two tabs: **Add label** and **Import labels**.
### Core fields
| Field | Type | Required | Notes |
|---|---|---|---|
| **Label Name** | text | yes | The field's name. |
| **Description** | text | yes | What this field captures (guides the extraction agent). |
A **Show Advanced Settings** disclosure reveals six accordions (all optional). Footer: **Add** (saves, keeps the dialog open for the next field) and **Add and exit** (saves and closes).
### Field "type" — how a Label becomes text vs number vs table
There is no single "data type" dropdown the way a spreadsheet has one. A Label's behaviour is shaped by a combination of its **validation rule** (in *View Config*), its **Record Config** (whether it is a record / table), and *Toggles*. The common shapes a builder produces:
| You want… | Configure it as | Where |
|---|---|---|
| **Plain text** | a Label with no special validation | default |
| **Number** | Label + a numeric validation rule | View Config ▸ Validation |
| **Currency / amount** | numeric validation + (optionally) **Enable Total Field** | View Config |
| **Date** | a date validation rule | View Config ▸ Validation |
| **Boolean / yes-no** | a validation rule constraining to two values | View Config ▸ Validation |
| **Single-select / enum** | a validation rule listing allowed values | View Config ▸ Validation |
| **Table / line-items** | turn on **Is Record** and add **child Labels** as columns | Record Config |
| **Masked / sensitive** | **Mask Values** toggle | Toggles |
| **Derived / looked-up** | Lookup Config (Meta Label, Dependent Label Auto Update) | Lookup Config |
> **Tip.** For a builder starting out, 90% of fields are "a Label + a validation rule". Tables (line-items) are the one shape that needs **Is Record** plus child Labels. Everything in the six accordions below is refinement on top of those two ideas.
### The six advanced accordions — every control
**1. Table Styling** — visual styling for table/record output:
- Header background colour, header text colour, body background colour, body text colour (each a colour-picker + hex field).
**2. Contextual Insights** — relationships and derived widgets:
- **Is Dependent Entity document** (toggle)
- **Enable RTD operation** (toggle) — real-time derivation
- **Learner + Label + Aggregation Type** picker — what to aggregate and how
- Widget **label filter**
**3. Record Config** — table / line-item behaviour:
- **Is Record** (toggle) — makes this Label a table; its child Labels become columns
- **Freeze Rows**
- **Label Grouping** (shown when validation Type = 4)
- **Group By** (`ProximityKind`)
- **Minimum Column Width (px)**
- Child-only toggles: **Duplicate Label**, **Add Default Column**, **Unique Label per record**, **Include Top Extraction**, **Include Segment Grouping**, **Enable Filter**
**4. Toggles / Features:**
- **Mask Values** (hide sensitive values in the UI)
- **Expand Label Values**
- **Enrich Label**
**5. Lookup Config** — derive/refresh values from another source:
- **Meta Label**
- **Skip Automation Lookup**
- **Disable Manual Refresh**
- **Dependent Label Auto Update** (+ Learner / Label picker)
- **Consolidated Derivation Label**
- **Show Default Recordview**
**6. View Config** — display, ordering, and validation (the most-used accordion):
- **Top Extraction Count**
- **Sort Using** (e.g. by confidence)
- **Doc Meta Property**
- **Is Data Entry**
- **Enable Total Field** (requires **Is Record**)
- **Add / Edit Validation rules** — this is where number/date/boolean/enum shapes are defined
- **Auto Resolve On Edit**
- **Ignore Errors On Stage Movement**
### Import labels (bulk)
- Tab **Import labels**: drag-and-drop or **Choose File**. Accepts `.txt`, `.xlsx`, `.tsv`, `.csv`.
- Shows a text example and an Excel/CSV format example — parent/child nesting is expressed by indentation (text) or by columns (spreadsheet), so you can import a whole table-with-columns in one go.
- **Upload & Create** creates every Label in one action.
> **Tip.** Importing is the fastest way to stand up a large schema. Build the field list in a spreadsheet (one column per nesting level), then **Import labels ▸ Upload & Create**.
## Schema tab — Learner list controls
The **Schema** tab is a master-detail surface:
- **Left list** — every Learner with Name + Description; a star marks the **Primary** Learner. A type filter (`All · Custom · Default · Imported`) and a search icon narrow the list. Footer buttons **Taxonomy** (create a Learner) and **Import** (import a Learner).
- **Right pane** (a Learner selected) — top-right **+ Label** (Labels sub-tab only) and an action menu with **Edit** (edit the Learner). Two sub-tabs: **Labels** (a hierarchical label tree) and **Details**.
---
## R4 · XFlow node reference
URL: https://www.botminds.ai/academy/r4
> Botminds Academy — Reference
# XFlow node reference
This reference enumerates every node in the XFlow palette, the anatomy of a node card, the canvas and toolbar controls, the Add/Edit and Execute dialogs, and the run-inspection surfaces. The concepts — what an XFlow is, the shape of the editor, how runs work — are taught in [XFlows & pipelines](/academy/a10); come here when you need the exact node, field, or control.
## How to read this
- An **XFlow is a processing pipeline** — a directed graph (DAG) of nodes that does work on documents or data. It is **not** a document Lifecycle/Stateflow (those are the review stages a document moves through). The codebase overloads the word "workflow" for both — keep them strictly apart.
- The editor is the workflow-activity canvas. It opens from the unified **Agents** list in Agent Builder (the `+ Agent` picker offers **XFlow**), and the same editor also has its own Studio home under **Automation ▸ XFlow** (`automation/xflow`).
- Under the hood, an XFlow is persisted to `bm.workflows` + `bm.workflow_tasks` and runs in the Agent-Orchestrator as a Prefect flow. You never see Prefect; you see nodes, edges, and runs.
- Each node has an **Operator Type** that determines its config form (the node config dialog). Some nodes show a warning badge until their required parameters are filled.
- A handful of nodes relate to **Mesh / pub-sub**. In mesh mode the palette is restricted to exactly **XFlow Operator + Queue + Service**. **Subscribe to Topic** and **Publish to Topic** are XFlow-mode pub-sub operators that are not mesh-designer tiles; they are listed here for completeness.
## The full node palette
The palette (top-right of the canvas, draggable; expand/collapse via the expand icon) groups into three kinds: **stage** nodes (big phase-shaped blocks), **activity** nodes, and **functional / operator** nodes.
> **Surfaced vs present-but-filtered.** This reference enumerates the whole node catalogue the engine supports — but the live editor filters the palette. Today only the **functional / operator** nodes plus a single **Python Library** activity are rendered as draggable tiles; the Stage group renders empty and the remaining Activity nodes are not surfaced. Each table below marks whether a node is **In palette** (you can drag it now) or **Filtered** (defined in the model, not currently offered). Build real pipelines from the In-palette rows.
### Stage nodes — coarse pipeline phases
> **All Stage nodes are Filtered** — the Stage group renders empty in the current palette.
| Node | What it represents |
|---|---|
| **Manual Review** | A human-review checkpoint inside the pipeline (work pauses for a person). |
| **Sources (Ingestion)** | Pulls documents in from a connector/source as the pipeline's intake (see [Connectors](/academy/d4)). |
| **RPA Bots** | Hands work to an RPA **Bot**. |
| **Agent Flow** | A phase that runs an agent over the documents. |
| **AI Pipeline** | Runs a chained AI-model prediction pipeline (Asset/AI Builder's chainer). |
### Activity nodes — common processing steps
> Only **Python Library** is surfaced; every other Activity node is **Filtered** today.
| Node | What it does | Surfaced |
|---|---|---|
| **Python Library** | Runs a Studio-authored Python **Library** snippet. | In palette |
| **Export** | Writes documents/extracted data out to a configured Export target (Connector ▸ Output — see [Connectors](/academy/d4)). | Filtered |
| **Data Feeds** | Pulls from / pushes to an external data feed. | Filtered |
| **Conditional** | Branches the pipeline on a condition (a coarse, stage-level branch). | Filtered |
| **Rescore Models** | Re-runs scoring against the trained AI models. | Filtered |
| **Regroup Summary** | Re-groups / summarises documents (e.g. recombine split pages). | Filtered |
| **User Allocation** | Allocates documents to users / review queues. | Filtered |
### Functional / operator nodes — the fine-grained operators
These are the workhorses. Each has an **Operator Type** and a parameter form. This whole group is surfaced in the normal (non-mesh) palette — except the **Mesh** rows at the bottom, which only appear in mesh mode (and even then only Queue + Service; Subscribe/Publish are XFlow-mode pub-sub operators, not mesh-designer tiles).
| Operator node | What it does | Notes |
|---|---|---|
| **Agent Operator** | Calls a configured **Agent** as a pipeline step (the agent-to-pipeline bridge — see [Your first agent](/academy/a3)). | In palette. Pass it input; capture its output downstream. |
| **Bash Operator** | Runs a shell/bash command step. | In palette. |
| **Python step** (via **Python Library**) | Runs your Python logic. | In palette. Authored as a **Library** asset. |
| **API Fetch** | Makes an outbound HTTP/API call and captures the response. | In palette. |
| **SQL Operator** | Runs a SQL query (e.g. against a **Datasheet**). | In palette. |
| **Send Email** | Sends an email (To / Subject / Message, with placeholder tokens). | In palette. |
| **Move To State** | Advances a document to a lifecycle **stage** — the bridge from pipeline to Stateflow. | In palette. This is how an XFlow touches a Lifecycle; the XFlow itself is still not a Lifecycle. |
| **Conditional Operator** | Fine-grained conditional branch at the operator level. | In palette. |
| **Xflow Operator** | Calls **another XFlow** as a sub-step (compose pipelines). | In palette. Reuse a pipeline you already built. |
| **Iterator Operator** | Loops a sub-step over a collection of items. | In palette. |
| **Bot Operator** | Invokes an RPA **Bot** at operator granularity. | In palette. |
| **Vector Ingestion** | Chunks → embeds → indexes text for Knowledge retrieval (the knowledge-spine core step). | In palette. `TaskType 14`; default 16 chunks per batch, 1 parallel batch, 429-aware. Powers Knowledge collections. |
| **Agent Finetuning** | Kicks off an agent / model fine-tuning step. | In palette. |
| **Queue** | A durable queue hop. | Mesh-mode only. |
| **Service (async/parked)** | Hands work to an external long-running **Service** and parks (holds no worker slot). | Mesh-mode only; Service is flag-gated. |
| **Subscribe to Topic** | Receives messages from a pub/sub topic. | Filtered — XFlow-mode pub-sub operator; not a mesh-designer tile. |
| **Publish to Topic** | Emits messages to a pub/sub topic. | Filtered — XFlow-mode pub-sub operator; not a mesh-designer tile. |
> **Under the hood.** The default ingestion XFlow every collection gets is a 5-task pipeline: route-by-job-kind → block-fetch → upload-to-jupiter → construct-document → write-to-Postgres. A **Knowledge** collection adds the **Vector Ingestion** operator as its core step. You rarely edit the seeded ingestion XFlow — you build your own XFlows for downstream processing and point a collection or schedule at them.
## The node card (anatomy of one node)
When a node sits on the canvas it shows:
| Region | What it is |
|---|---|
| **Icon tile** (coloured) | The node-kind glyph. |
| **Label** | Inline-editable name — click to rename. |
| **Description** | Inline-editable subtitle. |
| **Warning badge** | Appears when required params are missing. Fix before running. |
| **Doc-count footer** (optional) | How many documents this node touches; deep-links to those docs. |
| **Expandable detail** | "Can be viewed by" roles + the **Operator Type**. |
| **Hover actions** (permission-gated) | Start-connection (arrow-right) · cancel-connection (arrow-left) · **edit** (or double-click → node config) · **delete**. |
## Edges (connecting nodes)
- **Draw an edge:** hover a node, click its **start-connection** arrow, then click the target node.
- **Edit an edge:** click the edge line → **Edit Edge** dialog with **Name** and **Description**; edit or delete the edge there.
- **Disconnect:** click the line to remove it. Edges carry arrowheads and optional labels.
## Canvas controls
| Control | Location | What it does |
|---|---|---|
| **Switch Orientation** | bottom-right | Toggle horizontal / vertical layout. |
| **Zoom In / Zoom Out** | bottom-right | Scale the canvas. |
| **Zoom-to-window** | legend bar | Fit the whole graph. |
| **Maximize / Normal** | legend bar | Toggles palette visibility / full-canvas mode. |
| **Auto-zoom** | — | One-click auto-fit on first interaction. |
| **Mesh run-status chip** | bottom-left | In Mesh mode, shows per-segment states while running. |
Empty canvas shows "No task found in flow. Drag and drop any task to get started."
## Toolbar reference (above the canvas)
| Control | What it does | Disabled when |
|---|---|---|
| **Enable** toggle | Turns the XFlow's **scheduled** run on/off. | While there are unsaved (dirty) changes. |
| **Auto Refresh** toggle | Live-refreshes the Runs tab (with a pulsing spinner). | Outside the Runs tab. |
| **Save** | Persists the graph + dialog settings. | Unless there are unsaved changes. |
| **Discard changes** (trash icon) | Reverts to the last saved version. | — |
| **Execute** (hover-menu) | **Quick Run** / **Document Run** / **Custom Run**. | — |
| **Header action-menu** | Publish · Edit · Duplicate · Pin / Unpin · Delete (permission-gated). | — |
> **Watch out — reserved names.** XFlows whose name starts and ends with `__` are system-reserved (e.g. the seeded ingestion spine). Non-super-admins don't see edit affordances on them. Don't name your own XFlows that way.
## Add / Edit XFlow dialog
Opened from **+ XFlow** or the action-menu's **Edit**.
| Field | Notes |
|---|---|
| **Name** (required) | Duplicate-name and reserved-`__` validation. |
| **Description** | Free text. |
| *Show Advanced Settings →* | |
| **Concurrency Limit** | Max simultaneous in-flight items. |
| **Execution Profile** (SizeClass) | Resource size class for the run. |
| **Repeat Every** | Value + unit — the schedule interval (works with the **Enable** toggle). |
| **Retries** / **Retry Delay (min)** | Auto-retry policy on failure. |
| **Trigger** (multi-select event types) | How the XFlow fires. Selecting **Entity Ingestion** (value 19) reveals an **Entity** multi-select; selecting a **Stage** trigger (value 2) reveals a **Stage** multi-select. |
| **On Failure Notification** toggle | Reveals an **Email** action (To / Subject / Message, with Placeholder menus). |
Save label: **Save XFlow** (or **Save Mesh** in Mesh mode).
## Execute dialog
The **Execute** menu picks the mode:
| Mode | Input | Use it for |
|---|---|---|
| **Quick Run** | none | Fire the whole pipeline immediately with no per-run input. |
| **Document Run** | `document_url` (or a `drive_url` via the embedded drive picker) | Run the pipeline against one specific document. |
| **Custom Run** | a free-text **Run Input** textarea (help code `AXF013`) | Pass arbitrary JSON/parameters for a one-off run. |
Execute → the run is queued → the XFlow Progress overlay streams live status (runId, AO base URL). In Mesh mode all three delegate to a `runMesh()` path.
## Runs tab — inspecting and debugging runs
**Filter bar:** **Tags** chip input · **Stage** multi-select · **Date Range** picker (Start/End time + quick radios Today / Yesterday / Week / Month / Custom "N units ago") · **Clear** / **Search**.
**Bulk-select toolbar** (appears on selection): **Retry · Pause · Resume · Cancel · Delete** chips. **Paginator:** 5 / 10 / 20 / 50.
**Run table columns:**
| Column | Notes |
|---|---|
| **Flow Name** | Plus copy run-id / copy document-id. |
| **Status** pill | completed / failed / running / paused / cancelled — each with an inline action icon by state (Retry / Resume / Cancel / Suspend / rerun). |
| **Start Time** | Sortable. |
| **Total Duration** | — |
**Row click → right sidenav (60% width):**
- Header chips: `parent_run_id`, `flow_run_id`, `deployment_id`.
- State badge + created time + duration + "N Task runs".
- Tab **Task Logs** — expandable per-task rows → timestamped, level-coded log lines (this is where you read which operator failed and why).
- Tab **Logs** — infinite-scroll raw log stream with date separators ("All logs loaded").
- Panel menu: Copy Parameters (super-admin) · Delete.
Empty → "No Runs Executed".
### Debugging a failed run — the loop
1. Open the **Runs** tab; the failed run shows a red **Status** pill.
2. Click the row → **Task Logs** in the sidenav; expand the task with the failure (it's the one that stopped the chain).
3. Read the level-coded lines for the error; cross-check the operator's config in the node dialog.
4. Fix the node config (or the upstream data), **Save**, then use the inline **Retry** icon on the run — or re-**Execute**.
> **Tip.** If a run sits at **queued** forever and never starts, the Prefect worker likely isn't running. Locally that means the stack's worker container is down (see the launch runbook).
## Mesh-mode runs (forward reference)
When the editor is in Mesh mode (palette + Save/Run + Runs repurposed to mesh artifacts), the Runs tab becomes a two-pane **Mesh run list** (status / run-id / doc / hops) plus a **Run trace** pane: a member timeline (dot states done / failed / running / awaiting service), per-member "Show output" / "View full logs", a **queue-health** banner (queued vs stalled), and a **Baton trail** of pub/sub hops (delivered / queued / failed, with expandable payloads + attempt counts).
---
## R5 · RBAC permission reference
URL: https://www.botminds.ai/academy/r5
> Botminds Academy — Reference
# RBAC permission reference
This reference enumerates every field of the **Add / Edit Role** dialog — the RBAC grant that decides what a user can see, what they can do, and which lifecycle stages they may act on. The model itself is taught in [Access & roles](/academy/g1); open this page when you need to build a role precisely.
## The mental model: a role is a bundle of grants
When you open **+ Role**, you are filling in one object made of two layers of security:
- **Feature-level security** — which Studio pages and capability *actions* the role can use. These drive the permission gates that hide buttons and fields all over Studio and the runtime. (Stored as `AllowedStudioPages` + `AllowedActionIds`.)
- **Row / label-level security** — which *documents* and *labels* the role can even see or train on. (Stored via the **Label Content Filter** and **Label selection** / `LearnerMeta`.)
A role also carries **scope**: the **Entity** (collection) it applies to and the **Stages** it works in. Stage scope is the bridge to the lifecycle — see "How roles gate lifecycle stages" below.
> **Tip.** Every individual action in the dialog has its own inline help "i" bubble keyed `RAR` (for the action list) or an `SR0xx` code (for the field). Hover them in the product for the canonical one-liner.
## Basic fields (always visible)
| Field | Control | Required | What it does | Help |
|---|---|---|---|---|
| **Role Name** | text | yes | The role's display name (e.g. `L1-Reviewer`). Appears on stage gates, user assignments, and View "Allowed roles" chips. | `SR001` |
| **Entity** | multi-select of the project's collections | yes | Scopes the role to one or more **collections**. Changing it **re-filters the Stage list** — you can only pick stages that belong to the chosen entities. | `SR0015` |
| **Stage** | searchable multi-select | — | The lifecycle **stages** this role may work in. Options are grouped and labelled ` > `; there is an in-dropdown search box. Gated by `['security','Stage','Add Role']`. | — |
| **Users in Access Roles** | user multi-select | — | Assigns project users to this role (you can also assign users from the **Users** surface). Gated by `['security','Users in Access Roles','Access Roles']`. | `SR002` |
## Advanced fields (behind "Show Advanced Settings")
Click **Show Advanced Settings** to reveal the capability and filter grants. This is where most of the RBAC power lives.
| Field | Control | What it does | Stored as | Help |
|---|---|---|---|---|
| **Select action(s) for this role** | multi-select of the platform's capability actions | **The core capability grant.** Each entry is one thing the role may do (the per-item bubble is `RAR`). This is what most permission checks resolve against. | `AllowedActionIds` | `SR003` |
| **Label selection** | learner → label picker | Restricts which **labels** (fields) the role may **train** on. Edit/delete chips once set. Gated `['security','Label Content Filter','Add Role']`. | `LearnerMeta` | — |
| **Label Content Filter** | label picker **with a required value** | **Row-level data filtering.** Restricts the documents the role can see to those whose label *equals a value* (e.g. only documents where `region = EMEA`). Requires a value to take effect. Same gate as Label selection. | (label filter) | — |
| **Training Icons** | multi-select | Which annotation / training tools the role sees in the document viewer. When the full set is selected it is stored as `[]` meaning **"all"**. | (training actions) | `SR005` |
| **Allowed Document Actions** | multi-select | Per-document operations the role may perform (the document-level action buttons). | (document actions) | `SR006` |
| **Allowed Studio Pages** | multi-select | Which **Studio sections** the role may open. The choices are: **Project, Data Model, Connector, Automation, Search, Chat, Intelligence, AI Builder, Agent Builder, Asset Builder, Data Lake, Security**. This is page-level gating — a role with no Studio pages is a runtime-only (consumer) role. | `AllowedStudioPages` | `SR007` |
| **Allowed Summary Pane Actions** | multi-select | Summary-pane operations: **Lookup Update**, **Re-Group Summary**. | (summary actions) | `SR008` |
*Footer:* **Create / Update** button (gated `['security','Create','Add Role']`), disabled while the form is invalid; shows a spinner while saving. **View mode** (opening a role read-only) shows a flat table of Role Name, Actions, and Users — no editing.
> **Under the hood.** Saving a role writes back into the shared role signal, so Studio **re-gates immediately** — buttons appear and disappear without a reload. Two quirks worth remembering: Training Icons equal to the full set are stored as `[]` ("all"), and the Entity choice is what filters the Stage options.
## How roles gate lifecycle stages
This is the link to the review flows described in [Human-in-the-loop](/academy/g2). A lifecycle **stage** has a **Can be viewed by** setting (`ViewedByRoleIds`). Whatever roles you list there are the only roles that can **see and act on** documents sitting in that stage (empty = every role). The connection runs both ways:
- On the **stage** (Data Model ▸ Lifecycle ▸ edit a stage): you pick roles in **Can be viewed by** — this writes `ViewedByRoleIds`.
- On the **role** (here): the **Stage** field records which stages the role is meant to work in.
So to make a stage L1-only:
1. Create an **L1-Reviewer** role here (Entity = your collection; give it the review actions and document actions L1 needs).
2. Go to the stage's **Can be viewed by** and add **L1-Reviewer**.
The seeded **Four-Eyes** flow already ships this pattern: **L1 Review** is gated to `L1-Reviewer` (+ `L2-Approver` + `Admin`), and **L2 Approval** — the final human gate — is gated to `L2-Approver` (+ `Admin`). That is the L1-Reviewer / L2-Approver pattern: two distinct roles, two distinct gated stages, "four eyes" before a document is approved.
> **Watch out.** Deleting a role warns *"Users and workflow stages mapped to this role (if any), will no longer exist…"* — removing a role also breaks any stage gate that referenced it, which can silently make a stage visible to everyone (empty `ViewedByRoleIds` = all). Re-check your stage gates after deleting a role.
## Quick recipes
| You want… | Set this |
|---|---|
| A consumer-only reviewer (no Studio access) | Leave **Allowed Studio Pages** empty; grant the review **actions** + **Allowed Document Actions**; assign the **Stage**. |
| A builder who can edit the data model but not security | **Allowed Studio Pages** = Data Model, Project (omit **Security**). |
| Restrict a team to one region's documents | **Label Content Filter** = `region` with value `EMEA`. |
| Let a role train only certain fields | **Label selection** = just those labels. |
| The final approver gate | A role gated onto the **L2 Approval** stage's **Can be viewed by**. |
---
## S1 · What is Botminds
URL: https://www.botminds.ai/academy/s1
> Botminds Academy — Start Here
# What is Botminds
> **In one line.** Botminds is the platform where you hire AI agents and put them to work on your documents, your data, and your decisions — governed, auditable, and built without writing code.
## The problem we exist for
Most enterprise work is not in databases. It arrives as documents, emails, filings, contracts, claims, applications — unstructured, high-volume, and consequential. For fifty years, software automated the structured 20% and left people to be the integration layer for the rest: reading, extracting, checking, deciding, routing, explaining.
Large language models changed what machines can read and reason about. But a model is not a system. It has no memory of your documents, no rules it must obey, no queue of work, no audit trail, and no way for your team to supervise it. A chat window does not run an operation.
Botminds closes that gap. It is the layer between raw AI capability and real operational work: the place where agents get their knowledge, their assignments, their rules, and their supervisors.
## How it works — two heroes
Everything on the platform reduces to two ideas:
- An **Agent** is a configured AI worker. You do not program it — you describe it: what role it plays, which model it thinks with, what knowledge it may read, which tools it may use, and which rules it must obey. Then you test it live in a playground before it touches real work.
- A **Collection** is a typed home for records — the documents an agent processes, the knowledge it consults, the rows it produces. Collections carry the schema, the lifecycle, and the history of every record.
Hire an expert agent. Give it a collection of work. Watch it think. Every solution on the platform — from a one-hour Q&A assistant to a full origination platform — is those two ideas, composed.
## The three shapes of a solution
| Level | Shape | You get |
|---|---|---|
| 1 | [**Agentic Search**](/academy/sol-search) | Cited, conversational answers over your content. Ask; get an answer with sources you can click. |
| 2 | [**Agentic Workflow**](/academy/sol-wf) | A process that runs itself: documents in, decisions out, humans approving only the edge cases. |
| 3 | [**Agentic System**](/academy/sol-sys) | A domain brain: many collections, a fleet of agents, governance, compliance and reporting operating as one. |
This is a ladder, not a menu. Teams start at level 1 in an afternoon, ship a level 2 workflow in weeks, and grow into level 3 as trust and coverage build — on the same platform, with the same skills.
## The four pillars you build with
| Pillar | What it gives you |
|---|---|
| [**Agents**](/academy/a1) | The workforce: models, instructions, tools, skills, MCP integrations, guard rails, pipelines, multi-agent teams, evaluation. |
| [**Data**](/academy/d1) | The ground truth: collections with schema, taxonomy, lifecycle stages, connectors that ingest from wherever your content lives. |
| [**Experience**](/academy/e1) | The product your users touch: document workspace, cited chat, dashboards, inbox, purpose-built pages — branded as yours. |
| [**Governance**](/academy/g1) | The reason you can run this in production: roles and access, human-in-the-loop review, four-eyes approval, guard rails, audit. |
## What makes Botminds different
**Evidence first.** Answers cite their sources; extracted values link back to the exact page and span they came from. You never have to take an agent's word for it.
**Humans stay in command.** Confidence thresholds route uncertain work to review queues. Four-eyes approval gates the decisions that matter. The agent does the volume; your team does the judgment.
**No-code, end to end.** The person who understands the process — an operations lead, an analyst, a domain expert — builds the solution. Describe the agent, shape the collection, wire the lifecycle, publish the experience. Days, not quarters.
**One platform, not ten tools.** Ingestion, extraction, search, workflow, review, dashboards, access control and audit are one system that already knows how to work together — not an integration project.
**Open at the edges.** A [Runtime API](/academy/v1) for your systems to trigger jobs and read results, [MCP](/academy/v2) so other AI tools can drive the platform, and [Hubs](/academy/v4) to package and ship what you build.
## Where to go next
- Build something now: [Your first 30 minutes](/academy/s3).
- Get the concepts straight: [Core concepts — the two heroes](/academy/s2).
- See a full worked build: [Invoice settlement](/academy/uc-invoice).
---
## S2 · Core concepts — the two heroes
URL: https://www.botminds.ai/academy/s2
> Botminds Academy — Start Here
# Core concepts — the two heroes
> **In one line.** An Agent does the work; a Collection holds the work. Everything else on the platform exists to configure, connect, supervise, or display those two.
> **You'll be able to.** Read any screen in Studio and know which of the four pillars you are looking at — and why it exists.
## Agent — the worker
An agent is a configured AI worker. Its definition is a handful of decisions, each one a tab in the agent editor:
| Decision | Tab | What it means |
|---|---|---|
| Who is it? | **Persona** | Plain-language instructions: role, task, output expectations. You describe the worker; you don't program it. |
| What does it think with? | **Model** | An LLM you registered, or **Auto** to let the platform route. |
| What may it read? | **Knowledge** | The collections attached as its grounding. This attachment is the access boundary — an agent cannot see what you don't attach. |
| What can it do? | **Capabilities** | Tools, skills, and MCP servers. Every capability widens what the agent can act on — grant them deliberately. |
| What must it obey? | **Guard rails** | The rules and refusals layered onto every run. |
You build one in [A3 · Your first agent](/academy/a3), test it in a live playground, and only then point it at real work. Agents come in varieties — answering, extracting, deciding, generating — covered in [A4](/academy/a4), and they compose into [pipelines](/academy/a10) and [teams](/academy/a11) when one worker isn't enough.
## Collection — the work
A collection is a typed home for records. The type decides its behavior:
- **Processing** collections hold work in flight — each document moves through a lifecycle toward a decision.
- **Knowledge** collections hold reference content — documents become readable knowledge the moment they land; there is no lifecycle. This is the grounding for Agentic Search.
- **Structured** collections hold rows — records with fields rather than pages.
Three things live on a collection and do most of the platform's heavy lifting:
1. **Schema** — the fields you want out of every record (`vendor`, `amount`, `due_date`…). The schema is what agents extract into, what tables display, and what dashboards count. On this platform, the label set *is* the schema.
2. **Taxonomy & tags** — how records are classified and sliced.
3. **Lifecycle** — the stages a record moves through (`New → Extracted → In review → Settled`) and the automations that move it. Confidence gates live here: high-confidence work skips ahead; uncertain work routes to humans.
Details in [D1 · Collections & schema](/academy/d1) and [D3 · Taxonomy, lifecycle, tags & events](/academy/d3).
## The two surfaces
The platform has two faces, and knowing which one you're on orients you instantly:
- **Studio** is where builders work: collections, agents, pipelines, experiences, governance. If you can configure it, it's in Studio.
- **The consumer surface** is what your users get: the document workspace, cited chat, dashboards, the inbox. They never see Studio, and they never need to.
## The four pillars, one sentence each
- [**Agents**](/academy/a1) — hire and equip the workforce.
- [**Data**](/academy/d1) — shape the collections the workforce reads and fills.
- [**Experience**](/academy/e1) — decide what your users see and touch.
- [**Governance**](/academy/g1) — decide who can do what, and prove what happened.
## One concrete run, end to end
An invoice PDF lands in a Processing collection (ingestion — **Data**). The extraction agent reads it, fills the schema fields, and reports 0.97 confidence (**Agents**). The lifecycle automation sees the confidence and the matched PO and moves it straight to `Settled`; a low-confidence sibling routes to the review queue instead, where a person corrects one field and approves (**Governance**). The finance team watches both land in the workspace and the settled-per-week dashboard tick up (**Experience**).
That loop — ingest, think, gate, show — is the platform. Every chapter from here is a deeper look at one part of it.
## Where to go next
Build the loop yourself in [S3 · Your first 30 minutes](/academy/s3), or go straight to the pillar you need in the sidebar.
---
## S3 · Your first 30 minutes
URL: https://www.botminds.ai/academy/s3
> Botminds Academy — Start Here
# Your first 30 minutes
> **In one line.** One guided sit-down: build a small but real Agentic Search assistant over three documents, and meet every core idea on the way.
> **You'll need.** A project you can build in, and three PDFs you know well — policy documents, product guides, anything your colleagues ask questions about.
Don't read this chapter. Do it. Every concept you meet here — collection, agent, knowledge attachment, playground — carries the rest of the academy.
## Minutes 0–5 · Look around
Sign in and you land on the **Command Deck** — the cross-workspace home (press **Ctrl K** to jump anywhere). Open your project from **Jump back in** or **Browse everything**, and you're on the consumer surface: the workspace, chat, dashboards. This is what your users will get. Now find **Studio** in the navigation — Studio is where builders work, and your users will never see it. Take the two-minute tour in [E1 · Getting oriented](/academy/e1) if you want names for what you're seeing, then come back.
## Minutes 5–10 · Create a Knowledge collection
`Studio ▸ Data Model ▸ Collections ▸ + Collection`
1. Name it something honest — `HR Policies`, `Product Guides`.
2. Set **Category = Knowledge**. This single choice is what makes it a Search collection: documents become readable knowledge the moment they land. No lifecycle, no stages.
3. Upload your three PDFs.
While they process, understand what you just did: you gave your future agent its ground truth. An agent can only answer from what you attach — that boundary is a feature, not a limitation.
## Minutes 10–20 · Hire your first agent
`Studio ▸ Agent Builder ▸ Agents ▸ + Agent`
1. **Persona** — describe the worker in plain language:
*"You answer employee questions about our policies. Answer only from the attached documents, and always cite your sources. If the documents don't contain the answer, say so."*
2. **Model** — pick a registered LLM, or leave **Auto**.
3. **Knowledge** — attach `HR Policies`. This is the load-bearing wire of the whole build: it is what turns a generic chatbot into *your* expert.
Save. That's a hire.
## Minutes 20–25 · Ask it things
Open the agent's **Playground** and ask real questions — the ones people actually bring to your team. Watch what comes back: grounded answers with citations you can click through to the exact source passage.
Ask something the documents *don't* cover. A well-instructed agent says it doesn't know instead of inventing — if yours doesn't, tighten the persona line about refusing and try again. This test-refine loop in the playground is how every agent on the platform gets good.
## Minutes 25–30 · Give it to someone
Your users don't open Studio — they open **Chat**. Publish the experience and send the link to one colleague with the message "ask it anything about our policies." Watch what they ask. Their third question is usually the moment this stops being a demo.
## What you just built
**Agentic Search — solution shape 1 of 3.** A Knowledge collection, one agent, one attachment, one shared experience. The other two shapes are the same two heroes doing bigger jobs:
- Add a schema, a lifecycle, and a review queue and the agent stops answering questions and starts *processing work* — that's an [Agentic Workflow](/academy/sol-wf).
- Add more collections, more agents, and governance across all of it — that's an [Agentic System](/academy/sol-sys).
## Where to go next
- Make this build production-worthy: [the Search pattern](/academy/sol-search), then the full worked build in [B1 · Policy assistant](/academy/uc-policy).
- Meet the agent editor properly: [A3 · Your first agent](/academy/a3).
---
## ▸ · The Search pattern
URL: https://www.botminds.ai/academy/sol-search
> Botminds Academy — Solutions · Agentic Search
# The Agentic Search pattern
> **In one line.** Conversational, cited answers over your enterprise documents and data — a Knowledge collection plus an agent that reads it.
> **You'll be able to.** Recognize when Search is the right shape, build one in four steps, and tune it from demo to dependable.
## What it is
Agentic Search is level 1 of the solution ladder: the fastest way to turn a pile of documents into an expert your whole team can ask. Users type questions in plain language; the agent answers from — and only from — the content you attached, with citations that click through to the exact source passage.
Choose this shape when the sentence in your head is *"let people ask questions over our content."* If the sentence is *"automate this process,"* you want a [Workflow](/academy/sol-wf).
## The pattern, in four steps
```
1. KNOWLEDGE collection → 2. ADD documents → 3. AGENT → 4. ATTACH collection
(no lifecycle; (upload or (persona + (Knowledge tab —
readable on landing) connector) model) the load-bearing wire)
```
1. **Create a Knowledge collection** — `Studio ▸ Data Model ▸ Collections ▸ + Collection`, set **Category = Knowledge**. That category choice is the fork in the road: Knowledge means no lifecycle — documents become readable knowledge the moment they land.
2. **Add documents** — upload directly or wire a [connector](/academy/d4) so the collection stays current on its own.
3. **Build the agent** — `Studio ▸ Agent Builder ▸ Agents ▸ + Agent`. The persona sets the contract: answer from the attached documents, cite always, refuse when the answer isn't there.
4. **Attach the collection** on the agent's **Knowledge** tab. This attachment is both the power (grounded, cited answers) and the boundary (the agent cannot see anything you didn't attach).
Step-by-step with every screen: [B1 · Policy assistant](/academy/uc-policy).
> The Knowledge-collection category is a shipped release feature (`knowledgeCollections`, default on). If an environment has it switched off as a kill-switch you won't see the Knowledge toggle.
## Tuning it from demo to dependable
| You want | Do this | Where |
|---|---|---|
| Trustworthy answers | Keep citations on; make the persona refuse out-of-scope questions | Agent **Persona** |
| No leakage | Attach only the collections this audience may see; build separate agents for separate audiences | Agent **Knowledge** tab |
| Structured questions ("how many policies mention X?") | Add a Knowledge schema so facts also land in a [Datasheet](/academy/d5); the agent answers those with a SQL tool | Collection schema + [Tools](/academy/a5) |
| A guided start for users | Configure suggested questions in the chat experience | [Chat & search](/academy/e4) |
The distinction worth remembering: reading questions ("what does the policy say?") are answered from passages; counting questions ("how many contracts expire in Q3?") are answered by SQL over a Datasheet. A great assistant does both.
## Worked builds
| Build | What it adds |
|---|---|
| [B1 · Policy assistant](/academy/uc-policy) | The whole pattern, smallest form — the build from [your first 30 minutes](/academy/s3), production-grade |
| [B2 · Enterprise data Q&A](/academy/uc-eqa) | Multiple collections, Knowledge schema, structured + narrative answers together |
## Where to go next
- Ready for a process, not just questions: [the Workflow pattern](/academy/sol-wf).
- The controls behind step 3: [A3 · Your first agent](/academy/a3).
- What "Knowledge" does under the hood: [D2 · Collection types](/academy/d2).
---
## ▸ · The System pattern
URL: https://www.botminds.ai/academy/sol-sys
> Botminds Academy — Solutions · Agentic System
# The Agentic System pattern
> **In one line.** A governed domain brain: many collections and a fleet of agents powering a whole portfolio of use cases — with governance, compliance, recommendation and reporting operating over all of it at once.
> **You'll be able to.** Recognize when you've outgrown single workflows, and stand a System up in the right order: domain model first, fleet second, workflows third, facets last.
## What it is
An Agentic System is level 3 of the ladder. A [Workflow](/academy/sol-wf) automates one process; a System runs a *domain* — loan origination, compliance operations, a lending portfolio — where many processes share the same data, the same rules, and the same accountability.
Choose this shape when the workflows start overlapping: three processes reading the same collections, the same field meaning different things in different builds, auditors asking questions no single dashboard answers. Those are the signs you need one brain, not more arms.
## The canonical architecture
A System is a layered stack. Read it bottom-up — that is also the build order:
```
L5 OUTPUT & DELIVERY decision package + provenance, findings ┐
L4 HITL confidence gate; exceptions to a human │ cross-cutting facets
L3 VALIDATION & RULES within/cross-doc checks, screening, flags │ watch every layer:
L2 AI INTELLIGENCE classify, extract, transform, confidence │ governance, compliance,
L1 INTAKE collection ingestion fires the pipeline │ recommendation, reporting
L0 PREPROCESSING ids, hashing, PII pre-screen, page split ┘
──────────────────────────────────────────────────────────────────
THE SHARED DOMAIN MODEL — many collections + one taxonomy.
Every agent reads it; every workflow writes to it; every facet reports on it.
Worked by a FLEET of agents + shared skills.
```
1. **The shared domain model first.** The collections and the taxonomy — the field dictionary every agent and rule speaks. One model, reused everywhere. Get this wrong and every layer above inherits the mistake. ([D1](/academy/d1), [D3](/academy/d3))
2. **A fleet, not a hero.** Not one agent but many, each expert on a slice — a classifier, an income analyzer, a screener — sharing [skills](/academy/a6) so common logic lives once. The reference lending build runs 50 agents and 18 shared skills.
3. **Workflows on top.** Each layer's process is a level-2 workflow — a [mesh or XFlow](/academy/a10) moving work L0 through L5. Everything you learned in [the Workflow pattern](/academy/sol-wf) applies per layer.
4. **Facets over everything.** Governance, compliance, recommendation, reporting.
The idea that makes Systems tractable: **a facet is not a separate app — it is a lens over the same domain model.** Compliance is the validation rules, the screening agents and the audit trail, taken together. Reporting is dashboards over the telemetry those same agents emit. You build one domain model and turn on four lenses; you do not build four systems.
## The facets
| Facet | What it is | Built from |
|---|---|---|
| **Governance** | Who may touch what, versioned and auditable | [Access & roles](/academy/g1), versioning |
| **Compliance** | Rules, screening, and an immutable record | [Policy & guard rails](/academy/g3), [Audit](/academy/g5) |
| **Recommendation** | Agents that score and decide, with provenance | Decision agents ([A4](/academy/a4)) |
| **Reporting** | Dashboards and cost telemetry over everything | [Dashboards & inbox](/academy/e5) |
## Standing one up without drowning
Do not build all six layers on day one. The incremental path that works:
1. Ship **one** workflow end to end on the shared domain model (weeks, not months).
2. Add the second workflow *on the same collections* — resist the copy-paste fork; this is the step where the domain model earns its keep.
3. Turn on the facets one at a time, compliance first if regulators are in the room.
4. Package and version the whole thing when it stabilizes ([B10 · Package & ship](/academy/uc-ship)).
## Worked builds
| Build | Teaches |
|---|---|
| [B8 · Compliance evidence map](/academy/uc-compliance) | The compliance facet standing alone — rules to evidence to audit |
| [B9 · Capstone: Lending domain brain](/academy/uc-lending) | The full stack: domain model, fleet, layered workflows, all four facets |
## Where to go next
- See the smallest facet in action: [B8 · Compliance evidence map](/academy/uc-compliance).
- The domain model's foundations: [D1 · Collections & schema](/academy/d1) and [D3 · Taxonomy & lifecycle](/academy/d3).
- Ship it to another workspace: [V4 · Hubs & distribution](/academy/v4).
---
## ▸ · The Workflow pattern
URL: https://www.botminds.ai/academy/sol-wf
> Botminds Academy — Solutions · Agentic Workflow
# The Agentic Workflow pattern
> **In one line.** A multi-step automation that processes work and decides — documents in, decisions out, humans approving only the edge cases.
> **You'll be able to.** Recognize workflow-shaped problems, assemble the seven-part processing loop, and choose the right engine for the middle of it.
## What it is
An Agentic Workflow is level 2 of the ladder. Where [Search](/academy/sol-search) answers questions, a Workflow *does the work*: it takes each incoming document through extraction, validation and decision, routes the uncertain minority to people, and shows everyone the state of everything.
Choose this shape when the sentence in your head is *"we process these every day and it's manual"* — invoices, claims, contracts, applications, tickets — and there is a decision at the end: settle, escalate, approve, route.
## The processing loop
Same spine as Search (collection → ingest → agent), plus a lifecycle, a human, and an operations surface:
```
1. PROCESSING collection (+ lifecycle)
2. SCHEMA — the fields to fill
3. INGESTION — upload or connector
4. ENGINE — agent / team / xflow / mesh, assigned as the collection's processor
│ each document walks the lifecycle
├── 5. HITL INBOX — exceptions; a human decides
├── 6. OUTPUT / EXPORT — views, datasheet, export template
└── 7. EXPERIENCE — lists, inbox, dashboards for the operators
```
The build order matters less than the design order: **schema and lifecycle first.** They are the contract everything else fills.
1. **Processing collection** — `Studio ▸ Data Model ▸ Collections ▸ + Collection`, category Processing. ([D1](/academy/d1))
2. **Schema** — the fields a settled record must have: `vendor`, `amount`, `po_match`… ([D1](/academy/d1))
3. **Lifecycle** — the stages a document moves through, and the automations that move it: `New → Extracted → In review → Settled`. Confidence gates live here — this is where "humans only see the edge cases" is actually wired. ([D3](/academy/d3))
4. **Engine** — build the worker and assign it as the collection's intake/processor. One agent for simple extraction; a [team or mesh](/academy/a11) when steps deserve their own specialists; an [XFlow](/academy/a10) when you need scheduled or branching pipelines.
5. **Human-in-the-loop** — route low-confidence or flagged documents to the [Inbox](/academy/g2); reviewers correct, approve, and their corrections become feedback.
6. **Output** — views and [Datasheet](/academy/d5) for downstream consumption, export templates for other systems.
7. **Experience** — the workspace is live from day one; add [dashboards](/academy/e5) for throughput, exceptions and aging.
## Choosing the engine
| Engine | Use when | Chapter |
|---|---|---|
| Single **agent** | One coherent job — extract and flag | [A3](/academy/a3) |
| **Team / mesh** | Distinct steps deserve distinct specialists: classify → validate → enrich → approve → summarize, each lighting up live | [A11](/academy/a11) |
| **XFlow** | Scheduled runs, fan-out, branching, cross-collection pipelines | [A10](/academy/a10) |
The platform's reference example is the invoice settlement mesh: five decoupled members hand a baton down a durable bus, and the document's Summary pane fills with the settled fields as each lane goes green. Loan underwriting, claims adjudication and contract review are the same shape wearing different schemas.
## Worked builds, easiest first
| Build | Teaches |
|---|---|
| [B3 · Invoice settlement](/academy/uc-invoice) | The whole loop, smallest form — do this one first |
| [B4 · Support intake triage](/academy/uc-triage) | Routing, tags, inbox discipline |
| [B5 · Contract review](/academy/uc-contract) | Clause extraction, four-eyes review |
| [B6 · SEC filings analyst](/academy/uc-sec) | Scheduled XFlow pipelines over a public feed |
| [B7 · Loan underwriting](/academy/uc-underwriting) | Mesh engine, multi-collection, straight-through-processing gate |
Do B3 even if your real target is B7. Every workflow is the same skeleton wearing different clothes, and the skeleton is easiest to see on the small one.
## Where to go next
- Start building: [B3 · Invoice settlement](/academy/uc-invoice).
- The gates that keep humans in command: [G2 · Human-in-the-loop](/academy/g2).
- Outgrowing one workflow: [the System pattern](/academy/sol-sys).
---
## B8 · Build: Compliance evidence map
URL: https://www.botminds.ai/academy/uc-compliance
> Botminds Academy — Solutions · Agentic System
# Build: Compliance evidence map
> **In one line.** Turn a pile of SOC 2 evidence into control-tagged, human-confirmed records — with a live coverage picture and an immutable trail that answers the two questions every auditor asks.
> **You'll build.** A Processing collection with a control taxonomy, a **Control Mapper** agent that assigns control IDs with a confidence, a lifecycle that auto-accepts confident mappings and routes the doubtful ones to a reviewer, a read-only auditor seat, and a coverage dashboard.
> **You'll use.** [Collections & schema](/academy/d1) · [Taxonomy, lifecycle, tags & events](/academy/d3) · [Your first agent](/academy/a3) · [Access & roles](/academy/g1) · [Shaping the experience](/academy/e7)
The setup: your team is preparing for a SOC 2 audit. You have evidence — access-review exports, on-call rotas, change-management tickets, a pen-test report, screenshots of MFA settings — and a long list of controls each piece is supposed to satisfy (`CC6.1`, `CC7.2`, and so on). Today that mapping lives in a spreadsheet nobody trusts: you can't easily answer *"which controls have no evidence?"* or *"who confirmed this artefact maps to CC6.1?"* The auditor will ask both.
This is a **classify-route-report** build: a taxonomy names the controls, an agent maps each artefact to control IDs with a confidence, a lifecycle auto-accepts the confident mappings and routes the rest to a human, roles gate that review and give the auditor read-only access, and a dashboard shows coverage. Plan for 75–90 minutes for the core build. You need a project to build in, at least one LLM registered ([LLMs & services](/academy/a2)), and a handful of sample evidence files (PDF/PNG/DOCX) to upload.
> **One honest caveat up front.** This is a **Processing** collection (decide on each artefact), *not* a Knowledge collection. The platform's job here is to classify and route each piece of evidence and record an auditable decision — exactly what Processing collections and the Four-Eyes lifecycle are built for. If you *also* want auditors to chat with the evidence ("show me our access-review evidence"), that is a second, Knowledge collection — a different build.
## Steps
### Stage 1 — Create the "SOC2 Evidence Q4" Processing collection
Where: `Studio ▸ Data Model ▸ Collections` ([Collections & schema](/academy/d1)).
1. Click **+ Collection**.
2. **Purpose:** leave/select **Processing**. Evidence gets *decided on* per artefact — it moves through review stages.
3. **Collection Name:** `SOC2 Evidence Q4`.
4. **Description:** `Evidence artefacts mapped to SOC 2 controls for the Q4 audit`.
5. Leave the rest at defaults. Click **Save**.
> **Watch out — Category is permanent.** You pick **Processing** vs **Knowledge** once, at create time; afterwards it's a read-only chip. We want Processing here — don't switch it.
**Checkpoint.** `SOC2 Evidence Q4` appears in the left rail, and selecting it shows the seven-tab workbench (**General · Schema · Lifecycle · Tags · Events · Ingestion · Agents**). Because it's a Processing collection, it was seeded with the 8-stage Four-Eyes lifecycle automatically — you'll reshape that in Stage 5.
### Stage 2 — Define the control taxonomy (the schema)
This is the heart of the build: the schema drives extraction, so the fields you author here are exactly what the agent will fill. Where: select the collection, then the **Schema** tab.
First, create the Learner:
1. On the **Schema** tab, click **Taxonomy** (footer) to open **Create Taxonomy**.
2. **Taxonomy Name:** `Control Mapping`. **Description:** `Maps an evidence artefact to SOC 2 controls`.
3. **Type:** `DocumentClassification` — you're classifying a whole artefact, not pulling a table.
4. **Entity:** `SOC2 Evidence Q4` (pre-filled). **Submit**.
Then add the fields. Select **Control Mapping**, click **+ Label**, and add these five (use **Add** between them, **Add and exit** on the last). The **Description** is what the agent reads to know what to put there — write each one as an instruction to the agent:
| Field (Label) | Shape | Description to type |
|---|---|---|
| `control_family` | **Single-select** — open **View Config ▸ Validation** and list the families: `Security`, `Availability`, `Confidentiality`, `Processing Integrity`, `Privacy` | `The SOC 2 trust-services family this evidence supports` |
| `control_id` | **Text** (default) | `The specific control ID this artefact satisfies, e.g. CC6.1, CC7.2. List all that apply, comma-separated.` |
| `evidence_type` | **Single-select** — Validation listing `Policy`, `Screenshot`, `System Export`, `Report`, `Ticket`, `Log` | `What kind of artefact this is` |
| `coverage_status` | **Single-select** — Validation listing `mapped`, `partial`, `missing` | `mapped = clearly satisfies the control; partial = related but incomplete; missing = no control match found` |
| `mapping_rationale` | **Text** | `One sentence: why this artefact maps to that control. Quote the part of the document that proves it.` |
> **Tip — keep the family list flat.** A short single-select (`control_family`) is what the routing in Stage 5 and the per-family dashboard in Stage 6 both read. Five clean values beat a free-text field here.
**Checkpoint.** The **Labels** tree under **Control Mapping** shows all five fields. The collection now knows what to pull out of every artefact.
### Stage 3 — Bring the evidence in
Where: the collection's **Ingestion** tab, or `Studio ▸ Connector ▸ Ingestion` ([Ingestion & connectors](/academy/d4)). For a one-time audit pack, the fastest path is a direct upload:
1. Open the **Ingestion** tab on `SOC2 Evidence Q4` (or the **Upload** toolbar button on `Studio ▸ Connector ▸ Ingestion`).
2. **Upload** your evidence files — drop in 5–10 to start: a couple of access-review exports, an MFA screenshot, a change ticket, the pen-test report.
3. Each artefact appears in the collection's document list immediately with a **"Processing…"** chip, then fills in.
> **Under the hood.** On upload the backend creates the document row at once, stores the bytes, and hands off to the orchestrator to run the collection's ingestion and extraction — you watch the chip climb to 100% live. For a recurring pull from, say, a SharePoint "Evidence" library, build a **Connector** once and a scheduled **Job** instead ([Ingestion & connectors](/academy/d4)).
**Checkpoint.** Your artefacts are listed in `SOC2 Evidence Q4`. They have no control mappings yet — that's the agent's job, next.
### Stage 4 — Build the "Control Mapper" agent
Where: `Studio ▸ Agent Builder ▸ Agents` → **+ Agent ▸ Agent** ([Your first agent](/academy/a3)).
1. **Persona tab.**
- **Name:** `Control Mapper`
- **Description:** `Maps each evidence artefact to the SOC 2 controls it satisfies, with a confidence.`
- **Instructions:** click the **co-pilot**, seed it with *"Read a piece of audit evidence and decide which SOC 2 controls it satisfies,"* then refine to roughly:
> You are a SOC 2 compliance analyst. For each evidence artefact, identify which SOC 2 control(s) it satisfies and return the control family, the specific control ID(s), the evidence type, a coverage status, and a one-sentence rationale quoting the document. If the artefact clearly satisfies a control, set `coverage_status` to `mapped`. If it is related but incomplete, use `partial`. If you cannot tie it to any control, use `missing` and leave `control_id` blank. Never invent a control ID; only use IDs the evidence genuinely supports.
2. **Model tab.** Pick your project's **LLM Model**. Set **Agent Mode = Thinking** while you build (so you can watch its reasoning), then flip to **Fast** for production. Leave Advanced sampling at defaults — extraction wants a low temperature.
3. **Output tab.** This is what turns chatter into data. Turn on **Structured output**, then:
- Pick the **Taxonomy/Learner** `Control Mapping` (the schema from Stage 2).
- **Process unit = Page** (most artefacts are short; sectioned reports can use Section).
- Confirm the five **Labels** appear; tighten any **Description** if needed.
- Turn on **Confidence Score** and **References**. The per-field confidence is what routes a mapping to human review in Stage 5; References give the reviewer — and the auditor — the source citation.
4. **Save Agent.**
5. **Test in the playground** (right pane). Set **Input Type = Document**, pick one uploaded artefact, press **Enter**. Watch it stream the **Thinking** block, then the filled fields (`control_family`, `control_id`, `coverage_status`…), each with a confidence and a reference to the page. Wrong mapping? Sharpen a field **Description** and re-run. Once a few come out clean, flip **Agent Mode = Fast**.
**Checkpoint.** In the playground, the agent reads an artefact and returns `CC6.1` (or similar) with a confidence and a quoted rationale. It isn't wired to the collection yet — that's Stage 5.
### Stage 5 — The gap-review lifecycle: auto-accept vs route to a reviewer
Now make the decision auditable. Two parts: shape the stages so confident mappings auto-accept and shaky ones go to a human, then assign the agent so every new artefact runs through it. Where: the collection's **Lifecycle** tab ([Taxonomy, lifecycle, tags & events](/academy/d3)).
Your Processing collection already has the Four-Eyes flow. For evidence mapping you want a leaner shape — one human gate, not two — so edit the stages:
1. Keep **Intake → AI Processing → AI Recommendation** as-is: intake, the agent runs, then the branch.
2. Rename **L1 Review** to **`Compliance Review`** — confirm **Send to Inbox (human review)** is **on** (this is what makes it a review stage). This is where uncertain mappings land.
3. Set the terminal stages to read **`Mapped`** (the approve/End stage) and **`Gap`** (the reject/End stage — no good evidence found). Use the stage editor's **Final Name** for the display label.
4. You can delete **L2 Approval** for this lighter flow — one reviewer is enough for evidence triage — or keep it if your audit demands four eyes. Remember the validation rule: exactly one **Start**, one **End**, no dangling stages.
> **Watch out — don't Reset to default.** The **Reset to default** action rebuilds Four-Eyes and is gated behind a confirm-by-EntityId prompt. Edit the stages in place; don't reset a lifecycle that has live documents.
Next, turn on Auto-Decide for confident mappings. Below the stage graph, the **Auto-Decide policy** card lets the platform accept clean mappings without sending them to a human:
1. **Enabled = true**.
2. **Min Confidence = 0.90** — high-confidence mappings auto-accept; everything below routes to review.
3. **Require Zero Flags = true**.
4. **Applies To = approve** — auto-accept confident *mappings*, but always keep human eyes on the rest.
The card's preview should read roughly *"Auto-approve when AI confidence ≥ 0.90 AND zero flags."* A clean `CC6.1` mapping lands straight in **Mapped**; a 0.6-confidence guess (or a `missing`) routes to **Compliance Review** and the **Inbox**.
> **Under the hood.** Auto-decide never spoofs a user. An auto-accepted artefact's audit row shows actor `AI/auto` plus the confidence; a human confirmation shows the reviewer's email. The trail stays truthful — which is the entire point for an auditor.
Finally, wire the agent to the collection. On the collection's **Agents** tab, **Assign** `Control Mapper` as the intake/processing agent. From now on, every artefact that lands — uploaded or pulled by a connector — is run by the agent automatically, filling the five fields and entering the lifecycle.
**Checkpoint.** Upload one new artefact. Watch it: chip climbs, fields fill, and if confident it lands in **Mapped**; if not, it appears in the **Inbox** at **Compliance Review** for a human.
### Stage 6 — Roles, the auditor's seat, and the coverage dashboard
Two jobs left: give people the right roles — including a read-only seat for the auditor — and build the picture of mapped-vs-missing.
Roles first. Where: `Studio ▸ Security ▸ Access Roles` ([Access & roles](/academy/g1)).
1. **+ Role** → **Role Name** = `Compliance-Reviewer`, **Entity** = `SOC2 Evidence Q4`. Under **Show Advanced Settings**, grant the review/annotate **actions** a reviewer needs and the relevant **Allowed Document Actions**. **Create**.
2. Back on the **Lifecycle** tab, edit the **Compliance Review** stage and set **Can be viewed by** = `Compliance-Reviewer`. Now only that role can act on artefacts waiting for review.
3. **+ Role** again → **Role Name** = `Auditor`, **Entity** = `SOC2 Evidence Q4`. Grant **read-only** actions only: no document-edit actions, leave **Allowed Studio Pages** empty (consumer-only). The auditor can see evidence and mappings but change nothing.
> **The audit trail is the compliance record.** Every stage move — an `AI/auto` accept, a reviewer's confirmation, a re-classification — is written to the immutable **Audit** log (`Studio ▸ Security ▸ Audit`: who, when, what operation). When the auditor asks *"prove who confirmed this artefact maps to CC6.1"*, you filter the Audit log by document and hand them the trail — you never edit it. That trail *is* your answer.
Then a "Control Coverage" View. Open the collection in `Studio ▸ Data Model` and create a **View** ([Shaping the experience](/academy/e7)):
1. New **View** → **Name** `Control Coverage`, **Description** `Every artefact with its control mapping`.
2. **Columns:** `control_family`, `control_id`, `coverage_status`, `evidence_type`, plus the document title and current stage.
3. **Type = Project**, **Allowed roles** = `Compliance-Reviewer`, `Auditor`. **Save**.
Finally the dashboard, in `Studio ▸ Intelligence` ([Dashboards & inbox](/academy/e5)). Build one that answers *"which control families are evidenced, and which are bare?"*:
1. Add a **View Widget** pointed at your `Control Coverage` View — the table auditors browse.
2. Add a **Query Widget** grouping by `control_family` and `coverage_status`; pick **Chart Type = stacked-bar** so each family shows its mapped / partial / missing split at a glance. A family with a tall `missing` segment is a gap you need more evidence for.
3. Optionally add a **KPI / single-number** widget for a headline like "% artefacts mapped".
4. **Open live dashboard** to see exactly what your end-users get.
> **Tip.** The **Agentic Widget** lets you describe a tile in plain language ("a bar chart of evidence count per control family, coloured by coverage status") and have AI build it — the fastest way to a first chart if you're unsure which template fits.
**Checkpoint.** The dashboard shows mapped-vs-missing per family. A control family with no `mapped` rows is a coverage gap — visible, not buried in a spreadsheet.
### Stage 7 — Test the whole machine
A full pass, end to end:
1. **Upload** a fresh access-review export. It enters at **Intake**, the **Control Mapper** runs, and it auto-lands in **Mapped** tagged `CC6.1` (or similar) with a confidence at or above 0.90 — no human needed. Open its stage history: the audit row shows actor `AI/auto` plus the confidence.
2. **Upload** something ambiguous — a generic architecture diagram. The agent returns low confidence (or `coverage_status = missing`); it routes to **Compliance Review** and appears in the **Inbox**. Sign in as a `Compliance-Reviewer`, open it, correct or confirm the mapping, and push it to **Mapped** or **Gap**. The audit trail now shows *your* email on that move.
3. **Open the coverage dashboard.** The stacked-bar shows which families are evidenced and which still read `missing` — that's your gap list for the audit.
4. **Sign in as the `Auditor`.** Confirm you can browse the `Control Coverage` View and read every mapping and citation, but cannot edit anything. Filter the **Audit** log by one document and confirm it tells the full who-did-what story.
If a clean artefact auto-mapped, an ambiguous one routed to a human, and the dashboard surfaced a gap — the machine works.
## Make it production-worthy
- **Measure the mapper's accuracy** ([AI Builder](/academy/a9)). Once reviewers have corrected a few dozen mappings, those corrections are labelled examples. Train an **AI Model** on the `Control Mapping` Learner (`Studio ▸ AI Builder ▸ AI Models ▸ + Model`), then run a **Prediction Report** against a small reference project of known-correct mappings. Read the per-field accuracy — if `control_id` lags, that's where to feed more corrections. The `Control Mapper` agent already targets that Learner, so a better-trained model improves mappings with no re-wiring.
- **Freeze the configuration for the audit period** ([Access & roles](/academy/g1)). You built the read-only `Auditor` role above; pair it with **Project ▸ Version Control ▸ Governance** to **Freeze** the configuration once the audit period opens — nobody can quietly rewrite a control taxonomy you've blessed. The **Audit** log remains the immutable proof of every mapping decision.
- **Export a control-coverage report.** From the **Control Coverage** View or the dashboard, export the coverage table for your auditor — or wire an **Event** ([Taxonomy, lifecycle, tags & events](/academy/d3)) to POST to your GRC tool the moment an artefact reaches **Mapped**: a stage-change trigger with a Webhook action.
The pattern travels. Taxonomy names the categories, the agent assigns them with a confidence, the lifecycle auto-accepts the confident and routes the rest, the dashboard reports coverage. The same shape fits risk tiering, PII discovery, vendor due-diligence, records classification — swap the taxonomy and the rationale prompt, keep the machine. And wherever an agent's output feeds a decision, turn on **Confidence Score** and let **Auto-Decide** plus **Send to Inbox** split clean from uncertain: it's the cheapest, most auditable form of human-in-the-loop on the platform.
## Where to go next
- [Build: Contract review](/academy/uc-contract) — the other "agent reads a document and makes a judgement" build.
- [Package & ship a solution](/academy/uc-ship) — publish this whole compliance machine as a reusable Solution.
- [The Agentic System pattern](/academy/sol-sys) — this build is the compliance facet standing alone; here's how it fits a whole domain brain.
---
## B5 · Build: Contract review
URL: https://www.botminds.ai/academy/uc-contract
> Botminds Academy — Solutions · Agentic Workflow
# Build: Contract review
> **In one line.** A Processing collection plus one extraction agent that flags risky clauses, scores a risk band, and suggests fallback wording — a copilot for a lawyer, never the final word.
> **You'll build.** A `Contracts` collection with a clause table in its schema, a clause-detection skill, a fallback-language tool, the "Contract Reviewer" agent with structured output, an advisory guard rail, and the human review loop in the document detail.
> **You'll use.** [Collections & schema](/academy/d1), [Skills & skill packs](/academy/a6), [Tools & functions](/academy/a5), [Your first agent](/academy/a3), [Guard rails](/academy/a8), [Document detail](/academy/e3).
Someone in legal has to read every incoming NDA, MSA, or vendor agreement, hunt for the dangerous clauses — auto-renewal, uncapped liability, one-sided indemnity, missing termination rights — judge the risk, and suggest safer wording. That first-pass triage is exactly the kind of bounded reading an agent does well. Budget 60–75 minutes for a first build. Prerequisites: one **LLM** registered in the project ([LLMs & services](/academy/a2)), and basic comfort with the agent editor and the Schema tab.
> **A word of honesty up front — this is a copilot, not a compliance gate.** The agent *flags* risky clauses and *suggests* fallback language; a qualified human decides. In particular, the guard rail you'll add is **advisory prompt-level steering, not a hard output filter** — it nudges the agent to stay in scope and tone, but the platform does **not** read the answer back and block it. Treat every output as a first draft for a lawyer. See [Guard rails](/academy/a8) for exactly what a guard rail does and doesn't enforce.
Six pieces: a **collection** (the typed home), a **skill** (what to look for), a **tool** (what to suggest), an **agent** (that does the reading), a **guard rail** (that keeps it in lane), and a **review experience** (where a human reads the findings). We build them in that order.
## Steps
### Stage 1 — The collection and its schema
A contract is something you **decide about** (sign / negotiate / reject), document by document — so it's a **Processing** collection, not Knowledge.
1. Go to `Studio ▸ Data Model ▸ Collections`. Click **+ Collection**.
2. **Purpose:** leave **Processing** selected. This is **immutable after create** — pick it deliberately.
3. **Collection Name:** `Contracts`. **Description:** `Incoming agreements for clause review and risk triage`.
4. **Allowed Ingestion Types** (optional): leave default (Upload) so you can drag in a sample NDA.
5. Click **Save**. `Contracts` appears in the left rail — select it. You should see its tab strip: **General · Schema · Lifecycle · Tags · Events · Ingestion · Agents**.
The **schema drives extraction** — the agent fills in exactly the **Labels** (UI: *Fields*) you define, no more. We want header facts, a *table* of detected clauses, and an overall risk band.
6. With **Contracts** selected, open the **Schema** tab.
7. Click **Taxonomy** (footer) to create the **Learner** (the extractor that owns these fields): **Taxonomy Name** `Contract Review`, **Description** `Header facts, detected risky clauses, and an overall risk band`, **Type** `DocumentClassification` (whole-document field extraction), **Entity** `Contracts` (pre-filled). **Submit**.
8. Select **Contract Review**, then **+ Label** for each header field (use **Add** between them):
| Label name | Description | Shape — how to get it |
|---|---|---|
| `counterparty` | `The other party to the agreement` | Plain text (default) |
| `contract_type` | `NDA, MSA, SOW, vendor agreement, etc.` | Plain text |
| `effective_date` | `The date the contract takes effect` | **View Config ▸ Validation** → date |
| `renewal_date` | `Next auto-renewal / expiry date, if any` | **View Config ▸ Validation** → date |
| `risk_band` | `Overall risk: Low, Medium, or High` | **View Config ▸ Validation** → allowed values `Low, Medium, High` |
9. Now the important one — a **table** field for the clauses the agent flags. Click **+ Label**: **Label Name** `detected_clauses`, **Description** `One row per risky clause the agent flags`. Open **Show Advanced Settings ▸ Record Config** and turn on **Is Record** (this makes it a table).
10. **Add** child Labels as its columns (each child = one column), then **Add and exit**:
- `clause_type` — `e.g. auto-renewal, uncapped liability, one-sided indemnity` (text)
- `severity` — `Low / Medium / High` (**View Config ▸ Validation** → allowed values)
- `excerpt` — `The exact wording detected` (text)
- `suggested_fallback` — `Safer language to propose` (text)
If you'd rather not click the columns in one by one, build the field list in a spreadsheet (one column per nesting level) and use the **Import labels** tab instead — see [Collections & schema](/academy/d1). When you're done, the **Labels** tree under **Contract Review** shows the five header fields plus `detected_clauses` as a table with 4 child fields.
### Stage 2 — The capabilities: a skill and a tool
A **Skill** is a reusable playbook: a name, a "use when…" description for discovery, and a **Markdown body** that says *how* to do the job. We want one that teaches any agent how to scan a contract and surface risky clauses.
11. Go to `Studio ▸ Agent Builder ▸ Skills`. On the **Skills** tab, click **+ Skill**.
12. On the **Form** tab: **Name** `detect-risky-clauses` (lower-kebab — this is the handle agents refer to). **Description:** `Scan a contract and flag risky clauses (NDA scope, indemnity, liability cap, auto-renewal, termination, governing law). Use when the document is a contract or agreement.` The "use when…" half is what tells an agent to reach for this skill — don't skip it. **Tags:** `contract`, `legal`, `risk`.
13. Switch to the **Markdown** tab and write the body — the instructions the agent reads when it invokes the skill. Something like:
```text
Read the supplied contract. Identify clauses in these risk categories and report each you find:
- Auto-renewal — does it renew automatically? Capture the notice period and renewal date.
- Liability — is liability uncapped, or capped at an unusually high multiple? Flag uncapped.
- Indemnity — is indemnity one-sided (only one party indemnifies)? Flag asymmetry.
- Termination — can we terminate for convenience? Flag if only the counterparty can.
- Confidentiality / NDA scope — is the definition of "Confidential Information" overbroad or perpetual?
- Governing law / jurisdiction — flag an unexpected or unfavourable jurisdiction.
For each clause you flag, return: the clause_type, a severity (Low / Medium / High),
the excerpt (the exact wording), and — if you have a suggested-fallback tool available —
call it for safer language and put the result in suggested_fallback. Quote wording from the
document; never invent clauses that aren't there. If a category isn't present, simply omit it.
```
14. Click **Create**. `detect-risky-clauses` appears in the Skills list with a **V1** version chip and a **Project** scope badge (it's yours to edit).
A **Tool** is a single callable the agent invokes mid-run. Here we want a lookup that, given a clause type, returns your firm's **preferred fallback wording** — so suggestions come from *your* playbook, not the model's imagination. Point it at whatever endpoint your team exposes (or a small internal service that returns canned redlines).
15. Go to `Studio ▸ Agent Builder ▸ Tools`. Click **+ Tool**.
16. In the **import grid**, filter **Filter by type → API Endpoint** and import the closest GET-style card. The dialog flips to **form view**.
17. **Tool Name:** `fallback-language-lookup`. **Tool Description** (the model reads this to decide whether to call it — make it say *what* and *when*): *Look up your organisation's preferred fallback wording for a risky contract clause. Use this whenever you have flagged a clause and need to suggest safer alternative language.*
18. In the **code editor**, point the **API URL** at your fallback-language endpoint, set the **method**, and declare the **input schema**, e.g.:
```jsonc
{
"clause_type": { "type": "string", "description": "e.g. auto-renewal, uncapped-liability, one-sided-indemnity" }
}
```
19. If the endpoint needs a key: under **Default parameter values**, add a row, pick the key parameter, set its type to **sensitive**, and paste the key — it will be masked. Never put credentials in the description or URL.
20. **Save.** The tool appears in the list with a read-only **Snippet** on the right.
> **No external API yet?** Two honest fallbacks: (a) skip this tool for now and let the skill body ask the agent to *propose* fallback wording from the contract context — less consistent, but real today; or (b) author the fallback wording as a **Library** snippet or a **Datasheet** the agent reads — see [Library & bots](/academy/a13) and [Drive & datasheet](/academy/d5). The custom-API tool is the cleanest route once your firm exposes a clause-language service.
### Stage 3 — The agent
Now assemble the worker. Full editor tour: [Your first agent](/academy/a3). The editor opens as a full-window dialog with a builder pane on the left and a live **Playground** on the right.
21. Go to `Studio ▸ Agent Builder ▸ Agents` → **+ Agent ▸ Agent**.
22. **Persona tab.** **Name:** `Contract Reviewer`. **Description:** `Flags risky clauses, scores a risk band, and suggests fallback language for human review.` **Instructions** (use the **co-pilot** to seed, then edit to roughly):
```text
You are a cautious contract-review paralegal. For each contract, use your clause-detection
skill to find risky clauses, and for each flagged clause suggest safer fallback language.
Then assign an overall risk_band of Low, Medium, or High based on the worst clauses you
found. You flag and suggest — you never give legal advice or decide whether to sign. Only
report clauses actually present in the document; quote the wording. A qualified human makes
the final call.
```
23. **Model tab.** Pick your project's **LLM Model**. Set **Agent Mode = Thinking** while you build (so you can watch its reasoning); switch to **Fast** for production later. Keep **Temperature** low under **Advanced sampling** — this is judgement-sensitive reading, not creative writing.
24. **Knowledge tab.** Under **Views**, leave it scoped to this collection's own documents (the agent reads the contract in front of it). You don't need a separate Knowledge collection for this build.
25. **Capabilities tab.** **Skills → + Pin skill →** `detect-risky-clauses` (it shows as a **Pinned** card). **Tools → + Add tool →** `fallback-language-lookup` (a card under **Tools**). Optionally tick **Restrict this agent to pinned skills only** for tight, predictable behaviour.
26. **Output tab.** Turn on **Structured output**. Choose the **Taxonomy/Learner** `Contract Review`, set **Process unit = Page**, and add **Labels** matching your schema: `counterparty`, `contract_type`, `effective_date`, `renewal_date`, `detected_clauses` (the table) and `risk_band` — give each a short **Description**. Turn on **Confidence Score** and **References** so a reviewer can see *where* each value came from, and how sure the agent is.
27. **Governance tab.** Guard rail comes in the next stage. If a flagged contract should later trigger an external action (e.g. post to a CLM system via a tool), add a per-tool **Approval** here so a human signs off first — HITL gives you a real **Approve & Execute / Review / Reject** card.
28. Click **Save Agent**.
29. Test it now: in the **Playground** (right pane), set **Input Type = Document**, pick a sample contract, and **Send**. Watch the transcript: a **tool call** to `fallback-language-lookup`, the **detected_clauses** table filling in with severities and excerpts, a **risk_band**, and **References** back to the page. Wrong field? Sharpen its **Description** on the Output tab and re-run.
### Stage 4 — The guard rail (Governance), honestly
A **guard rail** is a named, reusable policy — a single instruction — that the platform **appends to the agent's instructions** at run time. It steers the agent; it does **not** read the answer back and block it. So we use it for what it's genuinely good at: keeping the agent **in scope** (contract review only) and **in tone** (professional, no legal advice).
30. Go to `Studio ▸ Agent Builder ▸ Guard Rails`. Click **+ Guard Rail**.
31. **Name:** `Scope & Tone: Contract Review`. **Description:** `Keep the agent to contract-review scope and a professional, non-advisory tone.` (Max 200 characters.)
32. **Instruction** — phrase it as a direct order; it's pasted verbatim into the agent's instructions:
```text
You assist only with reviewing the contract in front of you: flagging clauses, suggesting
fallback wording, and scoring risk. Maintain a neutral, professional tone. Do not give
legal advice, do not state whether the contract should be signed, and do not answer
off-topic questions — if asked, politely say you only help with contract clause review.
Always note that a qualified human must make the final decision.
```
33. **Save.** Confirm it shows in the list with your instruction in the detail panel.
34. Go to `Agents`, **Edit** `Contract Reviewer`, open the **Governance** tab, click **+ Add** under **Guard rails**, select **Scope & Tone: Contract Review** (it appears as a **shield chip**), and **Save Agent**.
> **Watch out — advisory, not a gate.** This guard rail strongly *steers* the agent, but the platform won't independently block an off-tone or off-scope answer. For anything that **must** be enforced, layer it: a clear guard rail **plus** the human approval in the review loop below **plus** tight knowledge scope. In the Playground, test it: ask `"should we sign this?"` — the agent should decline to advise and steer back to clause review. If it doesn't, sharpen the instruction's wording.
### Stage 5 — Wire it up and test the whole loop
An agent only processes documents once it's a collection's **Worker** (Intake Agent).
35. Go to `Studio ▸ Data Model ▸ Collections`, select **Contracts**, open the **Agents** tab.
36. **Assign** `Contract Reviewer` as the collection's intake/processing agent. The tab shows the assignment with an **Open in Agent Builder** link back to the editor. From now on every contract that lands in **Contracts** — uploaded or pulled in by a connector — is run by the agent automatically, filling the schema and entering the review lifecycle.
37. **Upload a real NDA or MSA.** From the **Contracts** collection (or the consumer document list), add a sample contract. It shows in the list with a **Processing…** chip.
38. **Watch it process.** Open the document — the [Document detail](/academy/e3) fills in *live* as the agent finishes: header fields, the **detected_clauses** table, and a **risk_band**.
39. **Read the findings as a lawyer would.** In the **Summary** pane: read the flagged / low-confidence fields first; click a clause's **excerpt** — the viewer scrolls to and **highlights the source segment** (the agent shows its work — verify it read the real wording); check the **risk_band** and each clause's **severity** and **suggested_fallback**.
40. **Correct and advance.** Fix any wrong value in place — it saves back to the Label and becomes a training signal ([AI Builder](/academy/a9)). Then use the **workflow action pane** to advance the document through its review **stages** (e.g. *approve* / *needs-info* / *reject*), each role-gated and written to the **audit trail**.
What "good" looks like: on a contract with an auto-renewal and an uncapped-liability clause, the agent flags both with **High**/**Medium** severities, quotes the wording, proposes fallback language for each, and scores **risk_band = High** — and a reviewer can verify every flag against the highlighted source in one click.
## Make it production-worthy
- **A clause library.** Instead of (or alongside) the API tool, hold your firm's preferred fallback wording in a **Datasheet** ([Drive & datasheet](/academy/d5)) the agent queries with the built-in **SQL search** toolkit, or as a **Library** snippet in a pipeline node ([Library & bots](/academy/a13)). Structure your redlines once; reuse everywhere.
- **A stricter guard rail — and real enforcement.** Add a second guard rail (e.g. `No External Disclosure`) — but remember guard rails are advisory. For a hard stop, pair it with a **HITL approval** on any tool that *writes* anywhere (**Governance ▸ Approvals**, [Your first agent](/academy/a3)).
- **An approval lifecycle.** Customise the collection's **Lifecycle / Stages** ([Taxonomy, lifecycle, tags & events](/academy/d3)) so a High-risk contract is *routed* to a senior approver before sign-off — the "two humans confirm" rule, made real for risk.
- **Export a redline summary.** Use the document **Export** action ([Document detail](/academy/e3)) to push the detected-clause table and fallback suggestions out to your counsel — or fire an **Event/Webhook** ([D3](/academy/d3)) on stage change.
- **Share it.** Publish the agent, skill, and guard rail to a **Hub** ([Hubs & solutions](/academy/v4)) so other projects install the whole contract-review capability — structure travels, data doesn't.
## Where to go next
- [Build: Compliance evidence mapping](/academy/uc-compliance) — the next review-copilot pattern: mapping evidence to controls.
- [Guard rails](/academy/a8) — exactly what a guard rail does and doesn't enforce; re-read this if the "advisory, not a gate" point still feels surprising.
- [Taxonomy, lifecycle, tags & events](/academy/d3) — design the approval stages a High-risk contract should route through.
---
## B2 · Build: Enterprise data Q&A
URL: https://www.botminds.ai/academy/uc-eqa
> Botminds Academy — Solutions · Agentic Search
# Build: Enterprise data Q&A
> **In one line.** An assistant that lets non-technical staff ask plain-language questions over tabular data — the agent writes read-only SQL against a Datasheet underneath.
> **You'll build.** A `Sales Data` Datasheet (sourced from a connection or materialised from a View), a **Sales Analyst** chat agent that becomes a SQL agent by attachment, a persona that shows its query and assumptions, and the consumer Chat experience.
> **You'll use.** [D5 · Drive & datasheet](/academy/d5), [A3 · Your first agent](/academy/a3), [A5 · Tools & functions](/academy/a5), [E4 · Chat & search experience](/academy/e4), [E7 · Shaping the experience](/academy/e7).
Your operational truth lives in tables, not prose: a sales ledger, an inventory feed, a transactions export. Today only the analysts who speak SQL can ask them anything; everyone else waits for a report. This build gives staff an assistant that answers *"top 10 customers by revenue last quarter"* or *"how many orders shipped late in March?"* correctly, with the agent writing the SQL underneath. Budget about 30 minutes plus the Datasheet's first materialise run. You need a project ([E1 · Getting oriented](/academy/e1)), at least one LLM registered ([A2 · LLMs & services](/academy/a2)), the Datasheet model from [D5 · Drive & datasheet](/academy/d5), and your tabular data ready: a spreadsheet, a database or API the platform can reach, or a Collection you already extract from.
How this differs from [B1 · Policy assistant](/academy/uc-policy): both are Agentic Search, but they retrieve in opposite ways. The Policy assistant does vector RAG — it embeds your question, finds the nearest document chunks, and quotes them. This assistant does SQL retrieval — it writes a `SELECT` against a flat table and computes the answer. Vector search can't reliably count or rank; SQL can't paraphrase a paragraph. Same pattern, two engines — and the single wire that picks the engine is what you attach on the agent's **Knowledge** tab: a Datasheet means SQL agent.
```
(A) spreadsheet / database / API ──┐ (B) a Collection you already extract from
via a source connection │ → View of its labels → materialise
▼ │
Sales Data (DATASHEET — a flat SQL table) ◄───────┘
customer · region · product · order_date · revenue …
+ system cols _BM_STATUS · _BM_RUN_ID · _BM_JOB_ID
│ attach on the agent's Knowledge ▸ Datasheet sub-tab
▼
Sales Analyst (chat agent)
datasheet bound ⇒ built-in SQL toolkit switches on
│
▼ App ▸ Chat
You: "Top 10 customers by revenue last quarter."
Analyst: "Here are the top 10 … [table]
I ran: SELECT customer, SUM(revenue) … GROUP BY … LIMIT 10"
```
Two halves: the **data layer** (get rows into a Datasheet) and the **assistant** (a chat agent whose attached Datasheet turns on the SQL toolkit).
## Steps
### Stage 1 — Get your data into a Datasheet
A **Datasheet** is the platform's structured-data layer: a flat SQL table an agent can query directly ([D5 · Drive & datasheet](/academy/d5)). It lives at `Studio ▸ Data Model ▸ Data`. There are exactly two sourcing paths — pick the one that matches where your data already lives.
| | **(A) Sourced** from a connection | **(B) Materialised** from a View |
|---|---|---|
| Use when… | your data is in a spreadsheet / database / API | your data is the extracted fields of a Collection you already process |
| Rows come from | a **source connection** pulling the external system | a saved **View**'s columns, flattened into the table |
| Typical case | a sales export, an ERP feed, an inventory CSV | "I already extract invoices — let me *analyse* them" |
Path A — sourced from a spreadsheet, database, or API:
1. Open **`Studio ▸ Data Model ▸ Data`**.
2. Click **+ Datasheet** (footer of the left rail) to open the add-datasheet dialog.
3. **Name:** `Sales Data`. **Description:** `Quarterly sales ledger — customers, regions, products, revenue.`
4. Choose its source: pick or create a **source connection** (a database, spreadsheet, or API binding — the same connections listed under the left rail's **Sources** tab). For a one-off spreadsheet, create a connection pointing at it; for a live system, a DB/API connection.
5. Confirm. The Datasheet appears in the list with a status icon. Open it: the **Data** sub-tab shows the rows, **Run Info** shows the first materialise run.
Path B — materialised from a document View. If your numbers are really extracted fields from documents you already process (e.g. the amount / vendor / date pulled from invoices in [B3 · Invoice settlement](/academy/uc-invoice)), don't re-key them — flatten them:
1. Build a **View** over that Collection surfacing the columns you want to analyse — e.g. `customer`, `region`, `revenue`, `order_date` ([E7 · Shaping the experience](/academy/e7)).
2. In **`Studio ▸ Data Model ▸ Data`**, click **+ Datasheet**, name it `Sales Data`, and for its source point it at that View instead of a connection. Each document becomes a row; each surfaced label becomes a column.
Both paths stamp three platform-managed system columns beside your own — you neither create nor edit them:
| Column | Meaning |
|---|---|
| `_BM_STATUS` | the row's processing status (e.g. `OK` / pending / error) |
| `_BM_RUN_ID` | which materialise/refresh run produced the row |
| `_BM_JOB_ID` | which ingestion job the row is associated with |
They let the platform reconcile rows across re-runs without duplicating them — and your agent can filter on them too (e.g. only `_BM_STATUS = 'OK'` rows).
Sanity-check the data before you wire an agent: on the **Data** sub-tab, toggle **Filter** and run a query like `"region" = 'EMEA'` (quoted-column syntax: `"col" = 'value'`), then **Apply Query**. If that returns the rows you expect, the agent's SQL tool will too — you're issuing SQL against the very same backing table the agent reads.
> **Under the hood.** The backing table is named like `DATA_SHEET_{id}_{guid}`. The **Data** tab's filter, the **Run Info** history, and the agent's SQL tool all read that one table.
**Checkpoint.** `Sales Data` appears in the Datasheets list with a healthy status icon; its **Data** tab shows your rows plus the three `_BM_*` system columns; a **Filter** query returns the slice you expect.
### Stage 2 — Build the "Sales Analyst" chat agent (it becomes a SQL agent)
The table exists; now build the Reader that answers over it — the agent editor from [A3 · Your first agent](/academy/a3).
1. Go to **`Studio ▸ Agent Builder ▸ Agents`**. Click **+ Agent ▸ Agent** — the tabbed editor opens beside a live **Playground**.
2. **Persona tab** — who the agent is (you'll tune the prompt fully in Stage 3). **Name:** `Sales Analyst`. **Description:** `Answers plain-language questions over the Sales Data table.`
3. **Model tab** — what powers it. Pick your project's **LLM Model**. Set **Agent Mode = Thinking** while you tune (you'll watch it choose columns and write SQL); flip to **Fast** for production. Leave **Advanced sampling** at defaults.
4. **Knowledge tab — the load-bearing step.** This tab has three sub-tabs — a **View**, a **Datasheet**, and (flag-gated) **Knowledge collections** ([A3 · Your first agent](/academy/a3), Tab 3). Open the **Datasheet** sub-tab and attach `Sales Data`. That single attachment is what makes this a SQL agent.
5. **Capabilities / Output / Governance tabs** — leave at defaults. You do not register anything on the Tools page: the **SQL search** toolkit is a built-in toolkit that switches on automatically the moment a Datasheet is attached on the Knowledge tab ([A5 · Tools & functions](/academy/a5)).
6. Click **Save Agent**.
> **Why attaching a Datasheet is enough — the capability rule.** An agent's capability is data-driven by its config: bind a `datasheet_id` and it becomes a SQL agent; bind a `view_id` and it becomes a search agent; bind neither and it's a general agent. You never tick a "make this SQL" switch — the attachment is the switch. This is the same Knowledge-tab wire as the Policy assistant; only *what* you attach (Datasheet vs Knowledge collection) selects the engine.
> **Watch out — the number-one "why won't it answer my data question?" mistake.** Skip the **Knowledge ▸ Datasheet** attachment and the agent has no SQL tool — it will either refuse counting questions or guess a number from thin air. No Datasheet attached = no SQL toolkit = no real analytics. Check the Knowledge tab first. The attachment is also your scope boundary: the agent queries only the table you gave it.
Don't confuse the two agent-to-data relationships: a **Worker** (intake agent) runs on each document and is set on a *collection's* **Agents** tab; a **Reader** answers over the data and is set here, on the *agent's* **Knowledge** tab. This Sales Analyst is a Reader.
**Checkpoint.** In the editor's **Playground**, set **Input Type = Text**, ask *"How many rows are in the sales data?"*, and press **Enter**. You should see it run a `SELECT COUNT(*)` (expand the **Agent Build Log** / tool calls to watch) and return a number. If it refuses or guesses, re-check the Datasheet attachment in step 4.
### Stage 3 — Tune the persona to explain its answers
A SQL agent that only emits a number is a black box. A trustworthy one shows its work — the query it ran and the assumptions it made — so a non-technical user can sanity-check the answer.
1. Back on the agent's **Persona tab**, open **Instructions** (the system prompt — the soul of the agent). Use the field **co-pilot** to draft, then edit to roughly:
```
You are the Sales Analyst. Answer questions **only** from the attached `Sales Data` table by
writing read-only SQL. For every answer: (1) state the result clearly, in a **table** when it's
a list or ranking; (2) show the **SQL you ran**; (3) name any **assumptions** (date ranges,
how you defined "last quarter", filters like `_BM_STATUS = 'OK'`). If a question needs a column
the table doesn't have, say so plainly — never invent figures. Round money to whole units.
```
2. **Save Agent**.
Make assumptions explicit. Plain-language analytics is full of ambiguity: *"last quarter"*, *"top customers"* (by revenue? by orders?), *"late"* (vs which date?). Telling the agent to state its assumptions turns a guess the user can't see into a statement they can correct — *"by last quarter I mean Apr–Jun; tell me if you meant the fiscal quarter."* That one instruction does more for trust than any model setting.
> **Under the hood — how structured Q&A differs from document retrieval.** A vector-RAG agent embeds the question and pulls the nearest document chunks. A SQL agent does something fundamentally different: it reads the table's column names, writes a `SELECT` (with `WHERE` / `GROUP BY` / `ORDER BY` / `LIMIT` as the question demands), runs it read-only against the backing table, and answers from the computed result set. That's why it can count, sum, rank, and trend — operations vector search can only fake. The flip side: it can only answer what the columns support. No `region` column means no "by region" answer.
**Checkpoint.** In the Playground, ask *"What's total revenue by region?"* — you get a table, the SQL it ran, and a one-line note on any assumptions.
### Stage 4 — Configure the Chat experience and ship it to end-users
Configure the consumer Chat surface ([E7 · Shaping the experience](/academy/e7)), then use it as an end-user would ([E4 · Chat & search experience](/academy/e4)).
1. Go to **`Studio ▸ Chat ▸ General`**.
2. **Default Questions** — seed the analytics people actually ask, as one-click starters: `Top 10 customers by revenue last quarter` · `How many orders shipped late in March?` · `Total revenue by region this year` · `Which product had the biggest month-over-month growth?`. Drag to reorder; tick **Pin default questions** so they stay on an empty chat.
3. **Chat Greeting Text:** `Hi — ask me anything about our sales data: totals, trends, top-N. I'll show you the query I ran.`
4. Leave **Hide Chat References** at your preference — a SQL agent's receipt is the query it shows, not a document chip, so references matter less here than in the Policy assistant.
5. **Save.** The unsaved-change red dot clears on a successful save.
6. Now open **`App ▸ Chat`**. The empty chat shows your greeting and pinned starters. Click **"Top 10 customers by revenue last quarter"**. Watch the **thinking…** footer; expand the **Agent Build Log** to see the agent compose and run its `SELECT`. Read the answer table and the query it reports. Ask a follow-up — *"now just for EMEA"* — and notice it remembers the thread.
Default questions double as documentation and a demo script. Write ones whose answers you've already verified in the Playground, so a first-time user's first click always lands clean.
**Checkpoint — the success condition for the whole build.** A non-technical user asked a plain-language analytics question in chat and got a correct answer computed from the data, with the SQL shown. That's an Enterprise data Q&A assistant.
### Stage 5 — Test it
A few-minute acceptance pass. Ask one of each question shape and verify against what you'd compute yourself:
1. **Count / filter.** *"How many orders shipped late in March?"* — expect a specific number, and the agent should show a `WHERE`-filtered `COUNT(*)`. Cross-check it with a **Data**-tab filter from Stage 1.
2. **Top-N / ranking.** *"Top 10 customers by revenue last quarter."* — a 10-row table ordered descending, with `GROUP BY customer … ORDER BY SUM(revenue) DESC LIMIT 10`.
3. **Aggregate / trend.** *"What's the trend of monthly revenue this year?"* — a per-month breakdown (a table or chart), `GROUP BY` month.
4. **Honest refusal.** Ask for something the table doesn't have — e.g. *"What's each customer's credit score?"* when there is no such column — the agent should say the data doesn't include it, not fabricate scores. If it invents figures, re-check the "never invent" instruction in Stage 3.
5. **Conversation memory.** Ask a follow-up that depends on the previous answer (*"now just EMEA"*) — it should narrow the prior query. Then **+ New chat** and ask the follow-up alone — no context.
If all five pass, the assistant is accurate, honest, and conversational — ship it.
## Make it production-worthy
- **One assistant for both structured and unstructured questions.** The real prize: a single chat that answers *"how many refunds did we issue last month?"* (data) and *"what's our refund policy?"* (docs). The Knowledge tab takes both a Datasheet and a Knowledge collection, so wire both onto one agent: build the Knowledge collection per [B1 · Policy assistant](/academy/uc-policy) Stages 1–2, then on the Sales Analyst's **Knowledge** tab keep the `Sales Data` Datasheet attached and add the collection on the **Knowledge collections** sub-tab (flag-gated by `knowledgeCollections`). The agent then carries two retrieval tools at once and the model picks per question: a "how many" question runs SQL; an "explain the policy" question runs vector retrieval and cites the page. Tighten the persona so it's explicit about which it used.
- **Scope by role.** Sales figures are sensitive. Build the assistant once, then gate who can open its chat with **Access Roles** ([G1 · Access & roles](/academy/g1)). For tiered data (regional managers see only their region), materialise a per-region Datasheet (or a View filtered by region) and give each audience an agent attached only to its slice — the attachment is the data boundary.
- **From answers to a dashboard.** Chat answers a question on demand; a dashboard answers the same questions standing. The Datasheet you built is also a feed for a per-collection or project dashboard ([E5 · Dashboards & inbox](/academy/e5)) — pin the top-N and trend tiles so the numbers your starters compute live on a page, while chat handles the ad-hoc follow-ups.
- **Reusable shape — "ask-my-data".** Get a Datasheet → attach on the Knowledge tab → tune the persona to explain → queried chat. Re-skin it for inventory, transactions, HR headcount, support tickets, an IoT feed — the build is identical; only the table changes.
## Where to go next
- [B1 · Policy assistant](/academy/uc-policy) — the unstructured sibling: vector RAG with citations over a document corpus. Combine the two for an assistant that answers everything.
- [The Search pattern](/academy/sol-search) — the capability ladder this build sits on.
- [D5 · Drive & datasheet](/academy/d5) — the data layer underneath, in depth.
---
## B3 · Build: Invoice settlement
URL: https://www.botminds.ai/academy/uc-invoice
> Botminds Academy — Solutions · Agentic Workflow
# Build: Invoice settlement
> **In one line.** Invoices land in a Processing collection, an **Invoice Extractor** agent pulls the fields, the Four-Eyes lifecycle auto-approves clean small ones and routes the rest to two human reviewers via the **Inbox**, and approved invoices export to your finance system.
> **You'll build.** A complete, audited invoice pipeline — collection, schema, ingestion, extractor agent, an auto-approve gate, export on approval, and a scoreboard tile — in about 45 minutes, entirely by configuration.
> **You'll use.** [Collections & schema](/academy/d1) · [Taxonomy, lifecycle, tags & events](/academy/d3) · [Ingestion & connectors](/academy/d4) · [Your first agent](/academy/a3) · [Document detail](/academy/e3) · [Dashboards & inbox](/academy/e5) · [Shaping the experience](/academy/e7)
This is the canonical "decide on each document" shape — **structured extraction + human-in-the-loop + export** over a **Processing** collection. Learn it here and the triage, contract and compliance builds are variations on it. Before you start you need a project you can build in, at least one LLM registered ([LLMs & services](/academy/a2)), the agent-and-collection model from [Core concepts](/academy/s2), and a handful of sample invoice PDFs.
```
INGESTION COLLECTION (Processing) EXPORT
Drive / Upload ──► Vendor Invoices ──► Finance system
schema: vendor_name, invoice_number, (Blob / Drive /
invoice_date, total_amount, webhook)
due_date, line_items (table)
worker: Invoice Extractor fills the schema
lifecycle: Four-Eyes
clean and under $500 ──► auto-approve
everything else ──► L1 Review ► L2 Approval (Inbox)
dashboard tile: Processed / Pending / Flagged
```
## Steps
### Stage 1 — Create the "Vendor Invoices" Processing collection
Goal: a typed home for invoices, with review stages.
1. Go to `Studio ▸ Data Model ▸ Collections` and click **+ Collection** (rail footer).
2. **Purpose:** **Processing** (the default). This choice is **immutable after create** — pick Processing deliberately.
3. **Collection Name:** `Vendor Invoices`. **Description:** `Incoming supplier invoices for approval`.
4. Leave every other accordion at its default and click **Save**.
> **Flag-gated.** The explicit Processing/Knowledge switch is gated by the `knowledgeCollections` lab flag — if you don't see a switch, new collections are Processing anyway.
> **Checkpoint.** **Vendor Invoices** appears in the left rail. Select it and the right pane shows its tab strip: **General · Schema · Lifecycle · Tags · Events · Ingestion · Agents**. The **Lifecycle** tab is already seeded with the 8-stage Four-Eyes flow — you tune it in Stage 5.
Full field-by-field reference: [Collections & schema](/academy/d1).
### Stage 2 — Design the schema (the fields to extract)
Goal: tell the platform exactly what to pull out of every invoice. **Schema drives extraction** — no Label, no extracted value.
1. With **Vendor Invoices** selected, open the **Schema** tab and click **Taxonomy** (footer) to create the Learner that owns the fields.
2. Enter the Learner: **Taxonomy Name** `Invoice Header`, **Description** `Top-level invoice fields`, **Type** `DocumentClassification` (whole-document field extraction), **Entity** `Vendor Invoices` (pre-filled). Click **Submit**.
3. Select **Invoice Header**, then **+ Label**. A field's *type* comes from a **validation rule** (under **View Config**) plus **Record Config** — there is no single "type" dropdown ([Collections & schema](/academy/d1)). Add these, using **Add** between each:
| Label Name | Description | How to make its type |
|---|---|---|
| `vendor_name` | `The supplier's name` | Plain text — no advanced settings |
| `invoice_number` | `The supplier's invoice number` | Plain text |
| `invoice_date` | `Date the invoice was issued` | **View Config** → add a **date** validation rule |
| `total_amount` | `Grand total including tax` | **View Config** → **numeric** validation rule; optionally tick **Enable Total Field** for a column total |
| `due_date` | `Date payment is due` | **View Config** → a **date** validation rule |
4. Now the line-items table. Click **+ Label** again: **Label Name** `line_items`, **Description** `One row per billed line`. Open **Record Config** and turn on **Is Record**. Add child Labels as its columns: `description` (text), `quantity` (numeric), `unit_price` (numeric). Click **Add and exit**.
> **Checkpoint.** The **Labels** tree under **Invoice Header** shows all six fields, with `line_items` as a table carrying 3 child fields. Exhaustive validation options: [Schema field reference](/academy/r3).
### Stage 3 — Wire ingestion (get invoices into the collection)
Goal: a repeatable way for invoice PDFs to land in **Vendor Invoices**. Go to `Studio ▸ Connector ▸ Ingestion`.
> **Flag-gated.** This teaches the modern **Sources v3** screen (the `ingestionV3` lab flag). If your menu lands on the older single-source wizard, enable `ingestionV3` from the Lab menu ([Getting oriented](/academy/e1)). Full detail: [Ingestion & connectors](/academy/d4).
The fast path, for testing right now: click **Upload** (toolbar), drag in a few invoice PDFs, set **Target collection = Vendor Invoices**, **Submit**. Use this to smoke-test your schema before automating — you'll do exactly this in Stage 9.
The recurring path, for production — a connector must exist before a job can use it:
1. **+ Connector** → pick **Botminds Drive** (this project's internal drive — no credentials). Give it a name → **Test connection** → **Save connector**.
2. **+ Job** → Step 1: select that Drive connector. Step 2: **Job name** `Invoices intake`; **Browse…** to the invoices folder; **Extensions** `pdf`; tick **Recursive**; **Target collection** `Vendor Invoices`. Step 3: **Recurring → every 6 Hours** (check the **Next 5 runs** preview) → **Create job**.
> **Checkpoint.** On the **Jobs** tab you see `Invoices intake … active`. Click **Run now**, then the **Runs** tab — the funnel counters (`Enum → Fetch → New → … → Disp`) fill, and a click on the run opens **Run detail** with a per-file log.
### Stage 4 — Build and assign the "Invoice Extractor" agent
Goal: an AI worker that fills the six schema fields on every invoice. Go to `Studio ▸ Agent Builder ▸ Agents` → footer **+ Agent ▸ Agent**. This opens the tabbed builder beside a live playground ([Your first agent](/academy/a3)).
1. **Persona tab.** **Name** `Invoice Extractor`; **Description** `Extracts header fields and line items from vendor invoices`. Click the **co-pilot** on **Instructions**, seed it with *"Extract the key fields and line items from a vendor invoice,"* then refine to roughly:
```
You are an invoice-processing assistant. For each invoice, extract the
vendor name, invoice number, invoice date, due date, total amount, and
every line item (description, quantity, unit price). Return only values
the document supports; never invent one.
```
2. **Model tab.** Pick your project's **LLM Model**. Set **Agent Mode = Thinking** while you tune, so you can watch its reasoning; leave **Advanced sampling** at defaults.
3. **Output tab.** Turn on **Structured output**. Pick the **Taxonomy/Learner** `Invoice Header`, set **Process unit = Page**, confirm the **Labels** (`vendor_name`, `invoice_number`, `invoice_date`, `total_amount`, `due_date`, `line_items`) each carry a short **Description**, and turn on **Confidence Score** and **References**. Per-field confidence is what routes a document to human review later.
4. Click **Save Agent** — there is no autosave.
5. Test it before wiring it up. In the right **Playground** pane: **Input Type = Document**, pick a sample invoice, press **Enter**. Watch the fields stream in with confidence and page references. Flip **Agent Mode = Fast** and re-run — same fields, quicker; that is your production setting.
6. Assign it as the collection's Worker. Go back to `Studio ▸ Data Model ▸ Collections ▸ Vendor Invoices` → **Agents** tab → **Assign** `Invoice Extractor` as the intake/processing agent.
> **Checkpoint.** The **Agents** tab shows **Invoice Extractor** assigned, with an **Open in Agent Builder** link. From now on every document that lands in **Vendor Invoices** is run by it automatically. The *Worker* you set here is different from a *Reader* — see [Collections & schema](/academy/d1).
### Stage 5 — Configure the lifecycle (auto-approve small, route the rest)
Goal: keep Four-Eyes for real money, but stop sending tiny clean invoices to two humans. Open `Studio ▸ Data Model ▸ Collections ▸ Vendor Invoices` → **Lifecycle** tab. The 8-stage **Four-Eyes** flow is already there (Intake → AI Processing → AI Recommendation → L1 Review → L2 Approval → Needs Info → Approved/Declined). You add **one** auto-approve rule and confirm the review routing — full detail in [Taxonomy, lifecycle, tags & events](/academy/d3).
1. Auto-approve under $500. Below the stage graph, open the **Auto-Decide policy** card and set:
- **Enabled = true**
- **Applies To = approve** (auto-approve only; always keep human eyes on declines)
- **Max Amount = 500**, and set the **Amount Field** to `total_amount`
- Leave **Min Confidence = 0.92** and **Require Zero Flags = true** (the defaults).
- **Save.** The preview should read roughly *"Auto-approve when AI confidence ≥ 0.92 AND zero flags AND amount ≤ $500."*
2. Confirm the review stages send to the Inbox. Click the **L1 Review** stage to open the State editor and confirm **Send to Inbox (human review)** is **on** (this is `IncludeManualIntervention`); do the same for **L2 Approval**. These are what put items in a reviewer's queue. In the seeded flow they're already on — you're verifying, not adding.
> **Checkpoint.** The Auto-Decide card shows your $500 preview. Clean invoices under $500 now skip both reviewers; everything at $500 or above, low-confidence, or flagged still routes to **L1 Review → L2 Approval** and lands in the **Inbox**. Do not use **Reset to default** on a lifecycle with live documents — it is destructive.
### Stage 6 — Walk the review path (how a human corrects and approves)
Goal: know exactly what your reviewers do, so you can design toward it. A document that doesn't auto-approve enters **L1 Review** and the platform creates an **Inbox** item that *wraps* it. The reviewer's path:
1. **Consumer app ▸ Inbox** (route `inbox`). Under **Needs Review / Needs Approval**, each card shows a headline, a **provenance line** (`wraps ▸ Vendor Invoices · doc-… · L1 Review`), age, and the amount. The **Inbox doesn't act** — it is read + snooze + dismiss only ([Dashboards & inbox](/academy/e5)).
2. Click **Open** — you land on the **Document Detail** page (`//:docId`), a split view: the invoice on one side, the extracted fields on the other ([Document detail](/academy/e3)).
3. In the **Summary** pane, read the **flagged (low-confidence)** fields first. Click a value — say **Total : $1,240.00** — and the viewer scrolls to and highlights the source segment it was read from. That is how you catch a mis-read, such as a subtotal grabbed instead of the grand total.
4. Correct a wrong value by editing it in place; your edit saves back to the label and becomes a teaching signal for the trainable model ([AI Builder](/academy/a9)). Run **Rescore** if dependent values need recomputing.
5. Advance the document from the **workflow action pane**: approve sends it to **L2 Approval** (the second eye), who finalises it to **Approved**. Every move is written to the **audit trail** — that trail *is* the decision.
> **Checkpoint.** When the reviewer advances the document past its human stage, the Inbox item resolves itself — it leaves the queue automatically. Editing requires a reviewer/annotator role; a subscription-viewer gets a read-only summary.
### Stage 7 — Export approved invoices
Goal: push approved invoices, with their extracted data, out to your finance system. Go to `Studio ▸ Connector ▸ Output` → **+ Export** ([Ingestion & connectors](/academy/d4)).
1. Pick the **Export Type** first — the rest of the form follows from it. **Name:** `Finance export`. Choose a split/bookmark type if you want structured output, or a plain type to ship the data as-is.
2. **Destination:** under **External Sources**, either **Azure Blob** (Storage Name / Key / Container) or **Botminds Drive** (drive URL). Useful common toggles: **Export input document** (ship the original PDF alongside the data) and **Add date-wise folders**. **Save** (disabled while the form is invalid).
3. Fire it on approval (recommended). So export happens the moment an invoice is approved, add an **Event** instead of exporting by hand: `Vendor Invoices ▸ Events` tab → **+ Event** → trigger **stage change**, **Workflow** `Four-Eyes`, **Stage** `Approved`, **+ Add Action → Webhook** to your finance endpoint ([Taxonomy, lifecycle, tags & events](/academy/d3)). Alternatively, an **Export**-type automation on the **Approved** stage runs the export template on entry.
> **Checkpoint.** Your export appears in the **Output** left rail with its **Type**, **Taxonomy** chips, and **Storage** details. Drive one invoice to **Approved** and confirm the file or POST lands.
### Stage 8 — Add a dashboard tile: processed / pending / flagged
Goal: a bird's-eye score of the pile for your finance lead. Go to `Studio ▸ Intelligence`, select or create a dashboard, and add widgets ([Shaping the experience](/academy/e7)). Building a widget is: **add → pick template → (optional) chart type → point at data → save**.
1. **Processed** — a **Documents Count** widget filtered to stage **Approved**.
2. **Pending** — a **Documents Count** widget filtered to stages **L1 Review** + **L2 Approval** (what's waiting on a human).
3. **Flagged** — an **Error Metrics** (or **QC**) widget, or a count filtered to documents carrying a review flag or a `Wrong Vendor`-type **Tag**.
Not sure which template fits? Use the **Agentic Widget** — describe the tile in plain language ("count of invoices approved this month") and let AI build it.
> **Checkpoint.** **Open live dashboard** jumps to `/_dashboard?did=` — the exact view your end-users get. The Dashboard tab is hidden from the `client` role and under the `DisableDashBoard` flag.
### Stage 9 — Test it end to end
About ten minutes:
1. **Upload a sample.** `Studio ▸ Connector ▸ Ingestion` → **Upload** → drag in one invoice PDF — use a small one, under $500, and a larger one to see both paths → **Target collection = Vendor Invoices** → **Submit**. The result panel reports *"N of M registered."*
2. **Watch it process.** Open the consumer document list for Vendor Invoices. The new row shows a **Processing…** chip that climbs to 100% as the **Invoice Extractor** fills the fields — live, no refresh ([Document detail](/academy/e3)). Stuck at 0%? The background worker isn't running — see [Ingestion & connectors](/academy/d4).
3. **See routing in action.** The under-$500, clean invoice should auto-approve (audit actor `AI/auto`) and skip the humans. The larger one should land in the **Inbox** under **Needs Review**.
4. **Review in the Inbox and Document Detail.** Open the Inbox item → **Open** → on the Document Detail, click a field to verify it against its highlighted source, correct one value, then approve from the action pane. It moves to **L2 Approval**; approve again → **Approved**, and the Inbox item disappears.
5. **See it exported.** Confirm the **Approved** invoice triggered your **Finance export** — a file in Blob/Drive, or a POST to your webhook.
6. **Read the tile.** On the dashboard, **Processed** ticks up and **Pending** reflects anything still in review.
If all six happened, you have a working, audited invoice pipeline — built entirely by configuration.
## Make it production-worthy
Four upgrades, in rough order of effort:
1. **More fields.** Add `purchase_order_number` and `tax_amount` Labels to the **Invoice Header** Learner (Stage 2), then add matching Labels with Descriptions on the agent's **Output** tab (Stage 4) and **Rescore** existing documents. Schema and agent must agree, or the field stays empty.
2. **A "Wrong Vendor" tag and an Overdue view.** On the **Tags** tab add `Duplicate`, `Missing PO`, `Wrong Vendor` for reviewers to apply ([Taxonomy, lifecycle, tags & events](/academy/d3)). Then in `Studio ▸ Data Model` define an **Overdue Invoices** **View** (columns: Vendor, Total, Due Date, Status; filter on due date / status), **Type = Project**, **Allowed roles = Reviewer** ([Shaping the experience](/academy/e7)). Your reviewers now get a one-click "what's overdue" list.
3. **A webhook with an SLA alert.** Extend the Stage-7 **Event** — under **Show Advanced Settings** set **Check SLA Breach** and **SLA Time** so you're alerted when an invoice sits in review too long ([Taxonomy, lifecycle, tags & events](/academy/d3)).
4. **A stricter approval threshold.** Lower the Auto-Decide **Max Amount** to `100` (or raise **Min Confidence** to `0.97`) so more invoices get human eyes — or set **Applies To = both** only once you trust the agent on declines too. Tune the gate to your risk appetite (Stage 5).
## Where to go next
- [Build: Support intake triage](/academy/uc-triage) — the same building blocks assembled to *sort* each document instead of settle it.
- [Taxonomy, lifecycle, tags & events](/academy/d3) — the Auto-Decide policy, Conditional automations, and Events in full.
- [Build: Policy knowledge assistant](/academy/uc-policy) — the other big pattern: answering questions over a corpus.
---
## B9 · Capstone: Lending domain brain
URL: https://www.botminds.ai/academy/uc-lending
> Botminds Academy — Solutions · Agentic System
# Capstone: Lending domain brain
> **In one line.** Stand up an entire governed lending domain — a shared field dictionary, a fleet of specialist agents over reusable skills, origination and servicing workflows, governance / compliance / recommendation / reporting woven across all of it, and one analyst chat that can question the whole tower.
> **You'll build.** Incrementally: first a working lending automation — five `LN` specialist agents over four shared `LN Skill` rules, a coordinator that fills the schema, a confidence gate, a dashboard — then the full Agentic System around it: three collections, a second workflow, RBAC, immutable audit, a trainable model loop, cost telemetry, an analyst chat, and a shippable Solution.
> **You'll use.** [Collections & schema (D1)](/academy/d1) · [Lifecycle & events (D3)](/academy/d3) · [Your first agent (A3)](/academy/a3) · [Skills & skill packs (A6)](/academy/a6) · [Teams & mesh (A11)](/academy/a11) · [LLMs & services (A2)](/academy/a2) · [Security & governance (G1)](/academy/g1) · [AI Builder (A9)](/academy/a9) · [Dashboards & views (E7)](/academy/e7) · [Hubs & solutions (V4)](/academy/v4)
One workflow is a feature. This is a platform. A System is level 3 of the ladder, and it is a *composition*, not an invention: the domain model is [D1's](/academy/d1) collection-times-schema repeated, the workflows are [B7's](/academy/uc-underwriting) shape, the analyst chat is [B2's](/academy/uc-eqa), distribution is [B10's](/academy/uc-ship). You assemble far more than you author. Budget an afternoon to walk one stage end to end; a day or two to do everything.
> **What's clickable vs what's a pattern.** Honesty matters more here than anywhere. The platform ships a real, configuration-only way to build the *spine* of a lending domain — collections, the fleet, the workflows, RBAC, the audit trail, dashboards, cost telemetry, the analyst chat. Several governance and compliance facets, though, are today **represented as taxonomy/labels and architecture** rather than fully clickable engines: model-drift monitoring, confidence calibration, prompt-version governance, data-residency assertions, numeric accuracy SLAs. Each stage below flags which is which — a *Represented today* callout marks the label-represented parts. A good builder labels the difference rather than overclaiming; that honesty is itself a governance discipline.
The build order is bottom-up, because every layer stands on the one below: agents fill a schema that must exist first; workflows route through collections that must exist first; the analyst chat reads collections that must be populated first.
```
TIER 4 ANALYST CHAT one agent, all domain collections attached (Stage 8)
FACETS GOVERNANCE · COMPLIANCE · RECOMMENDATION · REPORTING (Stages 6-7, span everything)
TIER 3 WORKFLOWS origination + servicing/exception (Stages 4-5)
TIER 2 AGENT FLEET LN specialists over shared LN Skills (Stages 2-3, 5)
TIER 1 DOMAIN MODEL three collections, one field dictionary (Stage 1)
→ Stage 9: package the tower as a Solution
```
## Steps
### Stage 1 — The domain model (three collections, one field dictionary)
A lending domain has at least three kinds of thing. `Studio ▸ Data Model ▸ Collections` → **+ Collection** for each ([D1](/academy/d1)):
| Collection | Purpose | Why this kind |
|---|---|---|
| **Lending Applications** | **Processing** | Each application is a case that gets decided — it moves through a lifecycle. |
| **Loan Documents** | **Knowledge** | Paystubs, W-2s, appraisals, bank statements — the evidence corpus the analyst chat reads. Knowledge = no lifecycle, becomes searchable. |
| **Loan Decisions** | **Processing** | The adjudicated outcome per loan — approve/refer/decline plus reasons. Kept separate so reporting and audit have one clean object to count. |
For **Lending Applications**, enter **Collection Name** `Lending Applications`, **Description** `Incoming loan applications for an automated decision`, leave the other accordions at defaults, **Save**.
> **Flag-gated.** The Knowledge category is gated by the `knowledgeCollections` flag — see [B1](/academy/uc-policy) for the honest fallback if you don't have it. And Purpose is **immutable after create** — pick deliberately.
**The shared taxonomy — the load-bearing part.** A domain model is only "shared" if the fields are shared. On **Lending Applications ▸ Schema** → footer **Taxonomy**:
1. **Taxonomy Name:** `Loan File` — **Description:** `The decision fields for a loan application` — **Type:** `DocumentClassification` — **Entity:** `Lending Applications` (pre-filled). **Submit**.
2. Select **Loan File**, then **+ Label** for each field (**Add** between, **Add and exit** on the last). A field's type comes from a **validation rule** under **View Config** — there is no "type" dropdown:
| Label Name | Description | Type |
|---|---|---|
| `applicant` | `The borrower's full name` | Plain text |
| `requested_amount` | `Loan amount requested` | **View Config** → **numeric** |
| `income` | `Total monthly qualifying income` | **View Config** → **numeric** |
| `DTI` | `Back-end debt-to-income ratio, as a percent` | **View Config** → **numeric** |
| `credit_band` | `Credit tier, e.g. Prime / Near-prime / Subprime` | Plain text |
| `risk_flags` | `Any fraud / red-flag findings` | Plain text (one line per flag) |
| `recommendation` | `Approve / Refer / Decline` | Plain text |
Keep `DTI` and `income` numeric — clean numeric fields read well on the dashboard and can gate the lifecycle. This Learner is your **field dictionary**: the single vocabulary every agent fills and every report reads.
> **Represented today — taxonomy governance.** A regulated field dictionary wants versioning, a Reviewer-to-Owner approval workflow, and sensitivity tiers. Real **Version Control** snapshots exist (Stage 6), but per-field sensitivity tiers and field-level approval are today represented as label/description metadata on the Learner, not a dedicated engine. Build the pattern now: add a `sensitivity_tier` note to each field's Description.
> **Checkpoint.** Three collections in the left rail; **Lending Applications** carries the `Loan File` dictionary. Tier 1 stands.
### Stage 2 — The shared skills (the fleet's toolkit)
Write each lending capability **once**, as a reusable Skill, so every specialist pins it instead of you re-pasting a prompt. This is what makes a fleet cheap to build and cheap to fix — change the rule in one place, every agent picks it up on next load.
**Clicks.** `Studio ▸ Agent Builder ▸ Skills` → **Skills** tab → **+ Skill** ([A6](/academy/a6)). For each: on the **Form** tab set **Name** and **Description** (write the description for *discovery* — the "use when…" half tells an agent to reach for it); on the **Markdown** tab write the rule body (write that for *execution*); then **Create** (note the new **V1** chip).
| Skill **Name** | **Description** | **Markdown** body — the rule |
|---|---|---|
| `LN Skill — Income Calculation` | `Compute monthly qualifying income from pay docs; use when verifying income.` | Base income = annual W-2 wages ÷ 12. Average variable income (bonus/OT/commission) over 24 months. Caution on declining income. |
| `LN Skill — DTI Affordability` | `Compute back-end DTI; use when assessing affordability.` | Back-end DTI = total monthly debt obligations (incl. proposed PITI) ÷ gross monthly income × 100. List what counts as a debt. |
| `LN Skill — Credit Analysis` | `Summarise a credit report into a band; use when reading credit.` | Read FICO, tradelines, derogatories. Map to a band: ≥740 Prime · 620–739 Near-prime · <620 Subprime. Note collections/lates. |
| `LN Skill — Fraud Red Flags` | `Spot loan-fraud indicators; use when screening a file.` | Flag income mismatch across statements, identity inconsistency, collateral risk, document tampering (math that doesn't foot, font changes). |
> **Tip — name with a prefix.** `LN Skill — ` and the `LN ` agent prefix are exactly the convention the real lending fleet used — it groups the fleet's assets in the searchable list. Pick a prefix and stick to it. Optionally bundle all four into one **Skill Pack** (`LN Lending Pack`) on the **Skill Packs** tab and pin the pack in one click.
### Stage 3 — The specialist fleet
Five thin specialists, each owning one stage and pinning only the skill(s) it needs. Small and single-purpose is the whole point — tune and test each on its own, not one mega-prompt.
**Clicks.** `Studio ▸ Agent Builder ▸ Agents` → footer **+ Agent ▸ Agent** ([A3](/academy/a3)). For each, set the tabs below, then **Save Agent** (no autosave):
| Agent (**Persona ▸ Name**) | **Instructions** (seed via the co-pilot, then refine) | **Capabilities ▸ Skills** to pin |
|---|---|---|
| `LN Income Verifier` | "Compute the borrower's total monthly qualifying income from their pay documents. Return only the monthly figure and how you derived it." | `LN Skill — Income Calculation` |
| `LN Credit Analyst` | "Summarise the credit report and assign a credit band (Prime / Near-prime / Subprime). Note any collections or late payments." | `LN Skill — Credit Analysis` |
| `LN Fraud Check` | "Screen the file for fraud indicators and list each red flag found. If none, say 'No red flags'." | `LN Skill — Fraud Red Flags` |
| `LN Affordability` | "Compute the back-end DTI percentage from income and monthly debts including proposed PITI." | `LN Skill — DTI Affordability` |
| `LN Decision` | "Given income, DTI, credit band and risk flags, recommend **Approve**, **Refer** or **Decline** with a one-line rationale." | `LN Skill — DTI Affordability`, `LN Skill — Credit Analysis` |
On every agent: **Model** = your project's LLM; **Agent Mode = Thinking** — lending decisions reason across several rules at once, and the whole real fleet runs in Thinking mode. On **Capabilities**, **+ Pin skill** per the table, and optionally tick **"Restrict this agent to pinned skills only"** so the specialist stays predictable. Leave **Output** at chat defaults for now — `LN Decision` gets structured output in Stage 4.
> **Flag-gated — the Playground.** The richer Agent Harness Playground (the right pane with `playground`, `runs`, `evaluation` tabs) is behind the `agentHarness` lab flag; enable it from the Lab menu ([E1](/academy/e1)). Without it you still get a working Playground — just the legacy projection.
**Golden-prompt test each one.** This is exactly how the real fleet is verified: a sharp prompt with a known answer. In the **Playground**, **Input Type = Text**, paste, press **Enter**:
| Agent | Golden prompt | A correct answer contains |
|---|---|---|
| `LN Income Verifier` | "W-2 box-1 wages $84,500/yr and an averaged monthly bonus of $900. State the total monthly qualifying income." | `7,941` (or `7,942`) |
| `LN Credit Analyst` | "Summarise: FICO 712, 6 open tradelines, 1 collection $480, 0 lates in 24 months." | `712` and `collection` |
| `LN Fraud Check` | "Paystub YTD gross $26,000 in March but the W-2 for the prior full year shows $84,500. Any income-fraud concern?" | `mismatch` / `inconsistent` / `discrepancy` |
| `LN Affordability` | "Gross monthly income $9,000. Debts: auto $450, student $250, cards $200, proposed PITI $2,520. Back-end DTI percent?" | `38` |
| `LN Decision` | "Income $9,000/mo; DTI 38%; credit band Prime (FICO 712); no red flags. Approve, Refer or Decline?" | `approve` |
> **Known gap.** Playground **Document** mode for Thinking-mode agents is a known gap — verify agents with these text prompts; PDFs are for the real collection run. Don't promise a live document-mode Thinking demo you can't show.
> **Checkpoint.** Each agent resolves in Thinking mode and its answer contains the golden token. Tier 2 stands: a verified fleet of five over a shared toolkit.
### Stage 4 — First workflow: origination end to end
This stage turns the fleet into a working lending automation — the milestone the rest of the system grows around.
**a) Ingestion.** `Studio ▸ Connector ▸ Ingestion` (Sources v3 is behind the `ingestionV3` lab flag — [D4](/academy/d4)). To test now: **Upload** → drag in a few application PDFs → **Target collection = Lending Applications** → **Submit**. For production: **+ Connector** → **Botminds Drive** → **Test connection** → **Save connector**; then **+ Job** → **Job name** `Applications intake`, **Browse…** to the loan-files folder, **Extensions** `pdf`, tick **Recursive**, **Target collection** `Lending Applications`, **Recurring → every 6 Hours** → **Create job**.
**b) Make `LN Decision` a coordinator over the fleet.** Select **`LN Decision`** → **Edit** → the **Subagents** tab ([A11](/academy/a11)):
1. **Coordination mode = coordinate** — delegate to members, then synthesise one answer.
2. **+ Add subagent** four times: `LN Income Verifier`, `LN Credit Analyst`, `LN Fraud Check`, `LN Affordability`. Give each a one-line **Prefix** (e.g. on Fraud Check: "List every red flag; if none, say 'No red flags'.").
3. On the **Output** tab: turn on **Structured output**, pick the Learner `Loan File`, confirm each **Label** carries a **Description**, set **Process unit = Page**, turn on **Confidence Score** and **References**. **Save Agent**.
**c) Assign it as the collection's Worker.** `Studio ▸ Data Model ▸ Collections ▸ Lending Applications` → **Agents** tab → **Assign** `LN Decision`. Every loan file that lands now runs the whole fleet: the coordinator delegates to the four specialists, synthesises, and writes the seven schema fields.
**d) The gate — auto-clear the easy approvals.** **Lifecycle** tab → the **Auto-Decide policy** card ([D3](/academy/d3)):
1. **Enabled = true**; **Applies To = approve** — keep human eyes on declines and refers.
2. **Min Confidence = 0.92**; **Require Zero Flags = true** — the AI's confidence and an empty `risk_flags` are the code-backed gate the evaluator actually enforces. **Save**; the preview reads roughly *"Auto-approve when AI confidence ≥ 0.92 AND zero flags."*
3. Click **L1 Review** → confirm **Send to Inbox (human review)** is on (`IncludeManualIntervention`); same for **L2 Approval**.
> **Honesty callout — capping on a numeric like DTI.** You may also want "only auto-approve DTI ≤ 43." The card exposes a **Max Amount**, but the shipped evaluator compares one number — the agent's self-reported `_meta.amount` — not an arbitrary schema field by name. A DTI cap only fires if `LN Decision` surfaces DTI as its `_meta.amount`; otherwise leave the cap off and gate on confidence plus flags alone. And never **Reset to default** on a lifecycle with live documents — it is destructive.
**e) The review path a human walks.** **Consumer app ▸ Inbox** — each card wraps a loan file (`wraps ▸ Lending Applications · doc-… · L1 Review`); the Inbox doesn't act, it points ([E5](/academy/e5)). **Open** → **Document Detail** (`//:docId`): click a flagged value — say **DTI : 46** — and the viewer highlights the source segment it was read from; correct in place (it teaches the model — [A9](/academy/a9)); **Rescore** if dependents change; **advance** through **L2 Approval** → **Approved**. Every move writes the audit trail — and that trail *is* the decision; there is no separate decision object.
> **Checkpoint — the milestone.** Upload two files: a clean Prime file (DTI ~38) auto-approves (audit actor `AI/auto`); a flagged or low-confidence one lands in the **Inbox** with a `recommendation` of Refer or Decline. You now have a complete, audited lending *workflow*. Everything after this widens it into a *system*.
### Stage 5 — From workflow to system: grow the fleet, add servicing
**Grow the fleet.** The real production fleet runs about 50 lending agents over 18 shared skills, organised into solution areas — origination intelligence, income verification, asset analysis, underwriting, compliance and fair lending, fraud and QC, pricing, servicing, portfolio and communication. You built a five-agent slice; grow it the same way: more `LN Skill —` rules, more thin `LN` specialists that pin them — an `LN LTV Calculator` (loan ÷ appraised value), an `LN AUS Findings Interpreter`, an `LN Adverse Action Letter Writer` for declines. Each extractor's **Output** tab points at the same `Loan File` dictionary and fills only its slice — one shared vocabulary, many writers.
**Compose Teams.** For multi-step jobs, compose agents into **Teams** ([A11](/academy/a11)): a dedicated `LN Underwriting Decision Team` leader that only coordinates keeps `LN Decision`'s prompt focused on writing the recommendation; **route** mode makes a leader pick one specialist per request — good for triage.
> **Flag-gated.** Nested Deep teams (a team-of-teams) are behind `BM_DEEP_NESTED_TEAMS_ENABLED`.
**Upgrade to a Mesh when you outgrow in-process.** When the pipeline grows long, has true parallel checks (credit *and* fraud at once), or a step needs a slow external service (a bureau pull past 240 seconds), build a **Mesh** (**+ Agent ▸ Mesh** — not flag-gated): members are runnables wired by queues, batons hop over a durable bus, and it survives a restart. Fan the file out to credit and fraud in parallel, then fan in to the decision. The full pattern is worked in [B7](/academy/uc-underwriting).
**Add the second workflow — servicing / exceptions.** A System is *many workflows*, not one. Model a second lifecycle — on **Loan Decisions**, or a dedicated servicing collection — for loans already on the books: escrow analysis, delinquency triage, loss-mitigation eligibility. Most items pass straight through; only exceptions (a delinquency bucket crossing a threshold, a covenant breach) raise a human review. Same [D3](/academy/d3) machinery, applied a second time.
> **Represented today — SLA by stage.** Per-stage SLA budgets (P95 latency, STP targets) are described as an `SLA Conformance` label, not measured by a live SLA engine. You *can* clickably add an SLA-breach alert on a stage **Event** ([D3](/academy/d3)) — teach the alert (clickable) and the budget table (represented).
### Stage 6 — Governance and compliance facets
**Roles / RBAC (fully clickable).** `Studio ▸ Security ▸ Access Roles` ([G1](/academy/g1)). Build the lending roles — `Loan-Processor`, `Underwriter`, `Compliance-Officer`, `Servicing-Agent` — and gate each lifecycle stage to the role allowed to act on it. Roles gate Studio buttons *and* the lifecycle, so "AI recommends, an Underwriter confirms" is enforced, not hoped for.
**Versioning (fully clickable).** `Studio ▸ Project ▸ Version Control` — snapshot and freeze the whole configuration so a change can't silently drift, and you can roll back. This is the real backbone under several governance facets.
**Validation (fully clickable).** The same **View Config** rules that give a `Loan File` field its type also enforce it — an amount is numeric, income on the paystub reconciles with the W-2 — plus agent-side [guard rails (A8)](/academy/a8).
**OFAC / fraud.** The fraud and QC agents run as part of intake, and their results land as fields the gate reads (`risk_flags`, an `OFAC Screen` label). The agents and the gate are clickable; an external OFAC reference-data service is represented as a `Reference Data Service` label rather than a live integration — the LLM does not know the watchlist, the policy just refuses to auto-approve past a flag.
**Immutable audit (fully clickable — this is real).** `Studio ▸ Security ▸ Audit` — every access, create, update, delete, download, and every stage move is recorded immutably. The stage-move history is the compliance record; the mesh run ledger gives a per-segment durable trace on top.
> **Represented today.** Model-agnosticism is half and half: the agent's **Model** tab is a real single swap point and `Studio ▸ AI & Services` lists the swappable models ([A2](/academy/a2)) — do the swap. But assertions like canonical-API-boundary access and data-sovereignty isolation are represented as labels plus architecture, not a clickable enforcement engine. Prompt-version governance is partially live — a versioned-prompt object exists with rough edges — so treat retention/IP assertions as labels plus the vendor-contract layer, not a finished UI.
> **Checkpoint.** Lending roles gate the stages; a frozen snapshot exists; the LLM swap point is exercised; the Audit page shows the immutable trail; clean loans go straight through while exceptions hit a reviewer.
### Stage 7 — Recommendation and reporting facets
**Recommendation (clickable).** The underwriting team already produces approve/refer/decline plus reasons. Wire its output into **Loan Decisions** so every loan ends with a structured recommendation and reasons — one clean object for reporting and audit to count.
**The trainable loop (clickable, honest depth).** `Studio ▸ AI Builder` ([A9](/academy/a9)) — the platform's own trainable extractor, owned by a Learner, improves every time a reviewer corrects a field on Document Detail: correct → train → re-predict. That is how a recommendation engine stops being a static prompt and starts being an apprentice. What is *not* clickable today is asking a Thinking agent to re-read the PDF and self-correct — that path hits the Stage-3 document-mode gap. Reviewers improve the model by correcting labels (real), not by re-running an agent over the document.
> **Represented today.** The production-grade quality controls around that loop — an active-learning dashboard, confidence calibration ("95% confidence means ~95% correct"), drift monitoring with retrain thresholds — are represented as `Active Learning` / `Calibration` / `Drift Monitoring` labels, not finished dashboards. The training loop is clickable; the MLOps governance around it is taxonomy.
**Dashboards (fully clickable).** `Studio ▸ Intelligence` ([E7](/academy/e7)). Build three, one per persona:
| Dashboard | Tiles | Persona |
|---|---|---|
| **Pipeline Ops** | counts by stage, approval rate (Approved ÷ decided), average `DTI` (numeric metric), risk distribution by `credit_band`, what's waiting on a human | Processor / Team Lead |
| **Model Health** | extraction accuracy trend, hallucination-vs-low-confidence split, field confidence summary | QC |
| **Cost** | cost per loan / document / stage / field, spike alerts | Owner |
Cost telemetry is genuine instrumentation — cost-aware inference is live, not a label. Not sure which template fits a tile? Use the **Agentic Widget** — describe it in plain language ("average DTI of approved loans this month") and let AI build it. Add role-scoped **Views** like *Loans Awaiting Underwriter* or *Exceptions Older Than 5 Days* — the lists your teams actually work from.
> **Represented today.** Numeric accuracy SLAs (98.5% classification, 99.9% on sensitive fields) are `SLA Conformance` labels, not measured — you can't truthfully show a 98.5% figure from a single demo loan. Teach the instrumentation; never a fabricated accuracy number.
### Stage 8 — The analyst chat over the whole domain
One chat that answers questions *across* applications, documents, and decisions — [B2](/academy/uc-eqa) applied at system scale. Build a chat agent ([A3](/academy/a3)) and, on its **Knowledge** tab, attach all three collections: `Loan Documents` (the evidence corpus, retrieval) plus the structured `Lending Applications` and `Loan Decisions` (counting and filtering via a Datasheet — [D5](/academy/d5)). That multi-collection attachment is the load-bearing wire: it scopes the agent to exactly the domain and nothing else.
Now an analyst can ask, in `App ▸ Chat`:
- *"What's our approval rate this quarter, and the top three decline reasons?"* (structured, over Decisions)
- *"Show me the income evidence for loan #4821."* (retrieval, over Documents, with citations)
- *"How many loans are stuck waiting on an underwriter?"* (structured, over Applications)
> **Watch out — scope is the guardrail.** Attach only the collections this analyst audience is allowed to see; the Knowledge-tab attachment is the access boundary, and the Chat audit records every question. A System's analyst chat is as governed as everything beneath it.
### Stage 9 — Package the system as a Solution
What you built once should run for the next team or tenant without a rebuild. `Studio ▸ Project ▸ Publish` / `Studio ▸ Hubs` ([V4](/academy/v4); full walk-through in [B10](/academy/uc-ship)). Publish the whole project as a **Solution** to the Solution Hub. The one load-bearing rule: **structure travels, data doesn't** — the package carries the shape (collections, the field dictionary, the fleet, lifecycles, roles, dashboards, guard rails) and deliberately leaves behind your documents, vector index, model credentials, and tenant ids. Those are re-created empty, required to pre-exist, or rebound at install time — the EMBED/DECLARE/REBIND model from [Core concepts (S2)](/academy/s2).
> **Checkpoint.** The lending domain appears in the Solutions catalog. Install it into a fresh project and confirm the structure lands while the data does not.
### Stage 10 — Test the tower
Run the whole thing once, top to bottom — the capstone proof:
1. **Drop a loan file in.** `Studio ▸ Connector ▸ Ingestion ▸ Upload` → a borrower's documents → **Target collection = Lending Applications** (route evidence to **Loan Documents**). The **Processing…** chip climbs as the fleet fills the `Loan File` dictionary.
2. **Spot-run a specialist.** Re-send any Stage-3 golden prompt in its Playground and confirm the fleet still answers with the golden token.
3. **Watch origination route it.** The clean, confident loan goes straight through (audit actor `AI/auto`); the low-confidence or flagged one lands in the right reviewer's **Inbox** under **Needs Review**.
4. **Review one as a human.** Inbox item → **Document Detail** → verify a flagged field against its highlighted source, correct a value (that correction feeds the Stage-7 training loop), approve through **L2 Approval** → **Approved**; the Inbox item self-resolves.
5. **Confirm the decision and the audit.** The loan lands a recommendation plus reasons in **Loan Decisions**; the **Audit** page shows the full immutable trail — who did what, when, at what confidence.
6. **Ask the analyst chat.** One structured question ("approval rate this week") and one retrieval question ("show the appraisal for that loan") — cited, scoped answers across collections.
7. **Read the three persona views.** **Pipeline Ops** (throughput and the gate at work), **Audit** (compliance), a coverage **View** (governance) — three personas, one system.
All seven and you stood up a governed lending domain platform — collections, fleet, workflows, facets — entirely by configuration.
## Make it production-worthy
1. **Tune the gate to your risk appetite.** Raise **Min Confidence** to `0.97` so more files get human eyes; set **Applies To = both** only once you trust the fleet on declines too.
2. **Keep specialists honest.** Golden-prompt every new `LN` agent before it joins a team, and restrict each to its pinned skills.
3. **Label the represented facets.** Fully clickable today: RBAC, versioning, validation, immutable audit, cost telemetry, dashboards, the analyst chat, distribution. Represented as taxonomy: sensitivity tiers, drift/calibration, prompt-version governance, residency, numeric accuracy SLAs. A real System mixes both; keep the labels that state which is which.
## Where to go next
- Ship it to the next team: [B10 · Package & ship a solution](/academy/uc-ship).
- The pattern behind this build: [The System pattern](/academy/sol-sys).
- The analyst-chat layer in depth: [B2 · Enterprise data Q&A](/academy/uc-eqa).
---
## B1 · Build: Policy assistant
URL: https://www.botminds.ai/academy/uc-policy
> Botminds Academy — Solutions · Agentic Search
# Build: Policy assistant
> **In one line.** A chat assistant that answers employee policy questions in plain English and cites the exact policy page — RAG over a Knowledge collection.
> **You'll build.** An `HR Policies` Knowledge collection, an ingest path for your policy PDFs, a **Policy Assistant** chat agent wired to the corpus, and a consumer Chat experience that answers with citations.
> **You'll use.** [D1 · Collections & schema](/academy/d1), [D4 · Ingestion & connectors](/academy/d4), [A3 · Your first agent](/academy/a3), [E4 · Chat & search experience](/academy/e4), [E7 · Shaping the experience](/academy/e7).
HR fields the same handbook questions all day: *"How many remote days am I allowed?"*, *"What's the bereavement policy?"*, *"Which policy covers a sabbatical?"*. The answers exist — buried across a dozen PDFs nobody reads. This build turns those PDFs into an assistant that answers in plain English and cites the exact policy page, so employees self-serve and HR stops being a search engine. Budget about 35 minutes plus index build time. You need a project ([E1 · Getting oriented](/academy/e1)), at least one LLM registered ([A2 · LLMs & services](/academy/a2)), and your policy PDFs ready to upload.
```
policy PDFs ── upload / Drive job ──► HR Policies (KNOWLEDGE collection)
intake: chunk → embed → index
(scoped vector index, entity_id)
│ attach on the agent's Knowledge tab
▼
Policy Assistant (chat agent)
persona · model · Knowledge = HR Policies
│
▼ App ▸ Chat
You: "How many days can I work remotely?"
Assistant: "Up to 3 days a week … [1]"
References: [1] Remote-Work.pdf p.3 ◄── the citation
```
Two halves: the **knowledge pipeline** (turn docs into searchable knowledge) and the **consumer experience** (ask, answer, cite). The single wire that joins them — attaching the collection on the agent's **Knowledge** tab — is what makes answers grounded and stops the agent leaking knowledge it was never given.
> **Honest status — read before you start.** The Knowledge-collection category is a shipped release feature (`knowledgeCollections`, default on); an environment can disable it as a kill-switch. The part still maturing is **auto-vectorise-on-ingest**: the design is settled (a system-seeded "knowledge spine" that chunks, embeds, and indexes every document), but the wiring may not run in every build. What is shipped and load-bearing today: (1) attaching a corpus on a chat agent's **Knowledge** tab, and (2) the chat-with-citations consumer experience — scoped retrieval, grounded answers, reference chips back to the source page. Every step below that leans on a not-yet-fully-shipped piece carries its status and a shipped fallback, so you still finish with a working, citing assistant.
## Steps
### Stage 1 — Create the "HR Policies" Knowledge collection
A Knowledge collection is the *passive corpus* category: you don't decide on each document (no review stages, no field-by-field extraction), you answer over the whole body. That's the opposite of the Processing collection behind [B3 · Invoice settlement](/academy/uc-invoice). Picking the right category is the most important decision in this build — and it's permanent.
| | **Processing** (invoices) | **Knowledge** (policies) — what you want here |
|---|---|---|
| Each document… | gets fields extracted, moves through review stages | is chunked, embedded, indexed for retrieval |
| The agent… | *works* it (a Worker) | *reads* it (a Reader) |
| Has a lifecycle? | Yes | No |
1. Go to **`Studio ▸ Data Model ▸ Collections`** ([D1 · Collections & schema](/academy/d1)).
2. Click **+ Collection** (rail footer). The **General** form opens.
3. **Purpose:** select **Knowledge**. **Collection Name:** `HR Policies`. **Description:** `Company HR policy documents employees can ask questions about`.
4. A **Knowledge settings** group appears (only for Knowledge purpose). Leave the defaults: **Embedding model** (your project default), **chunk size 2000**, **chunk overlap 10**. These control how documents are sliced before embedding — defaults are fine for prose policies.
5. Click **Save**.
> **Watch out — category is permanent.** Processing vs Knowledge is chosen once, at create time, and afterward shows as a read-only chip. There is no converting later. Pick **Knowledge** deliberately.
> **Status.** The **Purpose = Knowledge** switch and the **Knowledge settings** group ship behind the `knowledgeCollections` release flag, default on. If you don't see a Purpose selector, the environment has disabled the category; use the fallback at the end of Stage 2 — a plain collection plus a chat agent still gets you citations.
The UI says **Collection**; the API and URL still say `Entity` / `EntityId`. A Knowledge collection needs a Learner under the hood even without structured fields — the platform seeds one. Terms are in the [Glossary](/academy/r0).
**Checkpoint.** `HR Policies` appears in the left rail. Selecting it shows a tab strip; for a Knowledge collection that strip includes an **Index Health** tab (flag-gated) that a Processing collection doesn't have.
### Stage 2 — Ingest the policy PDFs
Two routes from [D4 · Ingestion & connectors](/academy/d4); for a one-off policy library, Upload is fastest.
Quick path — **Upload** (recommended for a fixed library):
1. From the `HR Policies` collection, open its **Ingestion** tab (or `Studio ▸ Connector ▸ Ingestion`).
2. Click **Upload** in the toolbar.
3. Drag-drop your policy PDFs (`Remote-Work.pdf`, `Leave-Policy.pdf`, `Travel-Policy.pdf`, `Code-of-Conduct.pdf`, …). Each shows its size with a remove control.
4. Confirm **Target collection = HR Policies** (pre-filled when you launched from the collection).
5. Click **Submit**. The result panel reports "N of M registered", the run id, and a per-file docId / error breakdown. Click **Done**.
Recurring path — a **Drive job** (for a library that grows): if HR drops updated PDFs each quarter, wire a recurring pull instead ([D5 · Drive & datasheet](/academy/d5) for Drive as a staging area): **+ Connector ▸ Botminds Drive**, then **+ Job** scoped to the policy folder, **Target collection = HR Policies**, schedule **Recurring** or **On-demand**. Dedup (the **Dup** counter) means re-runs are safe.
> **Under the hood.** For a Knowledge collection, intake doesn't extract fields — it runs the "knowledge spine" pipeline: resolve blob → extract text → chunk (~2000-char overlapping slices) → embed (batches of ~16 chunks) → index. Each chunk carries `{entity_id, knowledge_collection:true}` metadata, and that `entity_id` tag is the whole game: at question time, retrieval is filtered to only this collection's chunks, so an agent can never surface knowledge from a corpus it wasn't given — and a 100-doc and a 100,000-doc corpus answer just as fast.
> **Status — the partly-forward-looking part.** The automatic chunk-embed-index on ingest is still rolling out; the operator behind it is implemented but not shipped in every build. Do not assume a freshly uploaded policy is instantly answerable. If the pipeline is live, the collection's **Index Health** tab ([D3 · Taxonomy, lifecycle, tags & events](/academy/d3)) shows the index building and a readiness chip (e.g. **"141/146 ready"**) — wait for it. If it isn't wired yet, the shipped fallback is to build the chat agent (Stage 3) over the project's existing search index: retrieval and citations behave the same regardless of which path filled the index. Don't promise end-users "instant" until your build's Index Health confirms it.
**Checkpoint.** Your PDFs appear as documents in `HR Policies` with a **Processing…** chip that climbs to 100%. With the flag on, the **Index Health** tab shows each document reaching a ready state. If a doc sticks at 0%, the background worker likely isn't running ([D4 · Ingestion & connectors](/academy/d4)).
### Stage 3 — Build the "Policy Assistant" chat agent
The corpus exists; now build the Reader that answers over it, in the agent editor from [A3 · Your first agent](/academy/a3).
1. Go to **`Studio ▸ Agent Builder ▸ Agents`**. Click **+ Agent ▸ Agent** — the tabbed editor opens beside a live **Playground**.
2. **Persona tab** — who the agent is. **Name:** `Policy Assistant`. **Description:** `Answers employee questions about HR policies, with citations.` For **Instructions** (the system prompt — the soul of the agent), use the field **co-pilot** to draft, then edit to roughly:
```
You are the HR Policy Assistant. Answer employee questions **only** from the attached HR
policy documents. Quote or paraphrase the relevant policy and **always cite the source
document and page**. If the policies don't cover the question, say so plainly and suggest
they contact HR — never guess or invent a policy.
```
3. **Model tab** — what powers it. Pick your project's **LLM Model**. Set **Agent Mode = Thinking** while you tune (you'll watch its retrieval reasoning); flip to **Fast** for production later. Leave Advanced sampling at defaults.
4. **Knowledge tab — the load-bearing step.** Open the **Knowledge collections** sub-tab and attach `HR Policies`. A readiness chip beside it (e.g. **"141/146 ready"**) tells you the index is built and the agent can actually retrieve. Then consider the two locks: turn **Knowledge lock** on so the agent answers only from attached knowledge (no model-memory freelancing — exactly what you want for policy), and leave **Exact-match lock** off (you want semantic matching, so "WFH" finds "remote work").
5. **Capabilities / Output / Governance tabs** — leave at defaults. This is a read-and-answer agent: no Structured-output schema (that's for extraction agents), no tools, no guard rails to start.
6. Click **Save Agent**.
> **Watch out — the number-one "why won't it answer or cite?" mistake.** Skip the Knowledge-tab attachment and the agent has nothing to read: you get vague, source-less, un-citable answers, and it may leak from the model's own training. No attachment = no retrieval = no citations. Check the Knowledge tab first. The scoping is also your security boundary — an agent sees only the collections explicitly attached here.
> **Flag-gated.** The **Knowledge collections** sub-tab is gated by the same `knowledgeCollections` flag. With the flag off, attach knowledge via a **View** over the collection instead (also on the Knowledge tab) — retrieval and citation behaviour are identical; only the attach control differs. See [A3 · Your first agent](/academy/a3), Knowledge tab.
Don't confuse the two agent-to-collection relationships: a **Worker** (intake agent) runs on each document and is set on the *collection's* **Agents** tab; a **Reader** answers over the collection and is set here, on the *agent's* **Knowledge** tab. A Knowledge collection wants a Reader.
**Checkpoint.** In the editor's **Playground**, set **Input Type = Text**, ask *"How many remote days are allowed?"*, and press **Enter**. You should see it retrieve and answer with a reference back to the policy doc. If the answer is vague or uncited, re-check step 4.
### Stage 4 — Configure the Chat experience
A working agent isn't a product until end-users can find and use it. Configure the consumer Chat surface ([E7 · Shaping the experience](/academy/e7)).
1. Go to **`Studio ▸ Chat ▸ General`**.
2. **Default Questions** — add the prompts employees actually ask, as one-click starters: `How many days can I work remotely?` · `What's our bereavement-leave policy?` · `Which policy covers a sabbatical?` · `How much notice do I give to resign?`. Drag to reorder; tick **Pin default questions** so they stay visible on an empty chat.
3. **Chat Greeting Text:** `Hi — ask me anything about our HR policies. I'll point you to the exact policy and page.`
4. (Optional) **Chat Placeholder:** `e.g. How many sick days do I get?`
5. Leave **Hide Chat References** off — references (the citation chips) are the whole point here.
6. **Save.** The unsaved-change red dot clears on a successful save.
Default questions are the cheapest UX win on the platform — they double as documentation and a demo script. Write ones whose answers you've already verified in the Playground, so a first-time user's first click always lands a clean, cited answer.
**Checkpoint.** Your four starter questions are saved and pinned, and the greeting is set.
### Stage 5 — The end-user experience: ask, read citations, give feedback
Now use it as an employee would ([E4 · Chat & search experience](/academy/e4)).
1. Open **`App ▸ Chat`**. The empty chat shows your greeting and the pinned starter questions.
2. Click a starter — e.g. **"How many days can I work remotely?"** — or type your own.
3. Watch the **thinking…** footer: the agent embeds your question, runs a scoped nearest-neighbour match against the HR Policies index, and composes an answer from the retrieved passages. Expand the **Agent Build Log** to watch each step.
4. Read the streamed answer and the **References** block beneath it — `[1] Remote-Work.pdf p.3`.
5. Click a reference chip. The source policy opens at the exact cited page so the employee can verify the claim themselves. This round-trip back to the source is the entire value of the solution — the answer is grounded, not invented.
6. Click a follow-up chip (or ask one) — *"Does that apply to contractors?"* — and notice the assistant remembers the thread.
7. Give the answer a thumbs-up or thumbs-down. That feedback is recorded for you, the builder, to review in `Studio ▸ Chat ▸ Feedback` ([E7 · Shaping the experience](/academy/e7)).
The reference chip isn't decoration — it's the actual passage the agent retrieved, tagged with this collection's `entity_id`. The agent answered from that passage; the chip is the receipt. That's the difference between this and a generic chatbot.
**Checkpoint — the success condition for the whole build.** You asked a policy question in chat and got a cited answer pointing back to the source policy page. That's a Policy assistant.
### Stage 6 — Test it
A two-minute acceptance pass — confirm the load-bearing behaviour, not just that it talks:
1. **Grounded and cited.** Ask *"What's our remote-work allowance?"* — expect a specific answer with a `[1]` reference chip. Click it — it opens the right policy at the right page.
2. **Honest refusal.** Ask something the policies don't cover — e.g. *"What's the pet-bereavement policy?"* — with **Knowledge lock** on, the agent should say it's not covered and point to HR, not invent one. If it invents an answer, re-check the Knowledge lock and the "answer only from attached knowledge" instruction in Stage 3.
3. **Scoping, no leakage.** Ask about a topic that lives in a different collection in your project (e.g. an invoice detail) — the Policy Assistant should not answer it. Its world is exactly the HR Policies you attached.
4. **Conversation memory.** Ask a follow-up that depends on the previous answer — it should resolve the pronoun correctly. Then **+ New chat** and ask the follow-up alone — now it has no context.
If all four pass, the assistant is grounded, honest, scoped, and conversational — ship it.
## Make it production-worthy
- **Add structured answers.** Vector retrieval is great for *"explain it to me"*, but *"which policy covers sabbaticals, and who owns it?"* is a table lookup. Add a small Learner on the collection's **Schema** tab with Labels like `policy_name`, `topic`, `owner_department`, `effective_date`, `applies_to` ([D1 · Collections & schema](/academy/d1)); build a **View** surfacing those columns ([E7 · Shaping the experience](/academy/e7)); in `Studio ▸ Data Model ▸ Data` click **+ Datasheet** and point it at that View ([D5 · Drive & datasheet](/academy/d5)); then give the agent a **SQL tool** bound to that Datasheet ([A5 · Tools & functions](/academy/a5)). One chat then handles both shapes: "explain the remote-work rules" hits the vector index and cites the page; "which department owns the travel policy?" runs a SELECT.
> **Status.** A Knowledge Schema that auto-extracts structured fields during knowledge ingest is part of the same forward-looking design. The shipped fallback is fully real: build the View and Datasheet yourself and bind a SQL tool.
- **Scope by department.** If not every employee should see every policy, split the corpus: one Knowledge collection per sensitivity tier (e.g. `HR Policies — General` vs `HR Policies — Manager`) and a chat agent per audience, each attaching only its tier. Retrieval is scoped by the attached collection, so a general-audience agent cannot surface manager-only policies — the attachment is the access boundary. Gate who can open each agent's chat with **Access Roles** ([G1 · Access & roles](/academy/g1)).
- **Starters per audience.** Pair each scoped agent with its own **Default Questions** ([E7 · Shaping the experience](/academy/e7)) so each audience lands on the prompts they actually ask.
- **Reusable shape — "ask-my-documents".** Knowledge collection → ingest → attach on the Knowledge tab → tune Chat settings → cited chat. Re-skin it for a product manual, an FAQ corpus, an SOP library, contract clauses — the build is identical; only the documents change.
## Where to go next
- [B2 · Enterprise data Q&A](/academy/uc-eqa) — the structured sibling: the agent writes SQL over a Datasheet instead of quoting passages.
- [B6 · SEC filings analyst](/academy/uc-sec) — read a stream of public filings and surface the few things that matter.
- [The Search pattern](/academy/sol-search) — the capability ladder this build sits on.
---
## B6 · Build: SEC filings analyst
URL: https://www.botminds.ai/academy/uc-sec
> Botminds Academy — Solutions · Agentic Workflow
# Build: SEC filings analyst
> **In one line.** An analyst agent reads every incoming SEC 8-K as it lands, decides whether it discloses a material event, routes the flagged ones to a human, and auto-files the routine rest — with an audit trail for every move.
> **You'll build.** The `8-K Filings 2026` Processing collection with an 8-field schema, a scheduled SEC **Public Feed** connector, the analyst agent **Aurora** with a materiality skill and a cross-period tool, and a lifecycle that flags material filings to review and auto-files clean ones.
> **You'll use.** [Collections & schema](/academy/d1), [Taxonomy, lifecycle, tags & events](/academy/d3), [Ingestion & connectors](/academy/d4), [Your first agent](/academy/a3), [Tools & functions](/academy/a5), [Skills & skill packs](/academy/a6), [Shaping the experience](/academy/e7).
Public companies file **8-K** reports whenever something material happens — a goodwill impairment, an executive departure, a legal settlement. They arrive as a stream, unevenly, all day. A human can't read every filing of every issuer you care about fast enough to surface the ones that move the needle. This build is the platform's own canonical demo: the collection is **"8-K Filings 2026"**, the analyst is **"Aurora"**, and the headline moment is *"Aurora flagged a $1.2B goodwill impairment in Wells Fargo's Q4 8-K."* Budget 50–70 minutes for the full build; about 20 if you skip the scheduled feed and upload a sample. Prerequisite: at least one **LLM** registered in the project ([LLMs & services](/academy/a2)).
The shape: a scheduled **Public Feed** drips filings into a **Processing collection**; **Aurora** fills the schema on every arrival; a **lifecycle** branches on her materiality flags — material to a human, routine to auto-file.
## Steps
### Stage 1 — The collection and its schema
A **Collection** is the operational home for one type of record. Here the record type is "an 8-K filing."
1. Go to `Studio ▸ Data Model ▸ Collections`. Click **+ Collection**.
2. **Purpose:** leave **Processing** selected. This is the category that gives each document review **stages**, field **extraction**, and an agent that acts on each one — exactly what we want. It's **immutable after create**, so pick deliberately.
3. **Collection Name:** `8-K Filings 2026`. **Description:** `Incoming SEC 8-K current-report filings, analysed for material events.`
4. Leave the optional accordions at their defaults. Click **Save**. Select the new collection in the left rail — the detail pane shows its tabs: **General · Schema · Lifecycle · Tags · Events · Ingestion · Agents**. You'll touch five of them in this build.
**Schema drives extraction:** the agent pulls a value for **each Label** you define, and *only* those. We define the issuer, the date, a classification of the event type, three **materiality flags**, and a **confidence** score — the confidence is what later decides whether a filing needs human eyes.
5. With `8-K Filings 2026` selected, open the **Schema** tab. Click **Taxonomy** (footer) to open **Create Taxonomy**: **Taxonomy Name** `Filing Analysis`, **Description** `Top-level analysis of an 8-K filing`, **Type** `DocumentClassification` (whole-document field extraction), **Entity** `8-K Filings 2026` (pre-filled). Click **Submit**.
6. Select **Filing Analysis**, then **+ Label**. Add these, using **Add** between each and **Add and exit** on the last. Remember: a field's *shape* comes from a **validation rule** in **View Config**, not a type dropdown.
| Label | Description | Shape — how |
|---|---|---|
| `issuer` | `The filing company's name (e.g. "Wells Fargo & Co").` | Plain text (default) |
| `filing_date` | `The date the 8-K was filed.` | **View Config** → date validation |
| `event_type` | `The primary 8-K item/event category (e.g. impairment, exec change, settlement, other).` | **View Config** → validation listing allowed values (single-select) |
| `confidence` | `Aurora's confidence (0–1) that the event classification is correct.` | **View Config** → numeric validation |
7. Add the three **materiality flags** — each is just a boolean Label, one per material-event family. Add three more Labels under **Filing Analysis**, each with a **two-value (boolean)** validation rule in **View Config**:
| Label | Description |
|---|---|
| `is_impairment` | `True if the filing discloses a goodwill or asset impairment.` |
| `is_exec_change` | `True if the filing discloses an executive departure, appointment, or board change.` |
| `is_settlement` | `True if the filing discloses a legal settlement, judgment, or material litigation event.` |
Keeping the three flags as separate booleans (rather than stuffing everything into `event_type`) pays off twice: the lifecycle can branch on *"any flag true"*, and your end-of-week View can filter on each event family independently. Checkpoint: the **Labels** tree under **Filing Analysis** shows 8 fields.
### Stage 2 — Ingestion: a scheduled SEC Public Feed (or upload a sample)
The connector model is **Connector = identity**, **Job = scope + schedule**, **Run = one execution** ([Ingestion & connectors](/academy/d4)). The SEC stream is a built-in **Public Feed** connector.
> **Flag-gated screen.** This uses **Sources v3** (`Studio ▸ Connector ▸ Ingestion`, flag `ingestionV3`). If you land on the older single-source wizard, enable `ingestionV3` from the Lab menu first ([Getting oriented](/academy/e1)).
8. `Studio ▸ Connector ▸ Ingestion` → **+ Connector**.
9. **Step 1 — kind:** pick the **Public Feed** tile (*"Public gov data (SEC, CFPB, Federal Register)"*). Public Feed is a 2-step wizard — there's no auth step.
10. **Step 2 — pick the feed:** in the registry, search for and select the **SEC** filings tile. Live tiles are selectable with a primary border; greyed tiles are "Available in a future release" — don't pick those. Each tile shows its name, description, **drip** behaviour, and a license/use-case chip.
11. Give the connector a name (defaults to the feed name), click **Test connection** — it reports the last item date, and Public Feed connectors **cannot be saved until the test passes** — then **Save connector**.
12. Back on the **Ingestion** screen → **+ Job**. **Step 1 — Connector:** select your new SEC connector.
13. **Step 2 — Scope & mapping:** **Job name** `8-K nightly pull`; the Public Feed renders its own scope fields (issuer/form filters where the feed exposes them); set **Target collection** to `8-K Filings 2026`. Leave **Secondary XFlows** empty.
14. **Step 3 — Schedule:** public feeds offer preset chips — pick **Every 6h** (or **Daily 9am UTC**). Check the live **Next 5 runs** preview, then **Create job**.
A recurring feed job pulls only *new* items each run (**drip**) and reports `Dup` for filings it has already seen (**dedup**), so running every 6h is safe and cheap — you won't reprocess yesterday's filings.
Faster alternative — skip the connector entirely and upload a sample for the walkthrough:
15. `Studio ▸ Connector ▸ Ingestion` → **Upload**. Drag in a sample 8-K PDF (e.g. a real Wells Fargo Q4 8-K), set **Target collection** = `8-K Filings 2026`, **Submit**. The result panel shows the registration and the run id; the document is now in the collection with a **"Processing…"** chip — perfect for testing the rest of the build immediately.
Checkpoint: either the **Jobs** tab shows `8-K nightly pull · Every 6h · active` (click **Run now** to trigger it and watch the **Runs** funnel fill), or your uploaded sample is sitting in the collection. Filings are flowing in.
### Stage 3 — Aurora, her skill, and her tool
This is the brain: a persona, a model, one **skill**, one **tool**, and a **structured output** that fills the schema. Full editor tour: [Your first agent](/academy/a3).
16. `Studio ▸ Agent Builder ▸ Agents` → **+ Agent ▸ Agent**.
17. **Persona tab.** **Name:** `Aurora`. **Description:** `Reads SEC 8-K filings and flags material events for analyst review.` **Instructions** (the system prompt — the soul of the agent): click the **co-pilot**, seed it with *"Analyse an SEC 8-K filing and flag any material events,"* then refine the draft to read roughly:
```text
You are Aurora, a senior SEC filings analyst. For each 8-K filing, identify the issuer, the
filing date, and the primary event it reports. Decide whether the filing discloses a material
event in any of these families: a goodwill or asset impairment, an executive or board
change, or a legal settlement / material litigation. Set the matching flag(s) to true and
classify event_type. Quote the exact sentence that supports each flag. If a filing is routine
and discloses nothing material, set all flags false. Never invent a fact the filing does not
state; report only what the document supports, and give your confidence in the classification.
```
18. **Model tab.** Pick your project's **LLM Model**. **Agent Mode = Thinking** — materiality is a reasoning call, not a lookup; you'll watch its reasoning while testing, then ship in **Fast** if you trust it. Leave **Advanced sampling** at defaults.
19. **Output tab** — this is what turns chatty Aurora into a data extractor. Turn on **Structured output**. **Taxonomy/Learner:** `Filing Analysis`. **Process unit:** `Page`. Confirm the **Labels** match your eight fields, each with its short **Description**. Turn on **Reasoning**, **Confidence Score**, and **References** — the confidence is what routes a filing to human review; references quote the supporting sentence, your audit evidence. Click **Save Agent**.
20. Now author the skill. A **Skill** captures a reusable instructions-plus-tools recipe once, so you can hand the same materiality playbook to other agents later (a CFPB analyst, a Federal-Register analyst) without rewriting the prompt. `Studio ▸ Agent Builder ▸ Skills` → **Skills** tab → **+ Skill**.
21. **Form** tab: **Name** `material-event-detector`. **Description** (write this for *discovery* — when should an agent reach for it): *"Decide whether an SEC filing discloses a material event (impairment, executive change, or legal settlement). Use when analysing an 8-K or similar current report."* **Tags:** `sec`, `materiality`.
22. **Markdown** tab — the body (write this for *execution* — how to do the job):
```text
Read the filing. For each material-event family below, decide present/absent and quote the exact
supporting sentence:
1. Impairment — goodwill or asset write-downs, "impairment charge", non-cash impairment.
2. Executive / board change — resignation, appointment, departure of a named officer or director.
3. Settlement / litigation — settlement amount, judgment, consent decree, material legal proceeding.
Set the matching flag true only with a supporting quote. Classify event_type as the dominant
family (or "other"). State your confidence (0–1). If nothing material is disclosed, set all flags
false and event_type = routine.
```
23. Click **Create** (note the **V1** chip). Then pin it onto Aurora: open Aurora → **Capabilities** tab → **Skills** → **+ Pin skill** → `material-event-detector` → **Save Agent**. If you plan to add more SEC skills, bundle them into a **Skill Pack** (e.g. `SEC-Analyst`) — pin the pack once and every member skill comes with it ([Skills & skill packs](/academy/a6)).
24. Now the tool — a callable Aurora can invoke mid-analysis: a custom **API tool** that fetches a prior-period filing for the same issuer so she can do a cross-period comparison (*"is this impairment new, or already disclosed last quarter?"*). `Studio ▸ Agent Builder ▸ Tools` → **+ Tool**.
25. In the import grid, filter by type **API Endpoint** and import the closest GET-style card — the dialog flips to **form view**. **Tool Name:** `filing-period-compare`. **Tool Description** (the model reads this to decide *whether* to call it — say *what* and *when*): *"Fetch a prior-period filing for the same issuer so the current filing can be compared. Use when you need to tell whether a disclosed event is newly reported or a continuation of a prior period."*
26. **Code editor:** point the **API URL** at your filings endpoint, **method** GET, and declare an **input schema**:
```jsonc
{
"issuer": { "type": "string", "description": "Issuer name or CIK" },
"prior_period": { "type": "string", "description": "Period to compare against, e.g. 'previous-quarter'" }
}
```
27. If your endpoint needs a key, add a **Default parameter value** of type **sensitive** (masked) — never put credentials in the URL or description. **Save.** Then attach it: open Aurora → **Capabilities** → **Tools** → **+ Add tool** → `filing-period-compare` → **Save Agent**.
Why a tool, not a skill? The *skill* is the materiality *judgement* (a prompt playbook); the *tool* is a single *callable* that fetches data the judgement needs. Verb (tool) vs playbook (skill) — see [Skills & skill packs](/academy/a6).
Checkpoint: select Aurora, open the right-pane **Playground**, set **Input Type = Document**, pick your sample 8-K, and press **Enter**. Watch the **Thinking** block, the eight extracted fields, the per-field **confidence**, the **References** back to the page — and a **tool call** to `filing-period-compare` in the transcript when she reaches for prior-period context. Flip **Agent Mode = Fast** and re-run — same fields, much quicker.
### Stage 4 — Wire the loop: intake agent + lifecycle
An agent does nothing until it's given a stream of work.
28. Go to `8-K Filings 2026` (`Studio ▸ Data Model ▸ Collections`) → open its **Agents** tab. **Assign** `Aurora` as the collection's intake/processing agent. From now on, **every** filing that lands — pulled by the SEC job or uploaded — is run by Aurora automatically: she fills the eight schema fields and the document enters the lifecycle. The tab shows Aurora assigned, with an **Open in Agent Builder** link.
29. Now the *life* of a filing ([Taxonomy, lifecycle, tags & events](/academy/d3)). Your collection was seeded with the **8-stage Four-Eyes** flow (Intake → AI Processing → AI Recommendation → L1 Review → L2 Approval → Needs Info → Approved/Declined). We want: material filings go to a human; clean/routine filings file themselves. Open the collection's **Lifecycle** tab.
30. **Route material filings to L1 Review.** On the **AI Recommendation** stage, add a **Conditional** automation that branches on the flags Aurora set: **if** `is_impairment = true` OR `is_exec_change = true` OR `is_settlement = true` → move to **L1 Review** (which has **Send to Inbox** = on, so it reaches a human); **else** → continue toward **Approved**. The Conditional type is the routing workhorse — it reads an extracted/classification label value and picks the next stage. That's why we made the flags first-class booleans in Stage 1.
31. **Auto-file the clean ones.** Below the stage graph, open the **Auto-Decide policy** card and set:
| Field | Value | Why |
|---|---|---|
| **Enabled** | `true` | Turn the policy on. |
| **Applies To** | `approve` | Auto-approve clean cases; always keep humans on anything flagged. |
| **Min Confidence** | `0.92` (default) | Only auto-file when Aurora is sure. |
| **Require Zero Flags** | `true` (default) | Any material flag open means no auto-file — it routes to L1. |
32. The card's plain-English preview should read roughly *"Auto-approve when AI confidence ≥ 0.92 AND zero flags."* Save.
> **Watch out.** **Require Zero Flags = true** is doing the heavy lifting here: a filing with *any* materiality flag set can never auto-file — it's guaranteed to reach a reviewer. That's the safety property you want.
Checkpoint: a routine 8-K with all flags false and confidence ≥ 0.92 skips both reviewers and lands in **Approved**. A filing where Aurora flags an impairment is routed to **L1 Review** and sent to the **Inbox** — every move written to the audit trail.
### Stage 5 — Watch it live, then test end to end
Here's the honest picture of which live views actually exist.
33. **The consumer document list — real, works everywhere.** Open the project's consumer app → the `8-K Filings 2026` document list ([Document workspace](/academy/e2)). When a filing is being processed, its row shows a live **"Processing…"** chip with a percentage that climbs in real time; when it reaches done, the extracted fields fill in and the status/score appears. This is real and not flag-gated — it works on QA and Prod.
34. **The Agent OS "Living Workshop" heartbeat — real, but flag-gated.** If you're on a build with the **`agentOsDemo`** flag (realistically local/demo — it's **off in QA and Prod**), open **Agent OS ▸ Work ▸ `8-K Filings 2026`**. Because Aurora owns the collection, you get the **Living Workshop**: a **heartbeat banner** that breathes (**Ready** when idle, **At work right now** when a filing is in-flight); **Now reading {filing}** with a progress bar and the stage timeline (Loading → Validating → Parsing → Calling LLM → Extracting fields); a **reasoning stream** of Aurora's live bullets (thoughts, extractions like *"is_impairment = true"*, flags) that fade in and decay; and **this-shift pulse counters** (done · extractions · flags · escalations). This is the canonical *"Aurora flagged a $1.2B goodwill impairment in Wells Fargo's Q4 8-K"* moment.
> **Be honest about the boundaries.** Agent OS Phase 1a is a **read-only skin**. The Home page's *"Currently running"* and *"What's new"* strips are **always empty** (telemetry not wired), Agent L2's *Recent runs* / *This week* panels are **stubs**, and the only live heartbeat is the one inside Collection L2. If you're on QA/Prod, use the consumer **"Processing…"** chip — it delivers the same "watch it happen" feeling without the flag.
35. **Arrive.** Upload a real Wells Fargo Q4 8-K (or **Run now** the SEC job). The document appears in the `8-K Filings 2026` list with a **"Processing…"** chip.
36. **Read.** The chip climbs as Aurora reads the filing. Fields fill in: `issuer = Wells Fargo & Co`, `filing_date`, `event_type = impairment`, `is_impairment = true`, `confidence`.
37. **Flag and route.** Because `is_impairment = true`, the Auto-Decide policy's **Require Zero Flags** blocks auto-filing, and the **Conditional** on AI Recommendation routes the document to **L1 Review**. The filing lands in the **Inbox** ([Dashboards & inbox](/academy/e5)) for a reviewer with the **L1-Reviewer** role. Open it — the **References** show the exact sentence Aurora quoted for the impairment.
38. **Contrast.** Upload a *routine* 8-K (no material event). All flags come back false, confidence is high — it auto-files to **Approved** without touching a human.
39. **Audit.** Open either document's **stage history** — every move (AI handoff, route-to-L1 or auto-approve) is on the trail. The "decision" *is* that trail.
If a material filing *doesn't* flag, sharpen the **skill body** or the **field Descriptions** on Aurora's **Output** tab, re-run in the playground, repeat — that loop is the whole craft.
## Make it production-worthy
- **Cross-period diff skill.** Author a second skill `period-over-period-diff` that *uses* the `filing-period-compare` tool to report what changed since the prior filing (new impairment vs ongoing). Bundle it with `material-event-detector` into an `SEC-Analyst` **Skill Pack** and pin the pack onto Aurora ([Skills & skill packs](/academy/a6)).
- **Alerts via a webhook Event.** On the **Events** tab ([D3](/academy/d3)), add an Event: trigger **stage-change**, scope **Workflow = Four-Eyes · Stage = L1 Review**, **+ Add Action → Webhook** → your alerting endpoint. Now every flagged filing POSTs to your system the instant it's routed — *"material event detected, awaiting review."* Add **Check SLA Breach** if you want a late-review alarm too.
- **A "Material events this week" View and dashboard tile.** In `Studio ▸ Data Model`, create a **Project View** named `Material events` ([Shaping the experience](/academy/e7)): columns `issuer · event_type · filing_date · confidence`; filter *any flag = true*; **Allowed roles = Analyst**. Then in `Studio ▸ Intelligence`, add a **View Widget** pointed at that View (or a **Query Widget** counting flagged filings per week) — a live tile your analysts read in the [dashboards](/academy/e5). Add a **Default Question** in `Studio ▸ Chat` like *"What material events were filed this week?"* so chat opens on the question your users actually ask.
## Where to go next
- [Build: Package & ship](/academy/uc-ship) — package this whole build (collection, Aurora, skill, tool, lifecycle, View, dashboard) as a publishable **Solution** another project installs in one click ([Hubs & solutions](/academy/v4)).
- [Taxonomy, lifecycle, tags & events](/academy/d3) — the Conditional automations and Auto-Decide policy in full.
- [Shaping the experience](/academy/e7) — Views, dashboard tiles, and chat starters: the bridge from builder to end-user.
---
## B10 · Package & ship a solution
URL: https://www.botminds.ai/academy/uc-ship
> Botminds Academy — Solutions · Ship it
# Package & ship a solution
> **In one line.** Package the solution you built once as a recipe, publish it to a Hub, and install it into a fresh project for the next team — without copying a single document, credential, or tenant id.
> **You'll build.** A published **Solution**: snapshot and freeze Project A, publish it to the signed Hub with a setup guide and sample data, install it as Project B, wire Project B's own credentials and model, and prove it by running a sample invoice end to end.
> **You'll use.** [Build: Invoice processing](/academy/uc-invoice) · [Access & roles](/academy/g1) · [Hubs & distribution](/academy/v4) · [Glossary](/academy/r0)
The setup: you built the invoice solution in [Build: Invoice processing](/academy/uc-invoice). It works — for one team, in one project. Now Finance West wants it. Then the German subsidiary. Then a customer. Rebuilding it by hand each time is slow, error-prone, and drifts: version three quietly differs from version one. You want to build once and deploy to many.
The load-bearing idea: **structure travels; data doesn't.** A package carries agent instructions, schemas, pipeline steps, guard rails, dashboards — never your documents, vectors, or model keys. You'll take **Project A** (the finished invoice solution) and stand up a working copy in **Project B** (the next team), passing through a Hub in between. Plan for about 45 minutes; the full publish / install / REBIND mechanics live in [Hubs & distribution](/academy/v4).
Two grains of packaging exist, and you'll see both:
| | **Solution** (whole project) | **Object Package** (single object) |
|---|---|---|
| **You ship** | The entire invoice project | Just the **Invoice Extractor** agent |
| **It installs into** | a **new** project (or an existing one, via **Install here**) | an **existing** project |
| **Use for** | standing up the whole app for a new team or tenant | adding one reusable piece to a project that exists |
> **Honesty callout — read before you start.** The whole-project **Solution** path (the stages below) is the established, shipped way to distribute a solution today. The per-object **Object Package** track is partly forward-looking: the per-object publish → import → REBIND flow does ship, but the fuller design — signed single-object packages, an install wizard with schema-compatibility verdicts, per-object upgrade-in-place, a rollback ledger — is designed but not fully built (whole-project Solutions *do* upgrade in place and roll back on the signed Hub today). Treat **EMBED / DECLARE / REBIND** as the mental model (it already explains today's behaviour), and when in doubt, ship a Solution.
## Steps
### Stage 1 — Prepare the source: commit, snapshot, freeze
*(Project A · shipped)*
You never publish a moving target. Lock the configuration first; you'll describe the package at publish time.
1. In Project A, open `Studio ▸ Project ▸ Version Control`.
2. On the **History** tab, click **Commit…** and record a checkpoint — message e.g. *"v1.0 invoice solution — ready to ship"*. This is your named, rollback-able milestone.
3. Switch to the **Snapshots** tab and take a **full** export — your belt-and-braces copy before you hand the solution to other teams.
4. Switch to the **Governance** tab and click **Freeze**. The freeze-status chip (top-right) flips from green **Active** to red **Frozen**. Frozen configuration gates destructive edits, so nobody quietly rewrites the recipe you're about to publish.
> **Tip — the shipping rhythm.** *Commit* at each milestone, *snapshot* before anything risky, *freeze* once a solution is stable and shipping. Unfreeze only when you genuinely need to change it, then re-freeze.
**Checkpoint.** The version-control chip reads **Frozen**, and your commit shows in **History**.
You'll describe and publish the package in Stage 3 — but first understand exactly what ships, in Stage 2.
### Stage 2 — Know what ships: EMBED / DECLARE / REBIND
*(conceptual · the mental model — applies today)*
When you publish, the platform walks the solution's **dependency closure** — every object it needs to run — and classifies each edge into one of three buckets. This is *why* some fields appear in the publish dialog and others don't, and *why* the import asks you to pick local objects. Walk your invoice solution piece by piece:
| Piece of the invoice solution | Class | Ships? | Why |
|---|---|---|---|
| **Invoice Extractor agent** — instructions, persona, sub-agents, skills, guard rails | **EMBED** | Yes, by value | Pure config — re-created with a fresh id in Project B. |
| The **dashboards** (Intelligence) | **EMBED** | Yes, by value | Shipped as part of the Solution. |
| The **LLM model** the agent uses | **DECLARE** | No | An environment capability. The package says "I need a GPT-4-class chat model"; it never carries your endpoint or API key. Project B must already have one. |
| Any **MCP server** the agent calls; the platform version | **DECLARE** | No | Required at the destination, with its own credentials — verified at install, never shipped. |
| The **Invoice collection schema / view** the agent reads and writes | **REBIND** | No — the *binding* travels, not the data | A project-local data dependency. The package carries a named slot plus a description ("the invoices view"), and the importer wires it to one of *their* collections or views at install. |
| A **Datasheet** the agent queries (if your build used one) | **REBIND** | No | Same: a slot plus description, bound to Project B's datasheet at install. |
| Your **invoices, extracted values, vector index** | — | No, ever | Data. Sanitized out at publish. Project B starts empty. |
| Your **model keys, tenant ids, secrets** | — | No, ever | Stripped at publish. Nothing sensitive ships. |
Read the table top to bottom and you have the whole model: **EMBED** = config shipped by value; **DECLARE** = capability required, never shipped; **REBIND** = a data dependency wired at install. Structure travels; data doesn't.
> **Tip.** On the agent-object track, the REBIND rows are exactly the textareas in the publish dialog and the dropdowns the importer fills in. On the signed-Solution track, the DECLARE rows surface as the install **compatibility check**: the preflight requirement rows and the credentials preview the installer sees before committing — see Stage 4.
### Stage 3 — Publish to the Hub
*(Project A · shipped)*
Two choices of where the package lands, matching the two grains: publish the **whole project** (this build's main path — a signed Solution on the Hub), or publish just the **Invoice Extractor** agent to the **Agents** registry (covered under production notes below).
1. In Project A, open `Studio ▸ Hubs ▸ Solutions` and click **Publish to Hub**. (If your workspace has several Hub servers registered, the **Target hub** picker chooses where it lands — the registry of hubs itself is workspace-Admin-only.)
2. Describe the package in the modal, *for a stranger*:
- **Name / Version / Category / Summary** — e.g. `Invoice Processing`, `1.0`, `Finance`, one sentence on what each team gets.
- **Listing icon** — small PNG/SVG.
- **Overview & setup guide** — markdown, with a live preview. This becomes the Solution's **Setup guide** tab; write what the installer must do on day one.
- **Sample / demo data** — attach a test invoice or two. They ship with the Solution (stripped of secrets) and power **Run demo** after install.
- **Demo entry point** — optionally, the project route "Run demo" should open on.
3. Click **Publish to Hub**. A live per-stage progress bar runs (framing → packaging → signing → uploading), then the receipt shows exactly what shipped: asset count, bytes, content hash — *secrets redacted*.
> **Under the hood.** Behind **Publish**, the platform sanitizes the package — drops every document, vector, secret, and tenant id — signs it, hashes it, and registers it on the environment-independent Hub. It also stamps the package with the **platform version** of the ring it was built on, which is what the install-side preflight checks. Full mechanics: [Hubs & distribution](/academy/v4).
**Checkpoint.** Your **Invoice Processing** Solution appears under **Browse all solutions** on the same page, with a **Signed** pill and **v1.0** — no admin approval is needed to publish; governance kicks in at *install* and at *production promotion* (Stage 4).
### Stage 4 — Browse, preflight, and install
*(Project B · shipped)*
Now play the receiving team. For the Solution track the install creates the new project for you, so you can start from any context that can reach the Hub — the workspace's **Import from Hub** entry opens the same marketplace without a project.
1. Open `Studio ▸ Hubs ▸ Solutions`. The marketplace opens on a collapsible **Featured** rail, then a **split master–detail browser**: search or filter the list on the left, and select **Invoice Processing** to load its detail pane.
2. Read before you install: the **Overview** tab (summary + the dev → stg → prod promotion ladder), the **Setup guide** tab (your Stage 3 markdown), **Version history**, and **Samples**.
3. **Preflight.** In Overview, click **Check install compatibility**. You get: *signature ✓*, each **requirement** marked met or missing (the platform row is real — a Solution built on a newer ring fails preflight on an older one), and the **credentials preview**: "*you'll need to configure N credentials*", with counts and where (connection keys, script secrets) but never values. Missing rows are exactly your DECLARE dependencies — fix them *before* installing.
4. **Install.** Click **Install as new**, name the project (e.g. `Invoice Processing — Finance West`), and **Confirm & Import**. A live per-stage progress bar runs while the platform verifies the signature, unpacks the modules, and creates the project — Invoice collection schema, extractor agent, skills, guard rails, the Four-Eyes lifecycle, dashboards, all minted with fresh ids. No invoices come across; the new project starts empty of data. (Inside an existing project, **Install here** drops the modules into it instead.)
> **Governance on this path.** Some installs are **approval-required** — the result panel then offers a one-click **Approve & install**, keeping the gate with the platform, not the package. Shipping a Solution *up the ladder* is governed harder still: **Ship to stg** executes immediately, but **Request production release** queues for a superadmin's **Hub Release Approvals** — and the target hub is frozen at request time, so if the destination registry changes before approval, the approval is refused. Details: [Hubs & distribution](/academy/v4).
### Stage 5 — Wire the destination: credentials and REBIND slots
The install re-created your collections and modules, but the DECLARE dependencies still need *Project B's* capabilities — exactly what the Stage 4 credentials preview promised.
**On the Solution track (this build):** the **Configure imported credentials** dialog opens automatically after install. Bind Project B's **LLM model / key** (not yours — it never shipped) and fill the connection keys and script secrets the preview counted; you can start with demo values and add real ones later. Two extras land with the project: the **sample files + setup guide** appear in a **"Solution Samples"** File Drive folder (one click from the result panel), and **Run demo with sample data** pushes the shipped samples through the normal intake so you can watch the solution work before touching real data.
**On the agent-object track** (a single agent imported from the **Agents** registry), a configuration dialog opens instead — for each REBIND slot, pick a **local** object:
```
+- Import: Invoice Extractor -------------------------------[x]-+
| This needs you to map the following to your project: |
| |
| LLM Model * [ Select a model v ] |
| "any GPT-4-class chat model" <- the publisher's |
| note (DECLARE) |
| View * [ Select a view v ] |
| "the invoices view" (REBIND) |
| |
| Datasheet * [ Select a datasheet v ] |
| "invoice line-items table" (REBIND) |
| [ Import ] |
+----------------------------------------------------------------+
```
1. **LLM Model** (required) — pick **Project B's** GPT-4-class model. This is the DECLARE dependency resolving to a local capability: Project B's key, not yours.
2. **View** (required) — pick the invoices view in Project B (or the one the Solution just created). This is the REBIND slot binding the agent to *this* project's data.
3. **Datasheet** (required, if the agent referenced one) — pick Project B's. Each field shows the description you wrote at publish time, so you know exactly what to choose.
4. Click **Import**. The platform mints fresh ids for the embedded pieces and binds the slots to the local objects you picked.
**Checkpoint.** On the Solution track the result panel reads *"✓ Created project …"* with your samples materialized; on the agent track you get an *"…imported successfully"* toast. Either way, the installed agent appears in Project B's `Agent Builder ▸ Agents`.
### Stage 6 — Prove it: a plain project object that runs
*(Project B · shipped)*
The reassuring payoff: an installed object is just a normal project object. There is no special "imported" mode to learn.
1. In Project B, open `Studio ▸ Agent Builder ▸ Agents`. The **Invoice Extractor** is there like any agent you'd build by hand — open it; every reference resolved to *this* project's model, view, and datasheet, not Project A's.
2. Confirm the **Invoice** collection, its schema and labels, the Four-Eyes lifecycle, and the dashboards came across.
Then the real proof that structure travelled and the binding works — run a sample invoice end to end:
3. In Project B's **Consumer App**, open the **Invoice** collection (`App ▸ Documents`) — it's empty. Good: no data shipped.
4. Upload a single sample invoice PDF (reuse the test invoice from [Build: Invoice processing](/academy/uc-invoice)).
5. Watch the live progress chip: the *installed* Invoice Extractor, running on Project B's bound model, extracts the fields — total, vendor, dates — exactly as it did in Project A.
6. Follow the invoice through the Four-Eyes lifecycle (Intake → AI Processing → AI Recommendation → L1 Review → L2 Approval), reviewing and approving as before.
7. The invoice reaches **Approved** in Project B.
You moved a complete solution between projects without copying a single invoice. The recipe travelled; the data started fresh.
> **If extraction fails or the agent errors:** it's almost always an unresolved DECLARE — Project B doesn't have a matching LLM model, or you bound the wrong one. Re-open the agent and check the model picker (or re-open the credentials dialog). The Stage 4 compatibility check and credentials preview would have flagged this before install — run it again to see which row is missing. Empty pickers in the REBIND dialog usually mean the target object — a view, a datasheet — doesn't exist yet in Project B: create it first, then re-import.
## Make it production-worthy
- **Make Stage 1 a habit, not a one-off.** Before each re-publish: **Commit** a milestone, **Snapshot** (full) for safety, **Freeze** so the published recipe can't drift. To ship v1.1: unfreeze → edit → re-commit → re-snapshot → re-freeze → **Publish to Hub** again, choosing **Publish the next version**. Every project installed from the Hub then shows an *update available* banner: **upgrade in place** (keeps documents, queues and history; auto-saves a rollback snapshot) or install side-by-side — and the **⋯ ▸ Roll back** menu returns a project to any prior published version.
- **Ship a single agent when the team already has a project.** Sometimes the next team just wants the extractor agent, not a whole new app. In Project A, open the **Invoice Extractor** in `Studio ▸ Agent Builder ▸ Agents` and use its **⋮ ▸ Publish**: logo, **Name**, **Description**, **Tags**, plus the dependency description textareas (model = DECLARE; view/datasheet/collection = REBIND). **Publish** lands it in `Studio ▸ Hubs ▸ Agents`; in an existing Project B, open that tab, select it, **Import**, and resolve the REBIND slots as in Stage 5. The agent drops in as a plain agent — no new project created.
> **Coming soon / by design.** The per-object publish → import → REBIND flow above ships today. The fuller Object-Package design — signed single-object packages, an install wizard reporting schema-compatibility verdicts (exact / compatible / extendable / incompatible) per REBIND slot, upgrade-in-place vs install-as-copy, and a rollback ledger — is designed but not fully built. Use today's REBIND flow; don't expect the full wizard yet. For anything mission-critical, ship a whole Solution.
- **Govern both ends.** Freeze Project A's config before publishing, so the published recipe is the blessed one; ship across environments up the promotion ladder — **Ship to stg** is immediate, **Request production release** waits for a superadmin's approval, with the target hub frozen at request time ([Hubs & distribution](/academy/v4)). And set up **roles** in Project B *after* install — the Solution carries the lifecycle and stage gates' shape, but you assign **L1-Reviewer / L2-Approver** to the new team's actual people in `Studio ▸ Security` ([Access & roles](/academy/g1)). Roles are people-bindings: they don't, and shouldn't, ship.
What to keep from this build: structure travels, data doesn't — a package is a recipe, not a copy. Every dependency is EMBED (shipped by value), DECLARE (required at the destination, never shipped), or REBIND (wired at install); memorise which bucket each kind falls in and you can predict the whole publish-and-install experience. Commit, snapshot, freeze before you publish; assign roles in the destination after you install. The worked builds taught you to *build* solutions — this one taught you to *ship* any of them: package once, install everywhere, with nothing sensitive leaving the building.
## Where to go next
- [Hubs & distribution](/academy/v4) — the full publish / Hub / install / REBIND mechanics, dialogs, and maturity discussion.
- [Build: Invoice processing](/academy/uc-invoice) — the solution you just shipped, if you haven't built it yet.
- [The Agentic System pattern](/academy/sol-sys) — when what you're shipping is a whole domain brain, not one workflow.
---
## B4 · Build: Support intake triage
URL: https://www.botminds.ai/academy/uc-triage
> Botminds Academy — Solutions · Agentic Workflow
# Build: Support intake triage
> **In one line.** Inbound support items — emailed, uploaded, or typed — get classified by an agent, the lifecycle routes each by category, the clean confident ones auto-resolve, and the ambiguous or urgent ones queue in a human **Inbox**.
> **You'll build.** A triage pipeline: a Processing collection, a classification taxonomy (category, priority, sentiment), three intake paths, a **Triage Classifier** agent, and a routing lifecycle — about 60–75 minutes for the core build, plus 30 for the production upgrades.
> **You'll use.** [Core concepts](/academy/s2) · [Collections & schema](/academy/d1) · [Taxonomy, lifecycle, tags & events](/academy/d3) · [Ingestion & connectors](/academy/d4) · [Your first agent](/academy/a3) · [Dashboards & inbox](/academy/e5) · [Teams & mesh](/academy/a11)
This is the canonical *triage and routing* shape from [What is Botminds](/academy/s1): classify incoming items and send each to the right queue or person. Where [Build: Invoice settlement](/academy/uc-invoice) *decided on* each document, this one *sorts* each document — same building blocks, assembled for a different job. Having built the invoice pipeline first helps but isn't required. You need a project you can build in, at least one LLM registered ([LLMs & services](/academy/a2)), and enough Studio orientation to find your way around.
```
inbound support items "Support Intake" (Processing)
email (IMAP) ──┐ schema: Ticket Details (extract)
upload (one-shot) ──┼──► Triage (classify)
Input Form (typed)──┘ category: billing / technical /
account / urgent
priority · sentiment
worker: Triage Classifier fills the labels
lifecycle routes by category:
simple + confident ──► auto-resolve
ambiguous / urgent ──► Inbox (human opens
the wrapped ticket)
```
## Steps
### Stage 1 — Create the "Support Intake" Processing collection
A **Collection** is the typed home for one kind of record ([Collections & schema](/academy/d1)). Support tickets are records you *decide and sort*, not a corpus you read — so this is a **Processing** collection.
1. Go to `Studio ▸ Data Model ▸ Collections`. Click **+ Collection** (rail footer).
2. On the **General** tab: **Purpose:** leave/select **Processing**. **Collection Name:** `Support Intake`. **Description:** `Inbound support items to be classified and routed.` Optionally **Set as Primary** if this is the project's main intake target. Leave the other accordions at their defaults.
3. Click **Save**. `Support Intake` appears in the left rail.
> **Watch out — Category is permanent.** Processing vs Knowledge is chosen once, at create time, and shows as a read-only chip afterwards. Pick **Processing** deliberately.
> **Checkpoint.** Selecting `Support Intake` shows a tabbed detail pane (**General · Schema · Lifecycle · Tags · Events · Ingestion · Agents**). A new Processing collection is automatically seeded with the 8-stage Four-Eyes lifecycle — you reshape it for routing in Stage 5.
### Stage 2 — Build the classification taxonomy
A schema can do two jobs ([Taxonomy, lifecycle, tags & events](/academy/d3)): **extraction** (pull a *value* out — the customer's name) and **classification** (assign the item to a *category*). Triage is mostly classification, so you'll build classification **Learners**.
> **Vocabulary.** A **Learner** (a.k.a. *Taxonomy*) is the trainable extractor that owns a group of fields; a **Label** is one field (the UI shows it as a **Field**). A **classification label** is just a Label living under a *Classification*-type Learner — its name is a category the item can be sorted into. See the [Glossary](/academy/r0).
First, a few extraction fields so a human has context:
1. Select `Support Intake` → open the **Schema** tab → click **Taxonomy** (footer).
2. **Name:** `Ticket Details` · **Description:** `Who/what the ticket is about` · **Type:** `DocumentClassification` · **Entity:** `Support Intake`. **Submit.**
3. Select **Ticket Details**, click **+ Label**, and add (using **Add** between, **Add and exit** on the last): `customer_name` — *Description:* `The requester's name` (plain text); `subject` — *Description:* `The ticket's subject line or summary` (plain text); `account_id` — *Description:* `Any account/order reference mentioned` (plain text).
Then the **Triage** classification Learner — the heart of this build. It holds the three triage decisions: **category**, **priority**, **sentiment**.
4. Schema tab → **Taxonomy** (footer). **Name:** `Triage` · **Description:** `How to sort this ticket` · **Type:** **DocumentClassification** · **Entity:** `Support Intake`. **Submit.**
5. Select **Triage**, **+ Label**, and add these category labels — one per category the agent can assign. Enter each category as the **Label Name** with a one-line **Description**:
| Label Name | Description |
|---|---|
| `billing` | Invoices, charges, refunds, payment problems |
| `technical` | Bugs, errors, outages, "it doesn't work" |
| `account` | Login, profile, access, plan changes |
| `urgent` | Service down, data loss, anything time-critical |
6. Add two more single-select fields for **priority** and **sentiment**. For each, **+ Label**, open **Show Advanced Settings ▸ View Config**, and add a **validation rule listing the allowed values** — this is how a Label becomes a single-select; there is no "type" dropdown, the validation rule defines the shape ([Collections & schema](/academy/d1)):
- `priority` — allowed values `low`, `medium`, `high`.
- `sentiment` — allowed values `positive`, `neutral`, `negative`.
Keep classification Learners small and flat — one Learner per decision, a handful of labels each. It reads better later in the **Conditional** stage editor, where you'll branch on `category`.
> **Checkpoint.** The **Labels** tree under **Triage** shows your four category labels plus `priority` and `sentiment`. The schema drives extraction — the classifier agent will assign exactly the labels you defined here, and nothing you didn't.
### Stage 3 — Wire ingestion: three ways items arrive
Support items come from everywhere, so capture them three ways ([Ingestion & connectors](/academy/d4)). Open `Studio ▸ Connector ▸ Ingestion`.
> **Flag-gated.** This teaches the modern **Sources v3** screen. If you land on the legacy wizard, enable the `ingestionV3` lab flag first ([Getting oriented](/academy/e1)).
Email — the main inflow:
1. **+ Connector** → pick **Email (IMAP)**. Fill the mailbox credentials and run the live test — Email connectors can't save until the test passes. **Save connector.**
2. **+ Job** → Step 1: pick the Email connector. Step 2: **Job name** `Support mailbox`, **Folder** `INBOX`, tick **Include attachments**, **Target collection** `Support Intake`. Step 3: **Recurring → every 15 Minutes** (or a cron). Check the **Next 5 runs** preview → **Create job**.
Upload — ad-hoc and smoke tests:
3. The **Upload** toolbar button takes a one-shot batch — no connector or job needed. Drag in files, set **Target collection = Support Intake**, **Submit**. Use this to smoke-test your schema before you trust the recurring email job.
Input Form — direct typed capture. Sometimes there's no document: an agent on the phone needs to *type* a ticket. The **Input Form** builder defines a template that creates records directly:
4. Go to `Studio ▸ Connector ▸ Input Form` → **+ Add Form** → **Type: Create Source**. Name it `Log a ticket`.
5. Add **Columns** mapped to your taxonomy fields — e.g. a `subject` text column (mark **Is Title**), a `customer_name` text column, and a multiline `body` column. Each column's **Label** maps to a taxonomy field.
6. **Create.** Submissions now land in `Support Intake` as records, ready to be classified.
> **Checkpoint.** Drop 3–5 sample tickets via **Upload**. Each appears in the document list with a **"Processing…"** chip and fills in. The chip stalls at 0% only if the background worker isn't running — see [Ingestion & connectors](/academy/d4).
### Stage 4 — Build the "Triage Classifier" agent
The agent reads each item and fills in the **Triage** labels. Build it in `Studio ▸ Agent Builder ▸ Agents` ([Your first agent](/academy/a3)).
1. **+ Agent ▸ Agent** to open the editor.
2. **Persona tab.** **Name:** `Triage Classifier`. **Description:** `Classifies inbound support tickets by category, priority and sentiment.` For **Instructions**, click the **co-pilot**, seed it with *"Classify a support ticket into a category, a priority and a sentiment,"* then edit the draft to read roughly:
```
You are a support-triage assistant. For each inbound ticket, read the
subject and body and decide: the category (exactly one of billing,
technical, account, urgent), the priority (low/medium/high), and the
sentiment (positive/neutral/negative). Treat anything reporting an outage,
data loss, or a security issue as urgent with high priority. If the ticket
is genuinely ambiguous, prefer a lower confidence over guessing.
```
3. **Model tab.** Pick your project's **LLM Model**. Classification is well-bounded, high-volume work, so **Agent Mode = Fast** is the production setting — but set **Thinking** for now so you can watch its reasoning while testing. Keep Temperature low (**Advanced sampling**).
4. **Output tab.** Turn on **Structured output**. Choose the **Triage** Taxonomy/Learner, set **Process unit = Page**, add the **Labels** `category`, `priority`, `sentiment` with a short **Description** each, and turn on **Confidence Score** and **References**. The per-field confidence you turn on here is what routes a ticket to a human later — low confidence on `category` is the platform's signal that a person should look.
5. **Save Agent.**
6. Test in the **Playground** (right pane). Set **Input Type = Document**, pick one of your sample tickets, **Send**. Watch it stream the category/priority/sentiment with a confidence each. Feed it an ambiguous ticket and confirm the confidence drops. Flip **Agent Mode = Fast** and re-run — same answer, quicker. That's production.
7. Assign it to the collection. Open `Support Intake ▸ Agents` tab and **assign `Triage Classifier`** as the intake agent. From now on every item that lands — emailed, uploaded, or typed — runs through it automatically.
> **Checkpoint.** Upload a fresh ticket and watch the document fill in with `category`, `priority`, and `sentiment` plus a confidence on each.
### Stage 5 — Route by category: auto-resolve the easy, Inbox the hard
This is where classification becomes *routing*. A **Lifecycle** is the ordered stages a document moves through ([Taxonomy, lifecycle, tags & events](/academy/d3)) — not an XFlow. You'll use three lifecycle mechanisms: a **Conditional** automation to branch by `category`, the **Send to Inbox** flag (`IncludeManualIntervention`) to hand the hard ones to a human, and the **Auto-Decide policy** to resolve clean, confident ones without a human. Open `Support Intake ▸ Lifecycle` — the seeded **Four-Eyes** flow is already there.
Branch by category:
1. Click the **AI Recommendation** stage to open the **State editor**.
2. Set **Automation Type = Conditional**. In the **Conditional Stages** list, **+ Add Conditional Stage** one row per route — each row is a *label condition → target stage*:
- `category = urgent` → **L1 Review** (you'll send that stage to the Inbox, below).
- `category = billing` → a **Billing Review** stage. Add it with the **State (+)** button in the stage graph if you want a dedicated queue, or route to L1 Review to start. Note: **+ Lifecycle** creates a whole new stateflow — to add a *stage*, use the State button.
- `category = technical` → a **Tech Review** stage (same idea).
- `category = account` → straight toward **Approved** if your account changes are safe to auto-handle, or to a review stage if not.
Start simple: route *everything* to one **L1 Review** stage first, prove the Inbox hand-off works end to end, *then* split out Billing/Tech queues. Don't build five branches before you've seen one work.
Send the hard ones to the Inbox:
3. Open the review stage(s) you route to (e.g. **L1 Review**). In the State editor, turn on **Send to Inbox (human review)** — this is the `IncludeManualIntervention` flag that makes a stage a *review* stage. When a ticket reaches it, the server creates an **InboxNote** that *wraps* the source ticket, remembering its collection, doc id, and stage.
4. Optionally gate the stage with **Can be viewed by** to the role that should handle it (e.g. `L1-Reviewer`) — roles are covered in [Access & roles](/academy/g1).
> **The one point not to miss — you act on the wrapped document, not in the Inbox.** The **Inbox** ([Dashboards & inbox](/academy/e5)) is read + snooze + dismiss only. There is no approve/reject/edit button inside it. Each row is a *pointer*; you click **Open**, which takes you to the wrapped ticket, and you act there using the document's normal lifecycle UI. Advancing the ticket past its human stage resolves the Inbox note automatically. The Inbox is a worklist, not a workspace.
Auto-resolve the clean, confident ones:
5. Below the stage graph, open the **Auto-Decide policy** card. Set **Enabled = true** and **Applies To = approve** — auto-resolve clean cases; always keep human eyes on the rest.
6. Leave **Min Confidence** at its default `0.92` and **Require Zero Flags = true**. The preview reads roughly *"Auto-approve when AI confidence ≥ 0.92 AND zero flags."* Now a ticket the classifier is confident about — and that isn't `urgent` — can resolve without a human; everything ambiguous, flagged, or urgent still routes to the Inbox.
> **Under the hood.** Auto-decide never spoofs a user — an auto-resolved ticket's audit row shows actor `AI/auto` plus the confidence. Every stage move is written to the audit trail; the "decision" *is* that trail.
> **Checkpoint.** Validate the lifecycle: exactly one Start, one End, a Start→End path, no dangling cycles. If it complains, fix the graph before saving.
### Stage 6 — Test the whole loop
Drop in a spread of sample tickets and watch them classify and route.
1. **Seed varied tickets** via **Upload** (Stage 3): a clean billing question ("Why was I charged twice?"), a technical bug ("App crashes on export"), a routine account change ("Please update my email"), and a genuine emergency ("Production is DOWN, losing data"). Add one deliberately vague one ("It's broken, help").
2. **Watch classification.** Each ticket fills in `category` / `priority` / `sentiment` with a confidence. Confirm the emergency reads `urgent` / `high` and the vague one comes back with a low confidence.
3. **Watch routing.** The clean, confident, non-urgent tickets auto-resolve (Auto-Decide) — check their stage history shows actor `AI/auto`. The urgent and low-confidence ones route to the review stage and appear in the **Inbox** (`App ▸ Inbox`), grouped under **Needs Review** (or **To Triage**).
4. **Act on one — the right way.** In the **Inbox**, find an item, read its provenance line (`wraps ▸ Support Intake · · `), then click **Open**. Notice you leave the Inbox entirely and land on the document detail page — *that* is where you correct the category or advance the ticket. Advance it; return to the Inbox and confirm the note self-resolved.
5. **Try the Input Form.** Submit a ticket through your `Log a ticket` form and confirm it gets classified and routed exactly like an emailed one.
You're done when an emailed, uploaded, or typed ticket is classified, the easy ones vanish via auto-resolve, and the hard ones queue in the Inbox where a human opens the *wrapped* ticket to act.
## Make it production-worthy
Three upgrades, each a real surface from the chapters.
**A route-mode multi-agent team of specialists.** So far one agent does all the classifying. For richer handling, make the leader **route** each ticket to a specialist sub-agent ([Teams & mesh](/academy/a11)). A **route-mode** team has the leader pick the single member best suited to the request and hand off — exactly the triage shape.
1. Build two specialist agents the normal way (Stage 4): a **Billing Specialist** (instructions tuned for refunds/charges) and a **Tech Specialist** (tuned for bugs/outages).
2. Open your **Triage Classifier** agent → **Subagents** tab. Set **Coordination mode = route**.
3. **+ Add subagent** twice: add **Billing Specialist** and **Tech Specialist**, each with a short **Prefix** telling it how to behave inside the team.
4. **Save Agent.** The leader now classifies *and* routes each ticket to the one specialist that fits. A team runs in-process as one agent run; it does not survive a restart, and every member must be an agent. If you needed durable, long-running, or cross-runnable routing you'd reach for a **Mesh** instead — but a route-mode team is the right, simpler tool here. You can also require human approval before the leader hands a ticket to a specific member — set it on **Governance ▸ Approvals ▸ Team agents**.
**An SLA webhook.** Tell your systems when a ticket breaches its SLA, using an **Event** ([Taxonomy, lifecycle, tags & events](/academy/d3)). On `Support Intake ▸ Events`:
1. **+ Event** → **Name** `Urgent SLA breach`. Choose the **stage-change** trigger, scope **Workflow** to your lifecycle and **Stage** to the urgent review stage.
2. **+ Add Action** → Notification Type **Webhook** → your endpoint (or a Slack action to ping the on-call channel).
3. **Show Advanced Settings** → tick **Check SLA Breach** and set **SLA Time (sec)** — now the event fires when an urgent ticket sits unattended too long.
**A triage dashboard.** Give the team a bird's-eye view — consumers read it ([Dashboards & inbox](/academy/e5)); you build it in `Studio ▸ Intelligence` ([Shaping the experience](/academy/e7)). Widgets worth having:
- **Volume by category** — a bar or donut chart over the `category` label.
- **% auto-resolved** — a stat tile (auto-decided count ÷ total).
- **Queue depth** — a status breakdown of how many tickets sit in each review stage, plus an overdue count mirroring the Inbox's overdue chip.
Consumers read these on `App ▸ Overview`; you configure them in Studio.
This *classify → route → auto-resolve-or-Inbox* shape is reusable for any intake-and-sort problem: lead routing, document-type sorting, claims triage, content moderation queues. Swap the categories, keep the skeleton.
## Where to go next
- [Taxonomy, lifecycle, tags & events](/academy/d3) — the Conditional automation and Auto-Decide in full.
- [Teams & mesh](/academy/a11) — route mode, and when to graduate to a Mesh.
- [Build: Contract review](/academy/uc-contract) — the next end-to-end build.
---
## B7 · Build: Loan underwriting
URL: https://www.botminds.ai/academy/uc-underwriting
> Botminds Academy — Solutions · Agentic Workflow
# Build: Loan underwriting
> **In one line.** A borrower's application package — one fat PDF bundling the application form, financial statements, tax returns, bank statements, a collateral valuation — gets classified document by document, extracted per type, validated within and across documents, screened against sanctions and fraud, and the clean files sail straight through while the exceptions queue for an underwriter.
> **You'll build.** A multi-document Processing pipeline: a **Loan Underwriting** collection, one classify-then-extract agent (upgradeable to a five-member Mesh), validation rules plus a sanctions/fraud guard rail, a 0.99-confidence straight-through-processing gate, an output-package export, and an underwriting dashboard.
> **You'll use.** [Collections & schema (D1)](/academy/d1) · [Lifecycle, tags & events (D3)](/academy/d3) · [Ingestion (D4)](/academy/d4) · [Your first agent (A3)](/academy/a3) · [Teams & mesh (A11)](/academy/a11) · [Guard rails (A8)](/academy/a8) · [Dashboards & views (E7)](/academy/e7)
This is [B3's invoice loop](/academy/uc-invoice) scaled up: instead of *decide on each document*, you decide on each **application package made of many documents**. A classifier works out what each document is, an extractor pulls the fields that type owns, rules reconcile the numbers across documents, and the lifecycle auto-advances anything clean and confident. Budget about 75 minutes for the single-agent happy path; two hours with the Mesh upgrade and the dashboard.
> **Watch out — build this in a fresh project.** Underwriting taxonomies are big: one classification field plus dozens of extraction fields. On a production loan-origination build, adding ~12 labels under a new Learner in an already-busy project surfaced only 3 of them — label names collided with Labels under other Learners. In a fresh project the same bulk-add surfaces reliably. Create a clean project named `Loan Underwriting` before Stage 1. If a Label ever fails to appear in the tree after **Add**, you are in a busy project — move.
## Steps
### Stage 1 — Collection and schema
**Create the collection.** In your fresh project: `Studio ▸ Data Model ▸ Collections` → **+ Collection** (rail footer).
1. **Purpose:** **Processing** (the default). Application packages move through a decision.
2. **Collection Name:** `Loan Underwriting`
3. **Description:** `Borrower application packages for classification, extraction, validation and credit decision`
4. Leave every other accordion at its default. Click **Save**.
> **Flag-gated.** The explicit Processing/Knowledge switch sits behind the `knowledgeCollections` flag — if you don't see a switch, new collections are Processing anyway. Purpose is **immutable after create**, so pick deliberately.
> **Checkpoint.** **Loan Underwriting** appears in the left rail with the tab strip **General · Schema · Lifecycle · Tags · Events · Ingestion · Agents**. The **Lifecycle** tab is already seeded with the 8-stage Four-Eyes flow — you tune it in Stage 6.
**Create the Learner.** Open the **Schema** tab → footer **Taxonomy**:
1. **Taxonomy Name:** `Application Package`
2. **Description:** `Document type + loan-level and per-document fields`
3. **Type:** `DocumentClassification` (whole-document classification + field extraction)
4. **Entity:** `Loan Underwriting` (pre-filled). Click **Submit**.
**Add the classification field first.** Select **Application Package**, then **+ Label**. This field holds *what kind of document this is*:
| Label Name | Description | Type |
|---|---|---|
| `doc_type` | `Which document this is: application form, financial statement, tax return, bank statement, collateral valuation, KYC document` | Plain text — the classifier writes one of these values into it |
**Add the loan-level and per-document fields.** **+ Label** for each (**Add** between, **Add and exit** on the last). A field's type comes from a **validation rule** under **View Config** plus **Record Config** — there is no single "type" dropdown ([D1](/academy/d1)):
| Label Name | Description | Type |
|---|---|---|
| `borrower` | `Borrower's legal name` | Plain text |
| `loan_amount` | `Requested loan amount` | **View Config** → **numeric** rule; tick **Enable Total Field** |
| `dscr` | `Debt-service coverage ratio (computed)` | **View Config** → **numeric** |
| `ltv` | `Loan-to-value ratio (computed)` | **View Config** → **numeric** |
| `revenue` | `Total revenue from the financial statement` | **View Config** → **numeric** |
| `net_income` | `Net income from the tax return` | **View Config** → **numeric** |
| `stmt_balance` | `Ending balance on the bank statement` | **View Config** → **numeric** |
| `collateral_value` | `Appraised value of the pledged collateral` | **View Config** → **numeric** |
Every validation option is catalogued in the [Schema field reference (R3)](/academy/r3).
> **Under the hood.** A production underwriting taxonomy easily carries ~30 Labels across classification, document-intelligence and data-transform groups. You are building a teaching subset; the shape — one classification field, many extraction fields, confidence on each — is identical. Add the rest under *Make it production-worthy*.
> **Roadmap, not a click-path.** Taxonomy governance — field-dictionary versioning, a Reviewer-to-Owner approval workflow, sensitivity tiers — is designed but not a shipped configurator surface yet. Don't promise it.
### Stage 2 — Ingestion
**Clicks.** `Studio ▸ Connector ▸ Ingestion`.
> **Flag-gated.** This teaches the modern Sources v3 screen (the `ingestionV3` lab flag). If you land on the older single-source wizard, enable `ingestionV3` from the Lab menu ([E1](/academy/e1)). Full detail: [Ingestion & connectors (D4)](/academy/d4).
**The fast path (one-shot, for testing now).** Click **Upload** (toolbar) → drag in a sample application-package PDF → set **Target collection = Loan Underwriting** → **Submit**.
**The recurring path (for production).** A connector must exist before a job can use it:
1. **+ Connector** → pick **Botminds Drive** (this project's internal drive — no credentials). Name it → **Test connection** → **Save connector**.
2. **+ Job** → **Step 1:** select that Drive connector. **Step 2:** **Job name** `Application packages intake`; **Browse…** to the packages folder; **Extensions** `pdf`; tick **Recursive**; **Target collection** `Loan Underwriting`. **Step 3:** **Recurring → every 1 Hours** (check the **Next 5 runs** preview) → **Create job**.
> **Under the hood — preprocessing.** An application package is usually many documents in one PDF. The platform splits the package into per-document units (each gets a UUID and content hash) and deskews pages before the classifier sees them. You don't configure this per job. A package arriving as a folder of separate PDFs works too — each file is its own unit.
> **Checkpoint.** The **Jobs** tab shows `Application packages intake … active`. Click **Run now**, then the **Runs** tab — the funnel counters (`Enum → Fetch → New → … → Disp`) fill, and clicking the run opens **Run detail** with a per-file log.
### Stage 3 — The classifier + extractor agent
One agent that, per document, decides its **type** and fills the fields that type owns. Start with a single structured-output agent; Stage 4 shows when to split it.
**Clicks.** `Studio ▸ Agent Builder ▸ Agents` → footer **+ Agent ▸ Agent** ([A3](/academy/a3)).
1. **Persona:** **Name** `Underwriting Document Processor`; **Description** `Classifies each application document and extracts its fields`. Use the **co-pilot** on **Instructions**, seed it with *"Classify a loan-application document and extract its fields,"* then refine to roughly:
> You process documents from a borrower's loan application package. First decide the document type — one of: application form, financial statement, tax return, bank statement, collateral valuation, KYC document — and write it to `doc_type`. Then extract only the fields that document supports (e.g. revenue from a financial statement, net income from a tax return, ending balance from a bank statement, appraised value from a collateral valuation). Never invent a value the document doesn't show; leave it blank instead.
2. **Model:** pick your project's **LLM Model**. Set **Agent Mode = Thinking** while you tune.
3. **Output:** turn on **Structured output**. Pick the **Taxonomy/Learner** `Application Package`, set **Process unit = Page**, confirm each **Label** carries a short **Description**, and turn on **Confidence Score** and **References**. Per-field confidence is what routes a package to an underwriter later.
4. Click **Save Agent** — there is no autosave.
**Test in the Playground before wiring it up.** In the right pane: **Input Type = Document**, pick a sample application document, press **Enter**. Watch `doc_type` resolve and the right fields stream in with confidence and page references. Flip **Agent Mode = Fast** and re-run — same result, quicker; that is your production setting.
**Assign it as the collection's Worker.** `Studio ▸ Data Model ▸ Collections ▸ Loan Underwriting` → **Agents** tab → **Assign** `Underwriting Document Processor` as the intake/processing agent. Every document that lands is now run by it automatically (a *Worker* is not a *Reader* — [D1](/academy/d1)).
> **Honesty callout — live LLM agents on a local stack.** On a production build we hit real platform bugs running a live agent end to end: the bound model didn't always stick at run time, the fallback model wasn't deployed on the local key, and a document-attached run could throw inside the document runner. If your Playground works but the assigned Worker stalls at 0% on a real document, confirm the agent is bound to a **deployed** model — one your key actually serves — not a default that maps to an undeployed name. See [LLMs & services (A2)](/academy/a2).
### Stage 4 — Optional upgrade: the five-member Mesh
Decompose the single agent into a durable, multi-stage pipeline so each stage is tuned and tested on its own, survives a restart, and can fan out parallel checks. Optional — the Stage-3 agent already works; reach for a Mesh only when the automation is **long, branching, must survive restarts**, or has steps over **240 seconds** (OCR on a 200-page valuation report, a slow partner screening API). Full decision guide: [Teams & mesh (A11)](/academy/a11).
**Clicks.** `Studio ▸ Agent Builder ▸ Agents` → **+ Agent ▸ Mesh** (always available — not flag-gated). This opens the XFlow designer in mesh mode; the palette is **XFlow Operator + Queue + Service**.
The shape to draw — five members wired by queues:
```
package ─► classify ─► q.a ─► validate ──┬─► enrich ───────┐
(XFlow) (XFlow) │ (XFlow) ├─► approve ─► summarize
└─► screen ───────┘ (agent) (sink)
(sanctions/fraud
Service, parks)
```
- **classify**, **validate**, **enrich** are **XFlow Operator** nodes, each referencing a runnable.
- **screen** is a **Service** node — it parks (`awaiting`) while an external screening worker does the slow check and reports back. This is the platform's answer to the 240-second member ceiling ([A2](/academy/a2)).
- **approve** is an agent member that writes the decision; **summarize** is the sink that writes the Summary / output package.
- A **Queue** box sits between members; node→queue publishes the baton, queue→node subscribes. Two members on one queue = fan-out (validate feeds enrich and screen in parallel); one member with two incoming queues = fan-in (**approve** waits for both).
Click **Save Mesh**. **MeshId is global, not per-project** — pick a unique id like `loan-underwriting-uw`. Watch a run on the **Runs** tab: a member timeline with per-member states (`done` / `running` / `awaiting service`), a queue-health banner, and a **Baton trail** of pub/sub hops. The `awaiting service` dot on the screen step means it is parked on your worker — not stuck.
Assign the Mesh as the collection's Worker exactly as in Stage 3 — intake routes by kind (mesh → agent → xflow).
> **Under the hood — the run ledger.** Each mesh run is recorded as a durable trace: per-segment timestamps, baton hops, member states. On a production lending build this was the immutable audit fabric. You don't build the ledger; running the mesh produces it.
> **Tip.** Don't reach for a Mesh too early. If the single agent processes a package correctly and you don't need durability, parallel screening, or a >240 s step, ship the single agent.
### Stage 5 — Validation and the sanctions/fraud guard rail
**Within- and cross-document validation.**
- **Within-doc:** the numeric rules on `loan_amount`, `dscr`, `ltv` (Stage 1's **View Config**) reject garbage — negative, non-numeric. Set on the Label, enforced on every document.
- **Cross-doc:** the reconciliation checks — does `net_income` from the tax return agree with the financial statement's story? does `collateral_value` support the `ltv` against `loan_amount`? does `dscr` hold given `net_income` and the requested `loan_amount`? Express these as a **Conditional** automation on the **Validate** stage of the lifecycle, or as the **validate** member's own logic in the Mesh. Detail: [D3](/academy/d3).
**The sanctions/fraud screen as a guard rail.** A guard rail is a named policy object attached to the agent ([A8](/academy/a8)). `Studio ▸ Agent Builder ▸ Guard Rails` → **+ Guard Rail**:
1. **Name:** `Sanctions & fraud screen`
2. **Description:** `Flag any borrower name on a sanctions/PEP watchlist and flag anomaly patterns`
3. **Instruction:** *"If the borrower's name matches a sanctions or PEP watchlist, or the document shows tampering / inconsistent fonts / altered numbers, set a fraud flag and never auto-approve — route to human review."*
4. **Save.** Then attach it: edit `Underwriting Document Processor` (or the Mesh's **approve** agent) → **Governance** tab → **Guard rails ▸ + Add** → pick `Sanctions & fraud screen` → **Save Agent**.
> **Honesty callout — a real sanctions screen is an external service.** A genuine watchlist check calls a live screening API and can be slow — exactly why Stage 4 modelled it as a **Service** that parks, not inline agent reasoning. The guard rail sets the *policy* (flag, never auto-approve); the *lookup* belongs in a Service or Tool against your real list. The LLM does not "know" the watchlist.
> **Checkpoint.** The agent's **Governance** tab shows the `Sanctions & fraud screen` shield chip; validation rules show on the relevant Labels' **View Config**.
### Stage 6 — The lifecycle gate: STP by default, HITL by exception
**Clicks.** `Studio ▸ Data Model ▸ Collections ▸ Loan Underwriting` → **Lifecycle** tab. The 8-stage Four-Eyes flow is already seeded; you add one Auto-Decide rule and confirm routing ([D3](/academy/d3)).
1. Below the stage graph, open the **Auto-Decide policy** card:
- **Enabled = true**
- **Applies To = approve** — auto-advance only; keep human eyes on declines.
- **Min Confidence = 0.99** — the production straight-through gate.
- **Require Zero Flags = true** — any sanctions/fraud flag from Stage 5 forces a human.
- Optional: a **Max Amount** so only loans under a threshold auto-advance. Note the evaluator compares the agent's self-reported `_meta.amount`, not a schema field by name — the cap only fires if the Worker surfaces the loan amount in its `_meta`.
- **Save.** The preview reads roughly *"Auto-advance when AI confidence ≥ 0.99 AND zero flags."*
2. Click the **L1 Review** stage → confirm **Send to Inbox (human review)** is on (`IncludeManualIntervention`); same for **L2 Approval**. Seeded on — you are verifying, not adding.
> **Watch out.** Don't use **Reset to default** on a lifecycle with live documents — it is destructive.
> **Under the hood — the audit trail is the decision.** There is no separate "decision" object. The stage-move history — who advanced it, at what confidence, with what flags — is the record; an automatic advance is stamped by the auto-decide actor, a human one by name ([G5](/academy/g5)). On the Mesh path, the run ledger from Stage 4 is the inference-level companion.
### Stage 7 — Review, decide, export
**What an underwriter does.** A package that doesn't auto-advance enters **L1 Review** and an **Inbox** item wraps it:
1. **Consumer app ▸ Inbox** (route `inbox`). Each card shows the borrower, a provenance line (`wraps ▸ Loan Underwriting · doc-… · L1 Review`), age, and why it is here — low confidence, missing document, sanctions flag. The Inbox doesn't act — read, snooze, dismiss only ([E5](/academy/e5)).
2. Click **Open** → **Document Detail** (`//:docId`) — the document on one side, extracted fields on the other ([E3](/academy/e3)).
3. Read the flagged low-confidence fields first. Click a value — say **DSCR : 1.08** — and the viewer scrolls to and highlights the source segment it was read from. That is how you catch a mis-read or a cross-doc mismatch.
4. **Correct** a wrong value in place (the edit becomes a teaching signal — [A9](/academy/a9)); **Rescore** if `dscr`/`ltv` need recomputing.
5. **Advance** from the workflow action pane: approve → **L2 Approval** (second eye) → **Approved**. Every move writes the audit trail.
**Export the output package.** `Studio ▸ Connector ▸ Output` → **+ Export** ([D4](/academy/d4)):
1. **Name:** `Underwriting output package`
2. **Export Type:** a structured (split/bookmark) type, so the package ships as data plus provenance. A production build delivers a canonical JSON output package to the bank's loan-origination API.
3. **Destination:** **Azure Blob**, **Botminds Drive**, or a **Webhook** to your loan-origination endpoint.
4. Toggle **Export input document** to ship the original package alongside the data. **Save**.
**Fire it on decision.** `Loan Underwriting ▸ Events` tab → **+ Event** → trigger **stage change**, **Workflow** `Four-Eyes`, **Stage** `Approved`, **+ Add Action → Webhook** to your endpoint ([D3](/academy/d3)).
### Stage 8 — The underwriting dashboard
**Clicks.** `Studio ▸ Intelligence` → select or create a dashboard → add widgets ([E7](/academy/e7)). Building a widget is: add → pick template → optional chart type → point at data → save. Four tiles:
- **Packages** — a **Documents Count** widget (total ingested this period).
- **STP rate** — a ratio: auto-advanced (auto-decide actor in the audit trail) ÷ total.
- **Pending** — a **Documents Count** filtered to **L1 Review** + **L2 Approval**.
- **Exceptions / watchlist hits** — a count filtered to documents carrying a review flag or the `Watchlist Hit` / `Fraud Flag` **Tag** (add these on the **Tags** tab first).
> **Tip.** Not sure which template fits? Use the **Agentic Widget** — describe the tile in plain language ("STP rate this month") and let AI build it.
> **Checkpoint.** **Open live dashboard** jumps to `/_dashboard?did=` — the exact view your credit-ops users get. The Dashboard tab is hidden from the `client` role and under the `DisableDashBoard` flag.
### Stage 9 — Test it end to end
About fifteen minutes:
1. **Upload.** `Studio ▸ Connector ▸ Ingestion` → **Upload** → one clean application-package PDF and one messy one → **Target collection = Loan Underwriting** → **Submit**. The result panel reports *"N of M registered."*
2. **Watch it process.** The document list shows a **Processing…** chip climbing to 100% as the Worker classifies each document and fills the fields. Stuck at 0%? The background worker isn't running, or the agent is bound to an undeployed model — see the Stage 3 callout.
3. **See classification + extraction.** Open a document; `doc_type` resolved per document, the right per-type fields filled with confidence and page references.
4. **See routing.** The clean package auto-advances (stamped by the auto-decide actor); the messy or flagged one lands in the **Inbox** under **Needs Review**.
5. **Review it.** Open the Inbox item → **Open** → verify a flagged field against its highlighted source, correct one value, **Rescore** if DSCR/LTV shift, approve through **L2 Approval** → **Approved**. The Inbox item disappears.
6. **See it exported.** The **Approved** package triggered your `Underwriting output package` export.
7. **Read the dashboard.** Packages ticks up, STP rate reflects the auto-advanced file, Pending and Exceptions reflect the rest.
All seven and you have a working, audited loan-underwriting pipeline — built by configuration.
## Make it production-worthy
1. **More document types and fields.** Add the remaining per-doc fields (credit score, guarantor details, employment- or business-verification dates) as Labels on `Application Package` *and* matching Labels on the agent's **Output** tab, then **Rescore**. Schema and agent must agree or the field stays empty.
2. **Exception tags and a reviewer View.** On the **Tags** tab add `Watchlist Hit`, `Fraud Flag`, `Missing Document`, `Income Mismatch`; then define an **Exceptions** View (columns: Borrower, Loan Amount, DSCR, Flag, Status), **Type = Project**, **Allowed roles = Reviewer** ([E7](/academy/e7)).
3. **Cost telemetry.** A production build tracks cost per application / document / stage / field with a spike alert. Surface compute-cost analytics on the dashboard.
4. **A second model.** Build a second extraction agent on a different LLM and swap it in — the agent's **Model** tab is a single swap point, which is the proof against model lock-in ([A2](/academy/a2)).
5. **Graduate to the Mesh.** When you need the sanctions screen parked as a Service or credit and fraud checks fanned out in parallel, move from the Stage-3 agent to the Stage-4 Mesh.
## Where to go next
- The same loop in its smallest form: [B3 · Invoice settlement](/academy/uc-invoice).
- Mesh, teams, and when each earns its keep: [Teams & mesh (A11)](/academy/a11).
- Scale from one workflow to a governed domain: [B9 · Capstone: Lending domain brain](/academy/uc-lending).
---
## V1 · Runtime API
URL: https://www.botminds.ai/academy/v1
> Botminds Academy — Developer
# Runtime API
> **In one line.** Drive a delivered solution from your own systems over REST: authenticate with an API key, submit document packages, read structured results, findings, audit trails and metrics — everything under `api/runtime/v1`.
> **You'll be able to.** Create and manage keys, submit a package or trigger a job, poll it to completion, and consume its output without a human touching the UI.
## What it is for
The consumer surface is for people; the Runtime API is for machines. Loan origination systems submitting document packages, ERPs pulling settled invoice fields, portals embedding decision status — anything that treats a Botminds solution as a service calls this API.
It is deliberately a *runtime* API: it operates a solution that already exists. Building and changing solutions stays in Studio, where governance can see it.
## Keys and authentication
Keys are managed per project by an admin, and every key is scoped to that project's data — a key cannot read across projects.
- Create, rotate and revoke keys via the admin surface (or `api/projects/{finonId}/api-keys` if you automate key management itself).
- The full secret is shown **once** at creation; store it in your secret manager. What remains visible afterwards is the key's **prefix**, for identification.
- Send the key on every call in the `X-API-Key` header.
```
curl -H "X-API-Key: " https:///api/runtime/v1/docsets//status
```
Rotate keys on your normal credential schedule; rotation issues a new secret while the old one stops working, so plan a cutover window.
## The surface, by resource
| Resource | You can | Typical call |
|---|---|---|
| **Jobs & runs** | Trigger a one-off run of a configured job (async: `202` + `runId`); poll the run to a terminal state | `POST /jobs/{jobId}/runs`, `GET /runs/{runId}` |
| **Doc sets** — `api/runtime/v1/docsets` | Submit N documents as one package (inline base64, URLs, or a pre-uploaded `folderPath` for high volume); append documents; track status; reprocess | `POST /docsets`, `GET /docsets/{id}/status`, `POST /docsets/{id}/reprocess` |
| **Trailing documents** | Submit a late-arriving document — matched to its package by `loanNumber`, else held **UNMATCHED** for manual association | `POST /documents/trailing` |
| **Output** — under `docsets` | Pull the assembled decision package | `GET /docsets/{id}/output`, `GET /docsets/{id}/output/status` |
| **Documents** — `api/runtime/v1/documents` | Read classification, extracted fields, per-field history, validation findings, split/merge **lineage**, and the full actor-attributed **audit** timeline | `GET /documents/{docId}/fields`, `GET /documents/{docId}/audit` |
| **Sign-off** — under `docsets` | Read a package's attestation state and history — including a `stale` flag when output changed after sign-off | `GET /docsets/{id}/sign-off` |
| **Stacking** — under `docsets` | Read the effective document order; apply a stacking template | `GET /docsets/{id}/stacking`, `POST /docsets/{id}/stacking/apply` |
| **Findings** — under `docsets` | Generate and read the findings summary for audit and delivery | `POST /docsets/{id}/findings/generate`, `GET /docsets/{id}/findings` |
| **Snapshots** — under `docsets` | Capture a package's state now; list generations; retrieve a stored snapshot verbatim | `POST /docsets/{id}/snapshots`, `GET /docsets/{id}/snapshots/{gen}` |
| **Reviews** — `api/runtime/v1/reviews` | See the human-review queue and its event log; read who's assigned to a package | `GET /reviews/queue?status=open`, `GET /docsets/{id}/assignment` |
| **Metrics** — `api/runtime/v1/metrics` | Cost per day/model, straight-through-processing rate, QC fail rate, extraction quality, error distribution, drift | `GET /metrics/cost?from=&to=` |
| **Compliance** | The tenant's AI/OCR/LLM subprocessor register; the LLM invocation log (model, tokens, prompt *shape* — never prompt text) | `GET /providers`, `GET /prompt-log` |
## The canonical integration loop
1. **Submit** — your system posts a document package (`POST /docsets`) or triggers a job.
2. **Poll** — watch the doc set's `status` (or the run) until it reaches a terminal state.
3. **Read** — pull extracted fields, classification, findings, or the assembled output.
4. **Attest** — when a human signs off in the platform, read the attestation back (`GET /docsets/{id}/sign-off`) so your system of record stays aligned; its `stale` flag tells you if the output changed after the sign-off.
The surface is deliberately read-heavy: its writes are submit, append, trailing, reprocess, stacking-apply, findings-generate and snapshot-capture. Correcting a field and signing off a decision stay role-gated actions inside the platform, where the same lifecycle, confidence gates and audit trail govern them — every API write is audited and attributed to the key that made it.
## Practical notes
- **Idempotency** — job triggers honor an `Idempotency-Key` header (same key + job within 24h returns the original run). Pass a `loanId` on submit and a re-submit while that package is in progress is rejected with `409 DUPLICATE_SUBMISSION`. Poll `status` rather than re-queueing; reprocess is an explicit, separate call.
- **Errors** — standard HTTP semantics with a machine-readable body (an error code plus message): `401` for a missing/invalid key, `404` for objects outside the key's project scope.
- **Least exposure** — treat the key like a production database credential. One key per consuming system makes revocation surgical.
## Where to go next
- The human side of the same queue: [G2 · Human-in-the-loop](/academy/g2).
- Driving the platform from AI tools instead of code: [V2 · MCP integration](/academy/v2).
- What the packages contain: [D1 · Collections & schema](/academy/d1).
---
## V2 · MCP integration
URL: https://www.botminds.ai/academy/v2
> Botminds Academy — Developer
# MCP integration
> **In one line.** The Model Context Protocol connects Botminds to the wider agent ecosystem in both directions: your agents can consume external MCP servers, and the platform hosts its own MCP tool surface so AI assistants can operate Botminds.
> **You'll be able to.** Pick the right direction for your integration, and know what governs each.
## Two directions, one protocol
MCP is the open standard for giving AI tools capabilities. On this platform it runs both ways:
| Direction | What it means | Governed by |
|---|---|---|
| **Inbound capabilities** — your agents consume external MCP servers | An agent gains tools from any MCP server you register: an internal system, a SaaS product, a partner API | The agent's Capabilities tab; scope filters per server ([A7](/academy/a7)) |
| **Outbound operation** — external AI tools drive Botminds | The platform hosts an MCP server exposing curated platform operations — list collections, inspect runs, query documents — so an assistant like Claude can work with your workspace | Tool profiles + platform authentication; every call carries workspace scope |
## Consuming MCP servers (the common case)
Covered in depth in [A7 · MCP servers](/academy/a7): register the server in Studio, filter which of its tools are exposed, attach it to an agent. Two disciplines carry from there:
- **Scope tightly.** An empty tool filter exposes everything the server offers; curate the list to the job.
- **Prefer read-only servers** for agents that face users, and treat destructive tools with the same caution you'd give a production credential.
## The hosted Botminds MCP
The platform mounts its own MCP server (under `/mcp` on the orchestrator) whose tools are the platform's operations, organized into **profiles** — curated tool subsets shaped for a purpose rather than one giant surface. Calls authenticate with platform-service credentials and are scoped to a workspace; the tools respect the same RBAC as the UI.
This is the surface the Global Co-pilot itself runs on — when it answers "how many documents landed today," it is calling these same tools. Pointing an external assistant at it gives that assistant the same governed reach.
> The hosted MCP surface and its profiles are evolving faster than most of the platform. Treat the profile catalog you see in your environment as the source of truth for what's exposed.
## Choosing your integration style
| You want | Use |
|---|---|
| Deterministic system-to-system calls, contracts, SLAs | [Runtime API](/academy/v1) — REST, keys, stable paths |
| An AI assistant that *operates* the platform conversationally | The hosted MCP surface |
| Your Botminds agents reaching into other systems | Inbound MCP ([A7](/academy/a7)) or [custom tools](/academy/a5) |
The rule of thumb: machines integrate over REST; minds integrate over MCP.
## Where to go next
- Registering and scoping servers: [A7 · MCP servers](/academy/a7).
- The REST alternative: [V1 · Runtime API](/academy/v1).
- What governs any caller: [G1 · Access & roles](/academy/g1).
---
## V3 · Embed & share
URL: https://www.botminds.ai/academy/v3
> Botminds Academy — Developer
# Embed & share
> **In one line.** Put a Botminds experience where your users already are: share links for instant access, anonymous access for public-facing surfaces, and embedding for your own portals.
> **You'll be able to.** Choose the right exposure level for an experience, and know what each level does and doesn't protect.
## The exposure ladder
Every experience starts private: sign-in required, access governed by [roles](/academy/g1). From there you open it up deliberately, one rung at a time:
| Rung | What it is | Right for |
|---|---|---|
| **Signed-in access** | The default — users log in, roles apply | Internal operations |
| **Share link** | A link that opens a specific page or experience directly — recipients skip the navigation, not the rules | Sending a colleague straight to a dashboard, a document, a chat |
| **Anonymous access** | An experience opened to users without accounts | Public assistants, customer-facing lookups |
| **Embed** | The experience rendered inside another site or portal | Your intranet, your product, a customer portal |
## Share links
The **Share Link** control in the top navigation (available when enabled for the experience) captures where you are and hands it to someone else. What they can see when they arrive is still decided by their access — a share link is a pointer, not a permission.
## Anonymous access
Some experiences are built to face the world — a policy assistant on your intranet's front page, a public document lookup. The experience is configured for anonymous users; the platform serves it without a sign-in, and everything else stays locked. Two disciplines:
- **Attach only public-safe knowledge.** The agent behind an anonymous experience should be grounded exclusively in content you would hand to a stranger — that is the [attachment boundary](/academy/sol-search) doing its job.
- **Watch the audit surfaces.** Anonymous chat still lands in the [chat audit](/academy/g4), so you can see what the world is asking.
## Embedding
Rendered pages and chat experiences can live inside your own web properties, carrying your [branding](/academy/e7) so the seam doesn't show. Pair an embedded experience with either signed-in access (your portal handles identity) or anonymous access (public surface), per the ladder above.
For deeper integration — your system calling the platform rather than framing it — step up to the [Runtime API](/academy/v1).
## Choosing, quickly
| The sentence in your head | Rung |
|---|---|
| "Look at this" | Share link |
| "Our customers should be able to ask this" | Anonymous experience |
| "It should feel like part of our portal" | Embed |
| "Our system needs the data, not the screen" | [Runtime API](/academy/v1) |
## Where to go next
- Making it look like yours first: [E7 · Shaping the experience](/academy/e7).
- The pages you'd embed: [E6 · Pages & cards](/academy/e6).
- Who can see what, underneath it all: [G1 · Access & roles](/academy/g1).
---
## V4 · Hubs & distribution
URL: https://www.botminds.ai/academy/v4
> Botminds Academy — Developer
# Hubs & distribution
> **In one line.** Package what you built, publish it to a Hub, and install it into another project — so a solution you build once can run for many teams or tenants.
> **You'll be able to.** Publish an agent (or a whole project) to a Hub, and install a published item into a different project, resolving its dependencies correctly.
> **Where this lives.** `Studio ▸ Hubs` (the registries), an object's **⋮ ▸ Publish**, and `Studio ▸ Hubs ▸ Solutions ▸ Publish to Hub` (whole-project publish).
## Structure travels, data doesn't
You've built something that works. The next team wants it. The next tenant wants it. You do not rebuild it by hand each time — you **package** it once and **install** it everywhere.
The single load-bearing idea of this whole page:
> **Structure travels; data doesn't.**
A package carries the *shape* of your solution — agent instructions, schemas, pipeline steps, guard rails, dashboards. It deliberately leaves behind everything that is local, private, or environment-specific: your documents, your vector index, your model credentials, your tenant ids. Those are either re-created empty at the destination, required to already exist there, or wired up at install time to the destination's own objects.
That is what makes a package safe to share across teams and tenants: nothing sensitive ships. A published item is a *recipe*, not a copy of your data. The rest of this page is the three verbs that make this real: **package**, **publish**, **install**.
## The Hubs surface
`Studio ▸ Hubs` shows two tabs — the two registries you'll actually use:
| Hub tab | What it's a registry of |
|---|---|
| **Solutions** | The **signed Solution marketplace** — publish *this project* as a signed Solution, and install Solutions from a shared, environment-independent Hub. |
| **Agents** | Published single **Agents** (the *Hub List* screen). |
The same Hub List screen also serves the other object registries — **Teams (Multi-Agents)**, **XFlows**, **Guard Rails**, **Functions** — at their own routes; they are just no longer top-level tabs. Learn the screen once and you know all five.
> **Under the hood.** Two distinct hub systems sit behind this surface. The object registries use a **per-environment** hub catalog with an admin approval workflow. The **Solutions** tab talks to an **environment-independent signed Hub** (`/api/hub/*`). They look similar; they are different stores. This page teaches both and says which is which at each step.
### The Hub List — layout
Every object registry renders a two-pane layout:
- **List rail** (left, ~400px): a search box; a card per published item showing its logo (or generated **initials** on a gradient when there's no logo), name, tags, and "Created At". As a consumer you simply see the items available to you.
- **Detail pane** (right): the selected item's title, logo, a facts grid (name, tags), a **Suggested Prompts** section, and the full rich-text **description** the publisher wrote.
- **Empty states**: "No Results" in the rail, "No Selection — please select an item" in the detail pane.
The single action you'll use as a builder is the **Import** button in the detail pane.
### The status model — published / installed / available
Every published item carries a **status**. As a builder, what you mainly care about is whether an item is *available to import*; the other statuses are the moderation lifecycle behind it.
| Status | Means | Who sees it |
|---|---|---|
| **Active** | *Pending review* — published but not yet approved. (The label says "Active"; read it as "pending".) | Admins, in moderation. |
| **Approved** | Cleared for use — this is the catalog everyone imports from. | Everyone. |
| **Rejected** | Turned down in review. | Admins. |
| **Inhouse** | Curated / featured, with **suggested prompts** attached. | Everyone (merged into the import catalog). |
> **Tip.** As a consumer the rail only ever shows you **Approved** items (with **Inhouse** merged in). The **[All] [Approved] [Active] [Rejected] [Inhouse]** filter chips and the status pills are admin-only — if you don't see them, that's expected, not a permissions bug.
> **Role-gated.** The moderation buttons (**Approve / Reject / Inhouse / Remove**, plus **Edit** and **Delete**) only appear on the **admin** view of the Hub List. As an ordinary builder you publish and import; an admin approves.
## Publishing
### Two ways to start a publish
You can publish at two granularities:
1. **A single object** — open the object in its builder, use the **⋮** menu, choose **Publish**. This puts one Agent / Team / XFlow / Guard Rail / Function into the matching object registry.
2. **A whole project** — `Studio ▸ Hubs ▸ Solutions ▸ Publish to Hub`. This packages the *entire* project as a **signed Solution** on the Hub (see "The Solutions marketplace" below). The older `Studio ▸ Project ▸ Publish` form (the per-environment project template) still exists, but the signed Hub is the shipping path.
Both open a **publish dialog**. The single-object dialog is shown here; the Solution publish modal is covered under "The Solutions marketplace" below. The idea is identical: describe the package and confirm what ships.
```
┌─ Publish Your Agent - Contract Reviewer ───────────────────[×]┐
│ Choose a Template or Upload │
│ [ Upload ] [img] [img] [img] [img] (≤ 2 MB, ≤ 1024×1024) │
│ Name * [______________________________] │
│ Description * [ rich-text editor ..................... ] │
│ Tags [ legal × ] [ nlp × ] [ + add ] (max 10) │
│ Publisher Name [______________________________] │
│ Template Setup Tabs [ Data Sheet ▾ ] (Data Sheet / Drive) │
│ ── shown ONLY if this object needs them ── │
│ LLM Model Description * [ "any GPT-4-class model" ] │
│ View Description * [ "the invoices view" ] │
│ Datasheet Description * [ "the line-items sheet" ] │
│ [ Publish ] │
└───────────────────────────────────────────────────────────────┘
```
### What every control does
| Control | What it does | Notes |
|---|---|---|
| **Logo** | Upload an image **or** pick one of 4 defaults. | Upload ≤ **2 MB**, ≤ **1024×1024 px** (checked in-browser). |
| **Name** * | The published name. | Required; letters/numbers/`_`, must not start with `_`; max 100 chars. |
| **Description** * | Rich-text explainer for importers. | Required. This is what someone reads before importing. |
| **Tags** | Searchable labels. | Up to **10**. For a *project* Solution, at least **1 tag is required to publish**. |
| **Publisher Name** | Your name / org. | Max 100 chars. |
| **Template Setup Tabs** | Which extra surfaces ship — **Data Sheet**, **Drive**. | Object publish. The project Publish form has a much larger "Template Setup Tabs" panel (which Studio modules appear in the tour). |
| **Dependent-description fields** | One required textarea **per unresolved dependency** the object references. | Appear *only* when the object actually has that dependency — see next. |
| **Publish** | Publishes the package. | Enabled only when the form is valid (and, for a project Solution, has at least 1 tag). For an item that already exists this button reads **Update**. |
### The dependency closure — EMBED, DECLARE, REBIND
When you publish, the platform walks the object's **dependency closure** — every other object it needs to run — and classifies each one. This is the heart of "structure travels, data doesn't", and it's why some dependency fields appear in the dialog and others don't.
| Class | Meaning | Ships in the package? | Example |
|---|---|---|---|
| **EMBED** | Pure configuration, carried **by value**. Re-created with fresh ids at install. | **Yes** — by value. | An agent's **sub-agents**, its **skills / skill packs**, its **guard rails**. |
| **DECLARE** | An **environment capability** that must already exist at the destination. Verified at install; **never shipped**. | **No.** | The **LLM model** class; **MCP servers** and their credentials; platform version. |
| **REBIND** | A **project-local data dependency**. The package carries a named **slot + description**, and the importer wires it to a local object at install. | **No** (the *binding* travels, not the data). | A **knowledge collection**; a legacy **View** or **Datasheet** the agent reads. |
Concretely, for the Contract Reviewer agent above: its **sub-agents and guard rails EMBED** — they travel inside the package and are re-created in the destination project. Its **LLM model DECLAREs** — the package says "I need a GPT-4-class model"; it does not carry your endpoint or API key. Its **knowledge collection / view / datasheet REBIND** — the package carries a slot described in plain language, and the importer maps it to one of *their* collections at install.
This is why the dialog grows extra textareas: for each **REBIND** (and DECLARE) dependency the object actually has, you write a one-line **description** so the importer knows what to pick. "LLM Model Description: any GPT-4-class chat model." "Datasheet Description: a table of contract line-items with `clause` and `risk` columns." Those descriptions are shown to the importer at the exact moment they choose the local object to bind.
> **Tip.** Good dependency descriptions are the difference between an install that just works and one that confuses the next team. Write them for someone who has never seen your project.
## Installing
Importing a published item into **your** project is the mirror image of publishing. Open the Hub tab for the object type, select the item, read its description, and click **Import**.
### The import / install flow
1. **Browse & select.** Open the Hub tab (e.g. **Agents**), find the item, read its description and suggested prompts. The catalog you see is the **Approved + Inhouse** set.
2. **Import.** Click **Import**. If the item has no unresolved dependencies (common for XFlows, Guard Rails, and simple Functions), it imports straight away — you'll get a "*<Name> imported successfully*" toast and it appears in your project.
3. **Resolve REBIND slots.** If the item *does* have dependencies, a **configuration dialog** opens. For each slot you must pick a **local** object:
```
┌─ Import: Contract Reviewer ────────────────────────────────[×]┐
│ This agent needs you to map the following to your project: │
│ LLM Model * [ Select a model ▾ ] │
│ "any GPT-4-class chat model" ← the publisher's note │
│ View * [ Select a view ▾ ] │
│ "the contracts view" │
│ Datasheet * [ Select a datasheet ▾ ] │
│ "contract line-items table" │
│ [ Import ] │
└────────────────────────────────────────────────────────────────┘
```
**Agents / Multi-Agents** require an **LLM Model**, plus a **View** and/or **Datasheet** if the object referenced one. **Functions** vary by type: a prompt function needs a **Prompt**; a widget-download function cascades **Dashboard → Widget**; a view-download function cascades **Collection → View**. Each field shows the **description the publisher wrote** so you know exactly what to pick.
4. **Execute.** Confirm. The platform mints fresh ids for the embedded pieces and binds the slots to the local objects you chose.
### The Solutions marketplace — the signed Hub
The object registries import from your environment's own catalog. The **Solutions** tab is different: a **marketplace browser** over signed packages on a shared Hub.
The page opens on a collapsible **Featured** rail (the top-installed Solutions), then a **split master–detail browser**: a master list on the left (search box, category facet, sort by *Most installed* or *Name*) and a **detail pane** on the right for the selected Solution — its icon, a **Signed** pill, a version picker, the install buttons (**Install here** into the current project, or **Install as new** which names and creates a project), and a **⋯** menu (ship to the next ring, request production release, roll back, remove from Hub). Stat tiles show installs, module/model counts and the current version, above four inline tabs:
| Detail tab | What it shows |
|---|---|
| **Overview** | Summary, the **environment promotion** ladder (dev → stg → prod, with each ring's version), the signature & compatibility check, and adoption stats. |
| **Setup guide** | The publisher's markdown guide, rendered inline. |
| **Version history** | Every published version with its summary, publisher and date. |
| **Samples** | Sample/demo files shipped with the Solution, downloadable. |
Publishing here is the header's **Publish to Hub** modal: name, version, category, summary, a listing icon, the setup-guide markdown, optional **sample files** and a **demo entry point** (where "Run demo" lands after install). The receipt shows exactly what shipped — asset count, bytes, content hash — with secrets redacted.
Because packages cross environments, the marketplace layers on **trust + preflight + approval**:
- **Verify** — the package is **signed**; the signature is checked before anything installs.
- **Preflight** — **Check install compatibility** in the Overview tab lists each **requirement** as met or missing *before* you commit. The platform row is real: a Solution is stamped with the platform version of the ring it was built on, so installing onto an older ring fails preflight instead of failing later.
- **Credentials preview** — the same check tells you up front "*you'll need to configure N credentials*" (counts and where — connection keys, script secrets — never values), so the key-configuration work is known **before** install, not a surprise wall after.
- **Approval** — some installs are **approval-required** and offer a one-click **Approve & install**. Shipping to **prod** is governed harder: it's a *request* that lands in a superadmin **Hub Release Approvals** queue, and the target hub is frozen at request time — if the destination changes before approval, the approval is refused. Managing the Hub-server registry itself (which hubs you publish to and install from) is a workspace-**Admin**-only action.
- **Upgrades & rollback** — an installed project shows an update banner when a newer version is published: upgrade **in place** (keeps documents, queues and history; auto-saves a rollback snapshot) or install side-by-side. **Roll back** returns the project to a prior published version.
### What an installed object looks like afterwards
This is the reassuring part: an installed object is just a normal project object. An imported Agent shows up in your `Agent Builder ▸ Agents` list like any agent you built by hand. An imported XFlow appears in your XFlows. There's no special "imported" mode to learn — once the REBIND slots are wired, it's yours, editable in the usual builders, picked from the usual pickers.
## Solutions vs Object Packages
There are two grains of packaging. Choosing the right one is mostly about *where the result lands*.
| | **Solution** (whole project) | **Object Package** (single object) |
|---|---|---|
| **You publish** | An entire project | One Agent / Team / XFlow / Guard Rail / Function |
| **Where it installs** | Creates a **NEW** project (**Install as new**) or, from the marketplace, into the **current** one (**Install here**) | Drops into an **EXISTING** project |
| **Use when** | Standing up a complete, repeatable solution for a new team/tenant ("the whole Invoice Processing app") | Adding one reusable piece to a project you already have ("just the Contract Reviewer agent") |
| **Maturity** | **Shipped** — the established path. | **Partly forward-looking** — see below. |
> **Watch out — maturity.** The **whole-project Solution** path is the **established, shipped** way to distribute a solution today: publish a project, install it as a new project. The **per-object Object Package** path is **partly forward-looking**. What ships *today* is the per-object **publish → import → REBIND** flow you used above (single Agents/Teams/XFlows/Guard Rails/Functions, with dependencies rebound at import). The fuller Object-Package design — signed single-object packages with a formal EMBED/DECLARE/REBIND closure, an install wizard with schema-compatibility verdicts, upgrade-in-place, and a rollback ledger — is **designed but not fully built**. Treat EMBED/DECLARE/REBIND as the *mental model* (it already explains today's behaviour); don't expect the full wizard yet. When in doubt, ship a **Solution**.
> **Under the hood.** The EMBED/DECLARE/REBIND trichotomy is realised in today's UI as: the agent's embedded config travels in the package payload (**EMBED**); the model/MCP are required, not shipped (**DECLARE**); and the import configuration dialog's model/view/datasheet/prompt pickers are exactly the **REBIND** step. The named-slot + schema-contract install wizard is the design's next increment.
## Try it yourself
Publish an agent, then install it into a different project.
**Part A — publish (in Project A):**
1. Open an agent you've built — ideally the one from [A3 · Your first agent](/academy/a3) — in `Agent Builder ▸ Agents`.
2. Open its **⋮** menu and choose **Publish**.
3. In the dialog: pick a **logo**, give it a clear **Name** and **Description**, add a couple of **Tags** (e.g. `demo`, `extractor`).
4. Fill in any **dependency-description** textareas that appear — note *which* ones appear and tie each back to EMBED / DECLARE / REBIND (model = DECLARE; knowledge/view/datasheet = REBIND).
5. Click **Publish**. (If an admin approval workflow is in place, your item starts as **Active / pending** until an admin approves it.)
**Part B — install (in Project B):**
6. Switch to a *different* project, open `Studio ▸ Hubs ▸ Agents`.
7. Find your agent (it must be **Approved** to appear), select it, read the description.
8. Click **Import**. When the configuration dialog opens, **map each REBIND slot** to a local object — pick this project's model, and its view/datasheet/collection as prompted.
9. Confirm. Then open `Agent Builder ▸ Agents` in Project B — your imported agent is there as a plain project agent. Open it; everything resolved to *this* project's objects.
You just moved a solution between projects without copying a single document. Structure travelled; data didn't.
## Where to go next
- [B10 · Package & ship a solution](/academy/uc-ship) — the full publish-and-install walkthrough on a real solution.
- [A3 · Your first agent](/academy/a3) — build the agent you'll publish.
- [D1 · Collections & schema](/academy/d1) — the data dependencies your packages REBIND to.
- [R0 · Glossary](/academy/r0) — **Solution**, **Object Package**, **Hub**, **EMBED / DECLARE / REBIND**.
---